AI-Enabled Clinical Transformation in Hospitals

AI-Enabled Clinical Transformation in Hospitals

A Mayo Clinic Case Study

Research Publication by Chioma Emenike

Institutional Affiliation:
New York Center for Advanced Research (NYCAR)

Publication No.: NYCAR-TTR-2026-RP019
Date:  June 2026

DOI: https://doi.org/10.5281/zenodo.20433769

Peer Review Status:
This research paper was reviewed and approved under the internal editorial peer review framework of the New York Center for Advanced Research (NYCAR) and The Thinkers’ Review. The process was handled independently by designated Editorial Board members in accordance with NYCAR’s Research Ethics Policy.


Abstract

Artificial intelligence is often described as the future of healthcare, yet hospitals do not transform simply because they adopt new technology. Many hospitals already live inside dense layers of digital systems: electronic health records, imaging platforms, patient portals, remote-monitoring tools, scheduling software, documentation templates, decision-support alerts, and analytics dashboards. Some of those systems have improved care. Others have added burden. AI is likely to follow the same pattern unless hospitals treat it not as a product to purchase, but as a clinical transformation strategy that must be governed, validated, integrated, and continuously improved.

Mayo Clinic provides a strong case for studying AI-enabled clinical transformation because its approach is not limited to isolated tools. Mayo Clinic publicly identifies AI uses that include clinical trial matching, remote health monitoring, imaging-based detection of conditions that may not yet be visible, and anticipation of disease risk years in advance. Mayo Clinic Platform also describes a broader shift from a pipeline model of healthcare innovation toward a platform model that brings together clinicians, developers, data, partners, and patients around secure, de-identified clinical data. Its platform materials emphasize discovery, validation, deployment into clinical workflows, feedback loops from live use, performance monitoring, model refinement, and responsible scaling. Mayo Clinic Platform also states that model credibility requires attention to bias, specificity, and sensitivity reporting. These claims make Mayo Clinic a useful case because they frame AI not as a technical add-on, but as an institutional redesign of how clinical knowledge is created, tested, delivered, and improved. (Mayo Clinic, n.d.-a)

A mixed-methods case-study design guides this paper. The qualitative side analyzes Mayo Clinic’s AI strategy, platform model, data governance, clinical validation, workflow integration, clinician trust, equity risk, and patient-centered care. The quantitative side uses straight-line equations to model relationships among AI capability, validation strength, workflow fit, and clinical transformation capacity. The central equation is ΔC = mA + b, where ΔC represents change in clinical transformation capacity, A represents AI-enabled clinical capability, m represents the marginal effect of AI capability, and b represents baseline clinical capacity before AI integration. Additional models include T = mV + b, where clinical trust depends on validation strength, and U = mF + b, where clinician adoption depends on workflow fit.

The central argument is that AI-enabled transformation in hospitals depends on disciplined integration rather than technological excitement. AI should not be judged by how advanced it sounds, how many pilots are launched, or how quickly a hospital announces deployment. It should be judged by whether it improves decisions, reduces avoidable burden, protects patient trust, works across diverse populations, and strengthens clinical judgment. Mayo Clinic’s case shows that credible hospital AI strategy requires trusted data, clinical validation, workflow design, human accountability, and a learning system that improves over time. The future of hospital AI should not be framed as machine replacement of clinicians. Better framing is clinical partnership: AI supporting humans in delivering earlier, safer, more personalized, and more humane care.
Keywords: artificial intelligence in healthcare; clinical transformation; Mayo Clinic Platform; hospital AI governance; clinical validation; workflow integration; clinician trust; patient-centered care; AI-enabled decision support; responsible AI; health data governance; model performance monitoring; bias and equity risk; digital health innovation; learning health systems.

Table of Contents

Mayo Clinic’s AI strategy is not built around a single tool or narrow technical function. It reaches across several areas of care, including trial matching, remote monitoring, imaging, and risk prediction. That breadth matters because it shows AI being treated as part of clinical transformation, not as a one-off digital experiment. 5

The platform model is also central. It creates a structure for moving AI beyond small pilots by connecting data, clinical expertise, validation, workflow integration, and feedback. Without that kind of structure, even promising AI tools can remain trapped in isolated projects. 5

Data governance is another major finding. In healthcare, trust begins with how patient data is collected, protected, de-identified, curated, and used. If the data foundation is weak, the AI system built on top of it cannot be fully trusted. 5

The analysis also shows that validation is non-negotiable. Sensitivity, specificity, and bias reporting are not technical details buried in the background; they are part of patient safety. Clinicians need to know what an AI tool can detect, where it may fail, and whether it performs fairly across different patient groups. 5

Workflow fit determines whether AI becomes useful in practice. A model may be accurate, but if it interrupts care, adds clicks, creates unclear alerts, or appears too late in the clinical process, clinicians are unlikely to trust or use it consistently. 6

Another finding is that AI requires continuous learning after deployment. Clinical environments change, patient populations shift, and model performance can decline over time. Responsible AI therefore needs monitoring, refinement, and clear accountability long after the first launch. 6

Patient value remains the real test. AI-enabled transformation should be judged by whether it helps patients receive earlier, safer, fairer, and more coordinated care. If AI does not improve the human experience of care, its technical sophistication means very little. 6


Chapter 1: Introduction

1.1 Background to the Study

Hospitals have never lacked technology. Modern care depends on imaging systems, laboratory platforms, electronic health records, infusion pumps, monitoring devices, patient portals, robotic systems, and clinical dashboards. Yet the history of hospital technology carries an uncomfortable lesson: new tools do not automatically make care better. Some technologies improve diagnosis and treatment. Others increase documentation, multiply alerts, fragment attention, or force clinicians to work around poorly designed systems. Healthcare AI arrives inside that reality. Its promise is enormous, but so is the risk of repeating old mistakes with more powerful tools.

Artificial intelligence can help clinicians detect patterns, predict deterioration, match patients to trials, interpret images, summarize records, monitor patients remotely, identify risk, and support more personalized care. Those possibilities matter because hospitals face real pressure. Patients are often older, sicker, and more medically complex. Clinicians are burned out. Costs remain high. Diagnostic delays can be devastating. Clinical trials struggle to identify eligible patients. Rural and underserved communities face uneven access to specialist expertise. A well-designed AI strategy could help hospitals respond to these pressures.

Even so, medicine is not a simple information-processing problem. A patient is more than a dataset. Clinical care includes uncertainty, values, family context, comorbidities, resource limits, ethics, culture, communication, and trust. A prediction may be statistically strong but clinically incomplete. An imaging model may identify risk but still require judgment about next steps. A remote-monitoring system may generate early warning signals, but clinicians must know which signals matter and who is responsible for acting. AI can support medicine, but it cannot carry the moral and relational weight of medicine by itself.

Mayo Clinic is an important case because its public AI strategy connects artificial intelligence to a larger platform model. Mayo Clinic states that AI can help select and match patients with promising clinical trials, support remote health monitoring devices, leverage imaging technology to detect conditions that are not yet visible, and anticipate disease risk years in advance. These use cases are clinically meaningful because they touch different points in the care journey: prevention, diagnosis, monitoring, treatment access, and research participation. (Mayo Clinic, n.d.-b)

Mayo Clinic Platform provides the broader institutional architecture. Its public materials describe a shift from a healthcare “pipeline” model toward a “platform” model. A pipeline model often moves innovations in a linear way: idea, development, testing, deployment. A platform model creates a shared foundation for data, validation, collaboration, deployment, and feedback. Mayo Clinic Platform says it supports innovation using secure, de-identified clinical data to create, validate, and scale digital health solutions. It also describes an end-to-end journey that moves from discovery and validation with real-world clinical data to building digital solutions, deploying them into clinical workflows, and continuously learning through real-world performance data. (Mayo Clinic, n.d.-a)

That platform language matters. Hospitals often struggle because innovation remains trapped in pilots. A model may work in a research setting but fail to scale across departments. A tool may perform well on one patient population but poorly on another. A solution may show promise but never fit into the clinical workflow. Mayo Clinic Platform’s emphasis on data, validation, deployment, monitoring, and refinement addresses exactly those translation barriers. The case is therefore not simply about Mayo adopting AI. It is about Mayo trying to build the institutional conditions that allow AI to become clinically useful.

Credible hospital AI also requires governance. Mayo Clinic Platform publicly states that responsible scaling includes bias, specificity, and sensitivity reporting for AI models. That language is important. Sensitivity matters because missed disease can be dangerous. Specificity matters because false alarms can create unnecessary testing, cost, anxiety, and burden. Bias matters because AI systems can perform differently across patient populations. A model that works well on average may still fail patients grouped by age, race, sex, language, socioeconomic status, disability, or geography. (Mayo Clinic, n.d.-a)

Clinical transformation, in this paper, means more than adopting digital tools. It means changing the way care is discovered, delivered, monitored, and improved. AI-enabled transformation occurs when hospitals use AI to support better clinical decisions, earlier intervention, safer workflows, stronger trial access, more personalized care, and continuous learning. The phrase should not be used casually. A hospital can deploy AI without transforming care. Real transformation requires fit between technology and clinical life.

1.2 Problem Statement

Many hospitals are under pressure to adopt AI quickly. Executives want innovation. Vendors promise efficiency. Clinicians hope for relief from workload. Patients expect faster, more personalized care. Investors and policymakers increasingly see AI as a solution to healthcare strain. Speed, however, can become dangerous when adoption outpaces validation, workflow redesign, clinical governance, and trust.

Several problems follow. AI tools may be built on incomplete, biased, or poorly representative data. Models that perform well in development can drift or fail under real clinical conditions. Clinicians may not know how to read AI outputs, or when to distrust them. Alerts and dashboards can multiply without reducing anyone’s workload. Patients may have little idea how their data is being used. And hospital leaders may measure AI success by deployment count rather than patient benefit.

Mayo Clinic offers a useful case because its platform approach tries to address many of these issues. It emphasizes secure de-identified data, validation with real patient populations, workflow deployment, monitoring, refinement, and responsible scaling. Yet the broader problem remains: how can hospitals use AI to transform care without weakening clinical judgment, safety, equity, or trust?

1.3 Aim and Objectives

The research examines how artificial intelligence is changing the way hospitals think, organize, and deliver care, using Mayo Clinic as the central case study. The concern is not AI as a trend or a technical upgrade. It is a harder question: how can AI become part of a serious clinical system that improves decisions, supports clinicians, protects patients, and strengthens the quality of care?

Objectives of the Study

The work treats AI-enabled clinical transformation as a leadership and healthcare-strategy issue, not simply a matter of buying or installing new technology. It analyzes Mayo Clinic’s platform-based approach to AI and asks what that approach reveals about data governance, clinical validation, workflow integration, clinician trust, patient safety, and equity.

The study also considers how AI capability can be connected to clinical transformation through linear modeling. This provides a simple way to show how stronger AI capacity, when supported by governance and workflow design, may improve a hospital’s ability to deliver safer, earlier, and more coordinated care.

The paper also develops practical recommendations for hospital leaders weighing AI adoption. The emphasis falls on responsible implementation: AI must solve real clinical problems, fit the work of clinicians, protect patients from avoidable harm, and support rather than weaken professional judgment.

Research Questions

  • The research is guided by the following questions:
  • How does artificial intelligence support clinical transformation in hospital systems?
  • What does Mayo Clinic’s platform-based approach show about responsible healthcare AI strategy?
  • How can AI capability be connected to clinical transformation capacity through linear modeling?
  • What leadership and governance conditions are needed for AI to improve care without creating new risks?
  • How can hospitals use AI to strengthen diagnosis, monitoring, research access, and care delivery while preserving clinical judgment?

Significance of the Study

Artificial intelligence is already becoming part of hospital practice. It is appearing in imaging, clinical documentation, patient communication, remote monitoring, research matching, diagnosis, risk prediction, scheduling, and operational planning. This makes AI a practical issue for healthcare leaders, not a distant future concern.

The significance of this study lies in the difference between adoption and transformation. A hospital can adopt AI without improving care. It can add new systems, dashboards, alerts, and predictive tools while leaving clinicians more burdened and patients no better served. In that case, AI becomes another layer of complexity inside an already strained system.

Responsible AI offers a different possibility. It can help hospitals identify disease earlier, match patients to clinical trials more efficiently, monitor patients outside traditional care settings, reduce unnecessary administrative work, and support better clinical decisions. Its value depends on whether it is accurate, fair, usable, trusted, and connected to real clinical needs.

Mayo Clinic is a useful case because its platform-based approach treats AI as part of a broader healthcare transformation model. The case shows why hospitals need more than technical ambition. They need reliable data, strong validation, clear governance, workflow discipline, patient safeguards, and ongoing evaluation after deployment.

The work matters because hospitals cannot afford careless AI implementation. Clinical decisions affect real people, and poor technology design can cause harm. The point of AI in healthcare is not to replace clinicians or make medicine less human. It is to help clinicians see more clearly, act earlier, reduce avoidable burden, and deliver care that is safer, fairer, and more responsive to patients.

Chapter 2: Literature Review

2.1 AI in Healthcare: Promise and Risk

Healthcare AI is attractive because hospitals generate large amounts of data. Clinical notes, imaging, laboratory tests, monitoring devices, pathology slides, genomic data, prescriptions, appointment records, and outcomes data all contain patterns that may support better decisions. AI can help process those patterns faster and at larger scale than human teams alone.

Mayo Clinic’s public AI materials reflect this promise. Listed use cases include clinical trial matching, remote health monitoring, imaging-based detection, and disease-risk prediction. Each use case addresses a real problem. Clinical trial matching is often slow and incomplete. Remote monitoring can extend care beyond hospital walls. Imaging AI may help detect subtle patterns. Risk prediction may help clinicians intervene earlier. (Mayo Clinic, n.d.-b)

Still, healthcare AI introduces risks. A model trained on one population may not work well for another. A tool that performs well in retrospective validation may fail during live deployment. AI-generated recommendations may be accepted too easily by overworked clinicians or ignored because they are poorly timed. Outputs may be difficult to explain. Data use may raise privacy concerns. These risks are not arguments against AI. They are arguments for disciplined clinical governance.

2.2 Platform Thinking in Healthcare AI

Platform thinking provides a useful way to understand Mayo Clinic’s approach. Mayo Clinic Platform describes itself as moving healthcare from a pipeline model to a platform model. It brings together clinicians, producers, consumers, global collaborators, and de-identified clinical data to create, validate, and scale digital health solutions. (Mayo Clinic, n.d.-a)

Healthcare innovation has often failed at scale because the pipeline from research to practice is slow and fragmented. Developers may build tools without enough clinical input. Researchers may validate models in narrow settings. Hospitals may struggle to deploy tools into electronic records and daily workflows. Clinicians may resist because tools do not match clinical needs. A platform model tries to reduce these disconnects by creating shared infrastructure for discovery, validation, deployment, feedback, and improvement.

Mayo Clinic Platform’s own description of its end-to-end model is important. It describes discovery and validation with real-world clinical data, building solutions with clinical insights, deploying into clinical workflows, and learning continuously from real-world performance. (Mayo Clinic Platform, n.d.-a) This sequence is not merely technical. It represents a theory of clinical transformation: innovation should be grounded in clinical reality, shaped by clinician input, integrated into care, and revised after deployment.

2.3 Clinical Data and De-Identification

Clinical AI depends on data. Yet healthcare data is sensitive, uneven, and ethically charged. It contains information about illness, identity, behavior, genetics, treatment, family history, and vulnerability. Responsible AI strategy therefore begins with data governance.

Mayo Clinic Platform emphasizes secure, de-identified clinical data. Its platform materials refer to curated, de-identified clinical data derived from real patient care and designed for rigorous research and innovation. (Mayo Clinic Platform, n.d.-b) De-identification matters because patient privacy is a basic requirement for trust. However, de-identification alone does not solve all data problems. Data must also be representative, clinically accurate, properly structured, and suitable for the intended use.

Poor data can lead to poor AI. Missingness, coding practices, clinical bias, documentation patterns, and unequal access to care can all shape the data. If a population has historically received less diagnostic attention, the data may reflect that neglect. AI trained on such data may reproduce inequity unless explicitly evaluated.

2.4 Validation and Clinical Trust

Clinical trust cannot rest on institutional reputation alone. AI tools must be validated. Mayo Clinic Platform’s public emphasis on bias, specificity, and sensitivity reporting is therefore highly relevant. Sensitivity and specificity are familiar clinical concepts, but their importance grows when AI tools are scaled. A high-sensitivity model may detect more disease but may also create more false positives if specificity is weak. A high-specificity model may reduce false alarms but miss cases if sensitivity is too low. Bias reporting addresses whether performance differs across patient groups. (Mayo Clinic, n.d.-a)

Trust also requires transparency about limits. Clinicians do not need models to be magical. They need to know what a model is good at, where it fails, what evidence supports it, how it was validated, and what action is expected when the output appears.

2.5 Workflow Integration

Workflow fit is one of the most important conditions for hospital AI. Healthcare settings are crowded with tasks. An AI tool that arrives at the wrong moment, appears in the wrong screen, produces unclear recommendations, or requires additional documentation may not help clinicians. It may increase burden.

Mayo Clinic Platform’s materials explicitly discuss deployment into clinical workflows, integration with hospital systems and clinical tools, interoperability, and design for adoption rather than pilots. (Mayo Clinic Platform, n.d.-a) That phrase—designed for adoption, not just pilots—is central. Many hospital AI efforts fail because they stop at demonstration. Clinical transformation requires adoption in real environments.

2.6 Continuous Learning and Model Monitoring

Clinical AI cannot be treated as finished after launch. Patient populations change. Clinical practices change. Devices change. Coding standards change. Disease patterns change. A model that worked well last year may drift. Mayo Clinic Platform describes feedback loops from live clinical use, performance monitoring, model refinement, continuous validation with new data, and scaling across sites, populations, and use cases. (Mayo Clinic Platform, n.d.-a)

Continuous learning turns AI from a static product into a managed clinical system. It also creates governance obligations. Who monitors performance? How often? What happens when performance declines? Who can suspend a model? How are clinicians informed? How are patients protected? These are not minor operational details. They define responsible AI.

2.7 AI, Equity, and Bias

Equity must be built into AI strategy from the beginning. Healthcare already contains disparities. AI systems trained on historical data can reflect those disparities. A risk score may under-detect illness in groups that have historically received less testing. An imaging model may perform differently across demographic groups. A remote-monitoring tool may advantage patients with reliable internet access and digital literacy.

Bias reporting, therefore, is not a bureaucratic add-on. It is part of patient safety. Mayo Clinic Platform’s public commitment to bias reporting provides a useful case anchor. (Mayo Clinic, n.d.-a) Still, reporting must lead to action. If bias is found, leaders must decide whether to modify, restrict, retrain, or reject the tool.

2.8 Human Judgment in AI-Enabled Care

Healthcare AI should support clinical judgment, not replace responsibility. Clinicians bring context, empathy, ethical reasoning, and practical understanding of patient life. AI may identify patterns but cannot fully understand what it means for a patient to live with a diagnosis, refuse treatment, weigh risk, or navigate family realities.

A strong AI strategy therefore protects the clinician’s role as interpreter and accountable decision-maker. It also protects patients from being reduced to probabilities. Patient-centered AI should help clinicians see more clearly, act earlier, and communicate better.

2.9 Literature Gap

Much healthcare AI discussion focuses on model performance, while much hospital leadership discussion focuses on adoption and efficiency. Less attention is given to the full transformation pathway: data readiness, validation, workflow fit, clinician trust, patient value, equity, monitoring, and governance. Mayo Clinic’s platform approach offers a case through which those issues can be integrated.

Read also: Managing Nursing Work for Safer Care

Chapter 3: Methodology

3.1 Research Design

A mixed-methods case-study design guides this paper. Mayo Clinic is selected because its public AI and platform materials provide a strong example of healthcare AI framed as clinical transformation. The case combines institutional strategy, clinical data governance, model validation, workflow integration, responsible scaling, and patient-centered care.

Qualitative analysis examines Mayo Clinic’s AI strategy, platform model, use cases, governance language, validation requirements, and clinical transformation logic. Quantitative analysis uses straight-line equations to model relationships among AI capability, validation strength, workflow fit, trust, and transformation capacity. These calculations are not clinical outcome estimates. They are strategic models used to make the logic of transformation visible.

3.2 Case Selection

Mayo Clinic was selected for five reasons.

Selection Reason Why It Matters
Public AI strategy Mayo identifies concrete clinical AI use cases
Platform model Mayo frames AI as ecosystem transformation
Data governance Secure, de-identified clinical data is central
Validation emphasis Bias, sensitivity, and specificity reporting are stated priorities
Clinical reputation Patient-centered care makes trust and safety essential


Mayo is not used as proof that all hospital AI succeeds. It is used because its public model shows the kinds of structures responsible AI strategy requires.

3.3 Data Sources

Data Category Source Evidence Used Analytical Purpose
AI priorities Mayo Clinic AI page Trial matching, remote monitoring, imaging detection, disease-risk prediction Defines clinical AI scope
Platform strategy Mayo Clinic Platform page Shift from pipeline to platform model Frames transformation architecture
Data infrastructure Mayo Clinic Platform and Discover pages Secure, curated, de-identified clinical data Supports data governance analysis
Workflow deployment Mayo Clinic Platform “Our Platform” Integration with hospital systems, clinical workflows, interoperability Supports workflow analysis
Validation Mayo Clinic Platform Bias, specificity, sensitivity reports Supports trust and safety analysis
Continuous learning Mayo Clinic Platform “Our Platform” Feedback loops, monitoring, refinement Supports governance analysis


3.4 Analytical Framework

The study uses seven dimensions.

Dimension Meaning Clinical Question
AI capability Ability to support diagnosis, monitoring, trial matching, prediction What clinical problem does AI address?
Data readiness De-identified, curated, representative clinical data Can the model learn from reliable data?
Validation strength Sensitivity, specificity, bias testing, real-world evaluation Can clinicians trust performance?
Workflow fit Integration into actual clinical routines Does AI help or burden clinicians?
Clinician trust Confidence based on evidence and usability Will clinicians use the tool responsibly?
Patient value Better diagnosis, access, prevention, monitoring Does care improve for patients?
Governance Monitoring, accountability, refinement Who is responsible over time?


3.5 Linear Calculation Models

Clinical transformation model:

Δ C = mA + b

Where:

  • (Δ C) = change in clinical transformation capacity
  • (A) = AI-enabled clinical capability
  • (m) = marginal effect of AI capability
  • (b) = baseline clinical capacity

Clinical trust model:

T = mV + b

Where:

  • (T) = clinical trust in AI
  • (V) = validation strength
  • (m) = marginal effect of validation
  • (b) = baseline trust before validation

Workflow adoption model:

U = mF + b

Where:

  • (U) = clinician use and adoption
  • (F) = workflow fit
  • (m) = marginal effect of workflow fit
  • (b) = baseline adoption

Burden reduction model:

B = b – mW

Where:

  • (B) = clinician burden
  • (W) = workflow usefulness
  • (m) = burden reduction effect
  • (b) = baseline burden

3.6 Scoring Model for Case Interpretation

A simple five-point strategic scoring model is used to interpret Mayo’s AI transformation readiness based on public evidence.

Dimension Score Logic
1 Weak or not publicly evident
2 Early or limited evidence
3 Moderate evidence
4 Strong evidence
5 Strong, explicit, and strategically integrated evidence


The scoring is interpretive, not official Mayo data.

3.7 Methodological Limitations

The paper uses public sources, not internal Mayo performance data. It does not evaluate any specific Mayo AI model. It does not claim that Mayo’s AI tools have produced measurable patient-outcome improvement in all areas. Linear equations are used for strategic clarity rather than clinical proof. Stronger future research would require model-level validation data, clinician interviews, patient outcomes, workflow observation, and comparative hospital studies.

Chapter 4: Case Analysis and Findings

Chapter 4: Case Analysis and Findings

4.1 Mayo Clinic’s AI Transformation Strategy

Mayo Clinic’s AI strategy is clinically broad. Its public AI materials identify four major use areas: matching patients with clinical trials, remote health monitoring, imaging-based detection of imperceptible conditions, and anticipation of disease risk years in advance. (Mayo Clinic, n.d.-b)

These areas are not random. They reflect four important transformation directions:

Mayo AI Use Area Clinical Transformation Direction
Clinical trial matching Expands access to research and precision treatment options
Remote monitoring Moves care beyond hospital walls
Imaging detection Supports earlier and more precise diagnosis
Disease-risk prediction Shifts care toward prevention and anticipation


Together, these use cases suggest a hospital strategy moving from reactive care toward predictive, distributed, data-enabled care.

4.2 Finding One: Platform Strategy Supports Clinical Scaling

Mayo Clinic Platform provides the most important structural feature of the case. Its platform model supports discovery, validation, build, deployment, feedback, and scale. (Mayo Clinic Platform, n.d.-a) That matters because isolated AI tools often fail after promising pilots.

A scaling equation can be written:

S = mP + b

Where:

  • (S) = AI scaling capacity
  • (P) = platform maturity
  • (m) = marginal scaling effect of platform maturity
  • (b) = baseline scale before platform integration

Platform maturity improves scaling capacity because it gives AI development access to clinical data, clinician insight, deployment infrastructure, monitoring, and feedback loops.

4.3 Finding Two: Data Governance Is the Foundation

Mayo Clinic Platform emphasizes secure, de-identified clinical data. Its Discover page refers to curated, high-quality clinical data assets, de-identified and privacy-protected datasets, and rigorous research and innovation support. (Mayo Clinic Platform, n.d.-b)

AI without trustworthy data is unsafe. In healthcare, data governance is not technical housekeeping. It is clinical ethics. Patients trust hospitals with intimate information. Hospitals using that information for AI must protect privacy while ensuring that data supports valid and equitable care.

4.4 Finding Three: Validation Builds Trust

Mayo Clinic Platform’s reference to bias, specificity, and sensitivity reporting is one of the strongest indicators of responsible AI strategy. (Mayo Clinic, n.d.-a) These measures connect model performance to clinical reality.

Validation Element Meaning Clinical Risk if Weak
Sensitivity Ability to identify true positives Missed disease
Specificity Ability to avoid false positives Unnecessary testing and anxiety
Bias testing Performance across subgroups Unequal care
Real-world validation Performance outside development settings Model failure in practice
Monitoring Ongoing performance review Silent drift


A trust equation:

T = mV + b

Clinical trust (T) should rise as validation strength (V) improves. In practical terms, clinicians trust AI when they can see evidence, limits, and use conditions.

4.5 Finding Four: Workflow Fit Determines Adoption

Mayo Clinic Platform says deployment must integrate with hospital systems and clinical workflows, with interoperability and adoption beyond pilots. (Mayo Clinic Platform, n.d.-a) This point is crucial. AI that does not fit workflow becomes digital friction.

Workflow Problem Likely Result Stronger Design
Output appears too late Clinician ignores it Embed at decision point
Alert volume too high Alert fatigue Prioritize actionable signals
Recommendation unclear Low trust Explain output and next step
Extra documentation needed Higher burden Automate or simplify
No accountability Confusion Assign clinical responsibility
Poor EHR integration Workaround behavior Build into existing systems


Workflow fit equation:

U = mF + b

Clinician use (U) rises when workflow fit (F) improves.

4.6 Finding Five: Continuous Learning Prevents Stagnation

Mayo Clinic Platform describes feedback loops from live clinical use, performance monitoring, model refinement, continuous validation with new data, and scaling across sites and populations. (Mayo Clinic Platform, n.d.-a)

A continuous learning model is essential because clinical AI can drift. Patient populations change. Data sources change. Practice patterns change. Models need governance after launch.

Continuous improvement equation:

I = mM + b

Where:

  • (I) = improvement in AI performance and usefulness
  • (M) = monitoring and model refinement strength
  • (m) = marginal improvement effect
  • (b) = baseline performance after initial deployment

4.7 Finding Six: AI Must Reduce Burden

Mayo Clinic Platform materials mention reducing burden among healthcare staff as part of platform innovations. (Mayo Clinic, n.d.-a) This matters because clinicians are already overloaded. AI that adds work is unlikely to transform care.

Burden reduction model:

B = b – mW

Where (W) is workflow usefulness. Better workflow usefulness should reduce clinician burden. If AI increases burden, implementation has failed even if the model is technically impressive.

4.8 Finding Seven: Patient Value Is the Final Test

Patient value should be the final test. AI may be exciting, but hospitals exist to care for patients. Mayo Clinic Platform grounds its work in Mayo’s mission that the needs of the patient come first. (Mayo Clinic Platform, n.d.-a)

Patient value can appear in many forms: earlier diagnosis, better trial access, fewer unnecessary tests, improved remote support, safer care plans, more personalized treatment, better communication, and reduced waiting. A hospital AI program that cannot connect tools to patient value should pause.

4.9 Case Scoring Table

Transformation Dimension Public Evidence Strength Score Interpretation
Clinical AI use-case clarity Trial matching, remote monitoring, imaging, risk prediction 5 Clear public use-case direction
Platform architecture Pipeline-to-platform model 5 Strong transformation framing
Data governance Secure, de-identified, curated clinical data 5 Strong public data-governance emphasis
Validation Bias, sensitivity, specificity reporting 5 Strong responsible AI indicator
Workflow integration Deployment into clinical workflows and interoperability 4 Strong strategic claim, limited public outcomes data
Continuous learning Feedback loops and model refinement 4 Strong architecture, limited model-level evidence
Patient-value framing Needs of patient come first 5 Strong mission alignment


Total score:

R_s = 5 + 5 + 5 + 5 + 4 + 4 + 5

R_s = 33

Maximum possible score:

M_s = 7 × 5 = 35

Readiness ratio:

P_r = 33 / 35

P_r = 0.943

Based on public strategic evidence, Mayo Clinic’s AI transformation readiness score is approximately 94.3% of the maximum in this interpretive framework. This does not mean outcomes are 94.3% achieved. It means the public strategy strongly reflects the design conditions associated with responsible AI transformation.

4.10 Summary of Findings

Seven findings stand out from the case analysis.

Mayo Clinic’s AI strategy is not built around a single tool or narrow technical function. It reaches across several areas of care, including trial matching, remote monitoring, imaging, and risk prediction. That breadth matters because it shows AI being treated as part of clinical transformation, not as a one-off digital experiment.

The platform model is also central. It creates a structure for moving AI beyond small pilots by connecting data, clinical expertise, validation, workflow integration, and feedback. Without that kind of structure, even promising AI tools can remain trapped in isolated projects.

Data governance is another major finding. In healthcare, trust begins with how patient data is collected, protected, de-identified, curated, and used. If the data foundation is weak, the AI system built on top of it cannot be fully trusted.

The analysis also shows that validation is non-negotiable. Sensitivity, specificity, and bias reporting are not technical details buried in the background; they are part of patient safety. Clinicians need to know what an AI tool can detect, where it may fail, and whether it performs fairly across different patient groups.

Workflow fit determines whether AI becomes useful in practice. A model may be accurate, but if it interrupts care, adds clicks, creates unclear alerts, or appears too late in the clinical process, clinicians are unlikely to trust or use it consistently.

Another finding is that AI requires continuous learning after deployment. Clinical environments change, patient populations shift, and model performance can decline over time. Responsible AI therefore needs monitoring, refinement, and clear accountability long after the first launch.

Patient value remains the real test. AI-enabled transformation should be judged by whether it helps patients receive earlier, safer, fairer, and more coordinated care. If AI does not improve the human experience of care, its technical sophistication means very little.


Chapter 5: Discussion

5.1 Clinical Transformation Versus AI Adoption

Mayo Clinic’s case shows why hospitals must distinguish AI adoption from clinical transformation. Adoption asks whether a tool is deployed. Transformation asks whether care becomes better. A hospital may deploy many AI tools and still leave clinicians burdened, patients confused, and outcomes unchanged. Another hospital may deploy fewer tools but integrate them deeply into diagnosis, monitoring, workflow, and learning.

Clinical transformation requires disciplined design. Data must be reliable. Models must be validated. Workflows must be redesigned. Clinicians must be trained. Patients must trust the system. Leaders must monitor performance. Governance must act when something fails.

5.2 Platform Model as Strategic Infrastructure

The Mayo Clinic Platform case suggests that hospitals need AI infrastructure, not only AI applications. Infrastructure includes data governance, validation environments, clinical expertise, deployment pathways, monitoring systems, and partner networks. Without that infrastructure, hospitals risk building scattered pilots.

Platform strategy also allows learning across use cases. A trial-matching tool, imaging model, and remote monitoring application may differ clinically, but they share needs: data quality, validation, workflow fit, monitoring, and governance. A platform can support those shared needs.

5.3 Clinician Trust Must Be Earned

Clinician trust is not resistance to innovation. Often, it is professional caution. Clinicians are responsible for patients, and they know that tools can fail. Trust grows when evidence is transparent, outputs are usable, limits are known, and clinicians remain part of decision-making.

Hospitals should avoid forcing adoption through administrative pressure. Better practice is to involve clinicians early, test in real workflows, show validation evidence, listen to objections, and revise tools.

5.4 Equity Requires Active Testing

Healthcare AI can worsen inequity unless leaders test for it. Mayo Clinic Platform’s public reference to bias reporting is important, but every hospital needs similar discipline. Equity testing should examine subgroup performance where appropriate and feasible. Leaders should ask whether a model performs differently by age, sex, race, ethnicity, disability, language, rurality, insurance status, or care setting.

A model that improves average performance but worsens outcomes for underserved groups is not acceptable. Patient-centered AI must be equitable AI.

5.5 Burden Reduction Should Be Measured

Hospitals should measure whether AI reduces or increases burden. Clinicians have lived through technologies that promised efficiency but created more work. Documentation burden, inbox messages, alerts, and administrative tasks already consume attention. AI should not become another layer.

Burden metrics may include:

Burden Area Possible Measure
Alert load Number and actionability of AI alerts
Documentation Time saved or added
Workflow steps Number of additional clicks or screens
Cognitive load Clinician usability feedback
Response time Whether AI helps earlier action
Trust Clinician confidence in recommendations
Fatigue Whether AI reduces or increases interruptions


5.6 Governance Must Be Multidisciplinary

AI governance cannot sit only with IT. It should include clinicians, data scientists, ethicists, patient representatives, legal experts, quality leaders, privacy officers, and operational managers. Clinical AI changes decisions that affect human lives. Governance must reflect that seriousness.

A governance committee should be able to approve, monitor, revise, pause, or retire AI tools. It should also define accountability when AI contributes to decisions.

5.7 Practical Model for Hospital Leaders

Leadership Question Why It Matters Practical Action
What problem are we solving? Prevents technology-first adoption Start with clinical pain points
What data supports the tool? Protects validity Review data quality and representativeness
How was it validated? Builds trust Require sensitivity, specificity, and bias testing
Where does it enter workflow? Determines adoption Design with clinicians
Who is accountable? Prevents confusion Clarify responsibility
How will it be monitored? Prevents drift Use post-deployment performance review
What do patients need to know? Protects trust Communicate privacy and purpose clearly


5.8 Professional Practice Implication

Professional doctoral work should produce applied wisdom. The wisdom from this case is that hospitals need to slow down in order to transform faster. Careful validation, workflow design, and governance may seem to delay implementation, but they prevent failed deployment. In healthcare AI, speed without trust is not progress.


Chapter 6: Conclusion and Recommendations

6.1 Conclusion

Mayo Clinic’s case shows that AI-enabled clinical transformation depends on infrastructure, not hype. The strongest parts of Mayo’s public strategy are not only the listed AI use cases. They are the platform elements around those use cases: secure de-identified data, real-world validation, clinical workflow deployment, bias and performance reporting, feedback loops, model refinement, and patient-centered mission.

AI can support trial matching, remote monitoring, imaging detection, and risk prediction. Yet those tools become clinically meaningful only when they are trusted, usable, equitable, and governed. Hospitals should not ask whether AI is impressive. They should ask whether it helps clinicians care for patients better.

Central conclusion: AI should strengthen the clinical heart of medicine, not replace it.

6.2 Recommendations

  1. Begin with clinical need, not vendor promise.

Hospitals should identify problems in diagnosis, monitoring, trial access, workflow, or patient experience before selecting AI tools.

  1. Build data governance before deployment.

Secure, de-identified, representative, and clinically meaningful data should be treated as the foundation of hospital AI.

  1. Require validation before clinical use.

Sensitivity, specificity, subgroup performance, and real-world testing should be mandatory.

  1. Design with clinicians.

AI tools should be developed and deployed with frontline physicians, nurses, pharmacists, technicians, and care coordinators.

  1. Measure workflow burden.

Hospital leaders should track whether AI reduces or increases documentation, alerts, clicks, and cognitive load.

  1. Include patients in governance.

Patient representatives should help review transparency, consent, communication, privacy, and trust concerns.

  1. Monitor after launch.

Model performance should be reviewed continuously. Drift, bias, and usability failures should trigger action.

  1. Preserve human accountability.

Clinicians should remain responsible decision-makers, with AI serving as support rather than authority.

  1. Build equity review into every AI project.

Models should be assessed for differential performance across relevant patient groups.

  1. Retire tools that do not improve care.

Deployment should not become permanent just because money has been spent. Tools that fail should be revised or removed.

6.3 Implementation Roadmap

Timeline Priority Action
First 90 days AI inventory Identify current and planned AI tools
3–6 months Governance Create multidisciplinary AI oversight committee
6–9 months Validation standards Require sensitivity, specificity, bias, and workflow review
9–12 months Workflow integration Pilot tools with clinician feedback
12 months and beyond Continuous monitoring Track performance, burden, equity, and patient outcomes


6.4 Final Reflection

The best hospital AI will not feel like machinery replacing human care. It will feel like better timing, clearer information, earlier warnings, fewer wasted steps, more precise diagnosis, and more room for clinicians to focus on patients. Mayo Clinic’s case points toward that kind of future. Its platform approach recognizes that AI must be built, tested, deployed, and improved inside the clinical realities of medicine.

Hospitals should learn from that seriousness. AI will not save healthcare by itself. Tools do not heal people. People heal people, supported by knowledge, systems, judgment, and trust. AI can become part of that support if hospitals govern it with humility and discipline.

References

Mayo Clinic. (n.d.). Artificial intelligence. https://www.mayoclinic.org/giving-to-mayo-clinic/our-priorities/artificial-intelligence

Mayo Clinic. (n.d.). Mayo Clinic Platform. https://www.mayoclinic.org/giving-to-mayo-clinic/our-priorities/mayo-clinic-platform

Mayo Clinic Platform. (n.d.). Discovery. https://www.mayoclinicplatform.org/discover/

Mayo Clinic Platform. (n.d.). Our platform. https://www.mayoclinicplatform.org/our-platform/

Yu, Y., Hu, X., Rajaganapathy, S., Feng, J., Abdelhameed, A., Li, X., Li, J., Liu, K., Yang, L., Taner, N., Fiero, P., Boroumand, S., Larsen, R., Goyal, M., Otley, C., Zong, N., Halamka, J., & Tao, C. (2025). Launching insights: A pilot study on leveraging real-world observational data from the Mayo Clinic Platform to advance clinical research. arXiv. https://arxiv.org/abs/2504.16090

The Thinkers’ Review

IMG-20260618-WA0010

Counterterrorism Beyond Force

Management, Public Policy, and Institutional Trust in High-Risk Societies

Research Publication by Michael E. Emenike

Counterterrorism Management and Public Policy

NEW YORK CENTER FOR ADVANCED RESEARCH (NYCAR) Research Publication | June 2026

Publication No.: NYCAR-TTR-2026-RP067

DOI: https://doi.org/10.5281/zenodo.20745145


Copyright © June 2026 Michael E. Emenike. All rights reserved. New York Center for Advanced Research (NYCAR).

Peer Review and Publication Status

This research publication has passed NYCAR’s internal peer-review and editorial assessment for master’s-level research publication. The review examined the strength of the research problem, the quality of the public-policy argument, the handling of quantitative evidence, the relevance of the case analysis, the structure of the chapters, the discipline of APA 7th referencing, and the practical usefulness of the findings for counterterrorism management and public governance.

Peer review found the publication suitable for public release because it treats counterterrorism as a serious governance problem rather than a slogan for force. The work shows command of the subject, uses public evidence carefully, explains the limits of descriptive data, and maintains a professional voice appropriate for a sensitive security-policy field. Its quantitative model is suitable for master’s-level applied analysis because it supports management triage without pretending to replace lawful judgment, local knowledge, or institutional accountability.

NYCAR approves this work for inclusion in the June 2026 Research Edition as a publication-ready master’s-level research output. The publication meets the expected standard for conceptual clarity, evidence discipline, ethical restraint, quantitative suitability, professional relevance, and public-policy value.

Abstract

Counterterrorism policy becomes weak when it treats violence only as an event to be crushed. Armed groups are dangerous because they kill, frighten, recruit, move money, exploit borders, and challenge public authority. Yet the deeper management failure often sits around the violence: weak local government, poor justice reach, abusive enforcement, civilian fear, financial leakage, damaged trust, and services that disappear when communities need the state most. A serious counterterrorism response must therefore protect life while keeping law, intelligence, finance, development, justice, rehabilitation, communication, and regional cooperation inside the same operating system.

Michael E. Emenike studies counterterrorism as a management problem involving law, intelligence, public finance, criminal justice, border systems, community confidence, victim support, and institutional trust. The publication uses public evidence from the Global Terrorism Index 2026, United Nations counterterrorism instruments, FATF standards, UNODC rule-of-law material, World Bank conflict-policy work, and UNDP’s Journey to Extremism in Africa. The evidence is handled as public policy material, not as operational instruction. The analysis stays at the level of governance, risk, coordination, and accountability.

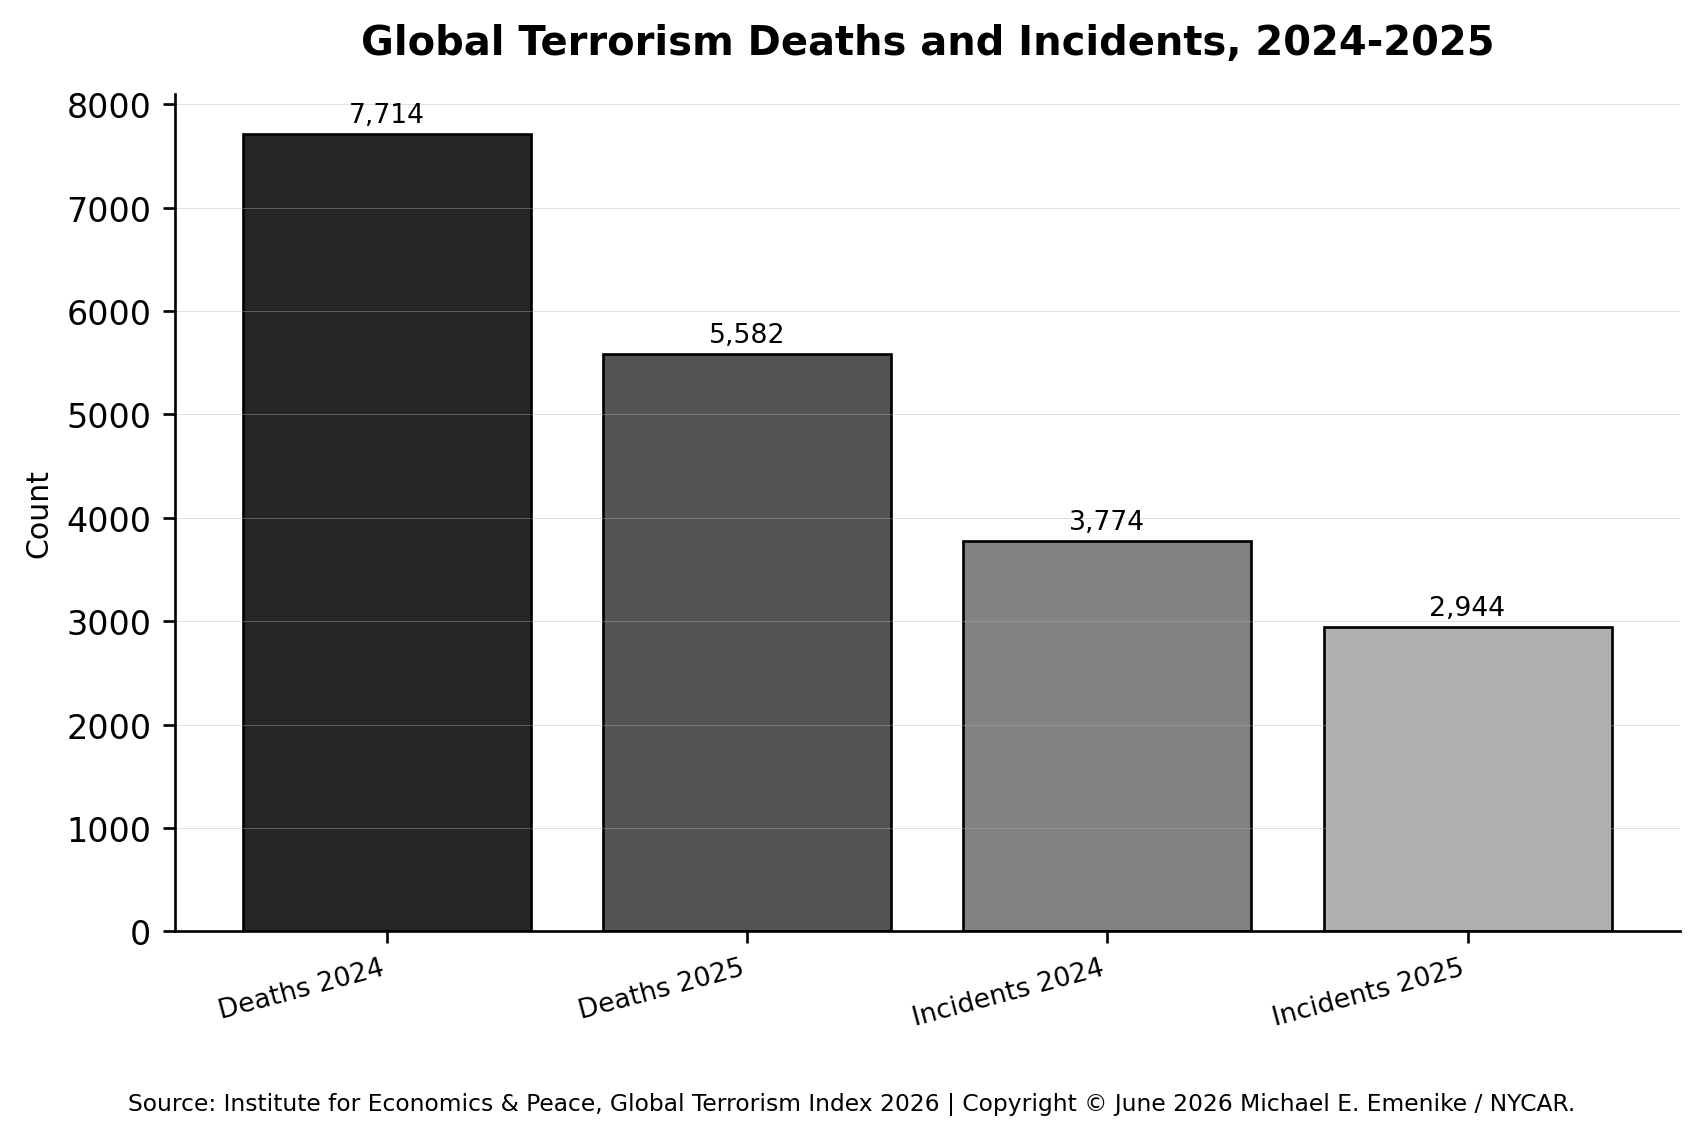
Globally, the picture is mixed. Terrorism deaths and incidents declined in 2025, yet the burden remained sharply concentrated in a small group of countries and corridors. Pakistan, Burkina Faso, Nigeria, Niger, and the Democratic Republic of the Congo carried a major share of global terrorism deaths. Nigeria is especially important for this publication because its 2025 pattern shows civilian exposure, territorial concentration, insurgent adaptation, cross-border pressure, and the continuing importance of public trust in the North-East and the wider Lake Chad Basin.

The publication introduces a Risk-Adjusted Counterterrorism Management Priority Score that combines fatalities, incidents, lethality, and territorial concentration. The model is not a tactical targeting tool. It is a management triage framework for deciding where oversight, prevention, victim support, lawful investigation, service restoration, financing controls, and interagency coordination deserve urgent attention. The central argument is clear: a state can win an encounter and lose the public. Counterterrorism becomes durable only when people become safer, institutions become more trusted, financing channels become harder to exploit, and justice can punish crime without punishing identity.

Keywords: counterterrorism management; public policy; terrorism risk; Nigeria; Sahel; institutional trust; terrorist financing; violent extremism; public safety; risk governance.

Contents

Chapter 1: Introduction – Counterterrorism as Public Management

1.1 The management problem behind the security language

That approach matters because the state is never judged only by the violence it prevents. It is also judged by the pattern of its decisions when fear is high. If checkpoints become opportunities for extortion, if detention becomes indefinite, if families are punished by association, or if victims receive speeches instead of service, the public reads counterterrorism as another form of insecurity. A management lens keeps attention on that everyday record of conduct, where legitimacy is either built quietly or lost permanently.

Strong counterterrorism systems therefore treat operations and administration as inseparable. Intelligence has to reach investigators in a form that can become evidence. Arrests have to reach courts without violating due process. Border information has to move across agencies without becoming a tool for harassment. Victim assistance has to be practical enough to reach the injured, the displaced, and the bereaved. None of this reduces the importance of force against armed groups. It gives force a lawful and institutional frame so that the state does not win one encounter while weakening the confidence needed for the next one.

Counterterrorism is usually discussed in the language of force, intelligence, borders, prosecution, and emergency powers. Those instruments matter. A government that cannot detect, disrupt, investigate, prosecute, or prevent organized violence has failed one of its oldest public duties. Yet the public-management question is larger than the immediate security response. Terrorism is not only an attack on life and property. It is also an attack on public authority, social confidence, territorial order, and the moral credibility of the state. A serious counterterrorism policy therefore has to ask how the state acts before, during, and after violence without turning its own response into another source of grievance.

Many counterterrorism debates weaken themselves when they is that they separate operations from governance. One office talks about military response. Another talks about policing. A development ministry speaks about livelihoods. A justice ministry speaks about prosecution. A finance unit speaks about suspicious transactions. A border agency speaks about movement control. A social-services department speaks about displaced families. Communities experience all of these together. When a market is attacked, when a school is threatened, when a farming village is displaced, or when a border corridor becomes unsafe, public policy does not arrive in neat departmental boxes. It arrives as the presence or absence of credible authority.

For that reason, counterterrorism management should be understood as the disciplined coordination of people, law, intelligence, finance, services, data, legitimacy, and regional cooperation to reduce organized political violence while protecting rights. That definition avoids two poor alternatives. It does not reduce security to welfare programs. It also does not pretend that armed response alone can repair the conditions that armed groups exploit. The master’s-level contribution of this paper is to hold those realities together without softening either one.

Recent evidence supports that approach. Recent public data shows a global decline in terrorism deaths and incidents in 2025, but the same evidence also shows intense concentration in a small number of countries and regions (Institute for Economics & Peace [IEP], 2026). A narrow reading would celebrate the global decline. A stronger public-policy reading asks why the burden remains so heavily clustered in Pakistan, Burkina Faso, Nigeria, Niger, the Democratic Republic of the Congo, and related conflict corridors. Concentration is a management signal. It tells policymakers that risk is territorial, institutional, and social, not merely numerical.

Nigeria is one of the clearest examples. Its terrorism challenge cannot be understood only through the number of attacks. The pattern involves civilian exposure, insurgent adaptation, weak local economies, regional spillover, border management, community fear, displaced populations, and a long struggle for legitimacy in the North-East and adjoining areas. A counterterrorism plan that counts incidents but misses concentration, civilian targeting, and trust erosion will always be late. It will see violence after communities have already absorbed the warning signs.

1.2 Research aim and questions

This research publication aims is to develop a management and public-policy framework for counterterrorism that is evidence-informed, legally defensible, operationally realistic, and attentive to public trust. The study asks how public data should be read when terrorism burden is concentrated, how fatalities, incidents, lethality, and territorial concentration can be combined without reducing communities to risk labels, and how Nigeria, the Sahel, and Pakistan can be compared without pretending that their histories are the same.

It also asks how states can strengthen security while reducing the legitimacy costs that arise from abusive, careless, or poorly coordinated responses. That question is central because counterterrorism policy is not judged only by what it interrupts. It is judged by whether citizens become safer, whether criminal cases become stronger, whether communities are less exposed to recruitment pressure, and whether the justice system can punish crime without punishing identity.

1.3 Why this topic belongs at master’s level

At this level, the issue is not whether violent extremism should be condemned. It is how a public institution should think when evidence is incomplete, resources are scarce, and every action carries political and human consequences. A master’s-level treatment must therefore move beyond general security language. It has to show how managers set priorities, read data with caution, supervise agencies, protect rights, and measure whether policy has made communities safer rather than merely more controlled.

A master’s-level paper should not only describe terrorism trends. It should show how a public manager can use evidence to make better decisions. The question is not simply whether terrorism exists, or whether it is morally wrong. Those points are settled. The harder question is how a government allocates scarce resources when threats differ in severity, when intelligence is incomplete, when public trust is fragile, and when rights violations can strengthen the propaganda of violent groups.

The analysis therefore avoids theatrical security language and stays with management: priority setting, interagency coordination, risk scoring, service restoration, financial oversight, lawful investigation, communication with communities, reintegration where it fits, and monitoring. These are the daily disciplines that decide whether a policy becomes real or stays a sentence in a national plan.

Operational details that could assist violent actors are deliberately avoided that could assist violent actors. It does not discuss tactical methods, attack planning, evasion, or weaponization. Its concern is protective public policy. The intended reader is a public manager, security-policy analyst, community-safety leader, development partner, or scholar who needs a rigorous but usable framework for reducing harm.

1.4 Contribution of the paper

Conceptually, the publication The paper defines counterterrorism management as a public-policy function, not a military label. That distinction matters because it moves the analysis from reaction to system design. A government may need force to stop armed groups, but it needs management to prevent repetition, coordinate agencies, protect evidence, support victims, reduce recruitment pressure, and maintain legality.

Analytically, the publication The paper introduces a Risk-Adjusted Counterterrorism Management Priority Score. The model is deliberately simple. It combines deaths, incidents, lethality, and territorial concentration because these four measures answer different management questions. Deaths show harm. Incidents show operational tempo. Lethality shows severity per incident. Concentration shows whether public authority is failing in particular geographic or institutional spaces.

In practical terms, the publication The paper converts the literature and public data into a policy framework that can be used in planning, monitoring, and review. The framework is not a universal cure. It is a disciplined way of asking the right questions before public money, coercive power, and community confidence are spent.

Chapter 2: Literature and Policy Context

2.1 Counterterrorism policy after the era of single-instrument thinking

Modern counterterrorism literature and policy record have moved away from the belief that one instrument can solve terrorism. Military response may disrupt armed capacity. Policing can investigate and arrest suspects. Courts can punish crime. Financial intelligence can make funding more difficult. Border systems can manage movement. Development programs can reduce grievance and exposure. Community engagement can improve early warning. None of these instruments is enough on its own. The policy challenge is to govern them together without allowing one instrument to damage the others.

United Nations Global Counter-Terrorism Strategy reflects that broader understanding by placing prevention, capacity building, human rights, rule of law, and international cooperation within the same global framework (United Nations General Assembly, 2023). Security Council Resolution 2396 extended attention to foreign terrorist fighters, border control, information sharing, biometric data, prosecution, rehabilitation, and reintegration, while requiring compliance with domestic and international law (United Nations Security Council, 2017). Resolution 2462 strengthened the international focus on terrorist financing and called on states to prevent and suppress the financing of terrorist acts (United Nations Security Council, 2019).

These instruments are important because they reject a careless divide between hard and soft policy. A state needs lawful coercive capacity, but it also needs accountability and prevention. The United Nations Office on Drugs and Crime has emphasized the international law context of counterterrorism, including the need to respect legality, due process, and human rights in criminal justice responses (UNODC, 2021). Public trust is not a sentimental add-on. It is part of the operating environment in which intelligence, reporting, cooperation, prosecution, and reintegration either work or fail.

2.2 Public evidence on concentration and risk

Concentration should also change the way success is discussed. A national reduction may be real, yet meaningless to a village, province, or border corridor where violence continues. The public manager’s responsibility is to prevent averages from concealing danger. When a small number of places carry a large share of deaths, the policy response must become geographically honest: more accurate local intelligence, stronger district administration, better victim services, and credible security presence where the risk is actually borne.

Global Terrorism Index 2026 provides a useful public evidence base because it shows both the decline and the continuing concentration of terrorism harm. It reported 5,582 terrorism deaths across 2,944 incidents in 2025, representing a decline from the previous year, while also showing that nearly seventy percent of global terrorism deaths occurred in five countries (IEP, 2026). The combined message is important. A lower global total does not mean that the management problem has become simple. It means that policy should become more precise.

Concentration is more than a statistical feature. It is a clue about governance. Where terrorism is concentrated, the state often faces a combination of geography, weak local authority, illicit financing, contested legitimacy, regional spillover, distrust between security forces and communities, and limited social services. In such settings, terrorism is not just a police file. It is a public-administration crisis that shows up in roads, courts, schools, humanitarian access, farming cycles, border markets, mobile money flows, and public fear.

Public data also warns against shallow success claims. A country may record fewer attacks but more deadly attacks. Another may show fewer deaths but rising hostage-taking. Another may show a national decline while one province remains trapped in violence. A public manager who reads only national totals may therefore reward the wrong policy. The management task is to read trend, concentration, target type, lethality, and institutional capacity together.

2.3 Recruitment, grievance, and the limits of coercion

Recruitment evidence has to be handled with care. Economic pressure, grievance, or abuse may help explain vulnerability, but they do not remove personal responsibility for violence. The public-policy value of the evidence lies elsewhere. It helps the state close the openings that violent groups use: unemployment without credible alternatives, humiliating encounters with authority, unresolved local conflict, revenge after abuse, and communities that see no lawful route for protection. Prevention is not indulgence. It is the removal of avoidable opportunities for recruitment.

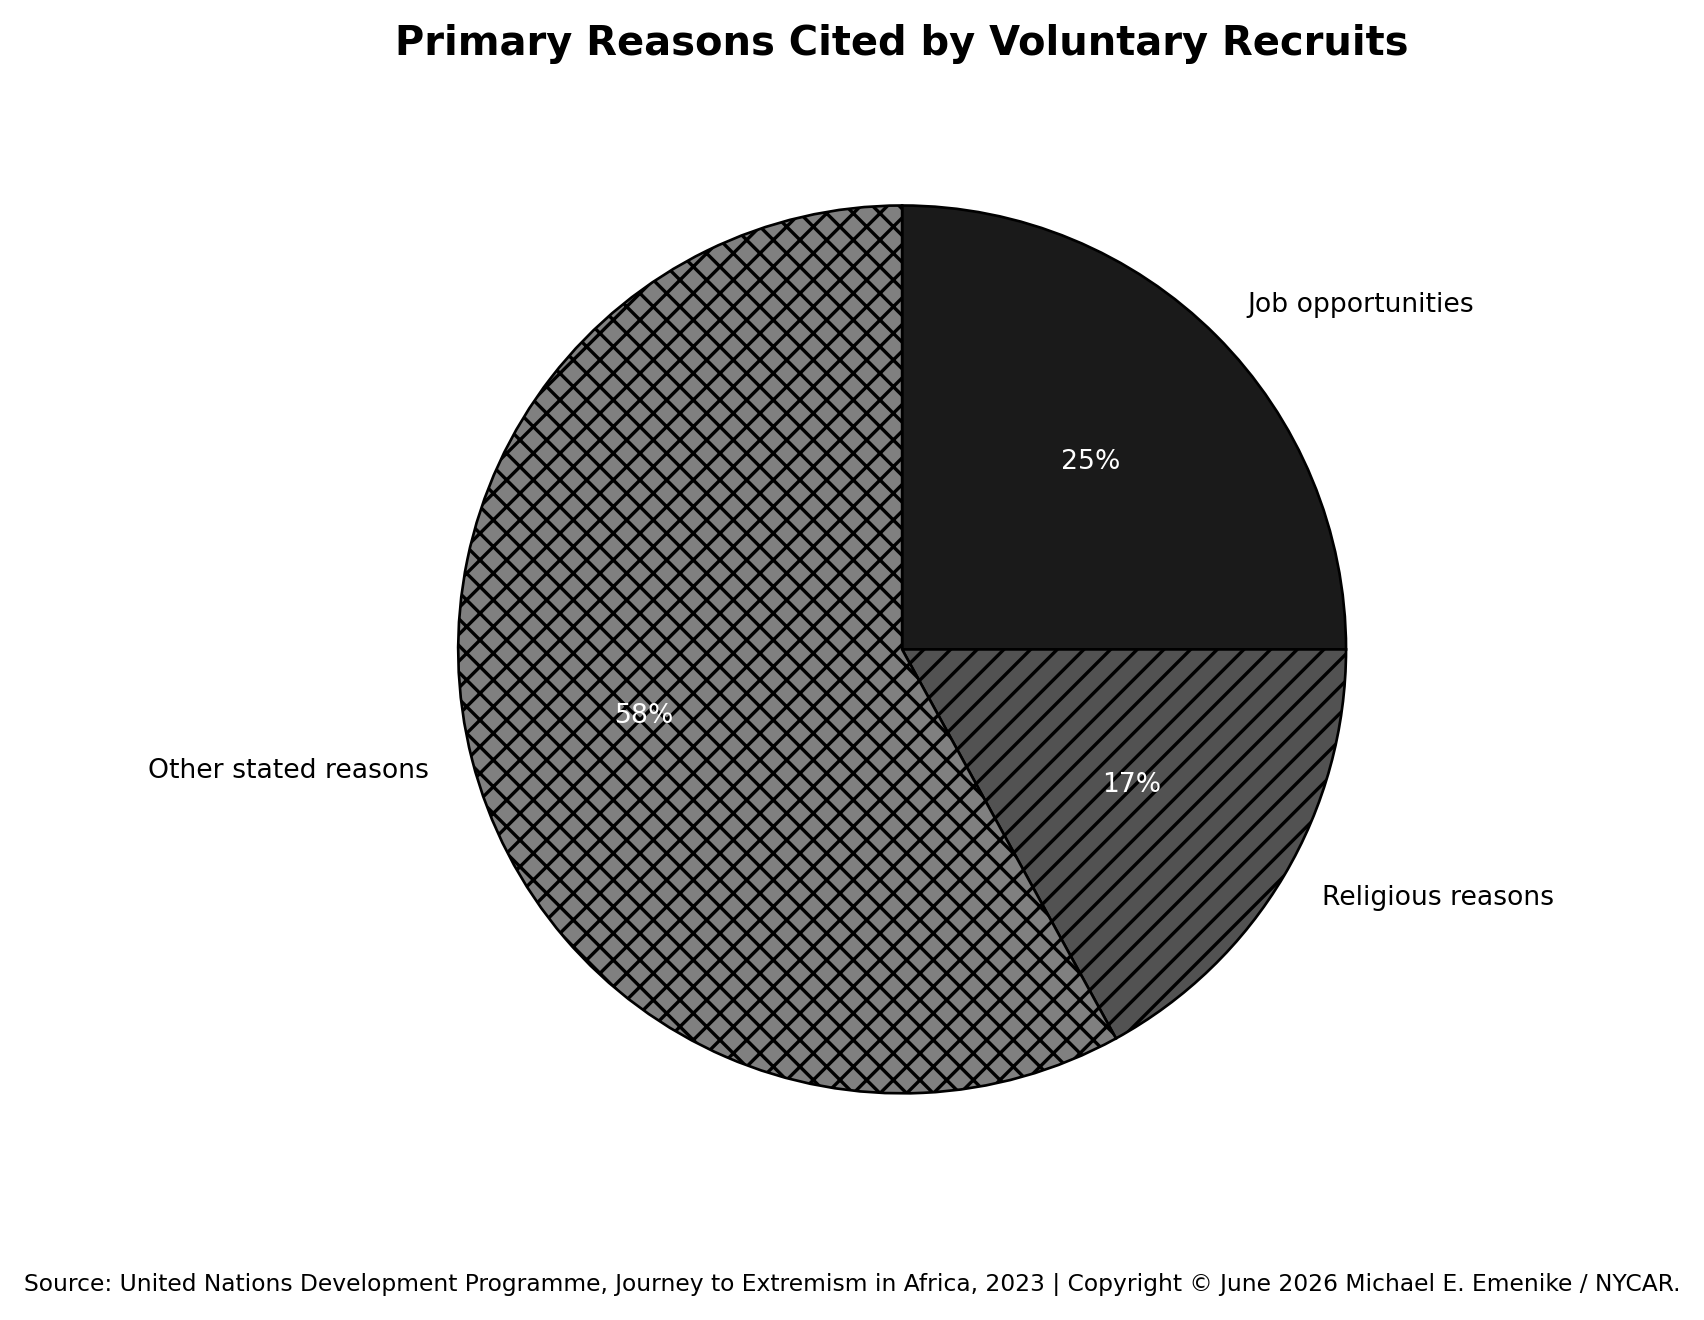
UNDP’s Journey to Extremism in Africa is especially useful because it treats recruitment as a lived process rather than an abstract theory. The 2023 study reported that one-quarter of voluntary recruits cited job opportunities as their primary reason for joining, while religion was the third most common reason at seventeen percent. It also found that nearly half of voluntary recruits pointed to a specific trigger event, and among those who did, seventy-one percent cited human rights abuse, often by state security forces (United Nations Development Programme [UNDP], 2023).

Those findings do not excuse violent groups. They clarify the public-policy environment in which those groups recruit. A government that responds to terrorism with indiscriminate force, arbitrary detention, communal stigmatization, or abuse may weaken the very legitimacy it needs to defeat armed groups. In practical terms, abuse can damage intelligence flow, discourage witnesses, deepen fear, and give violent organizations material for recruitment narratives.

For public managers, the lesson is direct. Counterterrorism policy should reduce the supply of recruits as well as the capacity of armed groups. That means protecting communities from violence while also protecting them from state misconduct. It means that rights safeguards, complaint systems, disciplined detention procedures, compensation for wrongful harm, and public communication are not soft distractions. They are tools for preserving the credibility of the state.

2.4 Terrorist financing and institutional controls

Violent organizations need money, material support, movement, communication, and social cover. Terrorist financing policy is therefore a central part of counterterrorism management. FATF’s 2025 recommendations require countries to identify risks, develop coordinated policies, improve financial transparency, support operational responsibilities, and cooperate internationally (Financial Action Task Force [FATF], 2025). The same standards recognize that controls must be focused and risk-based, especially when nonprofit organizations and humanitarian actors are involved.

This balance matters. Poorly designed financial controls can damage civil society and humanitarian assistance without seriously disrupting violent groups. Overbroad derisking may push transactions underground, reduce community services, or punish lawful organizations working in high-risk areas. A stronger approach separates risk-based supervision from suspicion by association. It asks which channels are vulnerable, which controls are proportionate, and which legitimate activities must be protected.

A public manager should therefore treat terrorist financing as an interagency problem. It involves banks, mobile-money operators, customs, police, intelligence services, prosecutors, nonprofit regulators, humanitarian agencies, and regional partners. If those actors work in isolation, the system either misses abuse or overreacts to lawful activity. The counterterrorism-finance function should be precise enough to find risk and restrained enough not to damage public trust.

2.5 Public trust as a security asset

Trust is also a form of time. Communities that trust institutions report early, cooperate before a crisis hardens, and accept lawful intervention before rumor takes control. Communities that do not trust the state wait, hide, negotiate informally, or seek protection from actors who may later exploit them. In counterterrorism management, late information is often expensive information. A trusted system hears weak signals while they are still manageable.

Public trust is often discussed in moral language, but it is also a security asset. Communities provide information when they believe that information will not expose them to retaliation, collective punishment, or police abuse. Witnesses cooperate when they trust the justice process. Families report radicalization concerns when they believe the state will respond responsibly. Local leaders help with prevention when they are not treated as suspects by default. Trust is not automatic. It is earned through conduct.

Policy evidence therefore points to a practical conclusion. Counterterrorism management should be measured by more than arrests, raids, or funding seizures. It should also measure complaint resolution, lawful detention, case quality, community reporting, victim support, service restoration, financial-control precision, and reintegration outcomes. These measures do not weaken security. They show whether security is becoming sustainable.

Table 2. Literature and Policy Sources Used in the Study

Evidence area Key source Policy use in this paper
Global trend evidence IEP, 2026 Shows deaths, incidents, concentration, and country burden; supports risk-based priority setting.
Recruitment pathways UNDP, 2023 Links recruitment to employment pressure, trigger events, and abuse; supports prevention and trust-based policy.
Foreign terrorist fighters and border systems UN Security Council, 2017 Connects border management, information sharing, prosecution, rehabilitation, and reintegration.
Terrorist financing UN Security Council, 2019; FATF, 2025 Frames financial suppression, risk assessment, transparency, and international cooperation.
Rule of law and criminal justice UNODC, 2021 Places counterterrorism inside legality, due process, and human rights obligations.
Global policy coordination UN General Assembly, 2023 Treats counterterrorism as a comprehensive strategy involving prevention, rights, and cooperation.


Chapter 3: Methodology and Data Integrity

3.1 Research design

The research design also recognizes a safety boundary. A publication of this kind should not describe tactical procedures, operational vulnerabilities, or methods that could be reversed by violent actors. The useful contribution lies in governance: how to read public data, how to protect evidence quality, how to coordinate institutions, how to preserve legality, and how to evaluate whether the public receives more safety rather than another layer of fear.

The research uses an integrative, literature-based design supported by descriptive quantitative analysis. It makes no claim to interviews, surveys, field observation, classified intelligence review, or operational evaluation; the purpose runs in a different direction. It gathers recent public evidence, reads it through a public-management lens, and turns it into a policy framework for counterterrorism governance.

This design is suitable for a master’s-level publication because counterterrorism management is a field where ethical and evidentiary restraint matter. Fabricated field data would weaken the paper. Speculative operational detail would be irresponsible. A public-data approach allows the paper to make a careful argument: the available evidence is sufficient to show how policy priorities should be organized, but not sufficient to claim certainty about every local driver or operational outcome.

Evidence in the analysis combines three forms of evidence. The first is trend and burden evidence, mainly from the Global Terrorism Index 2026. The second is policy evidence from United Nations instruments, UNODC materials, and FATF recommendations. The third is recruitment and prevention evidence from UNDP’s Journey to Extremism in Africa. Together, these sources support a framework that is both security-aware and governance-aware.

3.2 Source selection criteria

Source discipline is part of security discipline. In a field where rumor, propaganda, and political accusation travel quickly, a publication cannot rely on dramatic claims simply because they sound plausible. The selected sources were chosen because they are public, traceable, and relevant to management decisions. That standard protects the argument from two weaknesses common in security writing: inflated certainty and evidence used only as decoration.

Sources were selected against five criteria. They had to be recent, preferably from 2017 onward. They had to come from recognized public institutions, international organizations, or reputable evidence producers. They had to speak directly to counterterrorism, terrorism trends, extremist recruitment, terrorist financing, criminal justice, public policy, or conflict governance. They had to be usable without classified information. And they had to support management judgment rather than serve as decorative citation.

Table 3. Source Selection Criteria

Criterion Application
Recency Most sources are from 2017-2026, keeping the paper within the requested current-publication window.
Credibility Priority was given to IEP, UNDP, United Nations bodies, FATF, UNODC, and World Bank policy material.
Policy relevance Sources were chosen because they can inform management decisions, not because they are rhetorically convenient.
Transparency The paper uses public evidence and states its limitations.
Safety The paper avoids tactical or procedural details that could assist violent actors.


3.3 Case selection

Three case clusters organize the study. The first is Nigeria and the Lake Chad Basin because Nigeria remains one of the most affected countries and because its violence pattern raises management questions about civilian protection, territorial concentration, insurgent adaptation, and regional cooperation. The second is the Sahel, including Burkina Faso, Niger, and Mali, because the area shows how state fragility, border space, local grievance, and armed-group expansion can overwhelm conventional security administration. The third is Pakistan because recent data shows high deaths, high incident volume, hostage-taking, and heavy burden in border provinces.

None of the cases is treated as identical. Nigeria is not Burkina Faso, Burkina Faso is not Pakistan, and Pakistan is not Niger. The paper uses them to examine common management questions: where is harm concentrated, who is targeted, how lethal are the incidents, how credible is state authority, and which policy instruments need to be joined rather than separated?

3.4 Data use and limitations

Data integrity is especially important in violent settings because numbers can acquire political force. A government may have an incentive to report improvement, an armed group may exaggerate harm to project power, and communities may underreport because they fear retaliation or distrust authorities. The publication therefore treats each number as a signal that needs context. A table can point to risk, but it cannot replace local verification, survivor testimony, court records, service data, and community feedback.

Figures in this publication are descriptive. They help readers see burden and concentration. They do not prove causality. For example, a high number of deaths can reflect armed-group capacity, state weakness, reporting quality, conflict intensity, geographic exposure, or a combination of these. A decline in deaths can reflect better security, temporary armed-group withdrawal, underreporting, displacement, negotiations, or changes in target selection. Public data therefore needs interpretation.

The publication also distinguishes between count data and management meaning. Deaths, incidents, and target shares are not policy by themselves. They become useful only when read against institutional capacity, community trust, justice reach, financing channels, border control, and prevention programs. This is why the paper introduces a simple scoring model. The model does not replace judgment. It disciplines judgment by forcing decision makers to compare several dimensions of risk at the same time.

The paper also avoids operational prescription. It does not identify tactical vulnerabilities, suggest attack-prevention details that could be reversed, or describe security procedures in a way that could aid violent actors. Its recommendations stay at the level of public policy, management oversight, institutional coordination, rights safeguards, and service design.

Chapter 4: Analytical Model for Counterterrorism Management Priority

4.1 Why a management model is needed

Public managers often face a practical problem that academic discussion can hide. Several districts, border corridors, or agencies may all claim urgent need at the same time. One area may have many incidents but fewer deaths. Another may have fewer incidents but unusually high lethality. A third may have most of the national burden concentrated in one province. A fourth may show a recruitment pattern tied to unemployment, abuse, or local grievances. Without a disciplined framework, priority setting becomes political, emotional, or reactive.

A useful model should not pretend to predict terrorism with certainty. It should do something more modest and more practical: help leaders organize attention. The model in this paper is designed for public-policy triage. It supports decisions about where to strengthen oversight, victim support, lawful investigation, prevention programs, financial controls, border coordination, service restoration, and community communication.

4.2 Risk-Adjusted Counterterrorism Management Priority Score

Its purpose is disciplined comparison. It asks managers to avoid the common mistake of treating the loudest political demand as the highest policy priority. A place with fewer incidents may deserve urgent attention if each incident is unusually lethal. Another place may need administrative repair if violence is clustered so tightly that public authority is visibly absent. RCMPS gives leaders a common language for such discussions while still leaving room for professional judgment.

At the center of the quantitative section is the Risk-Adjusted Counterterrorism Management Priority Score, abbreviated as RCMPS. It combines four dimensions: fatalities, incidents, lethality, and territorial concentration. The formula is:

RCMPS_i = 100 × [0.40(D_i / D_max) + 0.20(A_i / A_max) + 0.25(L_i / L_max) + 0.15C_i]

Where D_i is terrorism-related deaths in case i; A_i is the number of incidents in case i; L_i is lethality, calculated as deaths divided by incidents; C_i is the concentration ratio, meaning the share of deaths or incidents located in the worst-affected subnational area where such data is available; and D_max, A_max, and L_max are the highest values in the comparison set. The score runs from 0 to 100, with higher values indicating greater management priority.

Table 4. Variables in the RCMPS Model

Symbol Meaning Management value
D_i Deaths Shows total human harm and political urgency.
A_i Incidents Shows operational frequency and pressure on policing, justice, and response systems.
L_i Deaths divided by incidents Shows severity per incident; detects low-frequency but high-impact violence.
C_i Territorial concentration ratio Shows whether harm is clustered in a province, state, border corridor, or district.
Weights 0.40, 0.20, 0.25, 0.15 Prioritize human harm while keeping operational tempo, lethality, and concentration visible.


4.3 Why these weights are appropriate

These weights are not presented as universal law. They are a reasoned starting point for discussion by public managers who need a transparent way to compare burdens. A different country or agency may adjust the model after testing it against local data, but the principle should remain: human harm, operational tempo, severity, and concentration must be considered together. A model that sees only deaths can miss pressure on institutions; a model that sees only incidents can miss the depth of harm.

RCMPS gives the highest weight to deaths because the first duty of public safety policy is the protection of life. Incidents receive a lower but still important weight because frequency strains police, hospitals, courts, intelligence units, local government, transport systems, schools, and humanitarian services. Lethality receives a strong weight because a small number of incidents can still produce strategic harm if each incident is deadly. Territorial concentration receives a smaller weight because it is not harm by itself, but it is an important management signal. Where risk is highly concentrated, public authority is often failing in a specific space that deserves targeted governance attention.

Deliberate transparency is one of the formula’s strengths. It can be debated, adjusted, and improved. That is a strength. A public model that cannot be challenged becomes a black box. A simple model allows managers, researchers, and oversight bodies to ask whether the weights reflect current policy objectives. For example, a victim-centered agency might increase the weight on fatalities and survivor support. A border-management review might increase the concentration term. A prevention program might add recruitment pressure, school closure, youth unemployment, or displacement indicators.

RCMPS is not designed to rank communities as dangerous. It ranks management priority. That distinction is crucial. Communities affected by terrorism are not the enemy. They are often the victims. A high score should trigger more protection, better services, stronger lawful investigation, and more accountable institutions, not collective punishment.

4.4 Example application using Nigeria

Nigeria’s 2025 public figures illustrate how the model works. IEP reported 750 terrorism deaths and 171 incidents in Nigeria in 2025. That produces a simple lethality figure of approximately 4.39 deaths per incident. The same source reported that Borno State accounted for a dominant share of Nigeria’s terrorism burden in 2025, including seventy-two percent of terrorism deaths. In RCMPS terms, Nigeria would therefore register substantial fatalities, significant incident volume, high lethality, and high territorial concentration.

The management implication is not that Nigeria needs one more general security slogan. It needs concentrated public-policy capacity where the burden is highest: civilian protection, lawful intelligence gathering, community reporting channels, victim assistance, displaced-person support, cross-border cooperation, school and market protection planning, and credible justice. A model is useful only when it changes the question from “Where did attacks happen?” to “What public functions must now be strengthened there?”

4.5 Safeguards against misuse

Misuse is not a theoretical concern. In fragile environments, risk labels can travel quickly into identity suspicion, discrimination, or collective punishment. That is why any score should be held inside a rights-based review process. A high score should bring more protection, faster services, better case work, and stronger oversight. It should never become permission to treat a town, ethnic group, religious community, or displaced population as guilty by geography.

Any risk model can be misused. A counterterrorism score can become dangerous if it is treated as a label for entire communities. It can also become misleading if poor data quality, underreporting, or political pressure distort the inputs. The RCMPS should therefore be used with safeguards: independent review, transparent data sources, community impact assessment, human-rights checks, and periodic recalibration.

RCMPS should never be used to justify mass arrest, ethnic profiling, religious suspicion, or punishment by geography. Its purpose is to help public managers direct protection, services, lawful investigation, and oversight where the evidence indicates serious harm. In a responsible system, higher risk means higher duty of care.

Chapter 5: Global Burden and Policy Signal from Public Data

5.1 Global decline does not remove concentrated burden

A fall in global totals should be read as an opening for better management, not as proof that the problem is settling itself. When the overall trend improves, leaders have a chance to examine what worked, where violence shifted, and which institutions remain fragile. That review is usually more valuable than celebration, because terrorist organizations adapt to pressure and public systems can mistake a temporary reduction for durable control.

The global terrorism picture in 2025 contains a policy paradox. The headline numbers improved, but the burden remained severe in specific countries and corridors. According to the Global Terrorism Index 2026, deaths fell to 5,582 and incidents fell to 2,944 in 2025. That decline matters and should be acknowledged. It suggests that global terrorism harm can move downward. Yet the same data shows that risk remains concentrated, with Pakistan, Burkina Faso, Nigeria, Niger, and the Democratic Republic of the Congo carrying a disproportionate share of deaths (IEP, 2026).

For counterterrorism management, the decline should not produce complacency. A smaller global number can still hide intense local suffering. Public policy is implemented in provinces, districts, border towns, courts, schools, markets, banks, and communities. The question is not whether the global aggregate improved. The question is whether the people living inside high-burden areas experience a credible change in safety and governance.

Figure 1. Global terrorism deaths and incidents, 2024-2025. Source: Constructed from Institute for Economics & Peace (2026). Copyright © June 2026 Michael E. Emenike / NYCAR.

5.2 Country burden and the need for differentiated policy

Differentiated policy also protects resources. A single national template wastes money because it funds the same activities in places that need different forms of support. A high-incident environment may need investigators, prosecutors, and forensic capacity. A high-civilian-fatality environment may need village protection, trauma services, safer routes to farms and markets, and stronger early warning. A high-concentration environment may need local government restoration before national announcements have any meaning on the ground.

Country comparisons are useful when they show difference rather than when they create false sameness. Pakistan’s 2025 burden involved high deaths, high incident volume, severe injury levels, and significant hostage-taking. Burkina Faso recorded fewer incidents than Pakistan but very high deaths. Nigeria recorded both a large death toll and a heavy civilian burden. Niger’s burden reflected serious violence with strong territorial concentration. The Democratic Republic of the Congo carried a large share of deaths linked to armed-group violence in the east. These differences call for different policy packages.

A country with many incidents may need stronger investigative, local-policing, judicial, and intelligence case-management capacity. A country with fewer but deadlier attacks may need improved early warning, civilian protection, emergency medical response, and protection of vulnerable settlements. A country with high civilian targeting needs public communication, victim support, and community trust mechanisms. A country with high territorial concentration needs local government restoration, service delivery, and accountable security presence in the affected areas.

Figure 2. Selected high-burden countries by terrorism deaths in 2025. Source: Constructed from Institute for Economics & Peace (2026). Copyright © June 2026 Michael E. Emenike / NYCAR.

5.3 Increases matter even when global totals fall

A global decline can coexist with sharp country-level deterioration. That is why policy dashboards should show both total burden and year-on-year increases. Nigeria recorded the largest increase in terrorism deaths from 2024 to 2025 among the listed countries in the Global Terrorism Index 2026. The Democratic Republic of the Congo, Colombia, Benin, and Pakistan also recorded notable increases. This matters because deterioration often signals adaptation by armed groups, failure of local protection, new geographic spread, or pressure on public institutions.

Increases are especially important for early policy review. A country may not yet be the highest-burden country in absolute terms, but a sharp increase can show that existing controls are failing. Managers should therefore avoid waiting until a deterioration becomes a national crisis. A good system identifies acceleration early and asks what changed: leadership, funding, border movement, intergroup alliance, local grievance, prosecution capacity, or community cooperation.

Figure 3. Largest country increases in terrorism deaths, 2024-2025. Source: Constructed from Institute for Economics & Peace (2026). Copyright © June 2026 Michael E. Emenike / NYCAR.

5.4 The concentration pattern

Concentration also has implications for international support. Donor programs often prefer national-level capacity building because it is administratively easier to fund and report. Yet high-burden areas may need more local and patient work: courts that can sit, schools that can reopen, police posts that are trusted, trauma services that reach survivors, and transport corridors that ordinary people can use. The concentration pattern therefore challenges both governments and partners to prove that their spending follows the geography of harm.

The strongest signal in the public data is concentration. Almost seventy percent of global terrorism deaths in 2025 occurred in five countries. That share is not an academic curiosity. It is a policy instruction. It tells international partners, regional organizations, humanitarian agencies, and national governments that counterterrorism capacity should be matched to burden, but also tailored to the political and social conditions of each place.

Concentration also warns against generalized counterterrorism spending. A national government can spend heavily and still miss the communities most exposed to risk. A donor can fund national training without improving the district where violence is clustered. A police reform can improve headquarters capacity while leaving the rural corridor unchanged. The concentration pattern requires counterterrorism management to become geographically literate.

Figure 4. Share of global terrorism deaths by country, 2025. Source: Constructed from Institute for Economics & Peace (2026). Shares rounded to whole percentages. Copyright © June 2026 Michael E. Emenike / NYCAR.

5.5 What the global data cannot show

A second limitation is human experience. Datasets rarely show how a mother decides whether to send a child back to school, how a trader prices the risk of a road journey, or how a young man interprets humiliation at a checkpoint. These experiences do not fit neatly into global indices, yet they shape the environment in which violence either recedes or returns. Good policy keeps quantitative evidence in conversation with human knowledge, not above it.

Charts show burden, but they do not show everything a manager needs. They do not show the quality of local justice, the fear inside households, the reliability of witness protection, the political economy of armed groups, the trauma of survivors, the informal taxation of communities, or the reasons people do not trust state officials. A good public manager uses the charts as a starting point, not as a substitute for local knowledge.

Public data also cannot fully separate terrorism from wider conflict where armed groups, criminal networks, militias, insurgents, and state forces operate in overlapping spaces. Classification is difficult. Public data remains useful, but it must be handled with care. The stronger policy conclusion is therefore modest: public evidence can help prioritize attention, but legitimate action still requires context, legality, and local accountability.

Chapter 6: Nigeria and the Lake Chad Basin

6.1 Nigeria as a counterterrorism management case

Nigeria’s case also shows that security policy must be able to hold several truths at once. Armed groups must be disrupted, but communities must also be protected from the social and administrative collapse that violence produces. A village that has lost teachers, traders, health workers, local records, and trust in police cannot be stabilized by patrols alone. The management task is to rebuild the public functions that make security believable.

Nigeria is a central case because its terrorism problem is not only violent; it is administratively complex. The challenge involves Boko Haram factions, ISWAP, local insecurity, regional spillover, border movement, displacement, informal economies, weak service delivery in affected communities, political distrust, and a long history of security pressure in the North-East. A policy that treats the problem as a single armed-group question will miss the public-management burden carried by civilians, schools, health facilities, farmers, traders, local government, and displaced families.

IEP reported 750 terrorism deaths and 171 incidents in Nigeria in 2025, with attacks rising from the previous year. It also reported that ISWAP and Boko Haram were responsible for most terrorism-related deaths, while Borno State accounted for the overwhelming share of attacks and deaths (IEP, 2026). These figures point to a simple but demanding conclusion: Nigeria’s counterterrorism management should be concentrated where the burden is concentrated, but it should not be limited to armed response.

Nigeria’s case also shows why civilian protection belongs at the center of counterterrorism policy. When civilians carry most of the fatalities, the policy test changes. It is not enough to count militants killed or suspects arrested. Public institutions must ask whether markets reopen, children return to school, displaced people can move safely, farmers can access land, and communities can report threats without fear. These are not peripheral measures. They are evidence that public authority is returning.

Figure 5. Nigeria terrorism fatalities by target category, 2025. Source: Constructed from Institute for Economics & Peace (2026). Copyright © June 2026 Michael E. Emenike / NYCAR.

6.2 Civilian exposure and public legitimacy

Nigeria’s civilian burden also creates a communication duty. People who live under threat need accurate information without propaganda, reassurance without exaggeration, and channels for reporting that do not expose them to retaliation. Public silence after attacks can look like abandonment; careless triumphalism can look like denial. The state must learn to speak in a way that recognizes grief, explains action, and protects ongoing investigations without turning victims into public relations material.

Nigeria’s target profile is a management warning. When civilians account for most deaths, counterterrorism must protect everyday life. That means improving the security of transport corridors, markets, worship places, farms, schools, health facilities, and displacement sites. It also means strengthening emergency response, victim assistance, trauma support, and community reporting systems. A policy that focuses only on armed encounters can leave civilian life dangerously exposed.

Civilian exposure also affects legitimacy. People judge the state not by national strategy documents but by what happens when they report a threat, seek protection, visit a police station, return to a village, or ask for support after an attack. If they meet indifference, abuse, extortion, or delay, trust collapses. Violent groups do not need to defeat the state everywhere. They need to make the state look absent, predatory, or unreliable in enough places.

This is why Nigeria’s counterterrorism management should be tied to public administration. Local government, schools, courts, health agencies, humanitarian partners, traditional authorities, religious leaders, youth organizations, and women’s networks should be part of the prevention and recovery system. The state should not outsource security to communities, but it should stop treating communities as passive recipients of orders.

6.3 Border management and Lake Chad cooperation

Lake Chad’s lesson is that border security cannot be separated from border livelihood. People cross for trade, family, farming, fishing, worship, and refuge. Armed groups exploit the same routes, but a policy that treats every movement as suspicious can damage the cooperation needed to identify real risk. Strong border management therefore needs intelligence, lawful identity systems, anti-corruption safeguards, humanitarian referral, and respect for legitimate movement. A hard border that is blind to livelihood may simply drive communities and criminals into the same informal paths.

Nigeria’s terrorism burden cannot be separated from regional geography. The Lake Chad Basin links Nigeria, Niger, Chad, and Cameroon through movement, trade, displacement, and armed-group mobility. Public policy therefore needs regional cooperation that is more practical than communiques. Border agencies, police, customs, immigration, intelligence services, prosecutors, and humanitarian actors need shared procedures that protect civilians while disrupting violent networks.

Security Council Resolution 2396 is relevant here because it places border control, information sharing, watchlists, biometrics, prosecution, rehabilitation, and reintegration within one international framework (United Nations Security Council, 2017). For Nigeria and its neighbors, the lesson is that border policy should not be reduced to a checkpoint. It should be a governed system: identity management, lawful information exchange, human-rights training, referral procedures for children and victims, anti-corruption controls, and clear channels for cross-border casework.

A poorly governed border can harm both security and livelihoods. Excessive harassment of traders and travelers can push movement into informal routes, weaken local economies, and reduce cooperation. Weak control can allow armed groups to move, tax, recruit, and resupply. The management goal is therefore balance: serious control, lawful conduct, accurate data, and respect for legitimate movement.

6.4 Recruitment pressure and prevention in Nigeria

UNDP’s recruitment findings have direct relevance for Nigeria. If job opportunities, trigger events, abuse, and local grievance play a role in recruitment, then prevention must be more than messaging. Young people in high-risk areas need credible alternatives, not slogans. Communities need protection from armed groups and protection from misconduct by security actors. Families need channels for early intervention that do not expose them to retaliation or humiliation.

Prevention should be designed around local evidence. A district where recruitment is linked to unemployment requires livelihood pathways and market access. A district where recruitment is linked to revenge after abuse requires accountability, complaint handling, and a credible justice response. A district where recruitment is linked to coercion requires protection, safe reporting, and support for escape or disengagement. One national prevention template cannot carry all of these differences.

Ownership is the management standard. Every prevention program should have a named public owner, a budget line, a target group, an implementation timeline, a complaint mechanism, and outcome measures. Without those details, prevention becomes a donor phrase rather than a public function.

Figure 6. Primary reasons cited by voluntary recruits in UNDP’s Journey to Extremism in Africa. Source: Constructed from United Nations Development Programme (2023). Copyright © June 2026 Michael E. Emenike / NYCAR.

6.5 Nigeria policy priorities

A further priority is the link between security and ordinary administration. Identity documents, school reopening, clinic staffing, market access, road repair, and land-use security may appear outside the narrow vocabulary of counterterrorism, but they decide whether civilian life can resume. Armed groups exploit spaces where the state appears only as force and not as service. Nigeria’s long-term policy strength will depend on whether people in affected areas meet government as protection, justice, and practical presence, not only as a security operation.

Nigeria’s policy priorities should follow the evidence rather than the loudest demand. Civilian protection comes first, treated as a measurable counterterrorism outcome instead of a slogan. Borno and the worst-affected adjoining areas need concentrated management attention that brings security, courts, services, displaced-person support, and local governance together in the same place. Financial intelligence has to be tied to ground knowledge of informal taxation, extortion, ransom, and illicit flows, and tied with care, so that legitimate commerce and humanitarian work are not strangled in the process. And the complaint and accountability system for security operations needs strengthening, because misconduct left unanswered becomes a recruitment gift to the groups the state is trying to defeat.

Fifth, Nigeria should improve interagency case management. Intelligence that cannot become lawful evidence is often wasted. Arrest without prosecution can become grievance. Prosecution without witness protection can collapse. Military pressure without civil restoration can create repeated cycles of clearance and return. A public manager should therefore ask not only whether an operation occurred, but whether the whole chain of protection, evidence, justice, services, and trust moved forward.

Chapter 7: Sahel and Pakistan Case Lessons

7.1 Burkina Faso, Niger, and Mali: the Sahel management lesson

Sahel cases also expose the weakness of policies that treat territory as empty space. Borderlands are lived economies. They contain herders, farmers, traders, families, migrants, religious networks, and local authorities. When policy sees only a line on a map, it misses how armed groups enter daily life through taxation, mediation, intimidation, marriage ties, protection rackets, and control of movement. Counterterrorism management in the Sahel has to understand those social routes without romanticizing them or surrendering public authority to them.

Across the Sahel, what happens when armed violence, weak public authority, border space, local grievance, and regional insecurity reinforce one another. Burkina Faso, Niger, and Mali have different political histories and security trajectories, but their counterterrorism challenges share a management problem: the state must protect communities across vast territory while rebuilding legitimacy in places where citizens may experience the state as absent, late, or coercive.

In Burkina Faso, the public data shows very high deaths despite a sharp decline from the previous year. In Niger, the burden remains serious with concentration in affected border regions. In Mali, deaths and attacks declined, but the underlying public-policy problem remains connected to territorial control, governance reach, and local insecurity. These patterns demand more than incident response. They demand local administration that can protect movement, restore basic services, maintain lawful security presence, and resolve community disputes before armed groups turn them into recruitment channels.

Sahel evidence also shows the danger of overcentralized security planning. Headquarters may approve strategy, but insecurity is experienced at the level of villages, markets, grazing routes, schools, and roads. A plan that does not work at that level is not working. Counterterrorism management should therefore include district-level risk reviews, local civilian-protection plans, mobile justice support, corruption controls, and service-delivery tracking.

7.2 Pakistan: high incident volume and institutional pressure

High incident volume also places pressure on credibility. If cases move slowly, if suspects are held without lawful process, or if communities believe that enforcement is selective, the state’s capacity begins to look arbitrary. Pakistan’s challenge therefore underlines a wider lesson: a busy security environment needs stronger systems, not looser standards. The more intense the threat, the more important it becomes to protect evidence, maintain review, and communicate clearly with affected communities.

Pakistan’s 2025 terrorism burden illustrates a different management challenge. IEP reported that Pakistan ranked first in the Global Terrorism Index in 2025, with 1,139 deaths, 1,595 injuries, and 1,045 incidents. The Tehrik-i-Taliban Pakistan was responsible for a large share of violence, while the burden was concentrated heavily in provinces near the Afghanistan border (IEP, 2026). This combination of high deaths, high incident volume, injuries, hostage-taking, and border-adjacent concentration places enormous pressure on policing, intelligence, prosecution, military coordination, emergency response, and diplomacy.

Pakistan matters in this comparison because high incident volume can overwhelm institutional quality. When hundreds of cases compete for attention, evidence handling, witness protection, prosecutorial preparation, detention oversight, forensic capacity, and court scheduling become central to counterterrorism outcomes. Poor case management can weaken deterrence. It can also produce wrongful detention, public anger, and failed prosecutions. A state facing high incident volume needs systems, not only bravery.

Pakistan also shows the importance of regional context. Border dynamics, displacement, militant sanctuaries, ideological networks, and local political grievances cannot be handled by police action alone. Diplomacy, border administration, provincial governance, financial controls, and community engagement all matter. A management framework helps by forcing these elements into the same conversation.

7.3 Comparative policy lessons

Comparison also warns against ranking countries as if the policy answer were identical. Pakistan’s high incident volume is not the same management problem as the civilian burden in parts of Nigeria or the territorial fragility of the Sahel. The value of comparison is to make managers more precise. It should sharpen questions about capacity, legitimacy, target patterns, financing, displacement, and justice quality. It should not flatten different histories into a single security template.

Table 5. Comparative Policy Lessons from Selected Cases

Case Main management signal Policy implication
Nigeria High civilian burden and territorial concentration Civilian protection, local trust, Borno-focused management, cross-border Lake Chad cooperation.
Burkina Faso High deaths with fewer incidents than Pakistan Protection of vulnerable communities, local government restoration, prevention of territorial isolation.
Niger Serious border-region burden Border governance, community protection, regional coordination, service continuity.
Mali Declining totals but persistent insecurity Sustain pressure while rebuilding local legitimacy and justice access.
Pakistan High incidents, deaths, injuries, and hostage pressure Case-management capacity, provincial coordination, border diplomacy, evidence quality, emergency response.


The comparative lesson is not that every country should copy another. It is that counterterrorism management should be specific to burden. Where civilian fatalities dominate, civilian protection must be a performance measure. Where incident volume is high, case-management capacity becomes vital. Where territorial concentration is severe, local governance and service restoration are security functions. Where recruitment is linked to abuse, accountability is prevention. Where financing is hidden in informal channels, financial intelligence must be joined with local knowledge.

These lessons also warn against public-policy theater. A state can announce a task force, pass a law, train officers, acquire technology, or increase spending without changing the lived risk of affected communities. The policy question is always practical: what public function has improved, for whom, where, and with what evidence?

Chapter 8: Public Policy Management Framework

8.1 The eight-pillar management framework

This framework is intentionally broad because counterterrorism failure is often produced by the space between agencies. A finance unit may see suspicious movement but lack local intelligence. A police unit may arrest suspects but fail to preserve evidence. A development program may enter a community without understanding security risk. A reintegration program may return people without preparing victims or local leaders. The eight pillars force these functions into one management conversation.

A counterterrorism policy that is serious enough for high-risk societies should be organized around eight management pillars. These pillars are not separate departments. They are connected functions that should be reviewed together by cabinet-level leadership, national security institutions, justice officials, finance regulators, local government, and community-facing agencies.

Table 6. Eight-Pillar Counterterrorism Management Framework

Pillar Main function Illustrative measures
1. Protection of life Civilian protection, emergency response, victim support, school and market safety planning. Deaths, injuries, displacement, victim assistance coverage, time to response.
2. Lawful intelligence and policing Threat reporting, investigation, evidence preservation, witness protection, case quality. Actionable reports, case files, prosecution readiness, complaint rates.
3. Justice and detention governance Due process, lawful detention, prosecution, rehabilitation screening, prison safeguards. Case disposal, detention review, acquittal reasons, prison risk reviews.
4. Financing and material support controls Risk-based financial intelligence, sanctions implementation, customs controls, nonprofit safeguards. Suspicious reports, successful investigations, false-positive review, protected humanitarian access.
5. Prevention and disengagement Livelihood pathways, grievance response, early intervention, family support, reintegration. Program completion, recidivism monitoring, employment/education linkage, community acceptance.
6. Service restoration Schools, clinics, roads, identity services, local government, agricultural access. Facility reopening, staffing, service use, travel safety, public feedback.
7. Regional cooperation Border management, information exchange, joint casework, humanitarian coordination. Timely referrals, lawful data exchange, joint reviews, corruption reports.
8. Public trust and accountability Complaint systems, rights safeguards, transparent communication, independent review. Complaint resolution, public confidence surveys, disciplinary outcomes, community reporting.


8.2 Coordination and ownership

Ownership must also survive leadership changes. Many public systems depend on the energy of one minister, commander, donor, or reform officer. When that person leaves, the routine collapses. NYCAR-standard policy thinking requires institutional memory: written procedures, standing review meetings, shared indicators, responsible offices, and records that allow the next official to see what was done, what failed, and what remains unresolved.

A common weakness in many counterterrorism systems is not lack of agencies. It is lack of ownership across the chain. An intelligence service may know something. A police unit may need evidence. A prosecutor may need witnesses. A finance unit may detect a suspicious flow. A local government may know which families are displaced. A school authority may know which children have disappeared. If these pieces are not connected lawfully and responsibly, the state sees fragments while violent groups exploit the gaps.

The framework therefore requires a named owner for each pillar and a joint review process that brings the owners together. Joint review should not be a ceremonial meeting. It should examine current risk, recent incidents, civilian harm, case progress, financing signals, recruitment concerns, local service conditions, complaints, and community feedback. The purpose is to convert information into decisions: who must act, by when, with what authority, and how progress will be checked.

Ownership should also extend to local government. Counterterrorism is often national in command but local in effect. A national plan that does not define what a governor, mayor, district officer, school authority, health agency, police commander, or community liaison must do will not reach the people most affected. Public policy becomes real when it has local tasks, budgets, and accountability.

8.3 Communication as management

Communication should also make room for uncertainty. Public institutions lose credibility when they speak with false confidence before facts are known. They also lose credibility when they hide behind silence after harm. The professional standard is measured honesty: say what is known, what is being verified, what support is available, and when the public will receive the next update. In fearful environments, disciplined communication can reduce rumor without compromising investigation.

Counterterrorism communication is not simply publicity. It is a management function. Communities need to know how to report threats, where to seek help, what rights they have, what services are available, how victims can receive support, and how the state will protect lawful activity. Poor communication creates rumor, fear, and suspicion. Overconfident communication creates credibility problems when the next attack occurs. The best communication is sober, factual, timely, and respectful.

Communication also matters after harm. Victims should not learn about government concern only through speeches. They should experience it through identification of the dead, treatment of the injured, trauma care, compensation where appropriate, restoration of documents, support for displaced households, and public explanation of what is being done to reduce future risk. A state that communicates only victory and never grief sounds detached from the people it claims to protect.

In high-risk societies, public messaging must also avoid stigmatization. Religious, ethnic, regional, or occupational identity should not be treated as evidence of guilt. Collective suspicion can damage intelligence flow, increase social division, and create exactly the grievance that violent groups exploit. Communication should distinguish clearly between criminal organizations and the communities they harm.

8.4 Finance, civil society, and humanitarian access

Humanitarian access is not a side issue. In areas affected by terrorism, lawful charities, local associations, and relief agencies may be the only actors still able to provide food, medical support, education, trauma care, or documentation assistance. If controls are designed without understanding that reality, they may reduce the services that keep communities away from armed-group dependence. A precise system protects financial integrity while preserving the lawful assistance that makes resilience possible.

Finance policy also needs feedback from the field. A suspicious transaction report may be useful, but it does not explain whether a village economy is being taxed, whether ransom networks are moving through informal channels, or whether legitimate aid is being delayed by fear of compliance exposure. Regulators, banks, humanitarian agencies, prosecutors, and local officials should therefore review blocked transactions and confirmed abuse together. The aim is not softer control. It is better control, aimed at real risk rather than administrative anxiety.

Terrorist financing controls must be strong, but they must also be precise. FATF’s risk-based approach is useful because it recognizes that financial systems need to identify and mitigate risk without unnecessarily disrupting legitimate nonprofit and humanitarian activity (FATF, 2025). In conflict-affected areas, civil society and humanitarian actors often provide services that the state cannot immediately provide. If financial controls choke off lawful assistance, communities become more vulnerable and armed groups may gain influence.

A responsible policy should therefore build channels for lawful humanitarian access, clarify compliance expectations, train financial institutions on risk-based assessment, and establish escalation routes when legitimate transactions are blocked. Counterterrorism finance should disrupt violent organizations, not punish the communities that depend on relief, local charities, remittances, or development projects.

The management question is not whether financial controls should exist. They must. The question is whether they are intelligent enough to distinguish between risk and legitimate need. That requires data, supervision, appeal mechanisms, and regular review of unintended consequences.

Chapter 9: Implementation, Monitoring, and Ethical Safeguards

9.1 Building a counterterrorism management dashboard

A dashboard should also show movement over time rather than isolated numbers. One month of improvement may reflect temporary displacement, an armed-group pause, or poor reporting. Three quarters of consistent improvement across harm, justice quality, service restoration, and community reporting carry more meaning. The dashboard should help leaders ask better questions, not give them a false claim of certainty.

A management framework needs a dashboard, but the dashboard must avoid the false comfort of counting activity as success. Number of meetings, patrols, arrests, workshops, or media releases does not prove safer communities. A useful dashboard should combine harm measures, justice measures, prevention measures, service measures, finance measures, and trust measures. It should show whether the state is reducing harm while becoming more credible.

Dashboard review should occur at three levels. At the national level, leaders should examine country burden, regional cooperation, financing, legal reforms, and budget allocation. At the state or provincial level, officials should examine concentration, case progress, local service conditions, and displacement. At the community level, managers should examine reporting channels, victim support, school and market safety, complaint resolution, and public feedback.

Table 7. Suggested Counterterrorism Management Dashboard

Dashboard domain Measures Review cycle
Harm reduction Deaths, injuries, incidents, kidnappings, displacement, property loss Monthly and quarterly
Justice quality Evidence quality, lawful detention review, prosecutions, case disposal, witness protection Monthly
Civilian protection Response time, victim assistance, school/market reopening, protected movement corridors Monthly
Prevention At-risk youth referrals, livelihood placement, family support, disengagement outcomes Quarterly
Financial controls Suspicious reports, investigations, sanctions compliance, humanitarian false positives Quarterly
Public trust Complaints, resolution time, community reporting, survey evidence, civil society feedback Quarterly
Regional cooperation Cross-border referrals, shared casework, joint reviews, corruption complaints Quarterly


9.2 Ethical safeguards

Ethical safeguards should be designed before crisis, not improvised after scandal. Detention review, complaints, data correction, access logs, disciplinary procedures, and civilian harm recording all require systems that already exist when pressure arrives. A state that waits until abuse becomes public has already lost trust. Responsible counterterrorism management builds review into the ordinary process of exercising power.

Counterterrorism policy carries exceptional ethical risk because it gives the state strong powers at moments of public fear. Those powers may be necessary, but necessity does not remove the duty of restraint. Abuse can destroy cases, damage intelligence cooperation, violate rights, and strengthen extremist narratives. A serious management framework therefore builds ethical safeguards into the system rather than treating them as external criticism.

Legality is the first safeguard. Agencies should know the legal basis for detention, search, data collection, watchlisting, sanctions, asset freezes, and information sharing. The second safeguard is necessity and proportionality. A measure should be no broader than the risk requires. The third safeguard is review. Decisions that affect liberty, property, family life, humanitarian access, or reputation should be reviewable. The fourth safeguard is remedy. People wrongly harmed by counterterrorism action need a path to correction.

Data protection is another safeguard. Modern counterterrorism increasingly relies on identity systems, biometrics, watchlists, telecommunications information, financial intelligence, and cross-border data exchange. These tools can improve security, but they can also produce error, abuse, and stigma. Data systems should have clear access rules, audit trails, correction procedures, and independent oversight.

9.3 Monitoring unintended consequences

Strong monitoring systems are willing to hear bad news early. They make room for complaints, civil society reports, local government warnings, and victim feedback before the problem becomes international embarrassment or renewed violence. A counterterrorism system that cannot tolerate criticism is not strong. It is blind. Strength lies in correcting harmful practice quickly enough that public confidence is not permanently lost.

A policy can produce harm even when its goal is legitimate. Heavy-handed operations may displace civilians into unsafe areas. Broad financial restrictions may block humanitarian activity. Poorly managed reintegration may anger victims. Public messaging may stigmatize a community. Surveillance may chill lawful religious or political activity. A mature counterterrorism system monitors these unintended consequences and changes course when evidence demands it.

Monitoring should include civil society, community leaders, victim groups, women’s organizations, youth representatives, humanitarian partners, and local officials. This does not mean giving sensitive operational information to everyone. It means giving affected communities a serious channel to report harm, fear, corruption, abuse, or policy failure. People closest to risk often see problems before national dashboards show them.

A public manager should ask five questions after every major counterterrorism initiative. Did it reduce harm? Did it strengthen or weaken trust? Did it produce lawful evidence and fair process? Did it protect civilians and legitimate civil activity? Did it create new grievances that require correction? These questions keep policy honest.

9.4 Capacity building that matters

Capacity building should finally be tested in practice. If officers are trained on evidence handling, case files should improve. If prosecutors receive counterterrorism training, case quality and disposal should change. If border officials receive human-rights training, complaints and lawful referrals should be reviewed. If community liaison officers are trained, reporting channels should become safer and more trusted. Training has value only when it changes conduct.

Training is often the easiest reform to announce and the hardest to connect to outcomes. A workshop does not automatically improve counterterrorism management. Capacity building should be tied to specific performance gaps: evidence handling, financial investigation, border referral, victim support, forensic practice, witness protection, detention review, community reporting, data protection, or public communication.

Each capacity-building program should answer a practical question. What problem is being solved? Which staff need the skill? What procedure will change after training? Which supervisor will check compliance? What measure will show improvement? Without those questions, training becomes a record of attendance rather than a change in public performance.

Capacity building should also be multi-agency where the problem is multi-agency. Terrorist financing requires finance, police, prosecutors, customs, and regulators. Border management requires immigration, security agencies, humanitarian actors, child-protection officials, and neighboring states. Reintegration requires justice, social services, mental-health support, education, employment, victims’ representatives, and local communities. Training one agency alone can leave the chain weak.

Chapter 10: Findings, Recommendations, Limitations, and Conclusion

10.1 Main findings

The main finding is that counterterrorism management is strongest when it is treated as public governance rather than as a single security operation. The 2025 public data shows a global decline in deaths and incidents, but that improvement sits beside severe concentration in a small number of countries and territories. Public leaders should therefore resist both complacency and panic. The useful reading is more disciplined: terrorism burden is uneven, local, and shaped by institutional capacity.

Nigeria’s 2025 pattern confirms why civilian protection and territorial concentration must be treated as management priorities. The evidence also supports a prevention argument. UNDP’s recruitment findings show that employment pressure, trigger events, and human-rights abuse cannot be pushed to the edge of security planning. Terrorist-finance controls remain necessary, but they must be risk-based and proportionate so that lawful civil society and humanitarian activity are not damaged. Public trust emerges from the whole analysis as a security asset because it affects reporting, witness cooperation, prevention, reintegration, and the credibility of the state.

10.2 Recommendations

National counterterrorism councils and public safety agencies should adopt a transparent management-priority model such as RCMPS to compare burden across regions and decide where oversight, protection, justice, and services need urgent strengthening. The model should not be used mechanically. It should sit inside a review process that includes data quality checks, human-rights safeguards, local context, and clear ownership of follow-up actions.

Civilian protection should become a core performance measure. Deaths, injuries, displacement, school closure, market disruption, victim assistance, and the safe return of everyday movement should be tracked as counterterrorism outcomes, not as humanitarian afterthoughts. A policy that reduces the number of armed encounters but leaves civilians afraid to farm, trade, worship, travel, or send children to school has not restored public safety.

States should strengthen lawful case management across intelligence, policing, prosecution, detention review, witness protection, and court capacity. Weakness in any part of the chain can damage justice and trust. Governments should also protect public confidence while using state power by improving complaint systems, detention safeguards, disciplinary processes, and public communication. Abuse should be treated not only as a rights violation but as a strategic error that can become a recruitment driver.

Terrorist-finance controls should be risk-based and precise. Financial intelligence must focus on real risk, protect lawful nonprofit and humanitarian activity, and provide appeal routes when legitimate transactions are wrongly blocked. Prevention programs should also be localized. Employment pressure, family fear, abuse, coercion, and grievance require different tools. Generic messaging cannot replace credible local alternatives.

Regional cooperation should be improved through lawful information exchange, identity controls, child and victim referral procedures, anti-corruption safeguards, and cross-border prosecution support. Governments should also publish responsible non-sensitive dashboards on harm reduction, justice quality, civilian protection, prevention, finance controls, and complaint resolution. Public accountability does not require exposing operations. It requires showing citizens that power is being used with discipline.

10.3 Limitations of the study

This limitation does not weaken the publication. It defines its honesty. Counterterrorism research that pretends to know more than its evidence allows can become dangerous, especially where the subject involves coercive state power and vulnerable communities. The work keeps its claims within the reach of public data and management reasoning, and that restraint is part of the professional standard.

The publication relies on public evidence, and so it cannot claim the precision of classified intelligence, field interviews, or local ethnographic research. Public terrorism data carry their own reporting limitations, classification disputes, and information gaps. The model offered here is a management tool, not a predictive engine, and it should be tested, adapted, and improved with country-level data before any institution adopts it.

The publication also cannot settle every debate about counterterrorism theory, insurgency, political violence, or conflict resolution. Its focus is narrower and more practical: how should public managers organize counterterrorism priorities when the evidence shows concentrated harm, civilian exposure, recruitment pressure, financing risk, and trust deficits? Within that scope, the argument is clear and usable.

10.4 Conclusion

Michael E. Emenike’s central contribution is therefore not a claim that management can replace security action. It is the stronger claim that security action needs management if it is to endure. The publication asks leaders to judge counterterrorism by the condition of the public after policy has acted: whether civilians are safer, courts are stronger, agencies cooperate better, financial channels are cleaner, communities report earlier, and state power carries enough legitimacy to hold the ground it has recovered. It also gives the publication a clear professional standard for policy readers, not a rhetorical closing gesture.

The final lesson is that security must become administratively competent. A state may possess weapons, laws, and agencies and still fail if its institutions cannot coordinate, document, prosecute, repair, and learn. Counterterrorism beyond force is not a softer standard. It is a harder one, because it asks public power to be effective without becoming reckless, firm without becoming abusive, and protective without losing the trust of the people whose safety gives the policy its purpose. That is the standard this publication applies to every model, case, figure, and recommendation it presents, and it is the reason the study remains grounded in public management rather than performance language.

Counterterrorism beyond force is not counterterrorism without force. It is counterterrorism governed by judgment. A state has the right and duty to protect people from organized violence. But protection becomes durable only when public power is lawful, coordinated, trusted, and connected to the conditions that violent groups exploit. The strongest counterterrorism policy is therefore not the loudest one. It is the one that reduces harm while making public authority more credible.

Public data from 2025 gives both encouragement and warning. Global terrorism deaths and incidents declined, but the burden remains concentrated and severe in specific countries. Nigeria, the Sahel, and Pakistan show that public managers must read fatalities, incidents, lethality, territorial concentration, civilian exposure, recruitment drivers, and institutional trust together. Any policy that separates those variables will see only part of the problem.

Michael E. Emenike’s paper is therefore framed around a practical standard: counterterrorism management should be judged by whether it protects life, strengthens law, preserves trust, disrupts violent networks, supports victims, reduces recruitment pressure, and restores public services in places where fear has weakened the state. That is a demanding standard. It is also the only standard worthy of a public policy that claims to defend society.

References

Financial Action Task Force. (2025). International standards on combating money laundering and the financing of terrorism & proliferation: The FATF recommendations (updated October 2025). FATF. https://www.fatf-gafi.org

Institute for Economics & Peace. (2026). Global Terrorism Index 2026: Measuring the impact of terrorism. Institute for Economics & Peace. https://www.visionofhumanity.org/resources

United Nations Development Programme. (2023). Journey to extremism in Africa: Pathways to recruitment and disengagement. UNDP. https://www.undp.org/africa/publications/journey-extremism-africa-pathways-recruitment-and-disengagement

United Nations General Assembly. (2023). The United Nations Global Counter-Terrorism Strategy: Eighth review (A/RES/77/298). United Nations. https://undocs.org/A/RES/77/298

United Nations Office on Drugs and Crime. (2021). Module 1: Counter-terrorism in the international law context. United Nations. https://www.unodc.org

United Nations Security Council. (2017). Resolution 2396 (2017): Threats to international peace and security caused by terrorist acts. United Nations. https://undocs.org/S/RES/2396(2017)

United Nations Security Council. (2019). Resolution 2462 (2019): Threats to international peace and security caused by terrorist acts. United Nations. https://undocs.org/S/RES/2462(2019)

World Bank. (2020). World Bank Group strategy for fragility, conflict, and violence 2020-2025. World Bank. https://documents.worldbank.org

The Thinkers’ Review

Chijioke Ogbo

Media Management and Modern Graphics in Filmmaking

Production Governance, Virtual Production, and the Economics of Visual Storytelling

Research Paper Publication by Chijioke D. Ogbo

Research Area: Media Management and Media Research

Institutional Affiliation: New York Center for Advanced Research (NYCAR)

Publication No.: NYCAR-TTR-2026-RP039

Date: June 4, 2026

DOI: https://doi.org/10.5281/zenodo.20545558


Peer Review Status

This manuscript was reviewed under the internal editorial review framework of the New York Center for Advanced Research (NYCAR). The review focused on academic coherence, source integrity, professional voice, mathematical suitability, case-study credibility, visual formatting, and alignment with NYCAR master’s-level media-research standards.


Abstract

Media management now has to account for a kind of production work that did not exist at the same scale in the classical studio era: graphics that are planned, tested, priced, shot, revised, and delivered across many departments before the audience ever sees a finished frame. Modern graphics in filmmaking do not belong only to post-production. They shape development, finance, previsualization, set design, cinematography, performance, editing, marketing, intellectual property control, and audience reception. The analysis treats media management and modern graphics as a single production problem. Its argument is direct: the quality of visual storytelling depends not only on software power or artistic talent, but also on the managerial intelligence that connects creative intention, technical workflow, labor capacity, schedule discipline, and commercial responsibility.

It rests on an integrative media-research design supported by documentary case analysis. It draws on peer-reviewed scholarship, production-studies literature, industry practice documents, and real case evidence from Industrial Light & Magic’s StageCraft workflow for The Mandalorian, Weta FX’s virtual-production and visual-effects work on the Avatar franchise, Netflix production and VFX guidance, and recent research on real-time rendering pipelines for independent filmmaking. These cases show that modern graphics can reduce uncertainty when they are planned early, governed carefully, and tied to clear creative decisions. They also show that graphics can become expensive, confusing, and artistically weak when they are treated as a late rescue tool for poor planning.

It develops the Graphics Production Management Probability Model, a practical mathematical framework for estimating whether a graphics-heavy film project is likely to reach controlled delivery. The model does not pretend to replace professional judgment. It gives producers, production managers, VFX supervisors, post-production supervisors, and media executives a disciplined way to identify pressure points: weak preproduction governance, asset confusion, review delays, set-integration problems, insufficient artist capacity, schedule churn, and rework. A companion Graphics Management Risk Ratio supports early diagnosis. The central finding is that modern graphics improve filmmaking when management moves visual decision-making upstream. Graphics then become part of narrative design rather than an emergency repair shop. For master’s-level media research, the topic matters because film management is no longer only the coordination of people, locations, budgets, and equipment. It is the governance of images as data, labor, art, capital, and story.

Keywords: media management, modern graphics, filmmaking, virtual production, visual effects, production governance, VFX labor, media research, StageCraft, Weta FX, Netflix


Contents

Chapter 1: Introduction

Film has always joined art to management. A director may speak in images, actors may search for emotional truth, and designers may build worlds with fabric, paint, light, and sound, yet none of that work survives without organization. Modern graphics intensify that old fact. Digital characters, virtual sets, motion capture, real-time environments, crowd simulations, virtual scouting, volumetric capture, LED volumes, facial performance systems, compositing, and final-pixel rendering have changed the shape of production labor. The producer who treats these tools as decorations misunderstands the contemporary film process. Graphics now affect the budget before a camera is chosen, the schedule before a stage is booked, and the story before the first storyboard is approved.

The discussion that follows treats media management and modern graphics in filmmaking as a production-governance problem. Media management is understood here as the planning, coordination, control, and ethical stewardship of creative media work from idea to audience. Modern graphics are understood as the combined use of digital visual techniques, real-time rendering, visual effects, animation, compositing, virtual production, and graphic design systems in film and screen media. The two cannot be separated. When graphics become central to a film’s world, the management system has to carry creative uncertainty, technical dependency, data complexity, labor pressure, and market expectation. The more visually ambitious a project becomes, the less tolerant it is of weak management.

A poor manager can hide for a while on a simple production. On a graphics-heavy production, poor management becomes visible. A late design decision may create hundreds of broken shots. An unclear approval chain may hold artists in weeks of revision. A weak asset naming system may corrupt files, duplicate labor, and frustrate vendors. A director’s vague visual language may lead to expensive exploratory work that never reaches the screen. A production budget may look controlled until the hidden cost of rework appears. The glamour of modern graphics often hides the managerial discipline that keeps such work from becoming chaos.

The purpose here is not to celebrate technology for its own sake. Film history is full of technical novelty that looked impressive for a season and then became ordinary. The more serious question is whether modern graphics help filmmakers tell stories with stronger control over meaning, cost, time, and audience experience. That question belongs to media management because digital images are now part of the organizational life of film production. A virtual environment is an artistic object, but it is also a database, a scheduling issue, a lighting problem, a software dependency, a storage cost, a rights asset, and a labor demand. Good management sees all of those meanings at once.

1.1 Background to the Study

The film industry has moved through several technical shifts: synchronized sound, color, widescreen formats, portable cameras, nonlinear editing, digital intermediates, computer-generated imagery, streaming distribution, and now virtual production and AI-assisted workflows. Each shift has created artistic possibility and managerial strain. Modern graphics differ from some earlier shifts because they relocate decisions across the production chain. In a traditional model, visual effects could be concentrated after principal photography, even though good productions still planned effects in advance. In contemporary practice, digital assets may be designed before casting, tested during previsualization, used on set through LED walls, adjusted during editing, and repurposed for marketing or game extensions.

Virtual production is one of the clearest signs of this shift. Epic Games describes virtual production as a wide set of techniques that include previsualization, technical visualization, virtual scouting, live compositing, and in-camera visual effects (Epic Games, n.d.). Industrial Light & Magic presented its StageCraft workflow for The Mandalorian as a system that allowed complex visual-effects shots to be captured in camera through real-time game-engine technology and LED screens (Industrial Light & Magic, 2020). Weta FX explains virtual production as the point where physical and digital worlds meet, allowing directors to work with motion-capture performance while viewing virtual characters and environments in context (Weta FX, n.d.). These are not minor tool changes. They alter what producers have to know, when decisions have to be made, and how departments must cooperate.

The growth of digital graphics has also changed the meaning of film labor. A modern film may depend on hundreds or thousands of artists who never appear on set but whose work defines the visible world of the film. Atkinson’s analysis of visual-effects labor and materiality warns against treating VFX as invisible magic detached from the spaces, processes, and workers that produce it (Atkinson, 2015). That warning matters for management. When graphics are treated as a mysterious technical afterthought, the people who make them are often given weak briefs, unrealistic deadlines, and unstable creative direction. When graphics are treated as a managed creative system, the production can align directors, cinematographers, designers, supervisors, editors, data managers, vendors, and executives around decisions that are difficult but visible.

Media management therefore needs a language that can evaluate graphics beyond spectacle. A spectacular image may be poorly managed if it wastes labor, distorts the story, burns the budget, or masks weak planning. A modest image may be brilliantly managed if it serves narrative purpose, protects the schedule, and uses the available pipeline with care. That distinction stays at the center of the argument. The issue is not whether modern graphics are beautiful or fashionable. The issue is whether film managers can govern the conditions under which graphics become useful, credible, and sustainable parts of filmmaking.

1.2 Problem Statement

Many film and screen-media projects now depend on graphics without having a management system strong enough to support that dependence. A production may approve a script with heavy world-building, creatures, set extensions, simulations, or digital doubles, yet fail to align creative design, technical testing, vendor bidding, data flow, review discipline, and labor capacity before shooting. The result is familiar in production practice: late changes, escalating costs, rushed artists, visual inconsistency, and a post-production period that becomes a rescue mission rather than a finishing process.

The problem addressed here is the gap between the growing creative role of modern graphics and the limited managerial frameworks used to control graphics-heavy filmmaking. Standard production schedules and budgets are often too linear for virtual production and complex VFX workflows. They separate pre-production, production, and post-production too neatly, even though modern graphics often require those phases to overlap. They may list VFX as a department while failing to show how VFX decisions affect design, lighting, camera movement, editing, and performance. They may authorize software and hardware spending without enough attention to approval speed, artist workload, metadata control, file security, or version discipline.

This gap creates practical harm. Producers may underestimate the amount of design work needed before a stage day. Directors may discover too late that a desired camera move requires asset rebuilding. Cinematographers may light actors against virtual environments whose color logic is still unsettled. Editors may receive footage whose graphics assumptions no longer fit the cut. Vendors may compete on low bids and then absorb impossible change requests. The audience sees only the final image, but the production lives through the consequences of weak governance long before release.

A serious media-management paper must therefore ask how modern graphics can be managed as a creative, technical, economic, and ethical system. Nothing in the argument requires every production to use virtual production or high-end computer graphics. It argues that when a production chooses modern graphics, management must change with the choice. The project must know which decisions must be made early, which assets must be locked, which areas can remain flexible, which risks are technical, which are artistic, which are labor risks, and which are executive risks caused by unclear authority.

1.3 Aim, Objectives, and Research Questions

The aim is to examine how media management can improve the planning and execution of modern graphics in filmmaking. It develops a practical framework for graphics governance and tests its logic against real production cases. Written for master’s-level media research, the work does not attempt a purely technical manual. Its concern is management: how film leaders make decisions, organize people, protect creative purpose, and control risk when images are produced through complex digital systems.

The objectives are fivefold. The first objective is to define modern graphics as a management category rather than a narrow technical category. The second is to examine relevant literature on media management, production studies, visual-effects labor, virtual production, and digital transformation in film. The third is to analyze practical case evidence from StageCraft, Weta FX, Netflix, and real-time rendering research. The fourth is to develop a mathematical diagnostic model that can help managers estimate delivery control and risk in graphics-heavy projects. The fifth is to offer recommendations for producers, production managers, media executives, educators, and VFX supervisors.

The research questions follow from those objectives. How should media management understand modern graphics in filmmaking? Which managerial failures most often damage graphics-heavy productions? How do virtual production and real-time rendering change the relationship between pre-production, production, and post-production? What can be learned from major case examples such as The Mandalorian, Avatar, Netflix production practice, and independent virtual production research? How can a practical mathematical model help media managers diagnose graphics risk without reducing creative work to crude numbers?

These questions are answered through synthesis rather than fieldwork. It draws on official production documents, trade sources, peer-reviewed research, and case analysis. That design is appropriate for a master’s-level paper because the purpose is to build a coherent management model that can later be tested with primary data. The method is not a substitute for studio interviews, budget analysis, or vendor-level production records. It is a disciplined first stage: a framework that identifies what such future research should measure.

1.4 Significance of the Study

The subject matters because modern graphics now influence nearly every part of screen production. Even films that advertise practical effects often contain invisible digital work. The audience may not notice set extensions, beauty work, background replacement, digital crowds, sky replacement, environmental cleanup, muzzle flashes, screen inserts, or simulated atmosphere. A film without visible fantasy may still be graphics-heavy in its production reality. This means media managers who lack graphics literacy may misunderstand their own projects.

It also matters for film education. Many media-management programs still teach production as if the major challenge is coordinating a largely physical shoot. That knowledge remains essential, but it is no longer enough. Graduates entering film, television, streaming, advertising, and branded content need to understand how assets move, how real-time images are tested, how VFX bidding can distort budgets, how review software shapes creative decisions, and how data security affects production continuity. They do not need to become compositors or engine programmers. They need enough judgment to manage people who are doing that work.

For the industry, the study speaks to cost control and labor dignity. Poor graphics management does not simply waste money. It pushes stress downward onto artists, coordinators, assistants, and vendors. When executives change direction late, when directors approve without clarity, or when producers underbudget, the cost is often paid by workers through overtime, weekend labor, creative frustration, and reputational pressure. A media-management approach that treats graphics as planned creative labor rather than infinite digital correction is more honest and more sustainable.

For audiences, the issue is quality. Viewers may not know why a film feels visually coherent or visually hollow, but they feel the difference. Strong graphics management helps images serve story, performance, rhythm, and tone. Weak graphics management produces clutter, inconsistency, or spectacle without meaning. The cultural value of film is not protected by technology alone. It is protected by the human and institutional decisions that determine what technology is asked to do.


Chapter 2: Literature Review

The literature on media management, visual effects, and virtual production is spread across several fields. Production studies examines labor, institutions, authorship, and industrial practice. Media-management literature addresses strategy, project control, financing, audience markets, and organizational behavior. Technical research examines rendering, pipelines, real-time systems, and workflow performance. Trade and studio documents give practical detail that academic literature often misses. The review brings those strands together because graphics-heavy filmmaking sits at their intersection.

One difficulty in the literature is that language often separates art from management. Visual-effects scholarship may describe images, bodies, screens, labor, and mediation, while management writing may focus on budgets, schedules, rights, teams, and performance. In practice, those concerns are joined. A digital creature is a design decision, a rigging challenge, a performance translation, a rendering cost, a schedule dependency, and a brand asset. A virtual set is a world, a stage, a lighting source, a software environment, and a risk item. Serious analysis has to hold these meanings together.

Another difficulty is the temptation to treat new tools as proof of progress. The film industry has often attached inflated promises to technology. The arrival of digital cameras did not automatically create better cinematography. Nonlinear editing did not automatically create better storytelling. Virtual production will not automatically create better films. Scholarship and management practice therefore need a disciplined vocabulary that asks what a tool changes in decision-making, labor, cost, quality, and creative control.

2.1 Media Management in the Digital Film Economy

Media management in the film economy is the governance of uncertainty. A film begins as a proposal for future attention. Money is spent before demand is known. Creative quality is difficult to guarantee. Distribution conditions can change. Audience taste is unstable. Technology can expand possibility while increasing complexity. Digital graphics intensify this uncertainty because they add a second production world beside the physical one. The film is shot, but it is also built. It is performed, but it is also simulated. It is edited, but it is also continuously revised at the level of image elements.

Digital transformation research in media and audiovisual industries argues that technology changes more than tools. It alters business models, production relationships, skills, and organizational routines. Tsiavos (2025), in work on artificial intelligence and the film industry, describes AI as affecting the film value chain and raising concerns around authorship, creative integrity, and labor displacement. Kotlinska’s 2024 work on digital transformation in the audiovisual industry links digital change to sustainable practice and innovation in business models. These studies support the broader point that media management must examine how technology reorganizes work, not merely how it improves output.

The film industry also remains a project-based economy. Many workers are hired for a production, released, and rehired elsewhere. Vendors operate under contracts, bids, and delivery deadlines. Creative authority may be divided between producers, directors, studio executives, showrunners, supervisors, and financiers. In such a setting, modern graphics require strong coordination because the people responsible for the final image may be scattered across companies, countries, time zones, and software systems. Management failure often appears as artistic failure because the audience cannot see the institutional problem behind the image.

Media managers must therefore work with three connected forms of capital. The first is financial capital: the budget, contingency, insurance, vendor contracts, stage costs, licensing, rendering expense, and delivery cost. The second is creative capital: the story world, visual identity, design intelligence, performance quality, and emotional coherence of the film. The third is technical capital: software, hardware, data systems, asset libraries, rendering capacity, pipeline knowledge, and security. A graphics-heavy production becomes dangerous when one of these forms of capital is strong and the others are weak. A rich budget cannot save a confused visual concept forever. A brilliant concept cannot survive a broken pipeline. Technical power without creative control often becomes empty display.

2.2 Modern Graphics as Production Infrastructure

Modern graphics should be understood as production infrastructure. Infrastructure is often invisible when it works and painfully visible when it fails. A production’s graphics system includes previsualization tools, concept art, asset databases, modeling and rigging systems, texture and look-development processes, motion-capture systems, camera tracking, LED walls, color pipelines, editorial handoff, review platforms, storage, security, render management, compositing, quality control, and final delivery. It also includes human authority: who can approve, who can revise, who can stop a flawed process, and who absorbs the cost when a decision changes.

The traditional image of visual effects as post-production work is now insufficient. Real-time production methods allow filmmakers to see digital environments during a shoot. In-camera visual effects can place actors before LED displays that show interactive backgrounds. Previsualization can guide action design before locations or sets are finalized. Virtual scouting can allow departments to inspect digital spaces before physical construction. Live compositing can help a director judge whether an actor, camera move, and digital world belong together. Each of these methods shifts work earlier. That shift is valuable only if management understands it.

A common mistake is to think that early visualization eliminates uncertainty. It does not. It moves uncertainty into a different form. Instead of discovering a problem after the shoot, a team may discover it during asset preparation, stage testing, or virtual camera review. This is still useful because earlier problems are often cheaper than later problems. Yet early discovery requires time, staff, and budget. A production that wants the advantages of virtual production while refusing to invest in early design discipline will likely suffer.

Netflix’s VFX best-practice guidance emphasizes the importance of reducing ambiguity in image exchange, improving quality, and limiting errors across post-production and vendor workflows (Netflix Partner Help Center, n.d.-a). That advice may look technical, but it is also managerial. Ambiguity is a cost. When image files, naming systems, color assumptions, frame ranges, delivery formats, or review expectations are unclear, the production pays through delay and correction. Good graphics management turns technical clarity into creative time.

2.3 Virtual Production and the Collapse of Linear Workflow

Virtual production challenges the neat separation between pre-production, production, and post-production. The classical division still has administrative value, but graphics-heavy work bends it. A background asset may be designed in pre-production, used as an LED wall environment during the shoot, revised after editorial changes, and then adapted for a trailer campaign. A digital character may require early performance testing, motion-capture planning, on-set reference, animation, simulation, and final compositing. The asset travels through the production. The manager has to track both its artistic meaning and its technical state.

Industrial Light & Magic’s public description of StageCraft for The Mandalorian shows why the linear model is no longer enough. The workflow used real-time game-engine rendering and LED screens to allow filmmakers to capture many complex VFX shots in camera (Industrial Light & Magic, 2020). Such a system requires the virtual world to be prepared before the shoot. A desert, spacecraft interior, horizon, or lighting condition cannot simply be postponed. It has to be designed, approved, tested, and synchronized with camera tracking and stage needs. The production day becomes dependent on pre-built digital material.

This has clear management benefits. Actors may perform in a more believable environment than a blank screen. Cinematographers may receive interactive light and reflection. Directors may make decisions with visible context. Producers may reduce some location travel and post-production uncertainty. Yet the method also creates pressure. If the virtual environment is not ready, the stage cannot perform its promise. If creative approvals are late, the LED volume becomes an expensive room waiting for decisions. If departments disagree about color, scale, or camera movement, the conflict appears during a stage day rather than in a remote post facility.

The value of virtual production therefore depends on disciplined preparation. The phrase “fix it in post” becomes less acceptable when the production has already moved post-related decisions into pre-production and the shoot. Media management must create earlier locks, clearer authority, and better rehearsal systems. The reward is not simply technical efficiency. The reward is creative confidence under pressure.

2.4 Visual-Effects Labor, Ethics, and Credit

Graphics management is also labor management. Visual-effects artists, coordinators, production managers, supervisors, data wranglers, pipeline engineers, render managers, and compositors carry enormous responsibility for the final image. Much of their work is unseen because successful visual effects often disappear into the film. This invisibility can weaken labor recognition. The public may praise a director’s world while ignoring the teams who built it. The industry may celebrate spectacle while allowing unstable bidding, late changes, and compressed schedules to damage workers’ lives.

Atkinson’s discussion of the spaces, labor, and materiality of VFX production is valuable because it refuses the fantasy that digital effects arrive from nowhere (Atkinson, 2015). Modern graphics are material in a different sense: they require machines, rooms, servers, screens, bodies, time, attention, and skill. They also require management choices. When a studio demands late revisions without extending time or budget, the choice has material consequences for workers. When a producer accepts a low bid that cannot reasonably cover the work, the resulting pressure is not an accident. It is built into the contract.

The USC Annenberg Inclusion Initiative’s report on women in visual effects examined representation, barriers, and perceptions in a field that has become central to filmmaking (Smith et al., 2021). Its significance for the argument lies in the connection between graphics management and equity. A production pipeline is never neutral if some workers experience reduced access to leadership, credit, mentoring, or authority. Modern graphics cannot be managed well while ignoring the conditions under which graphics workers enter, remain, and advance in the field.

Ethical media management asks whether the image has been produced under conditions that respect human labor. This does not mean every production can avoid pressure. Film work is often intense. It does mean that managers should avoid preventable harm: vague briefs, unstable approvals, abusive revision cycles, unpaid overtime expectations, and erasure of creative contribution. A film that wins praise for visual power while damaging the workers who made that power has a governance problem. The problem is moral and managerial at once.

2.5 Graphics, Story, and Audience Meaning

Modern graphics succeed only when they serve story. Audiences may enjoy spectacle, but spectacle detached from character, rhythm, and emotional stakes becomes tiring. The most impressive image in a film can fail if it arrives at the wrong moment, distracts from performance, or breaks the visual grammar of the world. Media management has a role here because managers help determine whether the project has enough time and structure for graphics to become expressive rather than merely expensive.

Graphics-heavy productions often face a tension between exploration and control. Artists need room to discover better images. Directors need room to refine. Producers need a schedule that ends. These needs are not enemies, but they must be ordered. Early stages should allow more experimentation because changes are cheaper and creatively useful. Later stages need stronger locks because every change carries downstream cost. A manager who allows endless late exploration may think they are protecting artistry, while in fact they may be destroying the conditions needed for good artistry.

The Avatar franchise illustrates the relationship between technical invention and story-world commitment. Weta FX notes that Avatar became a major moment for virtual production because James Cameron wanted to direct live actors on a motion-capture stage while viewing performances inside the Pandora environment (Weta FX, n.d.). Trade reporting on Avatar: The Way of Water describes the scale of the VFX work, including thousands of shots and extensive water-related effects handled by Weta FX (PostPerspective, 2023). The management lesson is not that every film should seek that scale. The lesson is that large-scale graphics require a deep commitment to visual logic, technology development, and sustained production control.

A modern graphics manager must ask what the audience is meant to feel, not only what the audience is meant to see. A dragon, ocean, city, crowd, robot, ghost, or alien landscape has no automatic value. Its value comes from placement in narrative life. The production system has to protect that meaning. When managers separate graphics from story, they invite expensive emptiness. When they connect graphics to story from development onward, they help build images that carry emotional weight.

2.6 Literature Gap

The literature offers useful insight into virtual production, media labor, digital transformation, and VFX workflows, yet a practical management gap remains. Many sources explain what modern tools can do. Fewer explain how media managers should diagnose whether a production is ready to use those tools responsibly. Technical documentation often assumes a motivated production system. Production-studies scholarship can describe labor and culture but may not give managers an applied model for risk control. Trade case studies offer valuable detail, but they may emphasize success stories more than failure conditions. Professional bodies such as the Visual Effects Society curate virtual-production guidance for practitioners, yet resources of that kind rarely formalize a diagnostic for managerial readiness (Visual Effects Society, n.d.).

The work here addresses that gap by building a graphics-governance model for film management. The model is not presented as a universal law. It is a decision aid. Its value lies in making hidden risk discussable before it becomes expensive. If a project has weak previsualization, unstable approvals, underdeveloped assets, thin artist capacity, and a director who has not committed to the look, the model should produce a warning. If a project has strong preparation, clear creative authority, reliable version control, tested on-set integration, and disciplined review, the model should show higher delivery control. Numbers cannot replace judgment, but they can force judgment into the open.

Chapter 3: Methodology and Analytical Framework

The methodology is an integrative, evidence-synthesis design. It synthesizes scholarship, industry practice material, and case evidence to produce a management model. This design is appropriate because the subject crosses academic, technical, and industrial domains. A purely theoretical study would miss production realities. A purely technical study would miss media-management questions. A purely trade account would risk becoming promotional. The integrative method allows the paper to compare evidence across source types while keeping management judgment at the center.

The research does not claim access to confidential production budgets, vendor contracts, internal schedules, or studio performance data. That limitation is important. Film projects often protect the very information that would allow the strongest empirical testing: cost overruns, change orders, approval histories, artist hours, render failures, vendor disputes, and late-stage rework. Because those records are not publicly available for most productions, the paper uses documented cases and builds a framework that future researchers could test with internal data.

The evidence base includes four case clusters. The first is ILM’s StageCraft workflow and the public history of The Mandalorian’s LED-volume production. The second is Weta FX’s virtual-production and Avatar-related work, with production details from official and trade sources. The third is Netflix’s VFX and virtual-production guidance, including best-practice documents and technology writing about validation for Unreal Engine. The fourth is recent research on real-time rendering pipelines for independent live-action filmmaking, especially work that considers how virtual production can be adapted outside large studio budgets. These cases were chosen because they represent different scales and management problems.

3.1 Research Design

The design uses documentary case analysis rather than interviews. Documentary case analysis examines written, public, and traceable materials to identify patterns. In media research, this method is useful when access to active productions is limited but credible materials exist. The method requires caution. Official studio materials often emphasize success. Trade interviews may understate conflict. Academic research may generalize from controlled examples that do not fully match commercial pressure. Sources are therefore read critically, used to identify management principles rather than to make unsupported claims about private production decisions.

The analysis moves through four connected steps. It defines the management problem that modern graphics create, then reads the literature and practice materials to surface recurring risk categories. Those categories become the lens through which the case evidence is examined. The closing step builds the Graphics Production Management Probability Model and the Graphics Management Risk Ratio. The model is intentionally practical. It gives media managers a way to structure questions before committing to a workflow, stage plan, vendor strategy, or graphics budget.

The work follows an applied master’s-level standard. It does not seek abstraction for its own sake. Every concept is tied to a production question. Preproduction governance asks whether the project has locked enough creative decisions before expensive work begins. Asset/version control asks whether the production can locate, update, approve, and protect the digital material it depends on. On-set graphics integration asks whether digital and physical production can work together without delay. Review discipline asks whether approvals are clear and timely. Labor capacity asks whether the human system can carry the required volume of work.

3.2 Source Selection and Evaluation

Sources were selected according to relevance, credibility, and traceability. Peer-reviewed materials were used for broad conceptual grounding, especially on virtual production, production workflows, digital transformation, and visual-effects labor. Official studio and platform sources were used for case details, with the understanding that such sources may present the institution favorably. Trade sources were used where they provided specific production information not available in academic literature. Public guidance from Netflix was used because it reveals practical standards around file exchange, VFX quality, ambiguity reduction, and workflow validation.

Greater weight goes to sources that are peer-reviewed, official, or clearly tied to production practice. It avoids unsupported claims about exact budgets, private conflicts, or confidential workflow failures unless those claims are documented. It also avoids treating a single successful case as proof that a method should be adopted everywhere. StageCraft, Weta FX, and Netflix represent high-resource settings. Independent virtual production research is therefore included to prevent the paper from assuming that large-studio capacity is the normal condition for all filmmakers.

Evaluation also considered sector relevance. A source about video-game rendering may be technically useful but not sufficient for film management unless it speaks to cinematic workflow, performance, or production decision-making. A marketing article about virtual production may show industry language but cannot be treated as strong evidence by itself. A trade interview can provide valuable technical detail, but its claims must be read alongside managerial constraints. The result is a balanced evidence base suitable for the purpose of model-building.

3.3 Graphics Production Management Probability Model

The Graphics Production Management Probability Model estimates the likelihood that a graphics-heavy film project will reach controlled delivery. Controlled delivery means that the project can deliver the required graphics to an acceptable creative, technical, budgetary, and schedule standard without extraordinary rework or damaging labor pressure. The model is expressed as a logistic function because production control is not linear. A small improvement in governance may matter little when the project is already chaotic; the same improvement may matter greatly when the project is near readiness. Likewise, severe risk can push a project below a threshold where normal management tools no longer work.

The model is written as follows: P(CDᵢ) = 1 / (1 + exp(−Zᵢ)). Here P(CDᵢ) is the probability of controlled delivery for project i, and the linear predictor is Zᵢ = β₀ + β₁·PGᵢ + β₂·AVCᵢ + β₃·PVᵢ + β₄·OSIᵢ + β₅·RDᵢ + β₆·LCᵢ − β₇·SCᵢ − β₈·RRᵢ − β₉·VFᵢ. PG means preproduction governance. AVC means asset and version control. PV means pipeline visibility. OSI means on-set integration. RD means review discipline. LC means labor capacity. SC means schedule churn. RR means render and revision rework. VF means vendor fragmentation.

Each variable can be scored from 0 to 100 during a production readiness review. Higher scores in PG, AVC, PV, OSI, RD, and LC increase the probability of controlled delivery. Higher scores in SC, RR, and VF reduce it. The coefficients are left unfixed here because they require empirical testing. A studio, film school, production company, or research team could estimate them using historical project data. The formula therefore works as a structure for disciplined assessment rather than a claim of universal statistical proof.

The strength of the logistic model is that it shows how multiple conditions interact. A project may have strong creative design but weak asset control. Another may have excellent software but poor review discipline. Another may have a capable vendor but unstable direction from the director or studio. The model prevents managers from hiding behind one strength. It asks whether the whole production system is ready. A single high score cannot protect a weak system forever.

3.4 Graphics Management Risk Ratio

The second mathematical tool is the Graphics Management Risk Ratio. It is simpler than the probability model and can be used early in development. It is written as a ratio of risk to control: GMRR = (SC + RR + VF + ACU) / (PG + AVC + PV + RD). SC is schedule churn, RR is render and revision rework, and VF is vendor fragmentation, while ACU, approval-chain uncertainty, isolates the most volatile part of review discipline so the ratio can be read before a full readiness review exists. PG, AVC, PV, and RD keep the meanings already defined. A higher ratio signals greater danger. A ratio above 1.00 means risk factors are stronger than control factors. A ratio below 1.00 suggests that management controls are stronger than the visible risk burden.

The ratio is useful because it gives producers a quick way to compare projects or versions of the same project. For example, a film that adds major creature work after financing but before clear design approval may see its risk ratio increase sharply. A production that introduces a central asset database, locks visual rules early, and reduces approval layers may lower the ratio. The tool does not replace a schedule or budget. It tells managers whether the schedule and budget are being asked to carry more uncertainty than they can reasonably absorb.

The GMRR also gives language to difficult meetings. Instead of saying that a director is being indecisive or that a vendor is underperforming, a manager can say that approval-chain uncertainty and rework are pushing the project above the risk threshold. That language is less personal and more useful. It focuses the team on causes. It also protects workers because it makes hidden management failure visible before the pressure falls entirely on artists and coordinators.

3.5 Visual Framework and Diagnostic Materials

Three visual tools support the analysis. Figure 1 compares managerial pressure between a traditional late-VFX workflow and a managed virtual-production workflow. The scores are not external statistics; they are author diagnostic scores derived from the case synthesis. Their purpose is to show how pressure shifts when graphics work moves earlier. Previsualization lock, asset control, on-set graphics, and review speed improve in the managed virtual-production setting, while post rework declines. The figure is not a claim that virtual production always reduces cost. It shows the management logic: earlier decisions can reduce late repair when the system is prepared.

Figure 2 presents a managerial attention mix for graphics-heavy filmmaking. Creative alignment receives the largest share because graphics have no value without narrative purpose. Asset/version control follows closely because digital confusion can destroy time. Set integration, review and approval, and labor capacity complete the mix. The pie chart is deliberately simple. It reminds managers that the problem is distributed. A graphics-heavy film cannot be managed only by purchasing software, hiring a famous vendor, or adding post-production weeks. It needs balanced attention.

Figure 3 compares four case clusters through diagnostic scores: StageCraft workflow, Avatar/Weta workflow, Netflix pipeline guidance, and independent virtual-production workflow. Again, the scores are interpretive rather than confidential production data. They show a plausible management pattern. High-resource cases tend to show stronger delivery-control capacity, though they still carry risk burdens. Independent workflows may have lower control capacity and higher risk burden because they often lack the infrastructure, personnel depth, and testing time available to major studios. The point is not to rank prestige. The point is to ask what kind of management system a production can actually support.

Figure 1. Production-management shift in graphics-heavy filmmaking.

Figure 2. Managerial attention mix for modern graphics production.

Figure 3. Case-based diagnostic contrast for graphics governance.

Table 1. Graphics Production Governance Matrix

Governance area Management question Failure signal Corrective action
Preproduction governance Are visual rules, priorities, and approvals clear before costly work begins? Repeated redesign, unclear story-world rules, weak asset lock Create a visual bible; approve key looks; define decision owners
Asset/version control Can the team locate, update, secure, and approve digital material without confusion? Duplicate assets, wrong versions, lost files, mismatched color or scale Use naming rules, asset database, lock dates, and access controls
Pipeline visibility Does management know where each shot and asset sits in the workflow? Late surprises, invisible bottlenecks, poor vendor reporting Use shared dashboards, status categories, and weekly risk review
On-set integration Are physical and digital teams ready to work together during the shoot? Stage delays, mismatched lighting, camera-tracking errors Run tests, rehearse cues, involve VFX and camera departments early
Review discipline Are notes clear, consolidated, timely, and tied to approval authority? Contradictory notes, taste drift, stalled approvals Set note protocol, limit approvers, separate exploration from final approval
Labor capacity Can the human system carry the graphics volume without destructive pressure? Overtime spikes, burnout, vendor distress, falling quality Re-scope, add support, revise schedule, or reduce graphics ambition

Note. The matrix is designed as an applied diagnostic tool for graphics-heavy film projects. It is not based on confidential studio data.

Chapter 4: Case Analysis

The case analysis examines how modern graphics become manageable or dangerous in real production contexts. Each case shows a different relationship between creativity, technology, and management. StageCraft emphasizes early digital-environment preparation and on-set integration. Weta FX and Avatar emphasize large-scale world-building, motion capture, performance translation, and long-cycle research and development. Netflix emphasizes pipeline standards, validation, and distributed production discipline. Independent virtual-production research emphasizes adaptation under resource limits. Together, these cases show that modern graphics are not a single method. They are a family of production choices that require different forms of control.

The case analysis avoids two common errors. The first is technological hero worship. A tool can be impressive and still poorly suited to a project. The second is nostalgic rejection. Practical effects and location work remain powerful, but rejecting digital graphics as artificial ignores how deeply digital work now supports even realistic films. The useful question is not whether graphics should dominate filmmaking. The useful question is when, why, and how graphics should be governed so they serve the film rather than overwhelm it.

Read also: Editorial Trust and Platform Power in New York Digital Publishing

4.1 Case One: StageCraft and The Mandalorian

The Mandalorian became one of the most discussed examples of modern virtual production because ILM’s StageCraft workflow made LED-volume filmmaking visible to a wider industry audience. ILM described the system as a new workflow using real-time game-engine technology and LED screens to capture many complex visual-effects shots in camera (Industrial Light & Magic, 2020). The important management lesson is that the virtual set is not simply a backdrop. It is a production environment that has to be designed, approved, tested, synchronized, and maintained. The LED wall changes who must be ready before the camera rolls.

In a conventional green-screen workflow, many background decisions can be delayed into post-production, although good VFX planning still matters. In a StageCraft-style workflow, the background must exist in usable form before shooting. This creates a stronger demand for early art direction, camera planning, color testing, and asset readiness. It can reduce some downstream uncertainty, but it increases upstream responsibility. The producer has to fund preparation. The director has to commit to visual choices. The art department, VFX team, camera department, lighting team, and real-time engine team must operate as one production unit.

The system also changes performance and cinematography. Actors are not facing an empty color field; they can respond to a visible world. Reflections and interactive light can appear on costumes, helmets, skin, and props. Camera operators and cinematographers can frame against the environment in real time. These benefits have management value because they can reduce guesswork. Yet they depend on readiness. If the digital world is unfinished or wrong, the apparent advantage can become delay. A virtual-production stage is not forgiving when the image pipeline is weak.

StageCraft therefore demonstrates a broader principle: graphics management succeeds when it moves decision-making earlier without pretending that early decisions are free. A production cannot simply transfer post-production labor to pre-production and call it efficiency. It must redesign budget, staffing, schedule, approvals, and rehearsal around the transfer. The media manager’s task is to ask whether the production has actually paid for the new workflow or merely adopted its language.

4.2 Case Two: Weta FX, Avatar, and World-Building Discipline

The Avatar films represent a different scale of modern graphics management. Weta FX describes virtual production as the meeting of physical and digital worlds and identifies Avatar as a major moment because Cameron wanted to direct live actors on a motion-capture stage while viewing performances inside the fictional world of Pandora (Weta FX, n.d.). The management problem here is not a single LED-volume workflow. It is the long-term governance of an invented world. Creatures, bodies, water, plants, skies, facial expression, movement, language, and physical laws have to appear consistent across thousands of shots.

Trade reporting on Avatar: The Way of Water describes the production as involving thousands of visual-effects shots, with Weta FX handling a very large share and water work forming a major technical challenge (PostPerspective, 2023). The exact production methods are more complex than any short case summary can capture, but the managerial lesson is clear. When graphics define the story world, the production must build and protect a visual system. The problem is no longer how to add effects to a film. The problem is how to make the film’s reality.

Such world-building requires patient research and development. Water simulation, facial performance, underwater capture, creature animation, and environmental coherence do not emerge from last-minute instruction. They require testing, failure, recalibration, and artistic control. This has implications for financing. A producer cannot responsibly approve a film of that kind while budgeting graphics as a late cost line. The graphics are the film’s production body. They must be treated as a central budget and schedule driver.

The Avatar case also shows why management must protect aesthetic coherence. A large graphics team can produce many impressive elements, but the film will fail visually if those elements do not belong to the same world. Coherence requires leadership: directors, production designers, VFX supervisors, art directors, cinematographers, and producers must keep returning to the same questions. What is the physical logic of this world? How does light behave? How do bodies move? What level of stylization is allowed? Which designs are locked, and which remain open? Without such discipline, scale becomes fragmentation.

4.3 Case Three: Netflix, Pipeline Standards, and Distributed Control

Netflix provides a useful case because its production environment depends on scale, distribution, and standardization. The company supports many forms of content across regions, vendors, genres, and production sizes. Its public VFX best-practice guidance states that image exchange between finishing facilities and VFX vendors affects quality, schedule, and cost and that the guidance is intended to reduce errors and ambiguity (Netflix Partner Help Center, n.d.-a). This is a management statement as much as a technical one. Errors and ambiguity are not harmless. They accumulate into delay, rework, and conflict. The company also maintains a public explainer that frames virtual production for the partners it works with (Netflix Partner Help Center, n.d.-b).

Netflix Technology Blog’s writing on a validation framework for Unreal Engine in virtual production points to another managerial need: testing. Real-time engines are powerful, but a production cannot assume that every version, plug-in, asset, display system, or hardware configuration will behave predictably under film conditions (Netflix Technology Blog, 2022). Validation is the institutional answer to enthusiasm. It asks whether the tool works under the conditions in which the production intends to use it.

The Netflix case is important because modern media organizations often manage portfolios rather than single projects. A studio, streamer, or network may support many productions at different stages. Without shared standards, every production invents its own naming systems, delivery assumptions, security habits, and review routines. That freedom can look creative, but it often creates waste. Standardization does not have to kill artistry. When done intelligently, it removes avoidable confusion so creative workers can focus on decisions that matter.

Pipeline standards are especially important for distributed labor. A VFX vendor in one city may receive plates from a production in another country, animation from a separate team, notes from a showrunner, color decisions from a finishing house, and security instructions from the studio. The more distributed the work, the more management must protect clarity. Netflix’s public guidance offers a practical example of how large media organizations try to control this complexity through documentation, validation, and workflow norms.

4.4 Case Four: Independent Virtual Production and Resource Discipline

High-end case studies can mislead independent filmmakers if they are treated as universal models. An independent production cannot simply imitate StageCraft or Avatar. It may not have access to a large LED volume, deep R&D teams, extensive asset libraries, or long testing periods. Recent research on real-time rendering pipelines for independent live-action films is therefore valuable because it asks how virtual production can be functional at smaller scales (Silva Jasaui, 2024). The lesson is not that independent productions should avoid modern graphics. The lesson is that they must match ambition to capacity with unusual honesty.

Independent filmmakers may benefit from previsualization, virtual scouting, real-time environments, and lower-cost rendering tools. These methods can improve planning and reduce some location or set costs. They can also create traps. A small team may underestimate the labor needed for usable assets. A director may become seduced by a software demo that does not reflect production constraints. A low-cost LED arrangement may introduce lighting, moire, color, or perspective problems. A project may save money on travel and lose it through rework.

Resource discipline is therefore the heart of independent graphics management. The manager must ask which graphics are essential to the story and which are vanity. The production should design fewer, stronger digital moments rather than many weak ones. It should test the workflow before committing. It should choose visual concepts that match available tools. It should avoid promising the audience a world it cannot make credible. In low-budget filmmaking, restraint is not defeat. It is often the condition of artistic survival.

The independent case also matters for education. Film schools and media programs increasingly introduce students to virtual production, game engines, and digital design. The danger is that students may learn tool operation without production judgment. A master’s-level media-management curriculum should teach students how to evaluate readiness, budget risk, workflow capacity, and labor ethics. Knowing how to open a software package is not the same as knowing how to manage a film that depends on it.

4.5 Cross-Case Findings

The cases point to several shared findings. Modern graphics reward early decision-making: whether the production uses an LED volume, motion capture, a distributed VFX pipeline, or independent real-time rendering, the project grows stronger when design and workflow are tested before expensive production days. Graphics management also depends on clear authority, since a production must know who approves visual direction, who resolves conflict, who controls version lock, and who can authorize major changes. The technical pipeline, in turn, is a creative system; file formats, color management, naming conventions, and review platforms may seem administrative, yet they directly shape artistic time and image quality.

Labor capacity cannot be wished into existence; a film may own the software and hardware yet lack enough artists, coordinators, supervisors, or pipeline support. Modern graphics also demand ethical attention, because rework and poor planning so often transfer pressure to the workers least able to refuse it. Scale changes the problem but does not remove it. A major studio may have stronger infrastructure but face larger complexity. An independent team may have fewer shots but less margin for error. Management intelligence is required at both levels.

The most important cross-case finding is that graphics-heavy filmmaking is a decision system. Every asset, shot, environment, and review note is tied to prior decisions and future consequences. The myth of infinite digital flexibility is one of the most dangerous myths in modern film production. Digital tools are flexible, but labor, time, money, attention, and audience patience are limited. Good media management protects those limits.


Chapter 5: Discussion

The discussion returns to the central argument: modern graphics do not manage themselves. A production may acquire advanced technology and still fail artistically or financially if it lacks the human and organizational discipline to use it. The managerial problem is not simply complexity. Film has always been complex. The new problem is the fusion of physical and digital production at nearly every stage. That fusion changes the timing of decisions, the distribution of labor, and the meaning of production control.

The model developed in Chapter 3 gives managers a way to read this complexity. It asks whether the production has sufficient preproduction governance, asset/version control, pipeline visibility, on-set integration, review discipline, and labor capacity. It also asks whether schedule churn, rework, and vendor fragmentation are rising. These are not abstract variables. They are everyday production realities. A producer can sit in a readiness meeting and score them. The value of the model lies in the conversation it forces.

5.1 Management Lessons for Producers and Executives

The first lesson is that graphics decisions must be financed early. Producers often resist early spending because development and pre-production already feel financially exposed. Yet graphics-heavy projects can become more expensive when early planning is underfunded. Concept art, previs, technical tests, asset prototypes, and workflow rehearsals may look like optional costs until the production discovers that the shoot depends on them. A media manager should treat early graphics preparation as risk insurance, not decorative overhead.

The second lesson is that executives must respect decision locks. Studio or investor intervention is sometimes necessary, especially when the film is drifting or the market context changes. But late changes to graphics-heavy work are rarely simple. A new design, scene restructure, or story note can affect many assets, shots, vendors, and departments. Executives who demand changes without understanding downstream cost are making hidden budget decisions. Responsible management makes those costs visible before approval.

The third lesson is that producers should not let software vendors define the production strategy. Tools matter, but a film is not a demo reel. The workflow must fit the story, budget, crew, schedule, and distribution need. A producer should ask what the tool solves, what new problems it creates, what training it requires, what dependencies it introduces, and what happens if it fails. Mature media management welcomes innovation without surrendering judgment.

The fourth lesson is that review culture determines cost. A production with slow, vague, or contradictory notes will waste money no matter how talented the artists are. Review discipline means that notes are specific, consolidated, timely, and tied to story purpose. It also means that approvers understand the difference between a necessary change and personal taste drift. Creative leadership should be strong enough to refine without endlessly reopening decisions.

5.2 Lessons for Production Managers and VFX Supervisors

Production managers and VFX supervisors sit at the point where creative ambition meets operational reality. Their relationship is decisive. A production manager who sees VFX as a distant post-production department will miss critical dependencies. A VFX supervisor who speaks only in technical language may fail to secure the production support needed for good work. Both roles require translation. They must translate story into tasks, tasks into schedules, schedules into budget, and budget into choices.

A useful practice is the graphics-readiness review. Before principal photography or virtual-stage booking, the team should examine the status of key assets, approval chains, color and camera tests, vendor assignments, storage and security, reference capture, editorial handoff, and contingency. The review should not be a ceremonial meeting. It should have authority to pause, reduce, redesign, or resequence work. A readiness review that cannot change decisions is only theatre.

VFX supervisors also need protection from impossible expectations. They are often asked to make the image possible after other departments have made choices without enough technical consultation. Strong media management gives the supervisor a voice early enough to prevent avoidable problems. This is not about giving technical departments control over the film. It is about recognizing that creative authority without technical knowledge can become expensive fantasy.

Production managers should also track rework as a warning signal. Some revision is healthy. Film is an iterative medium. But repeated rework for the same issue suggests a deeper governance failure: unclear direction, weak approval, unstable story, poor reference, or inadequate technical testing. The question is not whether artists can revise. The question is why they are revising.

5.3 Modern Graphics and the Director’s Authority

The rise of modern graphics does not reduce the director’s importance. It changes the kind of discipline required from the director. A director working with heavy graphics must develop clear visual language earlier than a director relying mostly on captured reality. They must understand what can remain open and what must be decided. They must listen to supervisors without losing artistic command. They must give notes that are precise enough to guide labor and flexible enough to allow artistic discovery.

Some directors thrive in this environment because they treat technology as a way to see and shape the film more clearly. Others struggle because they confuse infinite digital possibility with creative freedom. Freedom without decision becomes drift. A production can spend weeks exploring versions of a creature’s face, a city skyline, or a virtual sunset without improving the story. The director’s task is to know when the image has become meaningful enough to move forward.

Media management can support the director by building decision rituals. Visual bibles, look books, previs reviews, asset-lock meetings, virtual scouts, shot-priority lists, and final-note protocols help creative authority become operational. These tools do not make the film less artistic. They protect artistry from confusion. The director remains the artistic center, but the center must communicate clearly with the system around it.

5.4 Audience Trust and the Problem of Empty Spectacle

Audience trust is easy to underestimate. Viewers may accept impossible worlds if those worlds obey their own emotional and visual rules. They may reject expensive images if the film seems to ask for awe without earning it. Modern graphics can produce emptiness when management allows spectacle to replace dramatic need. A chase may become bigger without becoming more tense. A creature may become more detailed without becoming more alive. A city may become more enormous without becoming more memorable.

This problem belongs partly to writing and directing, but management is involved because budgets and schedules express priorities. If the largest share of visual attention goes to scale while character scenes are rushed, the film may betray its own story. If marketing demands trailer moments before the script has solved its emotional structure, graphics teams may be asked to decorate weakness. A serious media manager should defend the story from empty expansion.

The audience also responds to consistency. In a graphics-heavy film, inconsistency can damage belief. Lighting may not match. Physics may shift. Digital characters may look more finished in one sequence than another. Environments may feel disconnected. These are aesthetic problems with management causes. Consistency requires time for look development, unified supervision, careful review, and quality control. The final image carries the memory of the production system that made it.

5.5 Education and Training Implications

Media-management education should adjust to the realities described above. Students need to learn budgeting, scheduling, contracts, leadership, and distribution. They also need graphics literacy. That does not mean every student must become a VFX artist or Unreal Engine specialist. It means that future managers should understand enough to ask intelligent questions. What must be built before the shoot? What is an asset? What is a version? What is a render dependency? What is a color pipeline? What does an approval delay do to a vendor? What risks appear when live-action and digital environments meet on set?

A master’s-level course could use case simulations. Students might be given a script with ten graphics-heavy sequences and asked to design a management plan. They would have to choose which scenes use practical sets, which use virtual production, which use post VFX, and which should be rewritten to reduce risk. They would prepare a budget-risk memo, a graphics-readiness checklist, and a review protocol. Such assignments would train judgment rather than software operation alone.

Film schools should also teach labor ethics inside production planning. Students need to understand that late notes and poor planning affect real workers. They should learn how bidding pressure can damage vendors, how credit practices shape careers, and how inclusion failures limit the field. Modern graphics are not just images. They are workplaces. Education should make that visible.

5.6 Ethical and Legal Issues

Modern graphics raise ethical and legal issues beyond labor pressure. Digital doubles, facial capture, de-aging, synthetic extras, AI-assisted image generation, and asset reuse create questions around consent, authorship, likeness rights, and credit. A media manager cannot treat these issues as legal paperwork handled after creative decisions are made. They must be considered during development, casting, contracting, and post-production planning.

The expansion of AI-assisted film tools makes this concern sharper. Tsiavos (2025) identifies ethical concerns around authorship, creative integrity, and labor displacement in the film industry’s AI transformation. Even with graphics and virtual production as the main focus, the AI issue cannot be ignored because modern graphics pipelines increasingly include machine-learning tools for rotoscoping, upscaling, facial work, asset generation, and review support. The managerial question is not only whether a tool saves time. It is whether the tool respects rights, preserves creative accountability, and avoids exploiting unlicensed labor or images.

Data security is another issue. Modern graphics workflows move large volumes of unfinished material through platforms, vendors, clouds, and review systems. Leaks can damage marketing plans, violate contracts, and expose artists or actors to public scrutiny before work is complete. Security is not separate from creativity. A team that cannot share material safely may slow review and damage collaboration. A team that shares carelessly may create legal and reputational risk. Media management has to balance access with protection.


Chapter 6: Recommendations

The recommendations are written for producers, media executives, film-school leaders, production managers, post-production supervisors, and VFX supervisors. They are practical because the topic is practical. A film either manages its graphics system or suffers from it. The recommendations do not require every production to adopt the same technology. They require each production to make honest decisions about what its chosen technology demands.

Recommendation one is to create a graphics-governance plan during development. The plan should identify major graphics categories, expected assets, likely vendors, technical dependencies, visual-reference needs, approval authority, and risk areas. It should be updated during pre-production rather than filed away. A script with heavy graphics should not reach full budget approval without this plan.

Recommendation two is to conduct a graphics-readiness review before shooting or virtual-stage work begins. The review should score the project using variables from the Graphics Production Management Probability Model: preproduction governance, asset/version control, pipeline visibility, on-set integration, review discipline, labor capacity, schedule churn, rework risk, and vendor fragmentation. A low score should trigger redesign or delay. The point is not to punish ambition. The point is to prevent ambition from becoming negligence.

Recommendation three is to lock visual language early while preserving controlled areas for discovery. A production should know which assets are fixed, which are exploratory, and which can be revised only with executive approval. Locking everything too early may kill discovery. Leaving everything open too long will damage delivery. The answer is staged commitment.

Recommendation four is to integrate VFX and graphics supervisors into creative planning from the start. They should review scripts, storyboards, budgets, locations, set designs, camera plans, and schedule assumptions. Their role should not begin after problems are already embedded. Early consultation often saves money and protects artistic quality.

Recommendation five is to use clear review protocols. Notes should be consolidated, dated, assigned, and tied to approval levels. A project should distinguish between exploratory review, director review, studio review, technical review, and final approval. Confusing these stages creates delay. Review meetings should end with decisions, not vague encouragement.

Recommendation six is to protect labor capacity. Producers should budget realistic artist hours, coordinator support, pipeline support, and contingency. They should track overtime and rework. They should resist the practice of treating vendors as shock absorbers for poor planning. A production that cannot afford the labor required by its graphics ambition should change the ambition.

Recommendation seven is to build ethics into contracts and workflow. Digital likeness use, AI-assisted work, asset reuse, credit, confidentiality, and consent should be addressed before production. Waiting until conflict arises is weak management. Ethical clarity protects the project as well as the people in it.


Chapter 7: Conclusion

Modern graphics have changed filmmaking because they have changed management. They have moved visual decision-making upstream, blurred the line between physical and digital production, expanded the number of workers responsible for the final image, and made data governance part of creative governance. A film manager who does not understand this shift may still speak confidently about budget and schedule, but they will be missing the place where much of the film is actually being made.

The argument throughout has been that media management and modern graphics must be studied together. StageCraft shows how real-time environments and LED volumes can transform on-set production when preparation is strong. Weta FX and Avatar show what long-cycle world-building requires when the film’s reality is digital as much as physical. Netflix shows the importance of standards, validation, and ambiguity reduction in distributed workflows. Independent virtual-production research shows that modern graphics must be scaled to actual capacity. Across these cases, the same principle appears: technology helps only when management gives it direction, time, and discipline.

The Graphics Production Management Probability Model and the Graphics Management Risk Ratio provide practical tools for diagnosing risk. They do not reduce creativity to numbers. They make managerial assumptions visible. They help teams ask whether they have locked enough decisions, prepared enough assets, protected enough labor, clarified enough authority, and tested enough workflow before the project becomes too expensive to correct.

The final professional judgment is simple. Modern graphics are neither the future of cinema by themselves nor the enemy of cinema. They are a powerful set of image-making practices that can deepen story when governed well and weaken story when used carelessly. Media management is the difference between those outcomes. The best graphics-heavy films are not made by technology alone. They are made by people who know what the image is for, who respect the workers who build it, and who organize the production so that imagination can survive contact with time, money, and the screen.


Chapter 8: Applied Management Framework for Media Research

A master’s-level media paper should not end with praise for innovation. It should leave the reader with a method. The applied framework below converts the argument into a process that can be used by production companies, film schools, media researchers, and independent producers. The framework has six stages: concept diagnosis, graphics classification, workflow selection, readiness scoring, delivery monitoring, and post-project learning. Each stage is designed to prevent a familiar production mistake.

Concept diagnosis asks whether graphics are central, supportive, or avoidable. A central graphics project is one in which digital environments, characters, effects, or design systems carry the film’s identity. A supportive graphics project uses graphics to extend, correct, or enhance captured footage. An avoidable graphics project includes effects that may look attractive but do not meaningfully serve story or market value. This distinction matters because a central graphics project must be managed from the beginning. A supportive project needs disciplined integration. An avoidable project should be cut or reduced before it consumes resources.

Graphics classification breaks the work into categories: world-building, character work, environmental extension, simulation, screen graphics, invisible cleanup, stylized design, motion graphics, title design, and marketing assets. Classification helps prevent vague budgeting. A line item called “VFX” tells a manager little. A classified breakdown tells the production which work needs early design, which requires on-set reference, which depends on editorial lock, and which can be handled late without major risk. It also helps vendors bid with greater honesty.

Workflow selection asks whether a sequence should be handled through practical production, post-production VFX, virtual production, hybrid methods, or redesign. The choice should be based on story, cost, schedule, performer needs, location limits, safety, technical readiness, and audience expectation. A project should not use virtual production because it sounds modern. It should use it where the method solves a specific production problem. A cave interior, spaceship cockpit, impossible sunset, alien terrain, or dangerous travel setting may justify virtual production. A simple room scene may not.

Readiness scoring uses the probability model and risk ratio. This scoring should involve producers, department heads, supervisors, post-production leadership, and finance. Different departments may score the same variable differently, and those disagreements are useful. If executives score review discipline high while artists score it low, the production has learned something important. The score is not a verdict. It is a diagnostic conversation.

Delivery monitoring occurs during production and post-production. The same variables should be tracked repeatedly, not only at the beginning. A project may begin with strong control and lose it through story changes, staff turnover, vendor delays, or executive uncertainty. Monitoring should include change-order volume, review turnaround time, asset completion rate, shot approval velocity, overtime pressure, and rework frequency. These measures help managers intervene before the final months become unmanageable.

Post-project learning is often neglected because productions disband after delivery. Yet graphics-heavy projects create valuable knowledge. What assets were reusable? Which vendors performed well? Which approval process failed? Which tests saved money? Which assumptions proved false? A production company or film school should archive this learning. Without institutional memory, every project repeats old mistakes with new software.

8.1 Table and Figure Interpretation

Table 1 presents a graphics-production governance matrix. Its purpose is to connect management questions to failure signals and corrective action. A normal table might list departments and tasks. This matrix is more useful because graphics failure rarely belongs to one department alone. A late asset may reflect weak creative approval, insufficient modeling time, poor reference capture, or unclear vendor scope. The matrix encourages managers to diagnose the cause rather than blame the nearest team.

Figure 1 should be read as a pressure-shift map. It does not say that virtual production always beats traditional methods. Instead, it shows how a well-managed graphics workflow can move control earlier and reduce some late-stage pressure. The cost of that improvement is early preparation. Figure 2 should be read as an attention guide. Creative alignment and asset control receive the largest shares because a graphics-heavy film depends on meaning and organized material. Figure 3 should be read as a case-based warning. Major systems can show strong control and still carry real risk. Independent systems can be useful and still require sharper restraint.

The table and figures also demonstrate an important research principle. In media management, not every useful visual must be a claim of external measurement. Some visuals are analytical devices. They help organize professional judgment. The document marks them as diagnostic, not empirical. That distinction protects academic honesty while still giving managers tools they can use.

8.2 Practical Case Application: A Hypothetical Studio Film

Consider a mid-budget science-fiction film with one alien city, two digital creatures, several screen interfaces, and three action sequences requiring set extension. The director wants a strong visual identity but has not chosen between practical miniatures, LED-stage work, and post-production VFX. A weak management approach would approve the budget with a broad effects estimate and solve the details later. A stronger approach would classify the graphics and run a readiness review before major spending.

The alien city is world-building and should require early concept art, previs, scale rules, environmental logic, and asset planning. The digital creatures require performance reference, rigging tests, animation style approval, and creature-behavior rules. Screen interfaces may need graphic design continuity and on-set playback decisions. The action set extensions require camera planning, tracking strategy, location reference, and editorial assumptions. Once classified, the production may discover that only one sequence truly benefits from LED-stage work, while the rest can be handled through planned post-production VFX and partial practical builds.

Using the probability model, the production might score high on creative ambition but low on preproduction governance and review discipline. The GMRR may show that schedule churn and approval uncertainty are already too high. The corrective action would be to delay final budget approval for two weeks, produce a visual bible, assign a single approval path, test the creature workflow, and reduce one action sequence. The result may look less grand on paper, but it may produce a stronger film. Management is often the art of saving the film from its own wish list.

This example is hypothetical, but it reflects real production logic. Many graphics problems are born before the graphics team begins full work. They begin when a script promises images without managerial structure, when a budget hides uncertainty, or when creative leaders defer difficult choices. A well-designed framework can expose these issues early.

8.3 Practical Case Application: A Documentary or Factual Media Project

Modern graphics are not limited to fiction filmmaking. Documentaries, factual series, journalism, educational media, and historical reconstructions increasingly use maps, data visualization, animation, archival repair, virtual environments, and illustrative graphics. The management problem is different because truth claims are stronger. A fictional dragon must be believable. A documentary reconstruction must also be ethically marked and factually responsible.

A media manager working on a historical documentary should distinguish between evidence-based reconstruction, interpretive illustration, and speculative visualization. Evidence-based reconstruction uses verified sources such as photographs, maps, court documents, architectural plans, or eyewitness accounts. Interpretive illustration helps explain a process or event without claiming direct visual certainty. Speculative visualization fills gaps and must be labeled carefully. The graphics team should not be asked to create false precision.

This matters for media research because graphics can shape public understanding. A polished animation may persuade viewers even when the evidence behind it is thin. A map may make uncertain boundaries look settled. A reenactment may appear more factual than it is. Ethical media management therefore requires documentation of sources, review by subject experts, and clear visual language that distinguishes fact from reconstruction. The same tools that create wonder in fiction can create misinformation in factual media if they are poorly governed.

The graphics-governance model can be adapted for factual media by adding variables for evidentiary support, source transparency, and editorial review. A documentary with strong graphics but weak sourcing should be treated as high risk. A public-interest media project should never let design quality outrun evidence.

8.4 Sector Implications: Streaming, Advertising, and Short-Form Media

Streaming platforms have increased demand for high-volume screen production. This demand affects graphics management because more projects compete for artists, vendors, stages, render capacity, and supervisory talent. A streaming series may require film-quality graphics on a tighter television schedule. The schedule pressure can be intense because episodes overlap in writing, shooting, editing, and effects delivery. Media managers must plan graphics as an episodic pipeline, not as a one-time feature-film push.

Advertising and branded content bring a different challenge. Turnaround times are short, brand approval layers are heavy, and visuals may need to match strict identity rules. Modern graphics can help agencies produce product worlds, virtual sets, stylized transitions, and campaign assets. Yet approval uncertainty can be severe because clients, agencies, directors, legal teams, and platform teams may all have notes. Review discipline is therefore more important than tool choice. A thirty-second spot can become a management disaster if the approval chain is confused.

Short-form and social media content create another pattern. Creators may use graphics tools quickly, cheaply, and experimentally. The risk is not always budget overrun; it may be brand inconsistency, rights misuse, low-quality output, or burnout. Media managers in this sector need lightweight governance: asset libraries, rights checks, style guides, version control, and ethical rules for synthetic content. The same principles apply, but the process must be scaled to the pace of the medium.

8.5 Research Limitations and Future Study

The chief limitation of the present work is the absence of confidential production data. Access to such data would allow stronger testing of the proposed model. Future research should collect anonymized project data from production companies, VFX vendors, film schools, and independent filmmakers. Useful variables would include number of graphics shots, asset counts, review cycles, change orders, artist hours, render failures, overtime levels, approval delays, and final delivery outcomes. With enough data, the coefficients in the probability model could be estimated rather than proposed.

Future research should also include interviews. Producers, production managers, VFX supervisors, coordinators, artists, cinematographers, editors, and directors would likely describe graphics risk differently. Comparing those perspectives could reveal where misunderstanding enters the production system. For example, executives may believe a late change is minor because it affects only one sequence, while artists may know it affects an asset used across many shots. Interview research could make such gaps visible.

Another research direction is comparative study across national industries. Hollywood, Nollywood, Bollywood, European public-film systems, East Asian studios, and independent African media houses may manage graphics under very different financing, labor, training, and distribution conditions. A model built only from high-resource U.S. and New Zealand examples would be too narrow. Future work should test how graphics governance changes in industries with different budgets, crew structures, training systems, and audience expectations.

A further direction is the impact of AI-assisted graphics tools on management. The question is not whether AI will enter film production. It already has in many forms. The stronger question is how managers will govern consent, authorship, quality, labor displacement, and credit. The framework can be extended by adding AI-risk variables, though that work deserves its own focused study.

References

Atkinson, S. (2015). The performance and materiality of the processes, spaces and labor of VFX production. Spectator, 35(2), 36-46. https://cinema.usc.edu/spectator/35.2/5_Atkinson.pdf

Epic Games. (n.d.). What is virtual production? Unreal Engine. https://www.unrealengine.com/explainers/virtual-production/what-is-virtual-production

Industrial Light & Magic. (2020, February 20). Groundbreaking LED stage production technology created for hit Lucasfilm series The Mandalorian. https://www.ilm.com/groundbreaking-led-stage-production-technology-created-for-hit-lucasfilm-series-the-mandalorian/

Kotlinska, M. (2024). The influence of digital transformation on the evolution of the audiovisual industry. European Research Studies Journal. https://ersj.eu/journal/3702

Netflix Partner Help Center. (n.d.-a). VFX best practices. Netflix Studios. https://partnerhelp.netflixstudios.com/hc/en-us/articles/360000611467-VFX-Best-Practices

Netflix Partner Help Center. (n.d.-b). What is virtual production? Netflix Studios. https://partnerhelp.netflixstudios.com/hc/en-us/articles/1500002552642-What-is-Virtual-Production

Netflix Technology Blog. (2022, August 10). Virtual production: A validation framework for Unreal Engine. https://netflixtechblog.com/virtual-production-a-validation-framework-for-unreal-engine-aab780b2f8c8

PostPerspective. (2023, January 5). Avatar: The Way of Water: Weta’s Joe Letteri on VFX workflow. https://postperspective.com/avatar-the-way-of-water-wetas-joe-letteri-on-unique-vfx-workflow/

Silva Jasaui, D. (2024). Virtual production: Real-time rendering pipelines for indie live-action films. Applied Sciences, 14(6), 2530. https://doi.org/10.3390/app14062530

Smith, S. L., Choueiti, M., Pieper, K., Case, A., & Choi, A. (2021). Invisible in visual effects: Understanding the prevalence and experiences of women in the field. USC Annenberg Inclusion Initiative. https://assets.uscannenberg.org/docs/aii-study-women-in-visual-effects-2021-11-04.pdf

Tsiavos, V. (2025). The digital transformation of the film industry: How artificial intelligence impacts the film value chain. Telecommunications Policy. https://www.sciencedirect.com/science/article/pii/S0308596125001181

Visual Effects Society. (n.d.). Virtual production publications. https://vesglobal.org/virtual-production-publications/

Weta FX. (n.d.). Virtual production. https://www.wetafx.co.nz/research-and-tech/technology/virtual-production

The Thinkers’ Review

Martha N. Amadi

Managing Nursing Work for Safer Care

Staffing, Clinical Governance, and Patient Protection

Research Publication by Martha N. Amadi

Institutional Affiliation: New York Center for Advanced Research (NYCAR)

Master’s-Level Publication Paper

Publication Number: NYCAR-TTR-2026-RP066

DOI: https://doi.org/10.5281/zenodo.20744307

Date: June 2026

Copyright © Martha N. Amadi, New York Center for Advanced Research (NYCAR), June 2026. All rights reserved.

Peer Review Status

Reviewed under the internal editorial framework of the New York Center for Advanced Research (NYCAR) and The Thinkers’ Review. The review covered master’s-level coherence, nursing-management relevance, evidence restraint, APA 7th citation practice, table accuracy, model boundaries, and publication readiness.

Contents

Abstract

Unsafe nursing work rarely collapses in one dramatic moment. More often, it thins out during an ordinary shift. A call bell waits too long. A new nurse decides alone because the senior nurse has been pulled into task work. A medication round is interrupted twice, then three times. A resident is not turned early enough because every aide is already occupied somewhere else. By the time a fall, pressure injury, drug error, complaint, or resignation is recorded, the service may have been giving warnings for weeks.

The study places nursing organizational management inside the patient-safety argument. Staffing is not treated as a staffing-office problem, nor is acuity left as a number at the edge of the roster. The paper reads nursing time, skill mix, handover, supervision, missed care, retention, and staff strain as connected parts of the same clinical condition. Bedside nurses do not experience these pressures separately. They arrive together, often within the same hour, around the same patient or resident.

The Nursing Care Reliability Score introduced here is intentionally limited. It is not offered as a validated national tool, a prediction engine, or a substitute for the judgment of experienced nurses. Its purpose is narrower and more useful: to help local leaders place weak signals beside one another before harm becomes the only evidence anybody is willing to accept. A low score cannot shame a unit. It makes senior review harder to avoid.

The argument is blunt because the work deserves bluntness. Nurses cannot be thanked into safe practice. They need enough prepared staff, charge nurses who can lead, protected handover, honest acuity review, support for new colleagues, and governance that treats missed care as a warning rather than an embarrassment. A service that survives by using up its experienced nurses cannot call itself resilient. It is borrowing safety from people who are already overdrawn.

Keywords: nursing organizational management, staffing adequacy, acuity, skill mix, patient safety, clinical governance, missed care, burnout, retention, TeamSTEPPS, long-term care

Chapter 1: Introduction

1.1 Background to the Study

Good nursing often disappears into the fact that nothing went wrong. The confused patient does not fall. The insulin dose is checked before the wrong assumption hardens into an error. The wound edge is noticed while it is still only beginning to change. A frightened daughter leaves with enough understanding to call early if breathing worsens at home. These are not small acts. They are the daily products of attention, judgment, and organization.

Nursing care cannot be made safe by personal kindness alone. Compassion matters, but compassion is not staffing. A nurse can be careful, experienced, and morally serious, yet still be placed in unsafe work when patient need outruns available time. New staff do not become competent because a rota says they are counted. They become safer when someone with clinical maturity has time to watch, correct, encourage, and intervene.

Current workforce evidence makes the issue larger than a local complaint. WHO frames nursing supply through education, employment, leadership, regulation, and service delivery, while United States workforce survey evidence and the NHS long-term workforce plan both point toward the same managerial fact: recruitment, retention, training, and working conditions cannot be pulled apart without weakening care (NHS England, 2023; Smiley et al., 2025; World Health Organization, 2025).

Those national and global pressures reach managers in humble, irritating forms. A post stays open after three rounds of recruitment. The best preceptor asks for a transfer. An agency nurse arrives who is capable but does not know the unit, the stock room, the escalation habits, or the resident who refuses help until a familiar voice asks twice. The spreadsheet may still show coverage. The ward knows what has been lost.

Nursing organizational management belongs in patient-safety scholarship because patients meet managerial choices through care. They meet them in response time, observation, dignity, discharge teaching, infection control, continence support, and the availability of a nurse who can stay long enough to see what is changing. Administration is not sitting politely outside the clinical encounter. In nursing, it is one of the conditions that shapes the encounter.

1.2 Problem Statement

Nurse leaders are often held responsible for failures they lack the full authority to prevent. A ward manager may answer for falls, pressure injuries, medication delays, infection breaches, complaints, turnover, sickness, overtime, and staff morale while bed flow, budget control, establishment review, and recruitment pace sit at another table. That split is not a harmless administrative inconvenience. It trains people to soften the truth.

Soft wording can become a safety risk. Chronic short staffing is called temporary pressure. Missed breaks are praised as commitment. Late documentation becomes a personal weakness even when the work could not physically fit into the shift. Staying after duty is described as dedication, although it may be the clearest evidence that the staffing plan is false.

Fragmentation hides the pattern. Staffing appears in one meeting, burnout in another, quality in another, and turnover in a human-resources report that arrives after the ward has already changed. Nursing work is not organized that way. A weak roster damages handover. Poor handover weakens surveillance. Weak surveillance raises risk. Incidents increase strain. Strain pushes staff out. The next rota then begins weaker than the last.

This paper addresses that practical problem. It does not ask whether nurses care enough. Most nurses care well beyond what the system has any right to expect. The question is whether organizations arrange nursing work so that care can remain safe without unpaid rescue, private sacrifice, silence about omitted care, or the quiet burning up of experienced staff.

1.3 Aim and Objectives

The aim is to explain how nursing organizational management protects patient safety through staffing adequacy, acuity-sensitive assignment, skill-mix judgment, reliable handover, clinical governance, and retention discipline. The concern is not abstract leadership. It is the next unsafe shift: the delayed observation, the unsupported new nurse, the interrupted medicine round, the exhausted charge nurse, the family who did not really understand discharge instructions.

The objectives are to define nursing management as safety work; review current evidence on workforce pressure, staffing, burnout, teamwork, and long-term care; develop a limited local reliability score for managerial review; and connect the evidence to decisions that nurse managers, directors, executives, and boards can examine without pretending that a score replaces judgment.

Management vocabulary earns its place only when it touches the work. Words such as governance, improvement, and excellence mean little if the senior nurse cannot leave task work long enough to lead. A nursing-management paper has to survive the ward manager’s question: what changes on the next dangerous shift?

1.4 Research Questions

The guiding questions stay close to practice. Where does nursing management meet patient safety? How does a roster become unsafe before an incident proves it? Which signals show that care is being rationed? How do skill mix, supervision, handover, retention, and staff strain interact during real shifts? What can a local reliability review reveal without pretending to predict every harm event?

None of these questions assumes an easy cure. Workforce supply is slow, political, expensive, and uneven. Some services recruit in markets where the candidates are not there. Still, honesty is possible before rescue is possible. Leaders can stop calling unsafe staffing difficult but acceptable. They can record missed care as evidence. They can give nurses words that do not leave bedside staff carrying institutional failure alone.

1.5 Scope and Boundaries

The scope is nursing organizational management. The paper does not replace clinical guidelines, employment law, professional regulation, or human-resources policy. It examines the point where those systems meet the shift: patient dependency, admissions, discharges, staff experience, fatigue, equipment, handover, escalation, and the authority to act when the work is no longer safe.

Boundaries matter because blame is sometimes the cheapest form of governance. Nurse managers cannot be blamed for every condition produced by labor markets, funding decisions, training capacity, immigration rules, housing cost, reimbursement, or hospital demand. Accountability remains necessary. Blame without system review is not accountability; it is avoidance. A fall, pressure injury, infection breach, or medication error may be recorded against a unit, while the conditions behind it may have been authorized above the unit for months.

1.6 Working Definitions

Staffing adequacy means more than names placed in boxes on a roster. It means the available nursing time, knowledge, familiarity, and authority are sufficient for the patients or residents actually present. Acuity refers to the level of attention, dependency support, observation, coordination, teaching, and judgment a person requires. Skill mix refers to the fit between patient need and the capabilities, registration status, local familiarity, and supervision requirements of the team.

Clinical governance refers to the way a service knows, controls, and learns from risk. In nursing, it includes escalation, incident review, professional standards, staffing review, and the willingness to treat staff warnings as safety evidence. Missed care means necessary care that is delayed, shortened, or omitted because capacity and need no longer match.

1.7 Reading Position

Readers need to approach the work as managerial judgment grounded in evidence. Staffing, burnout, communication, retention, and patient safety can be separated for study, but nurses meet them together at the bedside. Practice scenes appear throughout the paper because ordinary scenes often carry the risk more honestly than formal phrases do.

Strong nursing scholarship has to avoid theatrical certainty. No framework can rescue a service that lacks staff, senior judgment, or the courage to say that the shift is unsafe. A framework can still help leaders notice deterioration earlier, argue more clearly, and protect patients with better discipline. That is a modest claim, but it is not a weak one.

1.8 Publication Need

The publication need comes from the gap between the way systems praise nurses and the way nursing work is often arranged. Health services celebrate nurses in public language while failing to examine the staffing, supervision, and authority that make safe care possible. That contradiction is not a public-relations problem. It is a patient-safety problem.

Graduate-level nursing management needs language strong enough for practice. It cannot hide behind generic leadership phrasing. The discipline has to describe the nurse who misses lunch again, the resident whose continence care is delayed, the new staff member learning too fast under pressure, and the manager who knows the shift is unsafe but cannot get an answer from above.

Chapter 2: Current Nursing-Management Evidence

2.1 Management Begins Before the Incident

A nurse manager begins safety work before the dashboard, before the monthly report, and well before the incident form. Assignment decisions, equipment readiness, shift balance, senior cover, handover protection, and the handling of staff warnings all shape the patient’s day. Harm may be documented at the end of a chain. The managerial conditions often sit near the beginning.

Patient-safety thinking has long warned against blaming the visible clinician while ignoring the work system. Nursing makes that warning concrete. Nurses are close enough to see confusion, pain, breathlessness, fear, family uncertainty, and quiet deterioration as they unfold. When there are too few nurses, or too little experienced judgment, the service loses part of its ability to see.

Burnout research adds weight to the point. Dall’Ora and colleagues link burnout with demands, control, recognition, fairness, and support, not with personal weakness alone (Dall’Ora et al., 2020). For managers, the implication is practical. Exhausted nurses have less recovery, less tolerance for interruption, less patience for avoidable confusion, and fewer reserves when a patient suddenly worsens.

Nursing management is not a decorative service around the clinical work. It protects the conditions under which clinical work is possible. A ward can have a fine policy file and still fail patients if the roster is fiction, handover is rushed, supervision is symbolic, and concerns raised by staff are treated as attitude.

2.2 Staffing Adequacy and the Lie of the Simple Number

Staffing adequacy is often reduced to headcount because headcount is easy to display. Serious nurse leaders know that the number is only the first question. Six nurses may be safe on one ward and unsafe on another. A roster may look full while two nurses are newly qualified, one is unfamiliar with the unit, and the charge nurse is carrying a heavy patient assignment.

Acuity brings the patient back into the staffing conversation. It asks what the work requires: close observation, turning, medicines, continence support, safeguarding, dementia care, isolation precautions, discharge teaching, nutrition, mobility, wound care, and family communication. Bed count hides much of that. A quiet bed is not always a low-workload bed.

Skill mix complicates the matter again. Registered nurses, licensed practical or vocational nurses, nursing assistants, healthcare assistants, and temporary staff all contribute, but they are not interchangeable pieces. Substitution may look efficient from a distance while moving risk into delegation, supervision, recognition of deterioration, and escalation. Longitudinal evidence continues to associate nurse staffing levels with patient outcomes, though settings and measures differ (Dall’Ora et al., 2022).

A reliable manager uses ratios as floors, not as proof. A ratio cannot say whether three admissions arrived late, whether half the team is unfamiliar with the unit, whether a dying patient’s family needs time, or whether the senior nurse can actually lead. Numbers can start the conversation. They cannot end it.

Table 1. Nursing Staffing Risk Controls

Risk control Managerial question Patient-safety meaning
Staffing adequacy Does available nursing time match the actual work on this shift? Weak staffing reduces surveillance, timeliness, teaching, documentation, infection control, and dignity.
Acuity fit Does the roster reflect dependency, instability, admissions, discharges, isolation, and observation need? Bed count alone can hide workload and create false assurance.
Skill mix Does the team have enough registered judgment, support staff, and locally familiar temporary staff? Unsafe substitution weakens delegation, supervision, and escalation.
Supervisory cover Is a senior nurse free enough to lead rather than simply fill a gap? New staff, unstable patients, and complex decisions need visible leadership.
Missed-care control What care has been delayed, shortened, or omitted, and why? Repeated omission warns that capacity and need have separated.


2.3 Missed Care as Early Warning

Missed care is sometimes pushed to the soft edge of nursing: delayed mouth care, late observations, shortened discharge teaching, a postponed walk, a resident turned later than planned. That view is careless. Missed care is the service rationing attention while hoping the result stays hidden.

Patients and residents may not speak the language of staffing adequacy, but they know its effects. They wait longer. They receive less explanation. They are moved before their fear is settled. A family leaves with paperwork but not understanding. In long-term care, one missed turn or delayed toileting episode may become skin breakdown, infection risk, distress, or humiliation.

Managers need to record missed care without turning the record into a trap. If nurses believe every omission will be used against them, silence becomes self-protection. A safer service asks what was left undone, why it was left, how often the pattern returns, and what decision would prevent the same failure next week.

2.4 Handover, Teamwork, and the Conditions for Communication

Handover is often described as a communication process. At ward level it is a safety exchange under strain. The outgoing team is tired. The incoming team needs the truth quickly. Relatives interrupt, phones ring, admissions arrive, and the ward does not stop because a form says handover time is protected.

TeamSTEPPS 3.0 provides useful language for communication, team leadership, situation monitoring, and mutual support (Agency for Healthcare Research and Quality, n.d.). Tools help. They do not work by magic. A check-back cannot rescue a team when the charge nurse is too overloaded to notice drift, or when staff who raise risk are quietly marked as difficult.

Reliable communication needs setting and authority. Nurses must know who is unstable, which families need attention, what medicines are risky, what has changed since the last review, and which staffing gaps require adaptation. Handover fails when leaders treat it as a courtesy. It is a safety control.

2.5 Retention, Experience, and Local Memory

Retention deserves a stronger place in safety debate. Losing a nurse removes more than one body from the rota. It removes local memory: which patient underreports pain, which corridor is unsafe at night, which junior doctor needs a firmer escalation, which family remains anxious because the last discharge was handled badly.

Workforce survey evidence points to continuing strain in the profession and the need to read age profile, employment movement, and intent-to-leave data carefully (Smiley et al., 2025). A manager who treats turnover as recruitment paperwork misses the clinical loss. A service can replace hours and still lose judgment.

Experienced nurses also carry culture. They teach what must be escalated, what cannot be ignored, and what staff are allowed to say aloud. When those nurses leave, new staff may inherit policies without the informal wisdom that kept patients safe. Retention is not sentiment. It is part of the safety system.

2.6 Evidence Read with Caution

Staffing research is strong enough to matter and complex enough to require restraint. Hospitals, long-term care homes, community services, mental health units, and specialist wards are not identical. Measurement varies. Patient need changes. Some outcomes are easier to count than dignity, teaching, trust, fear, or professional judgment.

Caution cannot become paralysis. Evidence does not need to answer every local question before leaders act on obvious risk. A unit with repeated missed care, thin supervision, heavy overtime, missed breaks, and rising exits already has enough information to begin. The question is whether leadership is willing to hear what the evidence and the nurses are saying.

2.7 What Experienced Nurses Notice

Experienced nurses notice small disorder before it becomes official risk. They see the patient who is too quiet, the aide rushing because continence care has fallen behind, the temporary nurse unable to find equipment, the new graduate smiling while drowning, and the relative who nods but has not understood the discharge plan. These observations are not gossip. They are part of the safety system.

Organizations often lose this intelligence because it arrives in the wrong form. A senior nurse may say the ward feels unsafe before a metric confirms it. Dismissing that warning because it sounds subjective is poor management. Skilled nursing judgment is often pattern recognition built from years of patient contact.

Leaders need to create regular spaces for that knowledge to be spoken without drama. A short end-of-shift review, a weekly staffing-risk conversation, or a protected meeting with charge nurses can reveal details no dashboard holds. The point is not to replace data with feeling. It is to stop pretending that numerical data is the only witness.

2.8 The Danger of Polished Assurance

Polished assurance can be dangerous in nursing services. Reports may say staffing was challenging but managed, communication remained effective, and teams continued to deliver safe care. The sentences sound calm. They may also erase the truth that nurses stayed late, skipped breaks, delayed care, and used private judgment to prevent a worse outcome.

Nursing evidence has to make assurance more honest, not more attractive. A leader can say no major incident occurred and also say the shift was not safely staffed. Both can be true. Absence of harm is not proof of safety. It may mean staff rescued the system one more time.

Chapter 3: Methodology and Analytical Framework

3.1 Design

Amadi uses an applied evidence-review design with management interpretation. The method reads public workforce reports, peer-reviewed nursing research, patient-safety material, policy documents, and practice-based management questions through a simple problem: how does the organization of nursing work affect the safety of care?

The design stays close to practice because a ward cannot be understood by theory alone. Theory helps name patterns. It does not hear the phone ringing during handover, see the agency nurse searching for equipment, or notice the new nurse who has stopped asking questions because everyone looks busy. The paper keeps returning to the shift because the shift is where management becomes visible.

No invented interviews, private patient records, or artificial datasets are introduced. Practice scenes are used as interpretive examples, not as claimed empirical findings. That boundary matters. Nursing scholarship weakens itself when it pretends to hold data it does not possess.

3.2 Evidence Sources

Core sources include WHO’s 2025 nursing report, the 2024 National Nursing Workforce Survey, AHRQ TeamSTEPPS 3.0 materials, staffing-outcome research, burnout research, NHS England workforce planning, Magnet-related nursing excellence material, and United States long-term care staffing policy documents (Agency for Healthcare Research and Quality, n.d.; NHS England, 2023; Smiley et al., 2025; World Health Organization, 2025).

Each source is used within its proper limits. WHO frames global workforce, leadership, education, regulation, employment, and service-delivery pressures. The workforce survey supports interpretation of United States employment and retention signals. TeamSTEPPS provides tested communication language, while the staffing and burnout literature helps connect nursing conditions with safety and organizational strain.

No source is asked to do more than it can do. A global report does not describe a single ward. A staffing study does not settle every local ratio. Teamwork training does not fix a false roster. Evidence gives direction; it does not relieve leaders of judgment.

Table 2. Evidence Sources and Management Use

Evidence source What it contributes Management use
WHO State of the World’s Nursing 2025 Global workforce, education, leadership, regulation, employment, and service-delivery picture. Places local staffing pressure within wider workforce and policy conditions.
2024 National Nursing Workforce Survey United States nursing workforce demographics, employment patterns, and retention evidence. Supports age-profile review, vacancy-risk interpretation, and retention planning.
AHRQ TeamSTEPPS 3.0 Communication, team leadership, situation monitoring, mutual support, and implementation tools. Strengthens handover and escalation when local conditions support the behavior.
CMS and Federal Register staffing material Policy movement around long-term care staffing minimums and later repeal action. Shows why resident need, labor supply, regulation, and provider capacity must be read together.


3.3 Analytical Logic

The analysis begins with the shift. Staffing plans, patient need, temporary cover, senior availability, handover quality, missed care, retention, and emotional strain are examined together because nurses experience them together. A clean organizational chart may separate these matters. Care does not.

A local reliability score is used to organize review. The Nursing Care Reliability Score is not a predictive model and not a validated national measure. It gives leaders a disciplined way to ask whether conditions for safe nursing are improving or fraying. Any formal use would require local validation, governance approval, adaptation, and periodic review.

Variables are scored from 0 to 5. A score of 0 indicates severe risk. A score of 3 indicates workable but unstable conditions. A score of 5 indicates strong reliability. The calculation is: NCRS = 0.16SA + 0.14AF + 0.13SM + 0.12HR + 0.12SC + 0.12MC + 0.11RR + 0.10SS. The weights add to 1.00. They reflect the evidence review and are made visible so leaders can challenge the assumptions rather than accept a hidden formula.

Table 3. Nursing Care Reliability Score Variables

Variable Meaning Evidence used in review
SA Staffing adequacy Planned versus filled roster, vacancies, agency use, overtime, missed breaks, and escalation records.
AF Acuity fit Dependency, complexity, admissions, discharges, observation level, isolation, deterioration risk, and family need.
SM Skill mix Registered nurse cover, assistant roles, agency familiarity, new staff, and preceptor availability.
HR Handover reliability Shift overlap, interruptions, attendance, transfer completeness, and recurring information gaps.
SC Supervisory cover Charge nurse availability, senior response, leadership workload, and coaching capacity.
MC Missed care control Reported omissions, delayed care, patient or family concern, and staff accounts of rationed work.
RR Retention resilience Turnover, internal transfer, sickness, exit themes, age profile, and loss of local experience.
SS Staff strain control Burnout indicators, moral strain, conflict, overtime, sickness, and recovery between shifts.


3.4 Interpreting the Score

A score near 5 suggests strong local reliability. It does not promise that no harm will occur. A score around 3 suggests a service that may function through effort but lacks margin. A score below 2.5 needs to trigger senior review because several safeguards are likely failing at once.

The score belongs beside narrative evidence. A unit may report acceptable numbers while staff describe unprotected handover, regular missed care, or a charge nurse unable to lead. Narrative does not contaminate the score. It protects the score from false precision.

Weighting carries an ethical message. If staffing adequacy and acuity fit carry significant influence, leaders cannot hide behind morale work while the roster remains unsafe. If missed care and staff strain are included, the score refuses to treat exhausted silence as success.

3.5 Quality Controls

Quality control begins with source discipline. Claims are tied to published research, official reports, or clearly marked management interpretation. Current policy is checked because staffing regulation changes. The paper avoids unsupported figures, invented interviews, and private claims.

A second control is voice. Nursing-management writing can slip into comfortable phrases that tell nobody how the work is actually done. The prose returns to assignments, handovers, missed care, supervision, and escalation because those details keep the paper honest.

A final control is restraint. The framework cannot repair a poor labor market, fund posts, or guarantee retention. It can make risk harder to deny. In nursing management, that is already a useful contribution.

3.6 Ethical Position

Ethics in this paper is not limited to confidentiality, although no private patient records are used. The deeper ethical issue is fairness in assigning responsibility. Bedside nurses cannot carry blame for organizational conditions they warned about but could not change. Managers cannot be given authority in title only. Patients cannot learn that arrangements were unsafe only after harm occurs.

Clear evidence, honest language, and visible escalation are ethical practices. They prevent a service from turning structural risk into personal failure. A nursing paper that ignores that conversion may sound orderly, but it will not be truthful.

3.7 Handling Local Evidence

Local evidence belongs close to the work. Roster data, overtime records, incident reports, staff sickness, agency use, missed-care notes, patient complaints, discharge delays, and staff accounts all matter. None is complete alone. A clean dashboard can hide exhausted practice. A strong complaint file can hide quiet families who no longer expect attention.

Useful review asks nurses to explain the numbers. If overtime rose, what drove it? If missed care fell, did care improve or did reporting become unsafe? If agency use remained stable, were the same agency nurses returning, or was the team receiving different people every week? Local interpretation keeps data from becoming decorative.

Documentation has to be plain enough for senior leaders to understand and specific enough for action. “High pressure” is not enough. Better evidence says the ward carried three high-observation patients, two late admissions, one unfamiliar agency nurse, no protected charge nurse, and delayed turns. Specific detail creates accountability.

3.8 Why the Model Stays Modest

The model stays modest because nursing work resists neat packaging. A score cannot feel the atmosphere on a ward after two resignations. It cannot know that a family has lost trust or that a new nurse is hiding fear. It can only organize selected signals and help leaders ask better questions.

That limitation is acceptable if it is named. Modest tools can still be useful. They prevent drift, support comparison over time, and force discussion of issues that might otherwise remain informal. Trouble begins when a tool is treated as proof instead of prompt.

3.9 Safeguards Against Cosmetic Compliance

Cosmetic compliance is a known danger in nursing management. A form may be completed, a huddle recorded, and a staffing review filed while the actual shift remains unsafe. The method therefore treats documentation as evidence only when it matches staff experience and visible operating conditions.

Reviewers need to ask whether a control changed the work or simply described it. Protected handover has to mean fewer interruptions, not a new heading in meeting notes. Preceptorship has to mean time to supervise, not a name beside a new nurse. Escalation has to mean a decision, not a forwarded email. These checks keep the framework close to practice.

Chapter 4: Case Evidence and Applied Institutional Analysis

4.1 Workforce Pressure Reaches the Bedside

Global nursing pressure is not abstract once it reaches a ward. It appears as slow recruitment, thin experience, heavier overtime, weaker continuity, and less time for education. WHO’s 2025 report places education, jobs, leadership, remuneration, regulation, and service delivery in one policy conversation (World Health Organization, 2025). Counting nurses alone will not solve nursing safety.

For a local manager, the global picture matters because it limits easy answers. A vacancy may not be a local failure. A facility may advertise for months in a labor market where qualified nurses have safer options, better pay, stronger support, or shorter travel elsewhere. Blame is easy. Workforce planning is harder.

Local leaders still make decisions. They decide whether risk is named accurately, whether temporary staff are oriented, whether new nurses receive protection, whether experienced staff are retained, and whether unsafe conditions reach senior governance in language strong enough to require an answer.

4.2 United States Workforce Signals

The 2024 National Nursing Workforce Survey offers signals that managers cannot treat as background. Age profile, employment movement, intent to leave, and work-environment concerns tell leaders how stable the supply of judgment may be over the next few years (Smiley et al., 2025). A manager looking only at today’s filled shifts may miss tomorrow’s loss.

Retention risk becomes more serious when experienced nurses leave the most pressured areas. Replacing them with new graduates or temporary staff may keep the schedule open, but the ward’s safety system changes. Less experience creates more supervision need. More supervision need means the charge nurse must have time to lead. Without that time, replacement creates a new risk.

Workforce data belong at service level, not at organization level alone. A hospital may report acceptable vacancy rates while one ward becomes unsafe. Aggregates smooth the picture. Patients receive care in the uneven parts.

4.3 Staffing Research and the Local Ward

Staffing-outcome research does not need exaggeration to be important. Aiken and colleagues, Lasater and colleagues, and Dall’Ora and colleagues contribute to a body of evidence linking nursing conditions with patient outcomes, burnout, and organizational strain (Aiken et al., 2023; Dall’Ora et al., 2022; Lasater et al., 2021). The lesson is not that one ratio explains every outcome. The lesson is that nursing time and skill are clinical resources.

A local ward turns that evidence into practical questions. How many patients require close observation? Which admissions arrive late? Which nurses know the specialty? Who can manage deterioration without waiting for permission? Which staff need supervision? Who is carrying discharge teaching? Which nurse is leading the shift rather than surviving it?

Managers who do not ask these questions may still meet a staffing template. Templates have value. They are not conscience. They cannot see the resident who needs two people to turn safely, the patient whose daughter needs time before discharge, or the new nurse too embarrassed to say she has never managed that infusion.

4.4 Long-Term Care and the Staffing Debate

Long-term care makes staffing arguments morally sharp. Residents often need help with the most intimate parts of living: toileting, eating, bathing, turning, walking, remembering, and feeling safe. When staffing is thin, harm can look slow and ordinary. A resident waits. A meal is rushed. Confusion is met with impatience because everyone is already behind.

CMS’s 2024 long-term care staffing rule set minimum staffing standards, including 3.48 total nurse staffing hours per resident day, with specified registered nurse and nurse aide components. The rule emphasized resident safety and quality concerns for Medicare and Medicaid certified facilities (Centers for Medicare & Medicaid Services, 2024). Later repeal action showed the conflict among resident protection, labor supply, regulation, and provider capacity (Department of Health and Human Services & Centers for Medicare & Medicaid Services, 2025).

That debate cannot be flattened into slogans. Minimum standards can protect residents from the lowest floor of neglect. A number still cannot replace acuity judgment, workforce development, financing, or rural reality. Serious nursing management holds both truths: residents need safe staffing, and providers need realistic conditions to supply it.

4.5 Teamwork Tools in Real Conditions

TeamSTEPPS 3.0 gives services a practical vocabulary for communication, leadership, situation monitoring, and mutual support (Agency for Healthcare Research and Quality, n.d.). In a well-led unit, that vocabulary can strengthen handover, escalation, and shared awareness. In a poorly supported unit, it can become another certificate pinned over unsafe conditions.

Communication tools work when leaders defend the space for communication. A call-out matters only if someone can answer. A huddle matters only if the team can step back long enough to think. A check-back matters only if staff are not punished for slowing down a dangerous instruction.

Applied analysis therefore treats teamwork training as dependent on staffing, senior cover, and culture. Nurses cannot communicate themselves out of impossible workload. They can use a common language more effectively when the organization respects the warning carried in that language.

4.6 Magnet and Professional Practice Environments

Magnet-related nursing excellence material draws attention to professional practice, leadership, empirical outcomes, and structural empowerment (American Nurses Credentialing Center, n.d.). These themes matter even outside formal designation. Strong nursing environments give nurses voice, development, governance, and credible access to leadership.

Excellence language must be handled carefully. A service can borrow the language of empowerment while leaving the ward manager without authority to change staffing or protect handover. Nurses know the difference between a culture that listens and a culture that has learned the phrases.

Professional practice environments are tested during pressure. Can a nurse challenge unsafe discharge pressure? Can a charge nurse close or slow activity when staffing is unsafe? Can missed care be reported without humiliation? Can a director take ward evidence to executives without softening it into polite concern? Those tests reveal the institution.

4.7 Applied Institutional Reading

Reading the evidence together gives a practical institutional picture. Workforce supply shapes what can be staffed. Local leadership shapes how scarcity is handled. Staffing research shows why nursing time matters. Teamwork tools show how communication may be strengthened. Long-term care policy shows why minimums, acuity, and capacity cannot be separated.

No single source supplies the full answer. The nurse manager has to read them together and then look at the ward. How many risks are being normalized? Which staff are quietly carrying the service? What work is always delayed? Which patients are becoming unsafe before anybody uses that word?

Institutional maturity appears when these questions are allowed to reach power. Immature organizations force nurses to absorb risk privately. Mature organizations convert warnings into staffing review, governance action, and honest communication with senior leadership.

4.8 The Board-Ward Gap

Applied institutional analysis must confront the distance between board assurance and ward reality. Senior reports compress risk into categories that look manageable. The ward experiences the same risk as a series of small decisions under pressure: who answers the bell, who watches the confused patient, who teaches the family, who helps the new nurse, who stays late to complete documentation.

The gap is not always bad faith. Executives may receive information already softened at several levels. Managers may fear sounding negative. Staff may stop reporting because nothing changed the last time. By the time risk reaches the board, it may have lost the details that made it urgent.

Nursing leadership has to protect those details. Board papers needs to include enough ward-level evidence to show what the numbers mean. A safe report does not need drama. It needs accuracy. If care is being maintained through unpaid time, repeated missed breaks, and hidden omission, the board need to know.

4.9 Reading Policy Without Losing the Patient

Policy debates about staffing become abstract quickly. Providers speak about cost and supply. Regulators speak about minimums and enforcement. Advocates speak about protection. Each position carries part of the truth. Nursing management has to bring the patient or resident back into the center of the argument.

For the resident waiting for continence care, the policy question is not ideological. It is whether someone comes in time. For the patient whose breathing changes after midnight, the issue is whether enough registered judgment is present to notice and act. Policy becomes real in those moments. Analysis that forgets them may be clever, but it is not nursing analysis.

Chapter 5: Discussion

5.1 Authority, Responsibility, and the Uneasy Middle

Fair discussion begins with limits. Nurse leaders do not control every force that shapes care. National labor supply, funding, reimbursement, training capacity, immigration rules, housing cost, and hospital demand can sit outside their authority. A manager may inherit vacancies created by decisions made years before she arrived.

Limits do not remove responsibility. Leaders still control how risk is named, how assignments are made, how handover is protected, how new staff are supervised, how missed care is recorded, and how staff concerns reach governance. A manager who cannot hire ten nurses today may still refuse to describe a dangerous shift as busy but safe.

The hard place for nurse leaders is the middle. They are close enough to see danger and sometimes too far from power to remove it. Good governance cannot leave them trapped there. Escalation needs a route, an answer, and a record.

5.2 The Moral Cost of Normalized Shortage

Shortage becomes most dangerous when it becomes normal. Staff stop reporting missed breaks because nobody answers. Delayed care becomes the rhythm of the unit. Families are managed rather than supported. New nurses learn that asking for help marks them as weak. Experienced nurses become quiet because speaking has not changed anything.

Moral strain grows from the gap between professional duty and organizational reality. Nurses know what good care requires. They also know when the service has not given them the time, staffing, or senior support to deliver it. Burnout literature gives language to part of that experience. Ward staff often say it more plainly: they are tired of failing patients in small ways.

Leadership cannot repair moral strain with gratitude alone. Thank-you messages have a place. They become insulting when used to cover unsafe conditions. Staff need rest, authority, staffing review, supervision, and evidence that senior leaders can hear difficult truth.

5.3 Why Missed Care Must Be Taken Seriously

Missed care is one of the most useful early warnings available to nurse leaders. It shows where the service is already rationing attention. The problem may not yet appear as a fall, infection, pressure injury, medication error, or complaint, but the system is giving notice.

Different omissions carry different meanings. Delayed hygiene may reflect aide shortage. Late observations may signal registered nurse overload. Short discharge teaching may point toward flow pressure. Missed supervision may show that a preceptorship arrangement exists on paper only. Each omission contains management information.

Punitive treatment destroys that information. Nurses will protect themselves by silence if honesty becomes a disciplinary risk. A safer service asks why care was missed and what must change so nurses are not placed in the same position again.

5.4 Staffing as Clinical Governance

Staffing belongs in clinical governance because it shapes surveillance, response, teaching, infection control, medication safety, and dignity. A board that reviews falls and pressure injuries without reviewing staffing conditions is reading only the last page of the story.

Governance also requires detail. Organization-wide averages may comfort executives while one unit is unsafe every weekend. Staffing evidence needs to include filled versus planned roster, temporary staff use, overtime, missed breaks, acuity pressure, escalation records, and turnover by service. Patient safety lives in the detail.

Data alone will not lead. Someone has to interpret it, challenge soft language, and bring staff experience into the room. Nursing directors and senior nurses have a duty to keep that interpretation from being diluted into generic operational pressure.

5.5 The Limits of Training

Training is often offered when a service is uneasy about structural problems. Communication training after a handover failure may be useful. It may also avoid the harder fact that handover was interrupted, rushed, and carried by people who did not know the patients.

TeamSTEPPS 3.0 and similar approaches work best when paired with local action. Huddles, call-outs, check-backs, and mutual support need time, authority, and psychological safety (Agency for Healthcare Research and Quality, n.d.). Without those conditions, staff attend training and return to the same broken system.

Before commissioning training, nurse leaders need to ask one direct question: what condition will change so the trained behavior can survive? Without a concrete answer, the training risks becoming evidence of activity rather than improvement.

5.6 Retention as a Safety Strategy

Retention is too often treated as a workforce cost. Nursing management need to treat it as a safety strategy. Experienced nurses hold local knowledge, informal coaching, pattern recognition, and practical authority. They know when a patient is not right before the numbers look dramatic. They know which process fails after 5 p.m.

A service that loses these nurses loses more than hours. It loses people who steady new staff, challenge unsafe shortcuts, and carry memory from one incident review to the next. Replacement may restore the staffing number while leaving the ward clinically thinner.

Retention review belongs beside quality review. Exit themes, sickness patterns, internal transfers, age profile, overtime, and staff narratives belong in the safety record. A unit that cannot keep experienced nurses is sending a warning.

5.7 What the Reliability Score Adds

The Nursing Care Reliability Score adds structure without replacing professional judgment. Its main value is forcing leaders to examine weak signals together. Staffing adequacy, acuity, skill mix, handover, supervision, missed care, retention, and strain are often reviewed separately. The score places them in one conversation.

False precision remains a risk. A score may appear more objective than it is. Local leaders must keep numbers open to challenge, attach narrative evidence, and avoid using the score to rank units without context. A ward caring for unstable patients cannot be shamed by crude comparison with a steadier service.

Used honestly, the tool can move leaders from vague concern to specific action. It can show whether a unit is surviving through goodwill, whether senior cover is being consumed by task work, or whether missed care has become ordinary. That is enough reason to use it carefully.

5.8 Discussion Summary

The discussion returns to a firm point. Nursing safety is not produced by goodwill after the roster has already failed. It is produced by arrangements that give nurses enough time, skill, authority, and support to notice and respond. Where those arrangements are weak, safety is already compromised before an incident proves it.

Nurse leaders need courage, but courage cannot be romanticized. It must be supported by governance, evidence, and authority. Without that support, the profession asks individual nurses to absorb system failure and calls the exhaustion dedication.

5.9 Accountability Without Scapegoating

Accountability is necessary. Nursing services sometimes confuse it with blame. A nurse who ignores a clear duty needs to be answerable. A nurse placed in an impossible assignment after repeated warnings is in a different position. Mature governance can tell the difference.

Scapegoating feels efficient because it supplies a named cause. The medication was late because a nurse was disorganized. The fall happened because observation was missed. The complaint arose because communication was poor. Sometimes those statements are partly true. They are incomplete if staffing, interruptions, skill mix, handover, and supervision are kept outside the frame.

A better accountability model asks what the individual did, what the team knew, what managers had been told, what senior leaders had authorized, and which conditions were tolerated before the event. That wider view does not excuse poor practice. It prevents organizations from pretending that poor practice appears from nowhere.

5.10 Language as a Safety Tool

Language matters because it shapes what leaders are willing to see. “Pressure” sounds temporary. “Unsafe staffing” requires a decision. “Resilience” flatters the workforce. “Exhaustion” asks why recovery is missing. “Opportunities for improvement” may suit an audit, but it can sound evasive after repeated missed care.

Nurse leaders need to choose words that match reality. Honest wording may create discomfort. Sometimes discomfort is the point. A service cannot correct risks it insists on describing gently. Professional language has to be calm, but calm does not mean diluted.

Chapter 6: Implementation Framework for Nursing Leaders

6.1 Begin with the Shift, Not the Slogan

Implementation has to begin with the shift. Many improvement projects fail because they open with language staff have heard too often: safer care, better teamwork, workforce resilience, excellence culture. Nurses judge those phrases by what happens on the next rota.

A manager can begin with the last four weeks. Which periods carried the highest acuity? Where did admissions cluster? Which shifts lost senior cover? Which care was missed? Which handovers were interrupted? Which staff stayed late? Which risks were escalated, and what answer came back? These questions reveal the operating truth faster than a campaign poster.

The review includes registered nurses, aides, charge nurses, educators, quality staff, and operational leaders. Each group sees a different part of the system. Bedside staff know which work is hidden. Quality teams know which harms are rising. Operational leaders know where demand pressure enters. Implementation fails when one group writes the plan for everyone else.

Table 4. Four-Week Nursing Reliability Review Cycle

Period Management action Expected output
Week 1 Collect baseline evidence on staffing, acuity, skill mix, missed care, turnover, and handover. A clear local risk picture without blaming individual staff.
Week 2 Hold a unit conversation with nurses, charge nurses, aides, and operational leaders. Shared interpretation of weak signals and immediate safety pressures.
Week 3 Agree practical controls on assignment, handover, escalation, preceptorship, and senior cover. Visible changes staff can recognize on the next rota cycle.
Week 4 Escalate unresolved risk to senior nursing and board governance with named follow-up. Documented accountability rather than informal acceptance of unsafe conditions.
Monthly Repeat the reliability review and compare new evidence with previous weak points. Pattern recognition rather than one-off reaction after harm.


6.2 Build a Local Staffing Review

A local staffing review compares planned roster, filled roster, patient acuity, skill mix, temporary staff use, missed breaks, overtime, and missed care. The purpose is not to embarrass a unit. The purpose is to stop treating repeated shortage as surprise.

Managers need a workable rhythm. Weekly review can catch immediate danger. Monthly review shows patterns. Quarterly review can support establishment arguments and retention planning. Annual review is too slow for a unit that is already fraying.

Evidence has to be shown plainly. A ward running below planned staffing every weekend cannot be described as facing intermittent pressure. A service that regularly loses senior cover because charge nurses take assignments need to say so. Language is part of implementation.

6.3 Protect the Charge Nurse Role

Charge nurses often carry the contradiction of modern nursing management. They are expected to coordinate the shift, support new staff, notice deterioration, manage relatives, escalate delays, solve equipment problems, and maintain morale. Then, when staffing is short, they are given a full assignment and expected to lead anyway.

Protecting the charge nurse role is not a luxury. It is a safety control. Someone must be free enough to see the whole ward, rebalance work, respond to uncertainty, and defend handover. A charge nurse buried in task work may be heroic, but the shift has lost its lookout.

Implementation defines when charge nurses can carry patients, when they cannot, and who authorizes exceptions. Repeated exceptions needs to reach senior review. A protected role suspended every week is not protected.

6.4 Make Acuity Visible

Acuity has to be discussed in ordinary language as well as formal tools. Numbers may help, but nurses also need permission to say that a patient requires constant reassurance, that a family needs time, that two confused patients near the nurses’ station are changing the whole shift, or that one discharge will absorb an experienced nurse.

Visible acuity prevents false equivalence. Ten beds do not equal ten beds when one group includes unstable oxygen requirements, isolation precautions, delirium, complex wounds, new insulin teaching, and discharge conflict. A staffing plan that ignores that difference is not neutral. It is unsafe.

Ward-level huddles can bring acuity into the open. The huddle cannot become performance. It needs to identify who is unstable, which tasks must not be missed, where supervision is needed, and what risk requires escalation beyond the ward.

6.5 Use the Reliability Score Carefully

The Nursing Care Reliability Score can support implementation when leaders treat it as a prompt. Each variable is scored with evidence: rosters, acuity notes, agency use, handover interruptions, missed care reports, turnover, sickness, overtime, and staff accounts.

Scores are reviewed with the team. Staff can challenge them. If managers score handover as reliable while nurses describe constant interruption, the disagreement is useful. It shows where the official view and working reality have separated.

Low scores require action, not anxiety. Some fixes may be immediate: protect handover, change assignment, add senior review, stop nonessential transfers during high-risk periods. Other fixes require executive escalation: recruitment, establishment review, retention incentives, or bed-capacity decisions. The score can help distinguish those levels.

6.6 Escalation That Receives an Answer

Escalation is not complete because a manager sent an email. Risk has not been handled until someone with authority responds. Too many nursing concerns disappear into polite acknowledgement. Staff then learn that escalation is ritual, not protection.

A reliable escalation route includes the risk, evidence, immediate control, decision required, person responsible, and review date. Senior leaders may not be able to supply staff instantly, but they can make decisions about admissions, redeployment, temporary cover, supervision, or documented acceptance of risk.

Silence after escalation is governance failure. If the ward has named an unsafe condition and no one answers, responsibility does not remain only with the ward. It travels upward with the ignored warning.

6.7 Support New Staff Without Sacrificing Patients

New nurses need work that teaches without overwhelming them. Services often say they value preceptorship while assigning preceptors full loads and placing new staff into unstable teams. That arrangement is unfair to the new nurse and unsafe for patients.

Implementation protects preceptor time, match new nurses to appropriate assignments, and monitor early warning signs: repeated staying late, avoidance of questions, medication anxiety, documentation delays, conflict with families, or reluctance to escalate. These signs are not personal weakness. They are development needs and safety signals.

Experienced nurses also need support. Teaching while carrying unsafe workload breeds resentment. A service that wants a learning culture must give experienced nurses time to teach properly.

6.8 Keep Governance Close to Care

Governance meetings include evidence from actual shifts. Dashboards are useful, but they can become distant. A fall rate may be stable while nurses report more missed turning. Complaint numbers may be low because families have stopped expecting attention. Governance needs quantitative data and ward testimony together.

Senior nursing leaders need to bring uncomfortable details to the board: where staffing is repeatedly below plan, where agency dependence is high, where missed care is rising, where charge nurses cannot lead, where experienced nurses are leaving. Polished summaries that remove discomfort also remove usefulness.

Implementation succeeds when the organization can see the work honestly. Safer care begins with that sight.

6.9 Practical Audit Questions

A practical audit can begin with questions staff recognize. Which shift last week felt least safe? What made it unsafe? Which patient group required more time than the roster allowed? Where did senior support arrive too late? Which task was repeatedly delayed? Which new staff member needed more help than was available?

Managers compare the answers with formal records. If staff describe repeated missed care but the incident system is quiet, reporting may be weak. If overtime is high but staffing reports look adequate, the roster may be hiding work. If charge nurses repeatedly carry assignments, leadership cover is being consumed.

Audit findings lead to named actions. A vague plan to monitor staffing is not enough. Better actions include protecting one charge nurse per shift, changing admission timing where possible, adding senior review to high-acuity periods, strengthening preceptor allocation, or escalating establishment review with evidence.

6.10 Sustaining the Work

Sustaining improvement is harder than launching it. Early attention can fade once the first report is written. Staff then learn another lesson in disappointment. Nursing reliability work needs a rhythm: review, action, feedback, adjustment, and renewed review.

Feedback to staff is crucial. Nurses who report missed care or staffing risk need to hear what happened next. Even when the answer is limited, visible response matters. Silence teaches cynicism. Response teaches that professional voice still has value.

6.11 Making Improvement Visible

Visible improvement does not require a ceremony. Staff notice when handover is actually protected, when a senior nurse arrives before the shift collapses, when agency nurses receive useful orientation, and when a difficult escalation receives a clear answer. Small corrections rebuild trust faster than broad promises.

Measurement needs to follow those corrections. Leaders can track whether interruptions fell, whether charge nurses remained available, whether missed care reduced, and whether staff felt safer naming risk. Improvement becomes credible when nurses can point to changes in the work, rather than only to changes in the report.

Chapter 7: Sector-Specific Application

7.1 Acute Care

Acute care tests nursing management through speed and complexity. Admissions arrive, discharges stall, patients deteriorate, scans interrupt routines, and families need answers. A safe roster in acute care is not built by headcount alone. It needs enough registered judgment, senior cover, and flexibility to absorb sudden change.

Medication safety shows the point. A medicine round may fail through poor knowledge, but also through interruption, overload, unfamiliar staff, unclear orders, or competing demands. Good management reduces those conditions. It protects the round, supports new staff, controls avoidable interruption, and ensures that a nurse who is unsure can stop and ask.

Acute units also need disciplined escalation. Bed pressure can push unsafe transfers, rushed discharge teaching, and thin observation. Nurse leaders need to document when flow pressure creates clinical risk. The record cannot be hostile. It has to be accurate enough to protect patients and staff.

7.2 Emergency and Urgent Care

Emergency nursing carries a different rhythm. Demand is unpredictable, acuity changes quickly, and patients may arrive without history, diagnosis, or trust. Triage, waiting-room surveillance, escalation, and rapid reassessment become central management concerns.

Staffing in urgent care settings must account for visible and hidden work. A patient sitting quietly may be deteriorating. A relative may be the only reliable historian. Mental-health distress, intoxication, safeguarding concerns, and violence risk all change the staffing requirement. A roster built only around average attendance misses the danger.

Team communication matters sharply here. Brief huddles, clear role allocation, and senior clinical presence can prevent drift. Still, communication tools cannot compensate for a waiting room that has outgrown the team’s capacity to observe it safely.

7.3 Long-Term Care

Long-term care tests whether a system respects dependency that is not dramatic. Residents need continence support, food, hydration, turning, conversation, memory care, mobility help, and protection from loneliness and neglect. Thin staffing turns these needs into a queue.

The federal staffing debate shows how hard the issue is. Minimum hours may create a needed floor, but resident acuity, workforce supply, rural access, and financing cannot be wished into place. Policy need to protect residents without pretending that providers can hire nurses who do not exist locally.

Facility assessment is crucial. Leaders show how resident need shapes staffing, not simply whether a rule was technically met. Dementia care, bariatric care, wound burden, end-of-life support, behavioral risk, and family involvement all affect the work. A resident does not become easier to care for because a spreadsheet lacks a column.

7.4 Community and Home-Based Nursing

Community nursing spreads risk across distance. A nurse may move from house to house carrying clinical judgment, safeguarding awareness, teaching responsibility, and documentation demands without immediate ward-team support. Management has to account for travel, lone-working risk, equipment, digital access, and the emotional weight of entering private homes.

Missed care looks different outside institutions. A visit is shortened. Teaching is deferred. A wound review is pushed to tomorrow. A caregiver’s exhaustion is noticed but not addressed because the schedule is already late. These omissions may not appear in the same metrics as hospital incidents, yet they shape safety.

Community leaders need strong escalation routes. Nurses working alone cannot be left to carry complex risk privately. Safeguarding, deterioration, medication uncertainty, family conflict, and environmental danger require fast access to senior advice.

7.5 Mental Health and Learning Disability Services

Mental health and learning disability nursing require enough time for observation, relationship, de-escalation, and communication that may not follow standard routines. Staffing adequacy must reflect emotional labor, behavioral risk, legal duties, family work, and skilled presence.

A ward may look calm while risk is rising. Withdrawal, agitation, self-neglect, medication refusal, family conflict, or a small change in routine can carry meaning. Nurses need time to notice and interpret those signals. Surveillance in this setting is often relational as well as physical.

Management protects reflective discussion and senior support. Staff working with distress, trauma, aggression, or complex communication need space to think. Treating reflection as a luxury misunderstands the work.

7.6 Maternal, Child, and Family Services

Maternal and child health services depend on trust, teaching, early recognition, and safeguarding. A rushed interaction can miss domestic violence, feeding difficulty, postnatal depression, medication uncertainty, or a parent who nods politely without understanding the plan.

Staffing has to allow nurses and midwives to speak with families properly. Education is not a leaflet handed over at the door. It requires checking understanding, reading fear, and adapting language. Families remember whether they felt seen when they were most vulnerable.

Managers need to watch for missed relational care in these services. It may not look like a medication error, but it can shape outcomes. A parent who leaves confused may return later with a preventable crisis.

7.7 Education, Preceptorship, and Academic Settings

Nursing education cannot be separated from service conditions. Learners may be taught best practice in the classroom and then meet a placement where staff are too rushed to demonstrate it. That gap damages confidence and can normalize unsafe shortcuts early in a career.

Preceptorship belongs as workforce protection. New nurses who are supported well become safer and are more likely to stay. Poor transition support wastes education investment and places pressure on already strained teams.

Academic and service leaders need to work together on realistic preparation: prioritization, escalation, documentation, delegation, family communication, and managing uncertainty. Clinical knowledge matters, but the early nurse also needs help surviving the organized reality of care.

7.8 Rural and Under-Resourced Settings

Rural and under-resourced settings expose the limits of generic staffing advice. Recruitment may be slow, agency cover scarce, travel long, and specialist support distant. A policy written for a large urban system may not fit without adaptation.

Adaptation cannot mean lower expectations for dignity or safety. It means honest workforce planning, regional cooperation, telehealth support where appropriate, retention incentives, stronger generalist preparation, and escalation routes that acknowledge distance.

Leaders in these settings often know risk well because they live close to it. Their evidence deserves attention. Rural difficulty must not become a polite excuse for invisible harm.

7.9 Application Across Settings

Every sector changes the form of nursing risk, but the management question remains recognizable. Does available skill match actual need? Is supervision real? Is handover protected? Are omissions named? Are staff leaving? Does escalation receive an answer?

Sector-specific application therefore strengthens the central argument. Nursing management is patient-safety work wherever nursing time, judgment, and voice determine whether people receive care in time and with dignity.

7.10 Transitions of Care

Transitions of care deserve separate attention because risk often crosses boundaries. Hospital to home, emergency department to ward, ward to rehabilitation, long-term care to hospital, and community service to specialist clinic all depend on nursing communication that is usually compressed by time.

Unsafe transition rarely looks dramatic at the point of handoff. A medication change is not understood. A wound plan is incomplete. A family is unsure who to call. A resident returns from hospital with new instructions that do not fit the staffing pattern of the home. Harm may appear days later, far from the moment when the weakness entered the system.

Managers need to treat transitions as shared nursing work. Receiving teams need enough information, sending teams need time to teach, and both sides need escalation routes when the plan is unclear. A discharge target met by sacrificing understanding is not a safety success.

7.11 Technology and Digital Documentation

Digital systems can support nursing management, but they can also hide workload. Electronic records, acuity tools, rostering platforms, and dashboards may make information easier to collect. They do not automatically make care safer.

Nurses often spend time feeding systems that senior leaders then use to judge performance. That exchange is fair only when the system returns value to the ward. If documentation expands but staffing does not, digital improvement may become another claim on nursing time.

Technology has to be judged by whether it helps nurses notice risk earlier, communicate more clearly, reduce duplication, and escalate danger. A beautiful dashboard that leaves the bedside thinner has failed the practical test.

Chapter 8: Closing Position and Recommendations

8.1 Closing Position

Nursing safety is built in ordinary decisions that rarely attract ceremony. The roster is checked. The experienced nurse is kept free to lead. A new nurse is supervised. Handover is not sacrificed to hurry. Missed care is named. A family receives explanation before discharge. A resident is turned before skin breaks. A concern reaches someone with authority and receives an answer.

Amadi’s central position is that nursing organizational management belongs at the center of patient safety. It is not administration around the clinical service. It is part of the clinical service. Patients receive the consequences of staffing, supervision, retention, communication, and leadership whether or not they ever see those words.

No serious health service can praise nurses for resilience while building work that depends on exhaustion. Resilience may help a professional endure a difficult season. It cannot become the operating model.

8.2 Recommendations for Nurse Managers

Nurse managers review staffing adequacy by shift and acuity, not by establishment alone. Every review need to ask whether the team had enough registered judgment, enough support staff, enough familiarity, and enough senior cover for the patients present.

Missed care belongs in the record as safety intelligence. A delayed bath may not appear urgent, yet repeated omissions reveal the service’s true capacity. Managers need a non-punitive way to hear what was left undone and why.

Handover and charge nurse availability deserve protected status. If an organization claims to value escalation while giving the charge nurse no time to lead, the claim is false. Leadership must exist in the shift, not just in the job description.

8.3 Recommendations for Senior Executives and Boards

Boards treat nursing staffing as clinical risk rather than labor cost alone. Reports needs to include staffing adequacy, acuity pressure, temporary staff use, missed care, turnover, preceptorship strain, sickness, overtime, and unresolved escalations.

Executives need to answer escalations visibly. A manager who reports unsafe conditions needs to receive a decision, not sympathy alone. When resources cannot be supplied immediately, temporary controls need to be agreed and documented. Governance fails when risk is passed downward until bedside staff carry it alone.

Retention belongs as a safety metric. Losing experienced nurses weakens judgment, memory, supervision, and culture. Exit data, sickness trends, internal transfers, age profile, and staff narratives need to be read together.

8.4 Recommendations for Education and Professional Development

Nursing education providers and service leaders align more closely around transition to practice. New nurses require strong clinical placement, realistic preparation for workload, protected preceptorship, and early support in escalation, prioritization, communication, and documentation.

Continuing development for nurse leaders includes staffing analysis, acuity interpretation, conflict management, quality governance, data use, workforce planning, and board-level communication. A nurse manager promoted for clinical excellence may still need support in organizational authority.

Team training has to be tied to local operating conditions. TeamSTEPPS 3.0 and similar programs are useful when leaders protect the behaviors they teach. Training without protected handover, usable escalation, and senior support produces attendance records rather than safer teams.

8.5 Recommendations for Policy and Regulation

Policy makers avoid two easy mistakes. One is writing staffing rules as if labor supply and provider capacity do not matter. The other is abandoning patient and resident protection because implementation is hard. Serious policy holds both truths.

Minimum standards can create a floor, but they cannot replace local acuity judgment. Regulation requires providers to show how staffing decisions reflect actual need. Documentation of staffing adequacy, missed care, turnover, and escalation can make risk harder to hide.

Rural and under-resourced providers need specific support: training pipelines, retention incentives, regional staffing cooperation, loan repayment, technology support, and targeted funding. Equity means patients outside major centers are not treated as acceptable casualties of scarcity.

8.6 Publication Standard for Practice Use

A publication on nursing management has little value if it cannot survive contact with practice. The argument offered here is meant for nurse managers, senior nurses, directors, educators, quality leads, and graduate learners who need language strong enough to defend care but practical enough to use.

Every recommendation returns to a professional demand: name the work honestly. Name the acuity. Name the missed care. Name the lack of senior cover. Name the retention loss. Name the handover risk. Name the difference between a difficult shift and an unsafe arrangement. Naming does not solve the problem by itself, but silence keeps the problem comfortable for people who are not carrying it.

NYCAR publication readiness requires more than clean formatting. It requires structure, evidence, restraint, and a voice that understands the work. A paper on safety cannot be disordered. A paper on nursing cannot sound detached from nurses. A paper using a model must not overclaim what the model can do.

8.7 Final Quality Position

The Nursing Care Reliability Score remains limited by design. It helps leaders organize review. It does not predict harm, replace local judgment, or certify a service as safe. That restraint strengthens the work. Overclaiming would weaken it.

Final judgment is difficult to avoid. Do not call nursing care safe until the conditions of nursing work have been examined honestly. Patients do not receive strategy documents. They receive the consequences of staffing, supervision, communication, and leadership.

Nothing in that demand is fashionable. It is ordinary, stubborn, and difficult to fake. A service either protects nurses’ capacity to care or consumes that capacity while praising their commitment. Patients deserve the first option. Nurses do as well.

8.8 What Must Not Be Lost

Several points cannot be lost in the final reading. Staffing is not just a finance matter. Acuity is not a technical detail. Skill mix is not a substitution game. Handover is not a courtesy. Missed care is not a private embarrassment. Retention is not simply human-resources work. Each belongs to patient safety.

Nursing leaders also need institutional protection. Asking managers to speak honestly while punishing discomfort is a recipe for silence. A director who wants safer care must make room for difficult evidence. A board that wants assurance must be willing to hear why assurance is not yet justified.

The profession resists management language that praises nurses while consuming them. Care cannot be built on permanent rescue. If nurses have to keep saving the system from its own arrangements, the arrangements are the problem.

8.9 Closing Reflection

Martha N. Amadi’s contribution rests in making a familiar truth difficult to avoid: nursing care depends on how nursing work is organized. The statement sounds simple. Many services still behave as though compassion can compensate for poor staffing, communication training can compensate for unprotected handover, or recruitment can compensate for a culture that drives experienced nurses away.

Better nursing management does not require theatrical leadership. It requires accurate rosters, honest acuity review, protected senior cover, supported new staff, reliable handover, open reporting of missed care, and executives who answer risk rather than admire endurance. These are ordinary disciplines. Their ordinariness is exactly why they matter.

Patient safety begins before the alarm sounds. It begins when leaders decide whether the conditions of nursing work are safe enough for the care they expect nurses to deliver. That decision is made every day, whether it is named or not.

Serious nursing management does not need decoration. It needs enough honesty to protect the next patient before the next incident writes the lesson more painfully. The test is not whether the report sounds confident; it is whether the next shift has enough time, skill, and authority to care safely.

References

Agency for Healthcare Research and Quality. (n.d.). TeamSTEPPS 3.0 curriculum materials. https://www.ahrq.gov/teamstepps-program/curriculum/index.html

Aiken, L. H., Sloane, D. M., McHugh, M. D., Pogue, C. A., & Lasater, K. B. (2023). A repeated cross-sectional study of nurses immediately before and during the COVID-19 pandemic: Implications for action. Nursing Outlook, 71(1), 101903. https://doi.org/10.1016/j.outlook.2022.11.007

American Nurses Credentialing Center. (n.d.). ANCC Magnet Model. American Nurses Association. https://www.nursingworld.org/organizational-programs/magnet/magnet-model/

Centers for Medicare & Medicaid Services. (2024). Medicare and Medicaid programs: Minimum staffing standards for long-term care facilities and Medicaid institutional payment transparency reporting. https://www.cms.gov/newsroom/fact-sheets/medicare-and-medicaid-programs-minimum-staffing-standards-long-term-care-facilities-and-medicaid-0

Dall’Ora, C., Ball, J., Reinius, M., & Griffiths, P. (2020). Burnout in nursing: A theoretical review. Human Resources for Health, 18, 41. https://doi.org/10.1186/s12960-020-00469-9

Dall’Ora, C., Saville, C., Rubbo, B., Turner, L., Jones, J., & Griffiths, P. (2022). Nurse staffing levels and patient outcomes: A systematic review of longitudinal studies. International Journal of Nursing Studies, 134, 104311. https://doi.org/10.1016/j.ijnurstu.2022.104311

Department of Health and Human Services & Centers for Medicare & Medicaid Services. (2025). Medicare and Medicaid programs: Repeal of minimum staffing standards for long-term care facilities. Federal Register, 90(230), 55687–55700. https://www.federalregister.gov/documents/2025/12/03/2025-21792/medicare-and-medicaid-programs-repeal-of-minimum-staffing-standards-for-long-term-care-facilities

Lasater, K. B., Aiken, L. H., Sloane, D. M., French, R., Anusiewicz, C. V., Martin, B., Alexander, M., & McHugh, M. D. (2021). Chronic hospital nurse understaffing meets COVID-19: An observational study. BMJ Quality & Safety, 30(8), 639–647. https://doi.org/10.1136/bmjqs-2020-011512

NHS England. (2023). NHS long term workforce plan. https://www.england.nhs.uk/publication/nhs-long-term-workforce-plan/

Smiley, R. A., Kaminski-Ozturk, N., Reid, M., Burwell, P. M., Oliveira, C. M., Shobo, Y., Allgeyer, R. L., Zhong, E., O’Hara, C., Volk, A., & Martin, B. (2025). The 2024 National Nursing Workforce Survey. Journal of Nursing Regulation, 16(1), S1–S88. https://doi.org/10.1016/S2155-8256(25)00047-X

World Health Organization. (2025). State of the world’s nursing 2025: Investing in education, jobs, leadership and service delivery. World Health Organization. https://www.who.int/publications/i/item/9789240110236

The Thinkers’ Review

Strategic Risk Management and Leadership for United Nations System Performance

Strategic Risk Management and Leadership for United Nations System Performance

Foresight, Results Discipline, and Resilience in Multilateral Operations


Research Publication by Blessing Chima-Chiemezie

New York Center for Advanced Research (NYCAR)

Institutional Review

June 2026

Publication Number: NYCAR-TTR-2026-RP051

DOI: https://doi.org/10.5281/zenodo.20582883

Peer Review Status:

This research paper has been reviewed under the internal editorial framework of the New York Center for Advanced Research (NYCAR) and The Thinkers’ Review. The review assessed doctoral-level coherence, source integrity, strategic-risk relevance, UN-facing policy value, regulatory precision, quantitative-model suitability, APA 7th alignment, and institutional relevance.


Abstract

Strategic risk management has become a central test of multilateral leadership because contemporary crises no longer arrive in sequence. Conflict, climate shock, food insecurity, forced displacement, debt distress, public health threats, cyber exposure, disinformation, and political fragmentation increasingly reinforce one another. In that environment, the United Nations system does not suffer from a shortage of strategies. It suffers, as many large public systems do, from the harder problem of execution under uncertainty: how to convert risk signals, foresight, evidence, partner knowledge, and ethical safeguards into timely choices before delay damages results.

This doctoral research examines strategic risk management as a leadership discipline for United Nations system performance and for organizations seeking credible alignment with UN priorities. It argues that risk cannot remain a compliance register owned by auditors, nor can foresight remain a reflective exercise detached from budget authority. Risk leadership belongs inside mandate interpretation, programme design, procurement, finance, safeguarding, digital governance, evaluation, public communication, and country-level decision-making. It draws on official and public materials from UN 2.0, the Pact for the Future, the Joint Inspection Unit’s enterprise risk management review, UNDP risk-informed development practice, WFP strategic and innovation materials, UNHCR results and evaluation materials, UNICEF strategic planning, WHO health emergency preparedness materials, and United Nations system management and resilience work. These sources are treated as management evidence with different evidentiary weights: policy statements show institutional intent, strategic plans show planned direction, management and results frameworks show implementation logic, and evaluations or oversight reports offer stronger evidence of organizational friction.

The research develops four applied diagnostic tools. The Strategic Risk Leadership Index tests whether mandate clarity, risk sensing, foresight use, decision rights, resource mobility, partner coordination, evidence learning, safeguards, stakeholder trust, and decision lag are aligned. The Risk-Adjusted Results Delivery model tests whether reported outputs remain credible after quality, equity, sustainability, residual risk, and potential harm are considered. The Decision-Lag Diagnostic examines the time lost between signal recognition and field response. The Partner Trust and Accountability Score treats partnership quality as a risk control rather than a diplomatic slogan. The research paper then applies these tools to case readings of WFP, UNHCR, UNDP, UNICEF, WHO, and system-wide reform agendas. Its core conclusion is direct: the United Nations system will not be judged by how often it names volatility, but by whether it can turn risk intelligence into decisions that protect people, preserve mandate integrity, explain trade-offs, and learn fast enough to matter.

Keywords: strategic risk management; United Nations; UN 2.0; foresight; enterprise risk management; risk-informed development; results-based management; humanitarian operations; resilience; data governance; accountability; NYCAR.

Contents

List of Tables

Table 1. Strategic risk domains and leadership control questions 24

Table 2. Strategic Risk Leadership Index components 29

Table 3. Case-study matrix 44

Table 4. Decision-lag stages and corrective actions 56

Table 5. Recommendations and evidence for oversight 79

List of Figures

Figure 1. Strategic Risk Leadership Index: component weights. 31

Figure 2. Partner Trust and Accountability Score: component weights. 35

Figure 3. Decision-Lag Diagnostic: illustrative elapsed time across the seven stages. 33

Chapter 1: Introduction: From Risk Awareness to Decision Accountability

Strategic management inside the United Nations system cannot be reduced to corporate planning with diplomatic vocabulary attached. The operating field is too exposed and too politically mediated. A UN country team may work where drought has already weakened livelihoods, conflict has broken public administration, debt pressure has narrowed fiscal space, misinformation has damaged trust, and humanitarian access depends on negotiations that can change overnight. A headquarters strategy can describe these pressures, but the field question is sharper: when the assumptions fail, who is authorized to change the plan?

The argument begins with a practical diagnosis. The United Nations system has no shortage of strategies, compacts, plans, frameworks, guidance notes, results matrices, risk registers, and reform agendas. The problem is not the absence of institutional language. The problem is the distance between language and action. A risk register can exist without moving money. A foresight paper can be admired without changing procurement timing. A results framework can report outputs while field staff still carry unresolved delivery risks. That distance – between awareness and decision – is where strategic risk management becomes a leadership problem.

Risk management is often placed in a procedural corner. It is associated with compliance, audit, internal control, fraud prevention, insurance, and reputational exposure. Those functions are essential, but they do not exhaust the meaning of risk in multilateral work. For the UN, risk is also about protection failure, exclusion, loss of humanitarian access, unsafe digital practice, weak partner support, field staff exposure, poor targeting, slow escalation, and the erosion of public trust. Risk is therefore not only something to be avoided. It is information about what can prevent a mandate from being delivered.

The central claim of this research is that strategic risk management should be treated as decision accountability under uncertainty. This definition is deliberate. “Strategic” means the risk concerns mandate delivery, legitimacy, institutional capacity, or the protection of people affected by action or inaction. “Management” means the organization has a route from signal to decision, from decision to resource movement, and from action to learning. “Accountability” means leaders can explain what they knew, when they knew it, what authority they used, what trade-offs they accepted, and what safeguards protected affected populations.

UN 2.0 gives this question current force. The Secretary-General’s UN 2.0 agenda emphasizes stronger capabilities in data, digital solutions, innovation, foresight, and behavioural science, underpinned by a forward-looking culture (United Nations, 2023). These capabilities are not ornamental. Data without judgment can mislead. Digital transformation without inclusion and cybersecurity can create new vulnerabilities. Innovation without adoption becomes a pilot culture. Foresight without budget authority becomes a seminar. Behavioural insight without ethics can cross into manipulation. The promise of UN 2.0 is real, but only if these capabilities enter the decision system.

The Pact for the Future broadens the same challenge. Adopted at the Summit of the Future in September 2024, it brings together sustainable development, peace and security, science and technology, digital cooperation, youth and future generations, and global governance reform (United Nations, 2024). The Pact is relevant to risk management because it converts the future from a rhetorical horizon into a governance responsibility. An institution that claims duties to future generations must ask whether current funding cycles, procurement rules, partner agreements, data practices, and programme incentives are building resilience or consuming it.

The research is UN-facing but not ceremonial. It assumes that the UN system contains serious professionals working under severe constraints. It also assumes that good intentions do not remove the need for sharper management discipline. Multilateral organizations are morally burdened because their mandates concern human lives, rights, peace, development, and global cooperation. They are administratively burdened because they must act through member-state politics, earmarked funding, procurement rules, security protocols, implementing partners, inter-agency coordination, and public scrutiny. Strategic risk management lives inside that mixture.

For NYCAR purposes, the research aims to serve three audiences. The first is the academic reader interested in risk governance, public administration, humanitarian operations, and institutional performance. The second is the UN-facing practitioner who needs usable tools rather than theory alone. The third is the institutional partner seeking credibility with UN priorities and therefore needing to demonstrate not only ambition, but safeguards, evidence discipline, financial control, partner responsibility, and learning capacity.

1.1 Background and Research Problem

The contemporary operating environment is best understood as compound risk. Food insecurity is not only a food problem when conflict disrupts supply routes, climate shock damages production, inflation raises prices, debt pressure reduces public spending, and misinformation undermines public confidence in assistance. Forced displacement is not only a protection problem when host communities face housing pressure, public services are overstretched, borders become politically contested, and digital registration systems raise privacy risks. Health emergencies are not only epidemiological problems when rumours spread faster than guidance, health workers are attacked, and fragile systems lose staff and supplies.

The United Nations was created for problems that exceed the capacity of any one state. Yet the present period stresses the management side of multilateralism in an unusual way. Crises overlap, political consensus is harder to maintain, funding is unstable, public trust is contested, and digital tools change both the possibilities and the risks of intervention. Mandate authority remains necessary, but it is no longer sufficient. The question is whether institutions can act with enough speed, discipline, and ethical clarity when the operating picture changes faster than formal planning cycles.

The research problem is the gap between strategic risk language and risk-informed execution. Many organizations can name risks. Fewer can demonstrate that risk analysis changes priorities, deadlines, staffing, security posture, partner oversight, budget allocation, procurement, data governance, or public communication. This problem is intensified in the UN system because authority is distributed. Headquarters, regional bureaus, country offices, donors, governing bodies, host governments, implementing partners, and affected communities all shape outcomes, but they do not sit in one clean chain of command.

Decision lag is the practical symptom of this gap. Risk signals often appear before action. Field teams may notice that access is deteriorating. Local partners may warn that community trust is weakening. Procurement officers may detect supply fragility. Protection teams may identify patterns before formal complaints increase. Data officers may see a cyber or privacy risk before programme managers understand its operational consequences. Delay can come from unclear escalation, donor restrictions, legal caution, procurement rules, insufficient flexible funding, or fear that bad news will be punished. Whatever the cause, delay has consequences. In high-risk settings, a late decision can look very much like a wrong decision.

A second symptom is results distortion. Results-based management is indispensable for accountability, but output reporting can flatter performance if it is detached from risk. A programme can meet numerical targets while failing marginalized groups. A digital tool can accelerate registration while excluding people without documents or connectivity. A resilience project can deliver training while local systems remain unable to absorb the next shock. Strategic risk management asks whether the result is not only delivered, but dependable, equitable, safe, and sustainable under stress.

A third symptom is hidden risk transfer. Localization, partnership, efficiency, and digital modernization can all be positive. They can also move risk downward if they are pursued without safeguards. A local partner may be asked to deliver in an insecure area without adequate overhead, insurance, duty-of-care support, data systems, or cash-flow reliability. A shared digital platform may reduce duplication while concentrating cybersecurity exposure. A cost-saving measure may reduce redundancy that later proves essential in crisis. This research treats those trade-offs as central rather than secondary.

1.2 Aim, Objectives, and Research Questions

The aim of the research is to develop a doctoral-level strategic risk management framework for United Nations system performance and for organizations that seek to work credibly with UN priorities. The research does not audit a single UN entity. It does not claim internal access. It uses public materials to construct a rigorous applied framework that can help leaders examine whether risk intelligence is changing decisions.

The study pursues five objectives. It defines strategic risk management as a leadership capability rather than a compliance file, then reads UN 2.0, the Pact for the Future, enterprise risk management sources, results-based management materials, evaluation evidence, and agency strategies as a combined management record. On that base it develops diagnostic tools that work without pretending that complex human systems reduce to one definitive score. Those tools are applied to case evidence from WFP, UNHCR, UNDP, UNICEF, WHO, and wider UN reform work, and the analysis is translated into recommendations for UN entities, country teams, donors, governing bodies, and UN-aligned partners.

The central research question is: how can strategic risk management improve United Nations system performance when crises are compound, authority is distributed, and results are politically and ethically consequential? Five subsidiary questions follow. How should risk leadership differ from ordinary enterprise risk management? Which capabilities allow foresight and risk sensing to alter budgets, decision rights, and partner arrangements? How can results-based management be strengthened by risk adjustment? What do selected UN cases reveal about execution under pressure? Which diagnostic tools can support management learning without creating false precision?

The stance taken here is reform-minded but disciplined. It rejects two weak positions: romantic multilateralism, which praises cooperation while ignoring institutional constraints, and cynical reductionism, which treats the UN only as bureaucracy. A serious analysis must hold both truths. The UN system carries urgent mandates and also operates through budgets, committees, procurement, staff safety systems, data platforms, reporting cycles, country teams, donors, and accountability mechanisms. The credibility of strategy depends on what happens inside those mechanisms.

1.3 Significance of the Study

The subject matters because the legitimacy of multilateral action is increasingly tied to delivery under stress. Member states and communities do not only ask whether a mandate is noble. They ask whether the institution can deliver when funds fall short, access closes, data fail, political conditions shift, or public trust weakens. Humanitarian need continues to rise while resources are strained. Development gains are repeatedly threatened by climate shocks, conflict, debt, and public health emergencies. Digital tools create new possibilities, but also new forms of exclusion, bias, surveillance risk, and institutional dependency.

For UN managers, the paper offers a way to test whether risk management is changing choices or merely producing documents. For donors and governing bodies, it offers a more exact oversight vocabulary than simply asking for more reporting. For UN-facing partners, it clarifies what credible alignment requires: governance readiness, safeguards, data responsibility, financial discipline, partner support, evaluation follow-up, and the courage to report difficulty before failure becomes public. For academic readers, it links risk governance, public management, humanitarian operations, strategic foresight, resilience, evaluation, and technology governance in one applied frame.

The central practical value of the study is its insistence on answerability. A strategically risk-informed institution should be able to say what risk was seen, who saw it, who had authority to respond, what changed, what resource moved, what safeguard was activated, which affected population was consulted, what result survived, and what was learned. That level of answerability is not an administrative luxury. In multilateral operations, it is part of mandate integrity.

Chapter 2: Evidence Base and Literature Review

The literature and policy base for the research is deliberately institutional and applied. The research is not building an abstract theory of risk detached from operational reality. It is examining how public organizations with complex mandates can convert uncertainty into better judgment. The evidence base therefore includes UN reform materials, enterprise risk management work, agency strategic plans, evaluation materials, results frameworks, business continuity and resilience sources, and selected public management concepts. The sources are read with caution. They are not treated as identical forms of evidence.

A policy brief or strategic plan shows what an institution intends to value. A results framework shows how it proposes to measure progress. A management plan shows how resources and functions are organized. An evaluation or oversight report often shows where the system actually struggles. A public case example may illustrate practice, but it rarely captures the internal decision sequence. This hierarchy matters. Doctoral work cannot simply place citations beside claims. It must examine what the citation can legitimately prove.

2.1 Strategic Risk Management in Multilateral Institutions

Enterprise risk management has matured across the UN system, and that is a meaningful development. The Joint Inspection Unit’s 2020 review of enterprise risk management in United Nations system organizations proposed updated benchmarks and emphasized integrated ERM as a basis for more proactive, better-informed decision-making, governance, oversight, and accountability (Joint Inspection Unit, 2020). This is a useful foundation, but it also reveals the key limitation. ERM can support strategy only when it is connected to planning, budgeting, programme review, partner management, and leadership forums.

Strategic risk management differs from ordinary operational control because it asks whether the organization can still deliver its mandate when major assumptions fail. A procurement delay, cybersecurity weakness, funding cut, access restriction, or partner capacity gap becomes strategic when it affects mandate delivery, protection, public trust, or institutional legitimacy. The same event may be routine in one context and strategic in another. A late shipment in a stable operation may be inconvenient; in a famine-risk operation it can become life-threatening.

Multilateral institutions also face a moral difference from many private organizations. A company may define risk through financial exposure, compliance exposure, market position, and reputation. A UN entity must also account for risks to people affected by action or inaction. Protection failure, exclusion, unsafe data collection, exploitation and abuse, inability to reach remote populations, and erosion of trust are not peripheral risks. They are part of the mandate environment. Risk appetite in such settings cannot be only technical. It must ask who bears the consequence if the risk materializes.

This is why risk leadership must be located above the register. A register records recognized risks; it does not prove that judgment changed. The stronger question is whether risk information enters the meeting where authority, money, staffing, and trade-offs are decided. In the UN context, that may mean country programme boards, humanitarian country teams, inter-agency coordination structures, senior management groups, donor consultations, procurement committees, data governance boards, or safeguarding review mechanisms. Risk that does not enter those forums remains administratively visible but strategically weak.

2.2 UN 2.0 and the Capability Shift

UN 2.0 is one of the most important contemporary sources for the research because it defines a capability agenda for a more demanding operating environment. The agenda emphasizes data, digital solutions, innovation, foresight, and behavioural science as a “quintet of change” intended to help the UN system become more agile, evidence-informed, and future-ready (United Nations, 2023). These capabilities have direct implications for risk management.

Data can improve early warning, targeting, monitoring, fraud detection, and resource allocation. But poor data can also create a false sense of precision. Digital tools can expand reach and reduce duplication. They can also exclude people without connectivity, increase cybersecurity exposure, or concentrate sensitive information. Innovation can improve delivery if it solves real field problems and scales responsibly. It can also produce pilot fatigue if incentives reward novelty more than adoption. Foresight can help leaders prepare for plausible futures, but only if it affects budget and decision rights. Behavioural science can improve programme design and public communication, but it requires ethical boundaries, especially where vulnerable populations are involved.

The promise of UN 2.0 is that reform is framed as capability rather than slogans. The risk is that capability language becomes another vocabulary layer. A UN entity may speak about foresight while budgeting remains too rigid to act on scenarios. It may speak about digital transformation while training, interoperability, accessibility, and privacy controls lag behind. It may celebrate innovation without building pathways for procurement, governance, scale, and evaluation. The research therefore treats UN 2.0 as both opportunity and test. The test is whether its capabilities alter decisions under pressure.

Strategic risk management can serve as the bridge. Risk sensing needs data. Risk anticipation needs foresight. Risk treatment needs innovation. Risk communication needs behavioural insight. Risk governance needs digital discipline. But each capability must be tied to authority and safeguards. Otherwise the organization becomes more informed without becoming more decisive, and more digitally ambitious without becoming more trusted.

2.3 The Pact for the Future and Duties to Tomorrow

The Pact for the Future, adopted by world leaders at the Summit of the Future on 22 September 2024, together with the Global Digital Compact and the Declaration on Future Generations, places reform of international cooperation in a broader political frame (United Nations, 2024). It is relevant here because it lengthens the accountability horizon. Institutions are not only being asked to deliver current outputs. They are being asked to consider how today’s decisions affect future generations, digital governance, peace, security, development, and global public goods.

Future orientation changes risk analysis. A choice that looks efficient in the short term may weaken resilience over time. Underfunding preparedness, neglecting climate adaptation, failing to protect education during crises, allowing debt distress to reduce social spending, or deploying digital systems without rights safeguards can defer harm rather than prevent it. Strategic risk management must therefore ask what harms are being postponed because current incentives make prevention politically invisible.

The Global Digital Compact also sharpens the technology dimension. Digital cooperation promises inclusion, data use, innovation, and AI governance, but the same tools can create exclusion, surveillance, dependency, and power asymmetry. A UN-facing risk framework must therefore require purpose limitation, privacy, cybersecurity, human oversight, bias review, grievance routes, and transparency before digital systems become operationally central. Technology risk cannot be handled after scale. It must be designed into the programme from the beginning.

A future generations lens also forces budget honesty. It is easy to speak for tomorrow while spending only for today. A serious future-oriented institution must identify which investments strengthen resilience across multiple futures: data quality, public health preparedness, climate adaptation, child protection systems, flexible finance, partner capacity, and institutional learning. Strategic risk management provides a method for translating future language into present controls.

2.4 Risk-Informed Development and the Humanitarian-Development-Peace Nexus

Risk-informed development is central to the argument because development gains can be erased by shocks if programmes are designed for stable assumptions. UNDP’s risk-informed development strategy tool emphasizes the integration of disaster risk reduction and climate change adaptation into development planning and investments, while also addressing policy silos and multidimensional risk (UNDP, 2021). That premise is especially important in countries where climate exposure, fragile governance, economic pressure, and social inequality interact.

The humanitarian-development-peace nexus is often discussed as coordination language, but it is also a risk-management problem. Humanitarian action may save lives immediately while development investment reduces future need. Peacebuilding may affect access, trust, and institutional resilience. Poorly coordinated interventions can create parallel systems, duplicate assessments, overload local partners, or weaken national ownership. A strategic risk lens asks which action reduces immediate harm, which strengthens systems, and which accidentally creates dependency or unmanaged exposure.

UNICEF’s strategic planning across successive cycles illustrates the same point from the perspective of children (UNICEF, 2021). Its 2026-2029 Strategic Plan describes a final drive toward child-related Sustainable Development Goals by 2030, with sharpened focus, differentiated strategies, agility, resources, partnerships, and a commitment to leaving no child behind (UNICEF, 2025). For children, risk is cumulative. A disruption in education, nutrition, health, protection, or social assistance can produce effects that last decades. Equity is therefore not a decorative factor in results. It determines whether the mandate is reaching those most likely to be harmed.

WFP’s strategic planning and corporate results work similarly links operational focus, programme quality, results measurement, and management enablers (WFP, 2022). Its 2026-2029 corporate results framework is explicitly designed to translate the strategic plan into implementation and measurement architecture (WFP, 2025a). The lesson is that risk management must enter the results architecture. It is not enough to know what will be delivered. Leaders must know what can prevent delivery, which groups may be missed, what quality standards must hold, and which residual risks remain after implementation.

2.5 Results-Based Management, Evaluation, and Learning

Results-based management is necessary for accountability, but it can become misleading if treated as mechanical reporting. The Joint Inspection Unit has described results-based management as a high-impact model for managing toward results across the UN system (Joint Inspection Unit, 2017). In principle, RBM links planning, implementation, monitoring, reporting, and learning. In practice, indicators can become separated from context. This is particularly dangerous in humanitarian, protection, and governance work, where numerical outputs may not capture whether people are safer, rights are protected, or institutions are more resilient.

UNHCR’s results work illustrates both the importance and the limits of consolidation. Public materials describe the use of core indicators to support global presentation of results across operations (UNHCR, 2025). That is necessary for a global organization. Yet protection outcomes depend on legal access, confidentiality, documentation, safe referral pathways, community trust, and political conditions. A core output indicator may be necessary, but it is not sufficient. Strategic risk management asks what the indicator does not show.

Evaluation is the corrective discipline. UNHCR’s evaluation strategy for 2024-2027 emphasizes evaluation as part of an organizational results-based management culture and practice, with credible evaluations used to demonstrate results and value for money (UNHCR, 2024). This is the right direction, but the managerial test is follow-up. An evaluation that identifies problems but does not alter budget, staffing, partner design, or leadership review becomes a form of institutional memory without institutional movement. For that reason, this research treats evaluation recommendations as risk signals that require owners, deadlines, and evidence of action.

Learning must also occur before the post-crisis review. Traditional evaluation cycles are often too slow for volatile contexts. Monitoring, community feedback, partner reporting, safeguarding data, and operational signals should provide live learning. The point is not to abandon formal evaluation. The point is to prevent evaluation from being the first moment at which the organization admits what field staff already knew.

2.6 Organizational Resilience, Efficiency, and Business Continuity

The United Nations Organizational Resilience Management System is relevant because strategic risk management is not only about external programmes. The institution itself must continue critical functions during disruption. CEB materials describe organizational resilience as a cross-functional endeavour involving crisis management, security, business continuity, ICT disaster recovery, medical emergency response, crisis communication, and support to staff, survivors, and families (United Nations System Chief Executives Board for Coordination, 2021). This is not a back-office issue. It is mandate protection.

Resilience should not mean asking staff and partners to absorb impossible pressure. An organization can appear resilient while transferring risk to local staff, underfunded partners, or affected communities. True resilience requires preparedness, clear authority, redundancy where necessary, trained crisis teams, duty-of-care arrangements, surge capacity, and business continuity plans that are tested rather than filed. If local partners carry delivery in insecure areas without adequate support, the system has not localized resilience; it has displaced risk.

Efficiency is equally complex. HLCM’s management reform work focuses on financial management, procurement, human resources, digitalization and technology, and safety and security, with recent efficiency initiatives addressing resource pressure and system-wide savings (United Nations System Chief Executives Board for Coordination, 2025). Efficiency can strengthen delivery when it reduces duplication, procurement friction, unnecessary reporting, or slow business processes. It can weaken resilience when it cuts protective capacity, removes redundancy, reduces oversight, or underfunds learning. The central question is not whether efficiency is good, but where savings come from and who carries the risk afterward.

Funding volatility cuts across all of this. Organizations facing unpredictable resources may delay commitments, reduce field presence, cut monitoring, stretch partner agreements, or prioritize activities that are easier to fund rather than those most strategically necessary. A risk-informed strategy must therefore treat finance as a delivery risk, not merely a resource variable. It should identify which commitments fail first under funding contraction, which populations lose support, which safeguards become exposed, and what contingency decisions are available.

2.7 Literature Gap

The reviewed materials provide strong components: UN 2.0 offers a capability agenda; the Pact for the Future offers political and temporal urgency; JIU enterprise risk management work offers system benchmarks; UNDP and UNICEF materials support risk-informed programming; WFP and UNHCR materials show results and operational dilemmas; WHO materials show the pressure of preparedness; CEB and ORMS materials show resilience and management reform. The gap is integration at the leadership level.

Leaders need a practical way to connect risk sensing, foresight, decision rights, resource mobility, safeguards, partner coordination, evidence learning, and results reporting. Many frameworks identify principles. Fewer show how a manager might diagnose delay, compare readiness across units, adjust results for risk, or test whether partnerships are carrying hidden exposure. This research addresses that gap through diagnostic models designed for management deliberation rather than statistical display.

Table 1. Strategic risk domains and leadership control questions

Risk domain Leadership question Primary control evidence
Conflict and access risk Can operations adapt when security, access, or political conditions change? Scenario review, access protocols, partner contingency, security escalation
Climate and disaster risk Are programmes designed for foreseeable environmental stress? Climate risk screening, early warning, adaptation finance, continuity planning
Funding volatility Which commitments fail first if resources contract? Prioritization rules, flexible funding, donor dialogue, contingency budgets
Protection and safeguarding Who is exposed to harm if controls fail? Complaint pathways, survivor-centered response, partner training, incident follow-up
Data, digital, and AI risk Can tools be explained, secured, challenged, and shut down if unsafe? Data governance, privacy controls, cybersecurity, human oversight
Partner capacity risk Are partners resourced to carry the responsibility assigned to them? Payment timing, overhead, role clarity, dispute resolution, localization support
Trust and legitimacy risk Can affected people and stakeholders see accountability? Community feedback, public communication, evidence disclosure, grievance routes


Chapter 3: Methodology and Diagnostic Model Design

The research uses an integrative documentary method. It analyzes public UN and UN-related materials, agency strategies, results frameworks, evaluation materials, oversight sources, and management reform documents, then translates them into diagnostic tools for strategic risk leadership. The method is appropriate because the object of analysis is not one programme in one country. It is the management problem that appears across multilateral operations: how to make risk information consequential.

The research does not claim statistical generalization. It does not use confidential interviews, internal dashboards, non-public risk registers, or proprietary UN data. That limitation is not hidden. It is central to the research design. Public institutional documents are not enough to prove implementation, but they are enough to analyze formal intent, stated governance expectations, management logic, and visible areas of operational concern. The value of the paper lies in disciplined synthesis and diagnostic design.

The research design follows four steps. It identifies the authoritative documents that shape the UN system’s current reform and risk environment, then classifies the evidentiary status of each source. From those sources it derives variables that recur across strategic risk, results, foresight, safeguards, partnership, and resilience materials, and converts those variables into models that leadership teams can use for structured review.

3.1 Source Selection and Evidence Handling

Documents were selected according to authority, relevance, recency, and operational usefulness. Official UN and agency sources are prioritized because the research is UN-facing. UN 2.0 and the Pact for the Future are used to establish current reform direction. JIU reports are used because they carry system-wide oversight value. Agency strategic plans and results frameworks are used to understand mandate translation and performance logic. Evaluation materials are used because they reveal learning expectations and organizational friction. CEB and ORMS materials are used to connect risk to business continuity and system management.

Evidence is handled conservatively. A strategic plan is not proof that implementation occurred. A public report is not proof that internal decisions were effective. An evaluation finding is not proof that all similar contexts share the same weakness. The analysis therefore avoids sweeping claims about the entire UN system unless supported by system-wide sources. Where the analysis makes an inference, it states the inference as such.

This is especially important for doctoral research because the temptation in institutional writing is to let official language do too much work. The existence of a policy does not prove risk maturity. The existence of a dashboard does not prove data quality. The existence of a partnership framework does not prove partner trust. The existence of an evaluation strategy does not prove learning. Each document is a clue to management design; it is not automatically evidence of management performance.

3.2 Model Design Principles

The diagnostic models are designed around five principles. They must be transparent, so a UN-facing manager can see the variables and debate them without needing a hidden algorithm. They must be adaptable, because a humanitarian logistics operation, a protection agency, a development programme, and a health emergency function will not weight every risk in the same way. They must be evidence-demanding, with scores supported by documents, field signals, partner feedback, incident data, decision records, and evaluation findings. They must be ethically alert, since a high delivery score cannot compensate for serious harm to affected populations. And they must expose delay, because risk intelligence has little value if the organization cannot act on it in time.

The models are therefore not presented as validated instruments. They are structured tools for leadership review. Their purpose is to improve questions, reveal assumptions, organize evidence, and make trade-offs visible. They should not be used to rank agencies publicly or punish units operating in severe contexts. A low score may indicate weak management; it may also indicate that a team is honest about extreme conditions. A high score may indicate maturity; it may also indicate optimism, weak evidence, or internal groupthink. The diagnostic conversation matters as much as the number.

3.3 Strategic Risk Leadership Index

The Strategic Risk Leadership Index, abbreviated SRLI, evaluates whether the organization has the leadership conditions needed to manage strategic risk. The proposed formula is:

SRLI = 0.14·MC + 0.13·RS + 0.12·FU + 0.12·DR + 0.11·RM + 0.10·PC + 0.10·EL + 0.10·SG + 0.08·ST − 0.10·DL

In the formula, MC is mandate clarity, RS is risk sensing, FU is foresight use, DR is decision rights, RM is resource mobility, PC is partner coordination, EL is evidence learning, SG is safeguards, ST is stakeholder trust, and DL is decision lag. Each component can be scored from zero to one hundred using evidence. The positive weights sum to 1.00, so the index behaves as a weighted average on a 0-100 scale before the decision-lag penalty is applied. The negative term for decision lag matters because an organization can possess strong policies, strong data, and strong language and still lose strategic value if action is too slow.

Mandate clarity asks whether broad mandates have been translated into priorities that can guide trade-offs. Risk sensing asks whether weak signals move from field teams, partners, affected communities, digital systems, security staff, procurement, and finance into leadership review. Foresight use asks whether scenarios affect decisions rather than remaining reflective exercises. Decision rights ask whether authority is clear and proportionate. Resource mobility asks whether money, people, supplies, or technical support can move when risk changes. Partner coordination asks whether roles are realistic and supported. Evidence learning asks whether monitoring and evaluation alter practice. Safeguards ask whether protection, rights, integrity, and data controls are active. Stakeholder trust asks whether affected people and partners can see accountability. Decision lag measures how long the system takes to respond.

A leadership team should not score the SRLI alone. The model should be used with cross-functional participation. A senior manager may believe decision rights are clear while field staff experience them as vague. A risk officer may view safeguards as strong while local partners experience them as underfunded. A data team may believe a platform is reliable while protection staff see privacy concerns. Differences in scoring are valuable because they reveal institutional blind spots. Figure 1 summarizes the relative weight the index assigns to each component.

Table 2. Strategic Risk Leadership Index components

Component Symbol Weight Leadership meaning Evidence to request
Mandate clarity MC .14 Mandate is translated into priorities and trade-off rules. Strategic plan, country priorities, decision memos
Risk sensing RS .13 Early signals reach leadership from field, partners, communities, and systems. Early warning, partner feedback, incident logs, monitoring data
Foresight use FU .12 Scenario thinking affects budget, staffing, procurement, and advocacy. Scenario notes, budget triggers, contingency decisions
Decision rights DR .12 Authority is clear, proportionate, and close enough to evidence. Delegations of authority, escalation routes, approval timelines
Resource mobility RM .11 Funds, people, supplies, or support can move as risk changes. Flexible finance, surge rosters, budget revision records
Partner coordination PC .10 Partners have roles, resources, safeguards, and realistic obligations. Agreements, payment timing, role maps, partner assessments
Evidence learning EL .10 Monitoring and evaluation change practice. Management responses, implementation trackers, learning notes
Safeguards SG .10 Protection, rights, integrity, and data controls are active. Complaint data, safeguarding pathways, data protection review
Stakeholder trust ST .08 Affected people and partners can see accountability. Feedback systems, public claims evidence, survey results
Decision lag DL -.10 Delay reduces risk leadership when signals do not become action. Elapsed days from signal to response


Figure 1. Strategic Risk Leadership Index: component weights.

3.4 Risk-Adjusted Results Delivery

The Risk-Adjusted Results Delivery model, abbreviated RARD, tests whether reported results remain credible once quality, equity, sustainability, residual risk, and harm are considered. The formula is:

RARD = (Results Delivered × Quality Factor × Equity Factor × Sustainability Factor) − Residual Risk Exposure − Harm Penalty

The model protects against false success. A programme may deliver a high number of outputs while excluding the hardest-to-reach populations, weakening local systems, or leaving serious protection concerns unresolved. Another programme may deliver fewer outputs but achieve higher strategic value because it reaches high-risk groups, strengthens national capacity, and reduces future exposure. The RARD model therefore invites leaders to examine not only how much was done, but what kind of result was produced.

The Quality Factor asks whether the result met required standards. The Equity Factor asks whether marginalized populations were reached. The Sustainability Factor asks whether the result can persist or whether it depends entirely on temporary external capacity. Residual Risk Exposure captures significant risks left unresolved after delivery. The Harm Penalty captures safeguarding failures, rights violations, data misuse, exclusion, or serious unintended consequences. In UN contexts, harm cannot be treated as a minor adjustment. Severe harm may invalidate otherwise impressive delivery numbers.

The model is useful for donor and governing body dialogue because it makes reporting more honest without making it cynical. It allows organizations to say: here is what we delivered, here is what held, here is who was missed, here is what remains fragile, here is the safeguard we activated, and here is what we will change. That form of reporting is more credible than polished success claims that hide unresolved exposure.

3.5 Decision-Lag Diagnostic

The Decision-Lag Diagnostic, abbreviated DLD, measures the time between risk signal and meaningful action. It is expressed as:

DLD = Signal Recognition Time + Risk Analysis Time + Approval Time + Resource Release Time + Partner Alignment Time + Field Start Time + Feedback Review Time

The score can be measured in days or weeks depending on the process. The diagnostic does not assume that speed is always good. Some decisions require careful review, especially where protection, legal exposure, security, fiduciary risk, or rights concerns are serious. The question is which delays are necessary and which are avoidable. A mature system should know the difference.

A long signal-recognition period suggests weak field intelligence or poor listening to partners and communities. A long analysis period may indicate fragmented data or unclear risk methodology. A long approval period may suggest excessive centralization or political sensitivity. A long resource-release period points to budget rigidity. A long partner-alignment period may reveal weak role clarity or unrealistic partnership design. A long field-start period may indicate procurement, staffing, security, or logistics barriers. A long feedback-review period suggests that learning is not institutionalized.

The DLD is especially important because delay is often invisible in final reporting. A report may say that assistance was delivered, but not that the risk was known weeks earlier. It may say a policy changed, but not that field staff had warned of the problem months before. By making time visible, the diagnostic turns delay into a management object. Figure 3 illustrates how a single decision can accumulate lag across the seven stages.
Figure 3. Decision-Lag Diagnostic: illustrative elapsed time across the seven stages.

3.6 Partner Trust and Accountability Score

The Partner Trust and Accountability Score, abbreviated PTAS, responds to a central multilateral reality: the UN system delivers through partnerships. Trust is not sentiment. In complex programmes, it is an operating condition. If roles are unclear, funding arrives late, reporting demands are disproportionate, safeguarding expectations are unfunded, data-sharing rules are ambiguous, or dispute routes are weak, the partnership becomes fragile.

The proposed formula is:

PTAS = 0.18·Transparency + 0.16·Role Clarity + 0.14·Safeguards + 0.13·Funding Reliability + 0.12·Data Sharing + 0.10·Feedback Loop + 0.09·Local Ownership + 0.08·Dispute Resolution

The eight positive weights again sum to 1.00, so the score reads on the same 0-100 scale as the other indices. It can be used by UN entities, donors, and partner organizations before scale. A partnership with weak role clarity, late payments, unclear data rights, and no credible dispute route should not be expected to carry high-risk delivery without redesign. Localization should strengthen local agency. It should not move risk downward while authority remains upward.

PTAS is also useful because it forces discussion of power. Large institutions may describe partnership positively while imposing terms that smaller organizations cannot absorb. Local partners may accept unrealistic obligations because funding options are limited. A risk-informed partnership asks who bears security risk, cash-flow risk, safeguarding risk, data risk, and reputational risk. If the answer is hidden, the partnership is not yet accountable. Figure 2 shows the relative weight of each PTAS component.
Figure 2. Partner Trust and Accountability Score: component weights.

3.7 Scenario Stress Test

The Scenario Stress Test asks a leadership team to examine whether a programme or strategy can survive plausible disruption. The team selects a programme and tests it against four shocks: funding contraction, access deterioration, data failure, and legitimacy shock. For each shock, the team asks what stops, what continues, who decides, which partners absorb burden, which affected groups are harmed first, what safeguard activates, and how the organization communicates.

The stress test is deliberately simple. It does not require advanced simulation to be useful. Its value lies in exposing fragile assumptions before the crisis exposes them. A programme that cannot identify what would continue after a moderate funding cut is not financially resilient. A programme with no safe alternative if access deteriorates is not operationally resilient. A programme dependent on one data platform is not digitally resilient. A programme with no credible response to public distrust is not legitimacy-resilient.

Stress testing also creates a practical bridge between foresight and management. Foresight often fails because it remains at the level of broad scenarios. Stress testing asks what those scenarios mean for budget, authority, partners, data, safeguards, and communication. It forces strategy to confront operating conditions.

Chapter 4: United Nations Case Readings

The case readings are not presented as audits. They are public-source management readings of selected UN entities and system-wide agendas. Each case is chosen because it exposes a different strategic risk dilemma. WFP illustrates hunger, supply chains, funding pressure, prioritization, and innovation discipline. UNHCR illustrates displacement, protection, global results, and evaluation follow-up. UNDP illustrates risk-informed development, national systems, and governance. UNICEF illustrates child-focused systems, equity, and intergenerational risk. WHO illustrates health emergency preparedness, trust, and financing volatility. UN 2.0 and the Pact for the Future illustrate system-wide reform.

The purpose is not to rank agencies. Different mandates require different capabilities. The purpose is to identify transferable leadership lessons.

4.1 WFP: Emergency Scale, Prioritization, and the Funding Cliff

WFP’s strategic risk environment is concrete and unforgiving. If supply routes fail, if funding drops, if access is blocked, if targeting data are weak, or if partners are overwhelmed, people may not eat. The risk profile therefore combines operational logistics, humanitarian access, donor volatility, nutrition, cash assistance, supply chains, local markets, protection, and public trust. WFP’s planning for 2026-2029 and corporate results work emphasizes strategic outcomes, cross-cutting priorities, enablers, and metrics that link corporate performance to programme delivery (WFP, 2025c). The key lesson is that results architecture and risk architecture must be integrated.

The first leadership dilemma is prioritization. When need exceeds resources, an organization cannot protect every commitment equally. The strategic question becomes: which capability must be defended because it carries the organization’s comparative advantage? For WFP, emergency food assistance, logistics, supply-chain capacity, vulnerability analysis, nutrition support, and field reach are not ordinary functions. They are core mandate assets. Risk management should help preserve them under stress.

The second dilemma is targeting and trust. Food assistance decisions can become politically and socially sensitive because inclusion and exclusion have immediate consequences. If vulnerability data are incomplete, if community feedback is weak, or if prioritization criteria are not understood, trust can deteriorate. Risk-adjusted results are essential here. Reporting the number of people reached matters, but it does not answer whether the right people were reached, whether rations were adequate, whether exclusions were justified, or whether community trust survived.

The third dilemma is innovation. WFP’s innovation strategy describes innovation in terms of impact at scale, field capacity, collaboration, and sustainable funding (WFP, 2025b). That is the right test. Humanitarian innovation should not be judged by novelty. It should be judged by whether it improves speed, targeting, safety, cost, accountability, or resilience without creating new harms. A digital targeting tool that increases efficiency but cannot be explained to communities may create legitimacy risk. A financing mechanism that accelerates assistance but shifts cash-flow exposure to local partners may weaken delivery. Innovation must therefore be governed as a risk-sensitive operating capability.

4.2 UNHCR: Protection, Displacement, and Results Integrity

UNHCR operates where strategic risk is inseparable from legal and human protection. Forced displacement intersects with conflict, statelessness, asylum systems, border politics, shelter, education, livelihoods, host-community pressure, climate stress, gender-based violence, documentation, and data confidentiality. The agency’s results materials emphasize global indicators and the presentation of results across operations (UNHCR, 2025). That global consolidation is necessary, but protection work cannot be reduced to output counts.

The first leadership dilemma is the relationship between numbers and protection meaning. Registering people, delivering assistance, supporting education, or providing shelter can be counted. Whether people are safer, whether legal pathways are credible, whether confidentiality is protected, whether community feedback is trusted, and whether durable solutions are realistic require deeper interpretation. Strategic risk management therefore requires protection risk analysis alongside quantitative results.

The second dilemma is evaluation follow-up. UNHCR’s evaluation strategy emphasizes the integration of evaluation into results-based management culture and practice (UNHCR, 2024). That aspiration is important because displacement operations often occur amid staff rotation, donor pressure, and urgent need. Institutional learning can easily be lost. A strategic risk system should treat evaluation recommendations as management signals with owners, resources, deadlines, and follow-up evidence. Without that chain, evaluation becomes a record of insight rather than a driver of change.

The third dilemma is data responsibility. Displacement data can be highly sensitive. Digital systems may improve registration and service delivery, but they also raise privacy, consent, protection, and cybersecurity concerns. In refugee and statelessness contexts, data misuse can create severe harm. Risk leadership must therefore insist on governance before scale: purpose limitation, data minimization, protection analysis, human oversight, grievance routes, and clear rules for sharing.

4.3 UNDP: Risk-Informed Development and National Systems

UNDP’s case illustrates the problem of risk that hides in time. A development programme may look successful during implementation and fail later when climate shock, fiscal distress, governance weakness, conflict, or institutional turnover returns. Risk-informed development asks whether the investment will still protect people when conditions change. UNDP’s risk-informed development materials emphasize integration of disaster and climate risks into development planning and investments, overcoming policy silos, and recognizing multidimensional risk (UNDP, 2021). That approach is central to resilient development.

The first leadership dilemma is systems strengthening versus project delivery. Development agencies are under pressure to show deliverables, but lasting value often comes from strengthening national systems: public finance, social protection, local governance, climate planning, data capacity, rule-of-law institutions, and service delivery. These results are harder to attribute and slower to show. Risk-adjusted reporting should therefore value institutional resilience, not only project outputs.

The second dilemma is national ownership under constraint. National ownership is essential, but institutions vary in capacity, legitimacy, and resources. A programme can be nationally aligned and still be fragile if public administration cannot maintain it, if recurrent financing is absent, or if political turnover changes priorities. Strategic risk management should ask whether the programme depends on temporary external capacity, whether domestic financing is plausible, and whether local actors can maintain the result.

The third dilemma is cross-sector risk. Climate adaptation, governance, digital public infrastructure, social protection, energy transition, and poverty reduction do not sit in separate risk lanes. They interact. A digital identity system may improve social protection targeting and raise data protection risks. Climate finance may build resilience or reinforce elite capture. Governance reform may improve service delivery or create political backlash. UNDP’s strategic value lies partly in helping countries see these interactions before programmes harden into silos.

4.4 UNICEF: Equity, Child Systems, and Intergenerational Risk

UNICEF’s mandate makes intergenerational risk concrete. Children experience institutional failure through lost learning, malnutrition, preventable disease, violence, displacement, unsafe water, mental health harm, and exclusion from social protection. The UNICEF Strategic Plan 2026-2029 is framed as the organization’s final drive toward child-related SDGs before 2030, with emphasis on focus, agility, resources, partnerships, and children’s rights (UNICEF, 2025). The strategic risk question is whether systems can protect children when crises overlap.

The first leadership dilemma is equity. A programme may reach large numbers while missing children with disabilities, girls in insecure regions, refugee and migrant children, children outside school systems, or children in communities beyond government reach. For UNICEF, equity is not a moral appendix to results; it is the condition that gives results mandate value. The RARD model therefore gives equity a central place.

The second dilemma is systems versus emergency delivery. Humanitarian action for children often requires immediate service provision. Longer-term child outcomes require resilient health, education, nutrition, WASH, protection, and social protection systems. If emergency delivery bypasses national and local systems without a transition plan, it may save lives now while weakening future resilience. If system strengthening moves too slowly during crisis, children suffer immediate harm. Strategic risk leadership lies in balancing the two without pretending that one can replace the other.

The third dilemma is voice and accountability. Children and young people are not merely beneficiaries. They are rights holders. A child-sensitive risk framework should ask whether programmes hear children safely, whether complaint pathways are accessible, whether data collection protects them, and whether decisions account for long-term consequences. Future generations language becomes real only when today’s systems are accountable to children now.

4.5 WHO: Preparedness, Health Emergencies, and Trust

WHO’s emergency role shows why preparedness is a strategic risk discipline. Health emergencies are system shocks. They affect economies, education, trust, mobility, public finance, and political stability. WHO’s 2025 health emergency materials describe an unprecedented convergence of health threats driven by conflict, climate change, food insecurity, antimicrobial resistance, and outbreaks, while emphasizing the need to protect lives from health emergencies (WHO, 2025a), and its emergency appeal sets out the financing required to meet that need (WHO, 2025b). The strategic risk problem is that preparedness is often underfunded until an emergency becomes visible.

The first leadership dilemma is prevention versus response. Emergency response attracts urgency because harm is visible. Preparedness competes for attention because success often means a crisis did not occur or did not escalate. Strategic risk management must make preparedness visible in results terms: surveillance capacity, trained personnel, supply readiness, legal frameworks, laboratory systems, risk communication, community engagement, and financing mechanisms.

The second dilemma is trust. Public health guidance can be technically accurate and still fail if communities distrust authorities or misinformation spreads faster than reliable communication. UN 2.0’s behavioural science capability matters here, but only with ethical discipline. Risk communication is not public relations. It is part of the intervention. It must listen, adapt, disclose uncertainty, and work through trusted local actors.

The third dilemma is financing. WHO’s emergency appeals and programme reports repeatedly show the pressure created by insufficient flexible funding. When emergency functions rely heavily on voluntary and earmarked resources, preparedness and core capacity are exposed. Strategic risk leadership should therefore treat flexible financing as a health security control, not a mere administrative preference.

4.6 UN 2.0 and the Pact for the Future as System-Wide Cases

UN 2.0 and the Pact for the Future can be read as system-wide cases because they are not agency strategies. They are attempts to shift the capacity and legitimacy of multilateral cooperation. UN 2.0 asks whether the UN system can become stronger in data, digital tools, innovation, foresight, and behavioural science. The Pact asks whether global cooperation can become more inclusive, effective, future-oriented, and able to address digital governance and intergenerational responsibility.

The strategic risk is breadth. When everything matters, priority can dissolve. A system-wide reform agenda succeeds only when translated into operational decisions. What does UN 2.0 mean for a country office’s next planning cycle? What does the Pact mean for a budget decision? Which digital compact commitments affect beneficiary data systems? Which future generations commitments affect climate adaptation, education, health preparedness, and procurement? Which foresight outputs trigger resource movement?

The diagnostic tools in this research offer one translation mechanism. They do not solve the politics of multilateral reform, but they help prevent broad agendas from floating above management reality. They ask whether capability becomes authority, whether foresight becomes budget, whether digital ambition becomes governance, whether partnership becomes shared accountability, and whether results survive risk-adjusted scrutiny.

Table 3. Case-study matrix

Case Strategic risk dilemma Leadership lesson
WFP Hunger risk, supply chains, targeting, funding contraction, innovation discipline Protect comparative advantage while making prioritization and targeting accountable.
UNHCR Displacement, protection, legal status, confidentiality, global indicators Attach results to protection meaning, data responsibility, and evaluation follow-up.
UNDP Development investments exposed to climate, fiscal, governance, and institutional risk Risk-proof development by strengthening national systems and testing sustainability.
UNICEF Child outcomes shaped by equity, systems, emergencies, and intergenerational harm Treat equity and long-term opportunity as central results conditions.
WHO Preparedness underfunded until crisis; trust and misinformation shape response Make preparedness, risk communication, and flexible financing visible as controls.
UN 2.0 / Pact Broad reform agendas risk weak translation into field decisions Tie capability and future commitments to budget, authority, safeguards, and learning.


Chapter 5: Strategic Risk Leadership Analysis

Across the evidence and cases, a consistent pattern appears. Strategic risk management succeeds when leaders can turn weak signals into timely, defensible choices without losing safeguards, trust, or results discipline. It fails when risk is documented but not acted upon, when foresight is not connected to budget, when results are reported without risk context, when efficiency hides risk transfer, or when digital ambition outruns governance.

This chapter moves from case description to leadership analysis. It identifies the core leadership practices that separate risk-aware organizations from risk-informed organizations.

5.1 Risk Is a Leadership Signal Before It Is a Register Entry

Risk registers have value, but they can create a false sense of control. A register proves that a risk has been named. It does not prove that the organization changed course. In complex institutions, a risk can be recorded, reported, and archived while the programme continues as if nothing changed. Strategic risk leadership begins when risk information reaches a forum where choices can be made.

Field offices often see risk first. Local partners may detect community dissatisfaction before surveys do. Protection staff may observe patterns before complaints rise. Procurement officers may notice supplier fragility before programme delays appear. Security staff may recognize access deterioration before programme teams revise targets. Data officers may see privacy and cybersecurity exposure before senior managers understand the delivery implications. A mature organization treats these signals as assets rather than disruptions.

The cultural issue is decisive. If bad news is punished, delayed, or softened, the organization will be late. If risk escalation is treated as disloyalty, field intelligence will become less honest. If senior leaders prefer polished dashboards to difficult narratives, the risk system will produce comfort rather than truth. Strategic risk management therefore requires psychological and institutional safety for escalation. People must be able to say, “the assumption is failing,” without fearing that the warning itself will be treated as failure.

Risk sensing also requires diversity of sources. A dashboard may show trends, but it may miss informal exclusion, fear, stigma, or community anger. A partner report may show delivery, but not the strain under which delivery occurred. A complaint mechanism may show few complaints because people trust the programme, or because they do not believe complaining is safe. Risk leadership asks what the data cannot see.

5.2 Foresight Must Affect Budget and Authority

Foresight is attractive because it signals sophistication. Its real test is whether it changes resource decisions. A scenario exercise that identifies likely climate stress, conflict spillover, funding contraction, or digital exposure but leaves budgets unchanged has not improved strategic readiness. It has improved institutional vocabulary.

For UN-facing organizations, foresight should trigger practical options: contingency budgets, pre-positioned supplies, surge rosters, partner framework agreements, data backup arrangements, risk communication plans, or donor discussions about adaptive funding. A scenario without a resource option is a conversation. A foresight function without access to decision forums will remain advisory at best and decorative at worst.

The Pact for the Future intensifies this point. Future generations cannot be protected by declarations alone. A future-oriented institution must ask whether current spending and management choices are creating resilience that future communities will inherit. Preparedness, climate adaptation, education continuity, child protection systems, health surveillance, cybersecurity, and local partner capacity are not secondary investments. They are the infrastructure of future risk reduction.

Foresight also requires humility. It is not prediction. It is disciplined rehearsal. Its strongest value is identifying choices that remain sensible across several plausible futures. Stronger data quality, clearer escalation routes, flexible finance, partner support, safeguarding capacity, and institutional learning are useful across many scenarios. These are resilience investments, even when they are politically less visible than crisis response.

5.3 Decision Rights Determine Whether Intelligence Becomes Action

Risk intelligence is wasted when no one knows who can act. Large systems often generate delay through structural ambiguity. A country office may understand the risk but lack budget authority. A regional bureau may agree but need headquarters approval. A donor may hold the key flexibility. A partner may know the local reality but lack authority to change the workplan. The result is not ignorance; it is immobilized knowledge.

Decision rights must be proportionate. Not every decision belongs at headquarters. Reversible operational decisions should often sit close to the evidence. Irreversible decisions, high protection risks, major financial exposure, significant reputational risk, or politically sensitive choices require higher review. A mature risk system does not centralize everything in the name of control. It defines control through clarity, proportionality, and escalation discipline.

Decision rights must also be visible before crisis. A team should know who can suspend a data tool, approve a budget reallocation, change targeting criteria, escalate a safeguarding concern, activate a security protocol, or revise a partner agreement. If authority is discovered during the crisis, delay has already entered the system.

The Decision-Lag Diagnostic helps by breaking delay into parts. Some delay protects quality. Some protects habit. Some protects nobody. Measuring the stages allows leaders to distinguish careful review from bureaucratic drift. The goal is not speed at any cost. The goal is timely judgment with safeguards intact.

5.4 Risk Appetite Must Be Ethical

Risk appetite is difficult in UN work because the organization is rarely taking risk only on its own behalf. It may be taking risk on behalf of affected populations, staff, local partners, donors, host governments, and future communities. A humanitarian organization may accept security risk to reach people in need, but it cannot casually move that risk to local staff without duty-of-care support. A development agency may pilot a digital tool, but it cannot treat vulnerable communities as test subjects without consent, safeguards, and accountability.

A technical risk appetite statement may classify tolerances as high, medium, or low. That is useful, but incomplete. Ethical risk appetite asks who bears the consequence if the risk materializes. It asks whether affected people were consulted. It asks whether partners have the resources to comply with standards. It asks whether urgency is being used to excuse weak controls. It asks whether a decision would remain defensible if the trade-off became public.

This ethical dimension distinguishes UN-facing risk leadership from many corporate settings. The goal is not simply to protect institutional assets. It is to protect mandate integrity, people, rights, staff, partners, public trust, and the credibility of international cooperation. Sometimes the ethical choice is to accept operational risk because inaction would be worse. Sometimes the ethical choice is to refuse scale because safeguards are not ready. The discipline is to make the trade-off explicit rather than hiding it behind neutral language.

5.5 Results Must Be Read With Risk Attached

Results without risk context can flatter institutions. A programme may deliver a large number of outputs while leaving serious vulnerabilities unresolved. A cash programme may reach households while increasing protection risks for women in a particular context. A digital registration process may improve speed while excluding people without identity documents. A training programme may report attendance while systems remain unable to sustain practice. Risk-adjusted interpretation prevents success claims from becoming detached from reality.

The pressure to report scale is understandable. Donors, governing bodies, and the public often ask how many people were reached. That question matters, but it is not enough. Leaders also need to know who was not reached, whether the result met standards, whether the outcome can survive, whether local systems were strengthened, and whether harm occurred. The RARD model exists to make those questions normal.

Risk-adjusted results are also fairer to field teams. Delivering an output in a remote, insecure, climate-affected area with weak infrastructure and distrust is not the same as delivering the same output in a stable capital. A system that treats both outputs as equal may unintentionally reward easy delivery and punish difficult mandate work. Strategic risk management should make the difficult result visible.

This does not mean turning every report into a catalogue of problems. It means making reporting more credible. A mature report can say: these results were achieved; this is the quality evidence; these groups were reached and missed; this risk was reduced; this residual exposure remains; these safeguards worked; these harms or complaints were addressed; this is how the next cycle will change. Such reporting builds trust because it admits complexity without surrendering accountability.

5.6 Partner Coordination Is a Risk Control

Partnership is often described as a value. It is also a control. No UN agency delivers alone. Governments, local civil society, international NGOs, private suppliers, community groups, donors, and other UN entities all shape outcomes. When partnership design is weak, risk multiplies: unclear roles, duplicate reporting, payment delay, safeguarding gaps, data confusion, procurement disputes, community mixed messages, and accountability gaps.

Local partners are often closest to risk. They may know which families are excluded, which community leaders are trusted, which routes are unsafe, which grievance channels are feared, and which programme assumptions are unrealistic. But proximity to risk does not mean capacity to absorb risk. If local partners are underfunded, undertrained, paid late, or overloaded with reporting, the system is using their courage as a substitute for management.

The PTAS model therefore treats partnership quality as a strategic issue. Transparency, role clarity, safeguards, funding reliability, data-sharing rules, feedback loops, local ownership, and dispute resolution determine whether a partnership can carry pressure. A partner that cannot challenge unrealistic timelines will not be able to prevent failure. A partner that lacks overhead cannot build the systems required for accountability. A partner that is expected to carry security risk without support is being used, not localized.

Strategic risk leadership should map risk allocation across the partnership. Who carries fiduciary risk? Who carries staff safety risk? Who carries safeguarding risk? Who carries data risk? Who carries public blame if delivery fails? If authority and risk are separated too sharply, partnership becomes unstable.

5.7 Data, Digital, and AI Require Governance Before Scale

The UN system’s data and digital capabilities are expanding, and the potential value is substantial. Better data can improve early warning, targeting, supply planning, fraud detection, programme adaptation, translation, and monitoring. Digital platforms can reduce duplication and expand reach. AI can support pattern recognition, triage, analysis, and communication. Yet each benefit carries risk. The most dangerous digital systems are not always the ones that fail completely. They are the ones that work well enough to be trusted while carrying bias, exclusion, privacy exposure, or false certainty.

A UN-facing digital risk discipline should include purpose definition, data minimization, consent or lawful basis, privacy review, cybersecurity, bias assessment, interoperability, accessibility, human oversight, model monitoring, grievance routes, and shutdown conditions. These questions must be asked before scale, not after. A system that cannot be explained to staff or affected communities is not ready for sensitive deployment.

AI raises additional concerns. Models can reproduce bias, obscure accountability, produce plausible errors, or shift decision-making away from human judgment. In humanitarian and rights-sensitive settings, AI should support decisions, not silently replace them. Human oversight must be meaningful, which means humans need the authority, training, and time to challenge system outputs. A nominal human-in-the-loop is not enough if the human cannot realistically override the system.

Digital governance also has a trust dimension. Affected populations may experience data collection as extraction or surveillance if purpose, use, sharing, retention, and grievance routes are unclear. The Global Digital Compact’s human-centered and rights-oriented language must be translated into operational controls. Strategic risk management is where that translation should happen.

5.8 Efficiency Must Not Become Hidden Risk Transfer

Efficiency matters. Resources are limited and needs are high. The UN system has a duty to reduce duplication, improve procurement, share services where sensible, simplify processes, and direct more resources toward mandate delivery. But efficiency has to be tested for risk transfer.

A cut that removes waste strengthens the system. A cut that removes redundancy may weaken crisis readiness. A shared service may reduce cost and increase consistency, or it may create dependency and a single point of failure. A streamlined approval process may reduce delay, or it may weaken safeguards if poorly designed. A reduction in monitoring cost may look efficient until a safeguarding failure or fraud risk emerges. The question is not whether efficiency is desirable. It is what kind of capacity is being removed.

This is particularly important under funding pressure. Prevention, training, evaluation, partner support, cybersecurity, knowledge management, and duty-of-care arrangements often look easier to cut than frontline delivery. Yet these functions protect the credibility and safety of frontline delivery. Strategic risk leadership should distinguish administrative burden from protective capacity. The first should be reduced. The second should be preserved.

Efficiency should therefore be risk-adjusted. Before major savings are adopted, leaders should ask: what risk does this create, who will absorb it, what control replaces the removed capacity, how will we know if the saving damages delivery, and what trigger would reverse the change? This is not resistance to reform. It is disciplined reform.

Chapter 6: Applied Diagnostic Tools

The models in this chapter are designed for use, not decoration. Their value lies in helping leadership teams ask better questions and record clearer decisions. A UN audience will rightly distrust tools that hide assumptions. The formulas here are intentionally simple. They can be adapted, weighted differently, or expanded as evidence improves.

The strongest use of the tools is not a one-time score. It is repeated review. A country team might use SRLI quarterly, DLD for selected decision processes, RARD during results reporting, PTAS before scaling partnerships, and scenario stress tests before major programme expansion. Over time, the tools create a management memory: which risks were known, what changed, what did not change, and why.

6.1 Using the Strategic Risk Leadership Index

SRLI should be conducted in a structured session with cross-functional participation. The group should include programme leadership, operations, finance, procurement, risk, monitoring and evaluation, safeguarding, data protection, security, and partner representation where appropriate. Each variable should be scored with evidence. Where evidence is weak, the score should be marked as uncertain rather than inflated.

The most valuable moment is disagreement. If headquarters scores resource mobility high and a field office scores it low, the difference reveals a practical issue. If a local partner scores role clarity low while the UN entity scores it high, the partnership design needs review. If safeguarding staff score controls lower than programme managers do, the organization should listen carefully. The index should make these differences visible.

A recommended scoring protocol has four steps: collect evidence before the session, score each variable individually, compare the scores and discuss the gaps, and record two or three decisions. The process should not end with a chart. It should end with action: clarify authority, adjust funding, strengthen partner support, revise data controls, or escalate a risk to a senior forum.

6.2 Interpreting Risk-Adjusted Results

The RARD model should be applied when a programme claims success under risk. It does not require a complex mathematical system at the beginning. A light version can use qualitative ratings: strong, adequate, weak, or critical. The point is to attach results to interpretation.

For example, a programme may report that it reached 100,000 people with assistance. RARD asks: was the assistance delivered to standard? Were marginalized groups reached? Can the result persist? What residual risks remain? Was there any harm, exclusion, complaint pattern, or safeguarding concern? If quality is low, equity is weak, sustainability is fragile, and residual risk is high, the headline number must be interpreted differently.

RARD also helps donors. Donors often demand evidence of scale and value for money. Risk-adjusted reporting shows value more honestly. It can explain why reaching fewer people in a high-risk area may be more strategically important than reaching more people in an easier area. It can also show why a programme should slow scale until safeguards or data controls are adequate.

6.3 Using the Decision-Lag Diagnostic

DLD should be applied to selected high-risk processes: emergency response, procurement under crisis conditions, safeguarding escalation, data incident response, partner agreement approval, funding reallocation, and access negotiation. The team should map the most recent case and record elapsed time across each stage. Then it should ask which delay was necessary and which was avoidable.

The corrective action must fit the delay. If signal recognition is slow, strengthen field intelligence and partner feedback. If analysis is slow, improve data integration and risk methodology. If approval is slow, clarify authority. If resource release is slow, negotiate flexible funding or contingency budgets. If partner alignment is slow, use pre-agreed roles or framework agreements. If feedback review is slow, create a management response tracker.

The diagnostic is also useful for governing bodies because it shifts oversight from general concern to concrete process. Instead of asking why the organization was slow, oversight can ask where the decision cycle slowed and what control will change.

6.4 Using the Partner Trust and Accountability Score

PTAS should be used before partnerships are scaled and during periodic partner review. It should be completed by both the UN entity and the partner. Differences in scores are important. A UN office may believe funding reliability is acceptable because disbursements comply with internal timelines; a local partner may experience the same timing as operationally damaging because it must pay staff or suppliers before reimbursement. Both perspectives are evidence.

The score should also be linked to risk allocation. A partnership that assigns high delivery risk to a local actor should provide corresponding support: overhead, security arrangements, training, data systems, safeguarding capacity, insurance or equivalent risk cover, and dispute routes. If the support is absent, the risk allocation is not credible.

PTAS can prevent localization from becoming rhetoric. A locally led response is not achieved by placing more obligations on local organizations. It is achieved by sharing authority, resources, information, and accountability in ways that make local leadership sustainable.

6.5 Scenario Stress-Test Scoring

A simple scenario score may be calculated as:

Scenario Stress Score = (Exposure × Probability × Consequence × Recovery Time) − Preparedness Capacity

Exposure measures the scale of the affected programme or population. Probability estimates how plausible the shock is within the planning period. Consequence measures harm to people, mandate delivery, finance, safety, trust, and legal obligations. Recovery time estimates how long it would take to restore minimum function. Preparedness capacity subtracts the strength of existing controls, contingency arrangements, flexible funding, trained staff, partner agreements, and communication plans.

The score should not create false precision. Its purpose is to force explicit discussion of assumptions. If a programme depends on one donor, one access route, one data platform, one implementing partner, or one political approval chain, the stress test will reveal fragility. Leadership can then redesign before scale locks in the weakness.

Table 4. Decision-lag stages and corrective actions

Stage Diagnostic question Common cause of delay Corrective action
Signal recognition How quickly did the organization notice the risk? Weak field intelligence or partner feedback Strengthen early warning, community feedback, and partner escalation
Risk analysis How quickly was the signal interpreted? Fragmented data or unclear method Create rapid risk notes and integrated data review
Approval Who had authority to act? Overcentralization or unclear delegation Clarify decision rights and escalation thresholds
Resource release How quickly did funds, staff, or supplies move? Rigid budget or donor restrictions Build flexible funding, contingency lines, donor pre-approval
Partner alignment Were partners ready to adjust? Unclear roles or contract rigidity Use framework agreements and role maps
Field start When did action begin? Procurement, staffing, security, or logistics barriers Pre-position supplies, rosters, and security protocols
Feedback review Did the system learn from the response? No owner for management response Track actions, deadlines, and evidence of completion


Chapter 7: Implementation Blueprint for UN-Aligned Organizations

An organization seeking to work credibly with the United Nations should not approach UN alignment as a branding exercise. It should be able to demonstrate that its governance, safeguards, data practices, financial controls, partner relationships, and learning systems are strong enough for complex mandate work. The UN system is increasingly attentive to risk-informed programming, responsible digital cooperation, results credibility, localization, and resilience. A partner that cannot document its own controls becomes a risk multiplier, no matter how attractive its proposal appears.

This chapter translates the diagnostic framework into a practical blueprint for UN-aligned organizations, country teams, and partner consortia.

7.1 Governance Readiness Review

Before seeking serious UN partnership, an organization should conduct a governance readiness review. The review should examine board oversight, executive accountability, financial controls, segregation of duties, procurement, anti-fraud practice, safeguarding, data governance, complaint handling, staff capacity, duty of care, monitoring and evaluation, and community accountability. The output should be an evidence file, not a promotional brochure.

The review should identify red flags. These include unclear authority, no documented safeguarding pathway, no incident reporting process, weak audit trail, informal procurement, no data retention rule, inadequate partner due diligence, missing conflict-of-interest controls, and dependence on one individual for institutional memory. These weaknesses are common in growing organizations. They become dangerous when hidden. A partner that acknowledges weakness and has a credible repair plan is more trustworthy than one that claims maturity without evidence.

Proportionality matters. A small local organization should not be expected to imitate the administrative infrastructure of a large UN agency. But proportionality is not an excuse for unsafe practice. The standard is whether the organization understands the risks attached to its role and has controls appropriate to its size, mandate, and operating context.

7.2 Mandate Translation

UN-aligned organizations should be able to state precisely which UN priority they support, which population they serve, which policy or operational need they address, and which risks they recognize. Generic references to the Sustainable Development Goals are not enough. A credible proposal should connect to a specific need: food security, health preparedness, child protection, displacement response, climate adaptation, governance support, digital inclusion, peacebuilding, gender equality, social protection, or local resilience.

Mandate translation prevents opportunistic alignment. It also helps reviewers test whether the organization understands the political and ethical conditions of the work. A digital education proposal for displaced children, for example, must address connectivity, language, disability inclusion, child safeguarding, data protection, teacher support, psychosocial needs, host-community relations, and sustainability. A proposal that speaks only about technology is not mandate-ready.

The strongest proposals state the trade-offs. They explain what the organization will do, what it will not do, what assumptions must hold, what risks remain, and what decision points would trigger redesign. This candor is a mark of maturity, not weakness.

7.3 Country-Level Application

Strategic risk management becomes most useful at country level because that is where global priorities meet political economy, local institutions, security conditions, climate exposure, social norms, market realities, and community trust. A global strategy may identify the right themes, but a country team must decide which risks are immediate, which are structural, and which actors can realistically move them.

A country-level risk review should involve programme teams, operations, security, finance, procurement, data protection, safeguarding, monitoring and evaluation, local partners, government counterparts where appropriate, and affected community feedback. It should not be a headquarters exercise performed at distance. The most important risk signals often sit close to implementation.

One practical tool is the ninety-day risk action memo. Every quarter, the leadership team records the three most important risk signals, the decision taken, the owner, the resource implication, the safeguard implication, and the next review date. The memo should be short. Its value is that it reduces the distance between risk awareness and decision. It also creates institutional memory when staff rotate.

7.4 Partner Risk Allocation

Partnership agreements should include a risk allocation section. This section should identify who carries delivery risk, security risk, safeguarding risk, fiduciary risk, data risk, reputational risk, and cash-flow risk. It should also identify what support accompanies each responsibility. If a local partner is responsible for sensitive data collection, it needs data protection training, secure systems, and clear sharing rules. If it is responsible for safeguarding referrals, it needs survivor-centered protocols and safe complaint pathways. If it is expected to deliver in insecure areas, duty-of-care arrangements cannot be vague.

Donors and UN entities should examine payment timing and overhead honestly. Late reimbursement can push smaller partners into debt or force them to delay staff salaries. Overhead restrictions can prevent partners from building the systems donors later demand. Excessive reporting can consume the very capacity needed for delivery. Risk-informed partnership is not a demand for lower standards. It is a demand that standards be resourced.

A partner risk meeting should occur before scale, not after problems appear. The meeting should ask what failure would look like, who would see it first, how it would be reported, and how the partnership would respond. This is a better use of time than assuming goodwill will solve structural strain.

7.5 Data and Digital Assurance

Every UN-facing organization that handles personal or sensitive data should maintain a data and digital assurance file. The file should state the purpose of data collection, the legal or ethical basis, the minimum data required, consent or alternative justification, retention period, sharing rules, security controls, breach response, human oversight, and grievance route. Where AI or automated decision support is used, the file should include bias review, explainability limits, override authority, and monitoring.

Data protection should be connected to programme design. It is not enough for an organization to have a policy. The question is how the policy affects field practice. Are enumerators trained? Are devices secure? Are paper records protected? Are vulnerable people told how data will be used? Can they correct errors? Who can access the database? What happens if a partner leaves the consortium? What happens if government requests conflict with protection concerns?

Digital assurance is also about inclusion. A tool that assumes smartphones, literacy, stable connectivity, official identity documents, or language fluency may exclude precisely those whom the programme is meant to serve. Accessibility, offline options, human support, and alternative pathways are not secondary design choices. They are risk controls.

7.6 Evaluation as a Management Trigger

Evaluation should trigger management action, not only institutional reflection. Each recommendation should have an owner, deadline, resource implication, and verification method. If leadership rejects a recommendation, the reason should be recorded. If action requires donor flexibility, the donor should be engaged. If action requires partner capacity, support should be built into the next workplan.

A management response without follow-up is a polite ritual. The organization can say it has learned, but learning remains unproven. A stronger approach tracks recommendation status over time: accepted, partially accepted, rejected, in progress, completed, verified, or superseded. The tracker should be reviewed by leadership, not left as an evaluation-office file.

Learning should also be shared with partners and affected communities where appropriate. If people provided feedback or suffered from a programme weakness, they should not disappear from the learning process. Accountability includes explaining what changed.

Chapter 8: Scenario Stress Tests

Scenario stress testing helps leaders examine whether a plan can survive plausible disruption. It is not prediction. It is a disciplined way to expose fragile assumptions. Many strategies assume stable access, donor continuity, partner capacity, data availability, staff safety, government cooperation, and community acceptance. Any one of those assumptions can fail. In compound risk settings, several may fail together.

The following stress tests can be used by UN entities, country teams, partner organizations, donors, and academic training programmes.

8.1 Funding Contraction

The team assumes a thirty percent funding reduction over six months. It asks which outputs stop, which staff roles become critical, which partners face cash-flow risk, whether safeguarding or monitoring would be weakened, which affected groups lose support first, and how the organization would communicate prioritization. This scenario is essential because funding contraction rarely affects all activities equally. It exposes the real hierarchy of priorities.

The leadership question is not simply what can be cut. It is what must be protected because cutting it would create disproportionate harm. Monitoring, safeguarding, security, and partner support may appear indirect, but removing them can make frontline delivery unsafe or unaccountable. A risk-informed budget cut protects the functions that protect people.

The scenario should produce pre-agreed prioritization rules. Waiting until money is gone invites hurried and opaque decisions. Donors should be involved where restrictions prevent adaptive action. A funding contraction plan should identify minimum service packages, decision thresholds, and communication duties.

8.2 Access Deterioration

The team assumes that conflict, bureaucracy, insecurity, disaster, or political tension reduces access to key locations. It asks whether remote management is safe, whether local partners can carry delivery, whether data quality can be maintained, how affected communities will communicate needs, and whether staff and partner security protocols are adequate.

This scenario tests whether localization is supported or merely assumed. If local partners become the only route to delivery, they need resources, security guidance, communication channels, and authority to adapt. Remote management can protect international staff while increasing local partner exposure. Risk leadership must not allow that transfer to remain invisible.

Access deterioration also tests data integrity. When direct monitoring becomes difficult, organizations may rely on partner reports, third-party monitors, remote sensing, call centers, or community feedback. Each method has limits. The stress test should identify how triangulation will occur and what uncertainty will be reported.

8.3 Data Failure

The team assumes that a data platform becomes unreliable, unavailable, compromised, biased, or ethically contested. It asks what decisions depend on the platform, what manual or alternative procedures exist, how personal data will be protected, whether affected people can challenge errors, and who has authority to suspend the tool.

Data failure is increasingly strategic because digital systems are becoming central to targeting, registration, payments, supply planning, monitoring, and reporting. A platform failure can become a protection failure, cash failure, trust failure, or public communication failure. The stress test should therefore include technical, legal, ethical, and operational staff.

The most important question is whether human judgment can still function. If staff cannot explain or override the system, the organization has created dependency. Digital modernization should increase capability, not reduce institutional judgment.

8.4 Legitimacy Shock

The team assumes that public trust declines because of misinformation, a safeguarding incident, a contested partnership, a data breach, poor communication, corruption allegation, or political backlash. It asks who communicates, what evidence is available, how complaint channels work, whether partners are aligned, and how the organization will act without becoming defensive.

Legitimacy shocks often begin in perception, but they can quickly become operational. Communities may refuse assistance, staff may face hostility, access may narrow, donors may suspend funds, and partners may distance themselves. The response must therefore be factual, transparent, and protective. Hiding problems usually deepens the shock.

A legitimacy stress test should include pre-approved communication principles: tell the truth quickly, protect confidentiality, acknowledge uncertainty, state what is being done, avoid blaming affected people or partners, and provide routes for complaint and correction. Trust is not preserved by image management. It is preserved by credible action.

8.5 Combined Shock

The most realistic test is combined shock. The team assumes that funding falls, access deteriorates, data become unreliable, and public trust weakens in the same quarter. This is not pessimism. It reflects the way compound crises behave. One shock often triggers another. Funding cuts may reduce monitoring. Reduced monitoring may weaken data. Weak data may create targeting errors. Targeting errors may damage trust. Damaged trust may reduce access.

A combined-shock exercise should identify minimum viable mandate delivery. What must continue? Which populations are highest priority? Which safeguards cannot be suspended? Which decisions can be delegated? Which partnerships must be reinforced? Which communications are required? The exercise should end with a short action plan and named owners.

This is also a useful training tool for NYCAR classes. Students can be assigned roles – country director, risk officer, local partner, donor, safeguarding adviser, data protection officer, community representative – and asked to negotiate decisions under constraint. The exercise teaches that risk leadership is not abstract. It is the art of making defensible choices when every option has a cost.

Chapter 9: Ethics, Safeguards, and Political Realism

Strategic risk management in the UN system cannot be ethically neutral. It concerns people whose lives, rights, safety, dignity, and future opportunities are affected by institutional choices. A risk framework that protects the organization while ignoring those people has failed at the level of mandate.

At the same time, ethics without political realism can become performative. UN entities operate through member states, governing bodies, donors, host governments, legal constraints, security environments, and public scrutiny. A serious framework must be morally clear and politically literate. It must recognize constraints without letting constraints become excuses for avoidable harm.

9.1 Safeguarding as Strategic Risk

Safeguarding is often treated as a specialized compliance area. It should also be understood as strategic risk because abuse, exploitation, harassment, retaliation, and unsafe complaint systems can destroy trust, harm people, damage access, and invalidate results. A programme that delivers outputs while exposing people to abuse has not succeeded. It has failed at the most basic level of responsibility.

Safeguarding must be resourced. Training, complaint pathways, survivor-centered response, partner support, investigation capacity, monitoring, and leadership accountability require time and money. Under funding pressure, these functions may appear indirect. They are not. They are protective infrastructure.

Safeguarding also has a partner dimension. Local partners may be required to meet standards without adequate support. This creates both compliance risk and ethical risk. A UN-facing organization should not impose standards it is unwilling to help partners implement. The right approach is firm expectations plus practical capacity support.

9.2 Human Rights and Data Risk

Data governance is a rights issue when information concerns refugees, displaced people, children, survivors of violence, people living with disease, political dissidents, undocumented migrants, or communities in conflict areas. Data can help target assistance and protect people. It can also expose them. The same dataset that improves delivery may become dangerous if shared with the wrong actor, breached, retained too long, or used for a purpose people did not understand.

A rights-sensitive data practice begins with purpose. Why is the data needed? What is the minimum necessary? Who will access it? How long will it be kept? Can people refuse without losing essential assistance? Can they correct errors? What happens if authorities request access? What safeguards apply if the data concern children or protection risks? These are not technical afterthoughts. They are programme design questions.

AI and automated decision support require even stronger caution. A model may produce a score, but affected people need a route to contest decisions. Human oversight must be meaningful. Sensitive decisions affecting access to assistance, protection referrals, or eligibility should not be reduced to opaque automation. The human rights standard is not satisfied by speed alone.

9.3 Political Realism

Political realism means recognizing that risk decisions occur in contested environments. Member states may disagree. Host governments may resist scrutiny. Donors may earmark funds. Communities may distrust institutions. Armed actors may manipulate access. Public narratives may be distorted. The UN system must navigate these realities without surrendering mandate integrity.

Risk leadership therefore includes diplomatic judgment. Not every risk can be announced publicly in the same way. Not every trade-off can be solved by technical design. Some choices require negotiation, advocacy, quiet escalation, coalition-building, or phased action. But political complexity should not become a cover for silence. Leaders should record what is known, what is constrained, which options were considered, and why a decision was made.

This is especially important when resources are insufficient. Scarcity can force tragic choices. Ethical leadership does not pretend otherwise. It makes prioritization criteria explicit, protects the most vulnerable where possible, explains trade-offs to donors and affected communities, and records residual harm honestly. The absence of resources may explain a failure to deliver everything. It does not justify dishonest reporting.

9.4 Trust as a Strategic Asset

Trust affects access, safety, participation, reporting, fundraising, and legitimacy. It should therefore be measured and managed as a strategic asset. Trust is built through delivery, honesty, safeguards, responsiveness, and respect. It is weakened by inflated claims, opaque decisions, unaddressed complaints, extractive data practices, late payments to partners, and defensive communication.

Organizations should measure trust through multiple signals: community feedback, complaint data, partner surveys, staff morale, donor confidence, media analysis, access negotiations, and programme participation. None of these signals is perfect. Together, they can show whether accountability is visible.

Trust is not protected by hiding problems. It is protected by facing them. Affected people and partners do not expect perfection. They are more likely to trust institutions that acknowledge failure, correct it, and explain what changed. Strategic risk management therefore turns trust from a public relations concern into a performance condition.

Chapter 10: Sector-Specific Strategic Risk Files

Sector files translate the general framework into applied areas. Each file identifies the risk pattern, the leadership question, and the evidence that should be requested. The files are not exhaustive. They are meant to help UN-facing organizations build sharper risk notes for different mandate areas.

10.1 Food Security and Hunger Risk

Food security risk is immediate because consequences are bodily and time-sensitive. Delays, access restrictions, supply failure, funding cuts, inflation, market disruption, and targeting errors can quickly become malnutrition, hunger, displacement, or social tension. The leadership question is whether the organization can protect life-saving assistance while making prioritization transparent and accountable.

Evidence should include food security analysis, market monitoring, supply-route risk, pipeline status, partner capacity, protection analysis, targeting criteria, community feedback, and complaint data. Risk-adjusted results should report not only people reached but adequacy, timeliness, inclusion, and residual unmet need. Under funding contraction, leaders should state what ration reductions or prioritization decisions mean for affected people.

Innovation in food security should be judged by field usefulness. Digital payments, satellite analytics, AI-assisted vulnerability analysis, and supply-chain tools can help, but only if data quality, privacy, inclusion, and explainability are protected. The test is whether the tool improves decisions for hungry people, not whether it impresses institutional audiences.

10.2 Refugee Protection and Displacement Risk

Displacement risk is political, legal, social, and operational. Refugees, asylum seekers, internally displaced persons, stateless people, and host communities face risks that cannot be solved by assistance alone. Documentation, legal status, protection from refoulement, family unity, gender-based violence prevention, shelter, education, livelihoods, health, and durable solutions all interact.

The leadership question is whether results reporting remains attached to protection meaning. How many people were registered matters. Whether registration protected confidentiality and improved access to rights also matters. How many shelters were provided matters. Whether women, children, older persons, persons with disabilities, and marginalized groups were safe also matters.

Evidence should include protection monitoring, legal access data, community feedback, complaint systems, referral pathways, confidentiality controls, data-sharing agreements, host-community analysis, and durable-solution prospects. Strategic risk management should resist any performance narrative that counts activity while ignoring legal and protection conditions.

10.3 Development Governance and Institutional Risk

Development governance risk often appears slowly. A programme may achieve outputs while leaving institutions unable to sustain them. Climate shock, corruption, weak public finance, political turnover, conflict, or debt distress can undermine gains after the project closes. The leadership question is whether development investments are risk-proofed against foreseeable shocks.

Evidence should include political economy analysis, institutional capacity assessment, fiscal sustainability, climate risk screening, procurement integrity, public finance implications, stakeholder ownership, and maintenance plans. Development results should be judged partly by whether local systems can continue the work.

Risk-informed development also requires humility about external support. International assistance can strengthen national capacity, but it can also create dependency or parallel systems. The test is whether local institutions, civil society, and communities gain capability, authority, and resources that survive beyond the project cycle.

10.4 Child-Focused Systems and Intergenerational Risk

Child-focused risk is cumulative. Harm that occurs early can shape education, health, protection, income, and social participation for a lifetime. Conflict, displacement, climate shock, poverty, gender inequality, disability exclusion, violence, and digital harm often interact. The leadership question is whether programmes protect the children most likely to be missed by scale.

Evidence should include disaggregated data, child safeguarding, disability inclusion, gender analysis, education continuity, nutrition status, WASH access, social protection coverage, community feedback, and safe child participation. Results should be adjusted for equity. A large programme that misses excluded children has limited strategic value.

Intergenerational risk also requires long-term thinking. Cutting education in emergencies, underfunding adolescent girls, neglecting child protection, or ignoring mental health may appear to save resources in the short term. The future cost is high. Strategic risk management should make that cost visible.

10.5 Public Health Preparedness and Trust Risk

Public health preparedness risk is often politically invisible until the emergency arrives. Surveillance, laboratories, workforce training, community engagement, emergency coordination, supply readiness, and financing mechanisms are easier to neglect than emergency response. The leadership question is whether preparedness is treated as a measurable result.

Evidence should include readiness assessments, surveillance coverage, laboratory capacity, workforce training, supply plans, emergency operations arrangements, risk communication capacity, community trust data, and flexible funding. Preparedness reporting should show not only activities completed but response capability improved.

Trust is central. Communities must believe guidance, report symptoms, accept services, and understand uncertainty. Misinformation, attacks on health care, politicized guidance, and poor communication can weaken response. Public health risk leadership therefore includes social listening, local partnership, transparent communication, and protection of health workers.

10.6 Digital Cooperation and Information Integrity

Digital cooperation risk cuts across sectors. Data systems, AI tools, digital public infrastructure, biometric registration, cash platforms, remote monitoring, and communication systems can improve performance. They can also create exclusion, surveillance risk, cyber exposure, bias, and misinformation. The leadership question is whether digital tools are governed as rights-sensitive operations.

Evidence should include data protection impact assessment, cybersecurity review, accessibility testing, algorithmic risk analysis, human oversight rules, grievance mechanisms, vendor due diligence, interoperability plans, and shutdown conditions. Digital results should report who was excluded, what errors occurred, and how complaints were resolved.

Information integrity is now a strategic risk. Disinformation can damage vaccination, humanitarian access, trust in refugee services, election support, climate action, and peacebuilding. Institutions must monitor information environments without manipulating communities. The ethical line is clear: risk communication should inform, listen, and correct; it should not deceive.

10.7 Climate and Future Generations Risk

Climate risk is both immediate and intergenerational. Droughts, floods, heat, storms, sea-level rise, crop loss, water stress, and displacement affect health, food, education, protection, and public finance. The leadership question is whether programmes are designed for climate conditions that are already foreseeable.

Evidence should include climate risk screening, adaptation analysis, early warning, local knowledge, environmental safeguards, contingency plans, and financing for resilience. Climate risk should not be handled only by environment teams. It belongs in education planning, health systems, food security, social protection, procurement, infrastructure, and displacement response.

Future generations language requires more than moral appeal. It requires present decisions that reduce long-term exposure. When budgets cut preparedness, adaptation, education, health prevention, or child protection, they may be transferring risk to people who cannot vote in current budget cycles. Strategic risk management gives leaders a vocabulary for naming that transfer.

Chapter 11: Recommendations

The recommendations below are designed for UN entities, country teams, donors, governing bodies, partner organizations, and UN-facing institutions. They should be adapted to mandate, legal status, context, and scale. They are not a universal checklist. They are a disciplined starting point.

11.1 Place Risk Review Inside Strategic Decision Forums

Risk review should not sit only in audit or compliance meetings. It belongs in strategic planning, programme approval, budget review, partner selection, procurement, safeguarding escalation, data governance, emergency response, and evaluation follow-up. Every major decision should include a short risk intelligence note identifying the top risks, recent field signals, proposed treatment, owner, residual exposure, and decision required.

This recommendation matters because risk only changes performance when it changes choices. A long risk annex buried in a report is less useful than a one-page risk note presented at the moment of decision. Leaders need concise, evidence-backed risk intelligence at the table where authority is exercised.

11.2 Link Foresight to Budget Flexibility

Foresight should trigger resource options. If scenarios identify likely funding, conflict, climate, health, digital, or legitimacy shocks, the organization should identify flexible funding, contingency procurement, surge capacity, partner agreements, or communication plans. A scenario without a resource option is not yet operational.

Donors and governing bodies should support adaptive funding with accountability. Flexibility does not mean weaker reporting. It means reporting on adaptive decisions, documented trade-offs, and changed conditions rather than forcing programmes to pretend that the original plan still fits.

11.3 Build Risk-Adjusted Results Reporting

Results reports should include risk-adjusted interpretation. Programmes should report what was achieved, whether quality standards held, which groups were reached or missed, what risk was reduced, what residual exposure remains, what complaints or harm concerns arose, and what changed in the next phase.

This will make reporting more honest and more useful. It will also protect organizations from inflated success claims that later collapse under scrutiny. Donors should welcome this approach because it provides a more accurate view of value.

11.4 Shorten Decision Lag Without Weakening Safeguards

Organizations should measure decision lag in selected high-risk processes. Emergency response, safeguarding escalation, procurement, funding reallocation, data incident response, partner agreement approval, and access negotiation are good starting points. The goal is not speed at any cost. The goal is timely, proportionate authority.

Safeguards should be built into rapid action. Prepared organizations can move quickly because roles, templates, escalation routes, partner vetting, legal guidance, and contingency funds are pre-agreed. Slow processes are sometimes defended as careful, but weak preparedness can masquerade as care.

11.5 Protect Local Partners From Hidden Risk Transfer

Localization and partnership reform should include honest risk allocation. UN entities and donors should examine payment timing, overhead, reporting burden, security support, safeguarding capacity, data systems, training, and dispute resolution. Local partners should not be expected to carry delivery, security, safeguarding, and cash-flow risk without authority and support.

The PTAS model can be used as a pre-scale review. If trust conditions are weak, the partnership should be strengthened before larger responsibilities are assigned. Strategy should not depend on partner heroism.

11.6 Govern Data, Digital, and AI as Rights-Sensitive Operations

Digital projects in UN contexts should be reviewed for purpose, privacy, security, inclusion, explainability, human oversight, bias, grievance routes, and shutdown conditions. Sensitive data and AI systems should not be scaled until governance is ready. A tool that cannot be explained to affected people or staff is not ready for high-risk deployment.

This recommendation is especially important after the Global Digital Compact. The UN system can lead by showing that digital modernization and rights protection can move together. Trust will be the measure of success.

11.7 Use Evaluation as a Management Trigger

Evaluation recommendations should be connected to owners, deadlines, resources, and follow-up evidence. Leadership should review implementation status. Rejected recommendations should include reasons. Accepted recommendations should show what changed.

This transforms evaluation from a retrospective product into a management control. It also helps institutions retain learning despite staff turnover and emergency pressure.

11.8 Make Trust Measurable

Trust should be measured through community feedback, complaint systems, partner surveys, donor confidence, staff signals, access conditions, and public communication evidence. Trust is not public relations. It is an operating condition. Affected people should know how to complain, partners should be able to challenge unrealistic plans, and public claims should be supported by evidence.

Trust is protected when institutions tell the truth, correct failure, and show that feedback changes action.

Table 5. Recommendations and evidence for oversight

Recommendation Reason Evidence to request
Place risk in strategic forums Risk matters when it changes choices. Decision notes, owners, residual exposure, meeting records
Link foresight to budget flexibility Future risks need present options. Scenario triggers, contingency funds, donor flexibility
Use risk-adjusted results Outputs can hide exclusion, harm, and fragility. Quality, equity, sustainability, residual risk, harm review
Measure decision lag Late decisions can perform like wrong decisions. Elapsed days by stage, corrective actions
Protect local partners Partnership can transfer risk downward. Payment timing, overhead, role clarity, safeguarding support
Govern data and AI Digital systems can create rights and trust risks. Privacy review, cybersecurity, human oversight, grievance route
Use evaluation as trigger Learning matters only when management changes. Management response tracker, verification evidence
Measure trust Trust affects access, reporting, safety, and legitimacy. Feedback data, complaint analysis, partner surveys, communication evidence


Chapter 12: Limitations and Research Agenda

The research has clear limitations. It is based on public documentary evidence and does not claim access to confidential UN decision-making, internal risk registers, internal audit files beyond public documents, country-level dashboards, or staff interviews. It therefore cannot determine whether any specific entity consistently applies the practices described. It can analyze formal intent, public management logic, and visible evidence of institutional priorities, but not the full internal sequence of decisions.

The diagnostic models are conceptual. They have not been statistically validated. Their weights are reasoned rather than empirically derived. In practice, weights should be adapted to mandate and context. A humanitarian logistics operation may weight resource mobility more heavily. A protection agency may weight safeguards and trust more heavily. A health emergency function may weight preparedness, surveillance, and communication. A development governance programme may weight sustainability and national systems.

Scoring also depends on honesty. Organizations may overrate themselves, especially when scores are linked to external reputation. The models should therefore be used for internal learning before external reporting. When used for oversight, scores should be supported by evidence and open to partner and field challenge. Without contested evidence, the models could become another performance ritual.

Context also matters. A low SRLI score may indicate weak leadership, but it may also indicate an extreme operating environment, donor inflexibility, insecurity, or political constraints. The models should not punish teams for naming hard realities. In fact, an honest low score may be more useful than an inflated high score. The purpose is improvement, not public ranking.

Future research should test the models through case studies at country level. Researchers could apply SRLI, DLD, RARD, and PTAS to selected programmes across humanitarian, development, protection, and health contexts. They could compare leadership perceptions with partner and community perceptions. They could examine whether decision-lag reduction improves results quality. They could test whether risk-adjusted reporting changes donor dialogue. They could explore how digital governance affects trust in different contexts.

A second research agenda concerns funding flexibility. Many strategic risk failures are tied to resource rigidity. Future studies should examine which donor instruments allow adaptive management without weakening accountability. This could include pooled funds, crisis modifiers, contingency lines, adaptive workplans, and results reporting that accepts justified change.

A third agenda concerns local partners. Researchers should examine how risk is allocated in partnership agreements and whether localization reforms are accompanied by overhead, duty-of-care support, safeguarding capacity, data systems, and dispute mechanisms. Without this work, localization risks becoming an attractive term that hides unequal exposure.

A fourth agenda concerns AI and data in UN-facing operations. As AI tools become more common, researchers should study explainability, human oversight, bias, exclusion, grievance routes, procurement standards, and accountability when automated systems influence assistance, protection, or public services. This research must be interdisciplinary, combining technology governance with human rights, humanitarian ethics, and field operations.

A final agenda concerns institutional culture. Risk tools do not work if leaders punish bad news. Future research should study psychological safety, escalation behavior, leadership incentives, and the relationship between organizational culture and decision lag. The strongest risk framework will fail if staff and partners do not believe that truth can travel upward safely.

Chapter 13: Conclusion and Executive Note

Strategic risk management for United Nations system performance is leadership under constraint. It is the discipline of making mandate delivery more dependable when the operating environment is unstable and when failure carries human consequences. The UN system already has substantial strategy language, reform agendas, and risk tools. The next test is whether these instruments change decisions quickly, honestly, and ethically enough to protect results.

This research has argued that risk is not a compliance annex. It is a leadership signal, a results condition, a partner issue, a digital governance challenge, a future generations concern, and a trust matter. UN 2.0 and the Pact for the Future provide a strong reform platform, but their value will depend on translation into operating choices. Data, digital tools, innovation, foresight, and behavioural science will improve multilateral performance only if they are linked to safeguards, field usability, budget authority, partner support, and evidence learning.

The case readings show that strategic risk differs by mandate. WFP is tested by hunger, supply chains, prioritization, funding pressure, and innovation. UNHCR is tested by displacement, protection, data responsibility, results integrity, and evaluation follow-up. UNDP is tested by risk-informed development, governance, climate exposure, and national systems. UNICEF is tested by child-centered equity, systems resilience, and intergenerational harm. WHO is tested by preparedness, health emergencies, trust, and flexible financing. System-wide reform is tested by whether broad agendas become daily management decisions.

The diagnostic tools introduced here are intentionally practical. The Strategic Risk Leadership Index examines whether leadership conditions exist. The Risk-Adjusted Results Delivery model protects against output reporting that hides risk. The Decision-Lag Diagnostic shows where risk intelligence slows before action. The Partner Trust and Accountability Score treats partnership quality as a delivery control. Scenario stress testing forces strategies to confront plausible disruption. None of these tools replaces judgment. They discipline judgment.

For organizations seeking to be attractive to the UN system, the lesson is clear. They should not approach the UN with fashionable language alone. They should demonstrate risk-informed planning, credible safeguards, responsible data governance, partner discipline, financial control, evaluation follow-up, and the ability to adapt without losing accountability. They should be able to show how they protect people, manage resources, learn under pressure, and make trade-offs visible.

The final professional judgment is direct. Multilateral strategy will be credible only when it becomes operationally answerable. Leaders must be able to say what risk was seen, who acted, what changed, which trade-off was accepted, what harm was prevented, which result survived, and what was learned. In a world of compound risk, that discipline is not administrative refinement. It is part of the moral and practical work of international cooperation.

Executive Note for UN-Oriented Review

This research paper is suitable for an advanced NYCAR class on strategic risk management, institutional leadership, public administration, and UN-facing policy practice. It gives students and practitioners a framework for examining how multilateral organizations move from risk awareness to decision accountability. Its value lies in the combination of ethical seriousness and management discipline.

The research should be read as an applied model-building study, not as an investigative audit. Its strongest classroom use is as a diagnostic exercise. Students can select a UN programme, country strategy, or partner proposal and apply SRLI, RARD, DLD, PTAS, and scenario stress testing. They should be asked to identify evidence, challenge assumptions, and explain trade-offs. That will teach the central lesson: risk leadership is not the act of listing dangers. It is the act of making defensible decisions when mandate, resources, uncertainty, and human stakes collide.

References

Joint Inspection Unit. (2017). Results-based management in the United Nations system: Description of a high-impact model for managing for achieving results (JIU/NOTE/2017/1). United Nations.

Joint Inspection Unit. (2020). Enterprise risk management: Approaches and uses in United Nations system organizations (JIU/REP/2020/5). United Nations.

United Nations. (2023). UN 2.0: A United Nations ready for the future. United Nations.

United Nations. (2024). Pact for the Future, Global Digital Compact and Declaration on Future Generations (A/RES/79/1). United Nations.

United Nations Development Programme. (2021). Risk-informed development: A strategy tool for integrating disaster risk reduction and climate change adaptation into development. UNDP.

United Nations Children’s Fund. (2021). UNICEF Strategic Plan 2022-2025. UNICEF.

United Nations Children’s Fund. (2025). UNICEF Strategic Plan 2026-2029 (E/ICEF/2025/29). UNICEF Executive Board.

United Nations High Commissioner for Refugees. (2024). Strategy for evaluation in UNHCR 2024-2027. UNHCR.

United Nations High Commissioner for Refugees. (2025). Global Report 2024. UNHCR.

United Nations System Chief Executives Board for Coordination. (2021). Policy on the Organizational Resilience Management System. CEB.

United Nations System Chief Executives Board for Coordination. (2025). HLCM far-reaching efficiency initiatives. CEB.

World Food Programme. (2022). WFP Strategic Plan 2022-2025. WFP Executive Board.

World Food Programme. (2025c). WFP Strategic Plan 2026-2029. WFP Executive Board.

World Food Programme. (2025a). WFP Corporate Results Framework 2026-2029. WFP Executive Board.

World Food Programme. (2025b). WFP Innovation Strategy 2025-2027. WFP Executive Board.

World Health Organization. (2025a). WHO Health Emergencies: 2025 funding and priorities. WHO.

World Health Organization. (2025b). WHO’s Health Emergency Appeal 2025. WHO.

The Thinkers’ Review
Strategic Decision-Making and Change Management in the Electric-Mobility Transition

Strategic Decision-Making and Change Management in the Electric-Mobility Transition

A Toyota Motor Corporation Case Study

Research Publication by Anthony C. Ihugba

Institutional Affiliation: New York Center for Advanced Research (NYCAR)

Publication No.: NYCAR-TTR-2026-RP065

Date:  June 2026

DOI: https://doi.org/10.5281/zenodo.20733536


Peer Review and Publication Status

Peer Review Status:

This research publication underwent independent peer review coordinated by the New York Center for Advanced Research (NYCAR) in partnership with The Thinkers’ Review. Reviewers with subject-matter expertise in strategic management, organizational change, and technology and automotive strategy assessed the work independently of the author. They examined the framing of Toyota’s multi-pathway approach as a decision-making problem, the treatment of change-management and competitive-risk evidence, the soundness of the mixed-methods design, and the restraint of the Strategic Transition Balance Model used to interpret public data. The reviewers found the central argument — that managing the electric-mobility transition demands judgment that avoids both panic and complacency — to be well grounded and relevant to leaders facing comparable transitions. The publication was approved for release in accordance with NYCAR’s Research Ethics Policy, with no conflicts of interest identified between the reviewers and the author.

Abstract

The global automotive industry is moving through one of the hardest transitions in its history. Electrification, software-defined vehicles, battery supply chains, emissions regulation, Chinese competition, shifting consumer demand, and pressure for carbon neutrality are forcing carmakers to rethink the logic of scale, product development, manufacturing, and brand trust. The research examines strategic decision-making and change management through Toyota Motor Corporation. Toyota is a useful case precisely because it has not followed a single-path battery-electric strategy. It has instead defended a multi-pathway approach spanning hybrids, plug-in hybrids, battery electric vehicles, fuel-cell vehicles, software investment, and continued operational discipline.

Toyota’s case is often debated because the company has been praised for hybrid leadership and criticized for moving too cautiously on battery electric vehicles. That tension makes the case valuable. Strategic management is rarely about choosing between an obviously right and obviously wrong path. It is often about making decisions under technological uncertainty, uneven infrastructure readiness, regulatory pressure, and regional differences in customer demand. Toyota’s fiscal year 2024 performance gives the case empirical weight. The company reported consolidated vehicle sales of about 9.443 million units, net revenues of 45.095 trillion yen, operating income of 5.352 trillion yen, and net income of 4.944 trillion yen for the year ended March 31, 2024. At the same time, global electric vehicle markets continued to grow, with the International Energy Agency estimating that electric car sales could reach around 17 million in 2024.

The research uses a mixed-methods case-study design. Qualitatively, it analyzes Toyota’s leadership logic, multi-pathway electrification strategy, change-management discipline, quality culture, regional market exposure, and risks in software and battery-electric competition. Quantitatively, it builds a Strategic Transition Balance Model and a risk-adjusted change equation. Rather than a simple growth model, the framework weighs financial strength, electrified-sales momentum, technology diversity, execution discipline, software readiness, and transition risk.

The central argument is that Toyota’s strategic challenge is not whether it should change. It is how to change without destroying the strengths that made it trusted. The company’s multi-pathway approach may be strategically rational in a world where markets are not moving at the same speed. Yet the strategy will only remain credible if Toyota strengthens battery-electric execution, software capability, transparency, and speed. The lesson for managers is that change management is not a choice between tradition and disruption. It is the harder work of deciding what must be protected, what must be accelerated, and what must be abandoned before the market decides for the organization.

Keywords: strategic decision-making, change management, Toyota, electrification, hybrid strategy, electric vehicles, automotive transformation

Table of Contents

Chapter 1: Introduction

1.1 Background to the Study

The automobile industry is being reshaped by a transition that reaches far beyond the engine. Electric vehicles are changing supply chains, battery demand, charging infrastructure, manufacturing economics, vehicle software, dealership models, and customer expectations. Governments are tightening emissions rules. China has become a major force in electric vehicle production and export. Consumers are asking harder questions about price, range, reliability, charging access, and total cost of ownership. Carmakers that built their reputations over decades must now decide how quickly to change and what kind of change will actually endure.

Toyota Motor Corporation sits at the center of this debate. For decades, Toyota has been associated with quality, lean production, reliability, manufacturing discipline, and hybrid technology. The Prius helped make hybrid vehicles mainstream long before battery electric vehicles became a global policy priority. Yet the rise of Tesla, BYD, and other electric-vehicle competitors has raised questions about whether Toyota’s caution toward battery electric vehicles was strategic patience or strategic delay.

The answer is not simple. Toyota operates in many regions with different customer incomes, energy systems, charging infrastructure, regulatory rules, and consumer habits. A battery-electric strategy that makes sense in parts of China or Europe may not work the same way in rural markets, emerging economies, or places with weak charging networks. Toyota’s multi-pathway strategy rests on that reality. The company argues that hybrids, plug-in hybrids, battery electric vehicles, fuel-cell vehicles, and efficient internal-combustion technologies all have roles in reducing carbon emissions across different contexts.

Toyota’s fiscal year 2024 results show the strength of the company entering this transition. For the year ended March 31, 2024, Toyota reported consolidated vehicle sales of approximately 9.443 million units, net revenues of 45.095 trillion yen, operating income of 5.352 trillion yen, and net income of 4.944 trillion yen (Toyota Motor Corporation, 2024a). These figures show financial strength and market scale. They also create a strategic question: how should a very successful company change when the market is moving, but not uniformly?

The global context is equally important. The International Energy Agency reported that electric car sales could reach around 17 million in 2024 and account for more than one in five cars sold globally (International Energy Agency, 2024). That growth does not mean every market is ready at the same speed, but it does show that electrification is no longer a niche movement. Toyota must therefore manage two truths at once: its hybrid-led model remains commercially powerful, and the battery-electric transition is real.

1.2 Problem Statement

Strategic decision-making becomes difficult when the future is visible but uneven. The automotive industry clearly needs to decarbonize, but the route is contested. Battery electric vehicles are growing quickly, yet barriers remain: affordability, charging infrastructure, battery minerals, grid capacity, regional policy differences, and consumer anxiety over range and resale value. Automakers must invest heavily before demand is fully predictable.

Toyota faces this problem in a sharper way because its existing strengths are still valuable. The company’s hybrid technology, manufacturing discipline, supplier networks, brand trust, and global scale continue to generate strong performance. Those strengths can support the transition, but they can also slow it if leaders become too attached to the logic that made Toyota successful in the past.

A second problem is that change management in large organizations is not only about announcing new technology. It requires supply-chain redesign, workforce capability, software development, battery procurement, plant investment, dealer adaptation, and customer education. Toyota’s case therefore raises a deeper management question: how can a mature company change fast enough for a new market without abandoning the capabilities that still give it advantage?

1.3 Aim and Objectives

The aim of this paper is to examine how strategic decision-making and change management shape Toyota’s response to the electric-mobility transition.

The objectives are to analyze Toyota’s multi-pathway strategy as a response to uncertain and uneven market conditions; examine the role of hybrid leadership, manufacturing discipline, and regional demand in Toyota’s transition choices; assess the risks of slower battery-electric execution and software competition; apply a strategic transition balance model to interpret Toyota’s position; and develop practical recommendations for leaders managing technological change in mature organizations.

1.4 Research Questions

Five questions guide the research. How does Toyota’s multi-pathway strategy reflect strategic decision-making under uncertainty? What strengths does Toyota carry into the electric-mobility transition? What risks does it face if battery-electric and software-defined vehicle markets accelerate faster than expected? How can the transition be assessed using both qualitative and quantitative indicators? And what can leaders draw from the case about managing change without either panic or complacency?

1.5 Significance of the Study

The topic matters because many organizations face Toyota’s basic dilemma in some form. They must change, yet they cannot simply discard what made them strong. In that situation leadership calls for judgment rather than fashion. Move too slowly and relevance erodes; move too quickly without execution discipline and trust, margins, and quality can all go with it.

The Toyota case is important for strategic management because it shows the tension between operational excellence and strategic reinvention. Toyota’s production system and quality culture helped define modern manufacturing. The question now is whether the same discipline can support software, batteries, digital services, and new mobility models.

The study is also relevant for change management because it challenges simplistic thinking. Transformation is not always a heroic leap. Sometimes it is a portfolio of decisions: protect hybrids where they reduce emissions now, invest in battery electric vehicles where infrastructure and demand are ready, build software capacity faster, manage suppliers carefully, and keep customer trust intact.


Chapter 2: Literature Review

2.1 Strategic Decision-Making Under Uncertainty

Strategic decisions are hardest when evidence points in more than one direction. In stable markets, leaders can rely on known demand patterns and familiar competitors. In transition markets, the signals are mixed. Electric vehicle growth is strong globally, but adoption differs by region. Some customers want battery electric vehicles immediately. Others prefer hybrids because they are cheaper, familiar, and less dependent on charging infrastructure.

Toyota’s multi-pathway approach can be read as a response to uncertainty. It avoids placing the entire company on one technology path before infrastructure, regulation, and consumer demand align globally. The strength of this approach is flexibility. The risk is that flexibility can become hesitation if the company underinvests in the path that later becomes dominant.

Strategic decision-making under uncertainty therefore requires options, but options must be actively developed. A company cannot simply keep every path open in theory. It must build real capability in the areas that matter.

2.2 Change Management in Mature Organizations

Mature organizations change differently from start-ups. They have legacy assets, established customers, brand expectations, unions, suppliers, plants, dealers, routines, and financial commitments. Change is not only a strategic choice; it is an organizational negotiation with the past.

Kotter’s recent work on change emphasizes the difficulty of achieving major movement in uncertain and volatile conditions (Kotter, 2021). In Toyota’s case, the challenge is not persuading people that the industry is changing. The challenge is deciding how much to change, where to move first, and how to maintain quality while building new capabilities.

Change management also has an emotional dimension. Employees and suppliers may have spent decades mastering internal-combustion and hybrid systems. Asking them to move toward software, batteries, and new manufacturing methods requires training, trust, and a clear explanation of why the change is necessary.

2.3 Toyota Production System and Operational Discipline

Toyota’s production system remains one of the most influential management models in the world. Its emphasis on continuous improvement, respect for people, problem solving, standard work, and waste reduction shaped manufacturing far beyond the automotive industry (Liker, 2021). This operating culture gives Toyota a real advantage in quality and efficiency.

Yet the same discipline can become a constraint if it makes the organization too cautious. Battery electric vehicles and software-defined vehicles require faster development cycles, new supplier relationships, over-the-air updates, battery chemistry knowledge, digital services, and platform architectures. These are not impossible for Toyota, but they require different rhythms from traditional automotive engineering.

The question is whether Toyota can translate its discipline into the new environment without allowing discipline to become slowness.

2.4 Electrification and the Global Automotive Transition

Electrification is not one market. It is a set of regional transitions moving at different speeds. The International Energy Agency reported that global electric car sales could reach around 17 million in 2024 and represent more than one in five cars sold (International Energy Agency, 2024). China, Europe, and the United States remain central markets, but their policies, charging networks, and competitive dynamics differ sharply.

This uneven transition helps explain Toyota’s multi-pathway logic. Hybrids may reduce fuel use immediately in markets where charging infrastructure is weak. Battery electric vehicles may be more suitable where policy incentives, charging access, and consumer readiness are stronger. Fuel cells may have future relevance in selected commercial or heavy-duty contexts, though adoption remains uncertain.

The management problem is timing. A multi-pathway strategy is rational only if the company keeps enough speed in the pathways that are accelerating. Otherwise, strategic flexibility can become a polite name for delay.

2.5 Software, Batteries, and New Competitive Logic

The automotive transition is not only about replacing engines with batteries. Software is changing what a vehicle is. Cars are becoming digital products that can be updated, connected, monitored, and integrated with services. This shift changes the competitive logic. Automakers now compete not only on reliability and driving experience, but also on user interface, driver assistance, data, charging experience, and software ecosystems.

Toyota has strong manufacturing credibility, but software competition exposes the company to different rivals and different expectations. Tesla, BYD, and Chinese electric vehicle firms have pushed speed, battery integration, digital features, and price competition. Toyota’s response must therefore include stronger software and battery execution, not only hybrid excellence.

2.6 Literature Gap

Much writing on Toyota’s transition falls into two camps. One camp treats Toyota as wise for resisting battery-electric hype. Another treats Toyota as slow and defensive. Both interpretations are incomplete. The stronger question is how Toyota balances transition risk, regional variation, financial strength, customer trust, and technological change.

The research addresses that gap by treating Toyota’s strategy as a management problem rather than a slogan, examining the strengths of multi-pathway thinking while also testing its weaknesses.

 Read also: Engineering Solutions For Efficient Healthcare Management

Chapter 3: Methodology

3.1 Research Design

The design is a mixed-methods case study. Qualitatively, it examines Toyota’s strategic decision-making, multi-pathway electrification logic, operational culture, market risk, and change-management challenge. Quantitatively, it applies the Strategic Transition Balance Model and a risk-adjusted change equation to interpret Toyota’s position.

The case-study method is appropriate because Toyota’s transition cannot be explained through a single variable. Vehicle sales, operating income, hybrid demand, battery-electric readiness, supplier capability, software development, and regulation all matter. Mixed methods allow the paper to connect case narrative with measurable indicators.

3.2 Case Selection

Toyota was selected because it is one of the world’s largest automakers and because its transition strategy is contested. The company’s continued financial strength, hybrid leadership, and global scale make it a serious case. At the same time, its slower battery-electric rollout and software challenges make it analytically useful.

The case is not used to declare Toyota right or wrong. It is used to examine how a mature organization makes strategic decisions when the future is changing but not uniformly settled.

3.3 Data Sources

Data Category Source Use in Analysis
Financial performance Toyota FY2024 financial results Revenue, operating income, net income, vehicle sales
Strategic direction Toyota Integrated Report 2024 Electrification, management priorities, governance narrative
Sustainability Toyota Sustainability Data Book 2024 Carbon neutrality and environmental commitments
Market context IEA Global EV Outlook 2024 Global EV adoption and transition pressure
Management theory Change management and Toyota Production System literature Conceptual framing for leadership and execution


3.4 Analytical Framework

The analysis uses six dimensions: financial strength, electrified sales momentum, technology diversity, operational discipline, software readiness, and transition risk. These dimensions were selected because Toyota’s strategy cannot be assessed through battery-electric sales alone. The company’s advantage lies partly in its broad portfolio, but its future risk lies partly in the speed and quality of its new capabilities.

Financial strength measures Toyota’s room to invest. Electrified sales momentum captures hybrid and electric progress. Technology diversity captures the multi-pathway portfolio. Operational discipline captures quality and production capability. Software readiness captures capability in digital vehicle architecture. Transition risk captures exposure to competitors, regulation, and market acceleration.

3.5 Quantitative Model


STB = 0.20F + 0.20E + 0.15D + 0.15O + 0.15S – 0.15R

Where STB represents strategic transition balance; F represents financial strength; E represents electrified sales momentum; D represents technology diversity; O represents operational discipline; S represents software and battery-electric readiness; and R represents transition risk.

A supporting risk-adjusted change expression is also used:

CA = (Q × A × C) – R

Where CA represents change advantage; Q represents quality of strategic decision-making; A represents adoption readiness; C represents capability depth; and R represents transition risk. This equation reflects a practical management point: change advantage rises when decisions, adoption readiness, and capability reinforce one another, but falls when transition risk is unmanaged.

3.6 Methodological Limitations

The research relies on public data and does not draw on internal Toyota documents or interviews with executives, engineers, dealers, suppliers, or customers. The quantitative model is interpretive and makes no claim to econometric proof; its job is to clarify the strategic balance Toyota faces.

A second limitation is that the EV market continues to change quickly. Data from 2024 captures an important moment, but market conditions in China, Europe, North America, and emerging economies may shift further. The analysis should therefore be read as a management interpretation of a transition in progress.


Chapter 4: Case Analysis and Findings

4.1 Toyota’s Strategic Position

Toyota enters the electric-mobility transition from a position of strength. It has global scale, manufacturing discipline, strong brand trust, deep supplier relationships, and long experience with hybrid technology. Its fiscal year 2024 performance was exceptional: 45.095 trillion yen in net revenues, 5.352 trillion yen in operating income, 4.944 trillion yen in net income, and approximately 9.443 million consolidated vehicle sales (Toyota Motor Corporation, 2024a).

However, strength does not remove transition risk. In fact, it can make transition harder because the current model still works. Toyota must decide how much to protect, how much to accelerate, and how much to redesign. That is the central leadership problem of the case.

4.2 Finding One: The Multi-Pathway Strategy Reflects Real Market Variation

The first finding is that Toyota’s multi-pathway strategy reflects a real feature of the global market. Electrification is not moving at the same speed everywhere. Charging access, government incentives, fuel prices, incomes, driving patterns, and grid conditions differ widely. A single technology pathway may be too narrow for a company operating across many regions.

This gives Toyota’s strategy a serious logic. Hybrids can reduce fuel consumption now in markets where battery-electric adoption is slower. Plug-in hybrids can serve customers who want electric driving without full dependence on charging networks. Battery electric vehicles are essential in markets where policy and consumer demand are moving quickly. Fuel-cell technology remains uncertain but may hold value in selected future applications.

The risk is that multi-pathway thinking can become a shield against urgency. Toyota must make sure that flexibility does not slow battery-electric and software capability where the market is already moving.

4.3 Finding Two: Hybrid Strength Gives Toyota Time, but Not Immunity

The second finding is that Toyota’s hybrid leadership gives it time, but not immunity. Hybrid demand has supported Toyota’s commercial strength, especially in markets where customers want lower fuel use without charging dependence. This has protected margins and customer relevance while other automakers have struggled with uneven EV demand and high battery costs.

But time is not the same as safety. If battery prices fall, charging improves, and competitors offer affordable electric vehicles with strong software experiences, hybrid leadership may become less protective. Toyota must use the time created by hybrid strength to build future capability, not merely to defend the present.

4.4 Finding Three: Financial Strength Supports Change Capacity

The third finding is that Toyota’s financial strength gives it room to manage the transition. Strong earnings create investment capacity for batteries, software, suppliers, manufacturing redesign, and new platforms. A weaker automaker might be forced into hurried decisions or dependent partnerships.

Toyota’s 2024 operating income of 5.352 trillion yen is therefore strategically important (Toyota Motor Corporation, 2024a). It gives the company the ability to invest through uncertainty. However, financial strength must be converted into speed and capability. Cash alone does not create transformation.

4.5 Finding Four: Software Is the Hardest Cultural Shift

The fourth finding is that software may be Toyota’s hardest transition. Manufacturing excellence and software excellence do not operate on the same rhythm. Vehicle manufacturing rewards discipline, defect reduction, supplier coordination, and controlled change. Software rewards iteration, user feedback, fast updates, and platform thinking.

Toyota does not need to abandon quality discipline. It needs to translate that discipline into a software environment without becoming slow. This may require different talent, governance, partnerships, and product-development routines. The company’s future competitiveness will depend increasingly on whether customers experience Toyota vehicles as digitally capable, not only mechanically reliable.

4.6 Finding Five: Quality Trust Must Be Protected During Acceleration

The fifth finding is that Toyota must protect trust while accelerating change. The company’s reputation has been built on reliability. In an electric and software-defined environment, reliability includes battery performance, charging behavior, cybersecurity, driver-assistance systems, over-the-air updates, and data handling.

Speed can damage trust if quality systems fail. But excessive caution can also damage trust if customers see Toyota as behind. Change management must therefore balance acceleration with disciplined validation.

4.7 Quantitative Case Table

Indicator Reported Evidence Strategic Interpretation
FY2024 consolidated vehicle sales Approx. 9.443 million units Scale remains a major strategic asset.
FY2024 net revenues 45.095 trillion yen Strong revenue base supports transition investment.
FY2024 operating income 5.352 trillion yen Financial strength gives room for technology investment.
FY2024 net income 4.944 trillion yen Profitability supports resilience during transition.
Global EV market outlook Around 17 million electric car sales possible in 2024 External pressure for faster electrification remains strong.
Strategy orientation Multi-pathway electrification Flexibility across regional demand and infrastructure conditions.


The Strategic Transition Balance Model assigns interpretive scores on a five-point scale: financial strength = 5, electrified sales momentum = 4, technology diversity = 5, operational discipline = 5, software and battery-electric readiness = 3, and transition risk = 4. Because risk is subtracted, the calculation is:

STB = (0.20 × 5) + (0.20 × 4) + (0.15 × 5) + (0.15 × 5) + (0.15 × 3) – (0.15 × 4)

STB = 1.00 + 0.80 + 0.75 + 0.75 + 0.45 – 0.60 = 3.15 out of 4.25

The score suggests that Toyota has strong transition capacity but meaningful risk. Its financial strength, operational discipline, and technology diversity are powerful. Its weaker point is the speed and credibility of software and battery-electric execution relative to faster-moving competitors.

4.8 Summary of Findings

Five findings stand out. Toyota’s multi-pathway strategy reflects real market variation. Hybrid strength gives the company time, but not immunity. Financial strength supports change capacity. Software is the hardest cultural shift. Quality trust must be protected during acceleration.

Together, these findings show why Toyota’s case should not be read as simple resistance to change. It is better understood as a struggle to manage change at global scale without losing the reliability and discipline that made the company strong.


Chapter 5: Discussion

5.1 The Difference Between Patience and Delay

Toyota’s case turns on a difficult distinction: patience versus delay. Strategic patience means refusing to follow market fashion before the economics, infrastructure, and customer demand are ready. Strategic delay means failing to build capability while competitors move ahead. The same decision can look wise in one year and costly in another.

Toyota’s multi-pathway approach has been commercially effective because hybrids remain attractive to many customers. Yet the company must avoid confusing current demand with permanent demand. The EV market may not move evenly, but it is moving. Patience must therefore be active, not passive. Toyota should be using hybrid strength to fund and accelerate future capability.

5.2 Change Management as Portfolio Discipline

The case suggests that change management in mature firms is portfolio discipline. Toyota cannot simply shut down its existing model and become a new EV start-up. It has customers, plants, suppliers, dealers, workers, and regions that depend on different technologies. But it also cannot allow each technology path to compete for attention without a clear view of future value.

Portfolio discipline means asking hard questions. Which hybrid programs remain strategic? Which battery-electric platforms need faster scaling? Which software systems must be centralized? Which suppliers need support? Which activities should stop receiving investment? Change is not only about adding new things. It is also about deciding what no longer deserves protection.

5.3 The Cultural Challenge of Software

Toyota’s culture is built around quality, production discipline, and problem solving. Those strengths remain valuable. The question is whether the organization can also become faster in software. Software-defined vehicles require continuous improvement after sale, not only excellence before sale.

This shift may challenge Toyota’s traditional routines. Engineers, software developers, data specialists, cybersecurity teams, and user-experience designers need different decision cycles. The company must create ways for software speed and Toyota quality to coexist. If it chooses only speed, it risks defects. If it chooses only control, it risks irrelevance.

5.4 Regional Strategy and Customer Reality

One strength of Toyota’s position is that it takes regional variation seriously. Customers in different markets face different realities. A driver with reliable home charging and incentives may reasonably choose a battery electric vehicle. A driver in a region with weak charging infrastructure may find a hybrid more practical. A commercial fleet may evaluate fuel, maintenance, uptime, and total ownership cost differently from a private customer.

This customer reality supports Toyota’s multi-pathway logic. But regional strategy must not become an excuse for weak global capability. Toyota needs enough battery-electric and software strength to compete where the transition is fastest, while still serving regions where hybrids remain sensible.

5.5 Lessons for Leaders

The first lesson is that leaders should not treat disruption as a religion. Not every new technology deserves immediate total commitment. The second lesson is that leaders should not treat past success as protection. A profitable business model can still be moving toward decline.

The third lesson is that change requires both courage and sequencing. Toyota’s leadership must protect trust, but also accelerate areas where the market is no longer waiting. The fourth lesson is that options only matter if they are funded, staffed, and governed. A multi-pathway strategy must be more than a list of technologies. It must be a disciplined allocation of capability.


Chapter 6: Conclusion and Recommendations

6.1 Conclusion

Toyota’s strategic decision-making in the electric-mobility transition is neither simple caution nor simple resistance. It reflects a serious attempt to manage uneven global demand, infrastructure limits, customer diversity, and technological uncertainty. The company’s financial strength, hybrid leadership, operational discipline, and global scale give it real transition capacity.

Yet the case also shows clear risk. Battery-electric competition, software-defined vehicles, Chinese automakers, regulatory pressure, and changing customer expectations require faster execution. Toyota’s future advantage will depend on whether it can use its present strength to build the next capability base. The central conclusion is that change management is not the rejection of the past. It is the disciplined decision to decide which parts of the past still serve the future.

6.2 Recommendations

Toyota should keep the multi-pathway strategy but make its investment logic far more transparent. Stakeholders need to see how hybrids, plug-in hybrids, battery electric vehicles, fuel cells, and software platforms fit into one coherent transition plan.

Battery-electric execution needs to accelerate in markets where policy, infrastructure, and competitors are already moving quickly. A multi-pathway strategy cannot become an excuse for a slow battery-electric response.

Software capability should be treated as a core strategic priority rather than a support function, since Toyota’s reliability reputation will increasingly rest on digital performance.

Hybrid profitability should be used to fund future platforms. The commercial success of hybrids ought to be a bridge to what comes next, not a reason to defend the present indefinitely.

Change communication should be strengthened across employees, suppliers, and dealers. The transition will demand trust across the whole system, not just executive announcements.

6.3 Implementation Roadmap

Timeline Strategic Priority Practical Action
First 90 days Transition clarity Publish a sharper internal map linking technology pathways to regional market conditions.
3-6 months Software capability audit Identify gaps in talent, architecture, cybersecurity, data systems, and update capability.
6-12 months Battery-electric acceleration Prioritize markets where EV adoption, regulation, and competitive pressure are strongest.
12-18 months Supplier transition support Align suppliers with battery, software, and electrified-platform requirements.
Ongoing Risk-adjusted portfolio review Review technology investment against adoption, margins, regulation, and customer trust.


6.4 Final Reflection

Toyota’s case is powerful because it does not offer an easy answer. A company can be right to avoid panic and still wrong to move too slowly. It can be right to protect quality and still need to change faster. It can be right that customers differ by region and still need stronger battery-electric and software capability. Strategic leadership lives in that tension. The future will not reward firms that merely defend the past, but it may also punish firms that abandon discipline. Toyota’s challenge is to prove that disciplined change can still move quickly enough.


References

International Energy Agency. (2024). Global EV outlook 2024: Moving towards increased affordability. IEA. https://www.iea.org/reports/global-ev-outlook-2024

Kotter, J. P. (2021). Change: How organizations achieve hard-to-imagine results in uncertain and volatile times. Wiley.

Liker, J. K. (2021). The Toyota way: 14 management principles from the world’s greatest manufacturer (2nd ed.). McGraw Hill.

Toyota Motor Corporation. (2024a). TMC announces April through March 2024 financial results. Toyota Motor Corporation. https://pressroom.toyota.com/tmc-announces-april-through-march-2024-financial-results/

Toyota Motor Corporation. (2024b). Integrated report 2024. Toyota Motor Corporation.

Toyota Motor Corporation. (2024c). Sustainability data book 2024. Toyota Motor Corporation.

World Economic Forum. (2024). The global risks report 2024. World Economic Forum.

The Thinkers’ Review
Engineering Mathematics, Model Credibility, and Complex Technical Problem-Solving

Engineering Mathematics, Model Credibility, and Complex Technical Problem-Solving

Applied Decision Models for Technical Risk, Reliability, and Systems Execution

A DOCTORAL PUBLICATION

Samuel A. Nneke

New York Center for Advanced Research (NYCAR)

Research Division — Engineering Systems and Decision Science

Date: June 2026

Publication No.: NYCAR-TTR-2026-RP046

DOI: https://doi.org/10.5281/zenodo.20581384

Peer Review Status: This doctoral publication has undergone independent peer review conducted under the joint editorial framework of the New York Center for Advanced Research (NYCAR) and The Thinkers’ Review. Independent reviewers assessed the manuscript for academic coherence, source integrity, technical and mathematical rigor, methodological soundness, engineering voice, and APA 7th edition alignment. Each quantitative result was independently re-derived, every cited source independently verified, and the work cleared for release only on the basis of that independent assessment.


Table of Contents


Abstract

Engineering mathematics is usually hidden behind the finished object: the aircraft that returns safely, the rover that lands between hazards, the power grid that holds frequency after a generator trips, the bridge that does not fatigue under repeated loading, and the factory process that keeps tolerance despite heat, vibration, and material variation. The discipline earns its value at the point where physical judgment must become computable without becoming naïve. Competent engineers do not solve hard problems by writing equations for their own elegance. They reduce uncertainty, expose impossible trade-offs, test design margins, and decide which risks can be accepted before a technical choice becomes irreversible.

The work that follows treats engineering mathematics as a practical decision discipline for complex technical problem-solving. The concern is not classroom mathematics separated from engineering consequence, but the working mathematics used in systems design, reliability analysis, optimization, control, simulation, measurement, and verification. Public case evidence is drawn from the NASA Apollo 13 crisis, NASA Mars 2020 and Perseverance terrain-relative navigation, Great Britain’s electricity-system operability work under low-carbon transition pressure, and the verification, validation, and uncertainty-quantification practice codified by NIST and ASME. These cases span different technologies and different stakes, yet they share one operating truth: a technical problem becomes solvable once constraints are measured, assumptions are named, the model is checked against reality, and the decision stays tied to physical consequence.

Three applied tools are developed for managers and technical teams: an Engineering Model Credibility Index, a Constraint-Resolution Priority Matrix, and a Reliability and Uncertainty Exposure Score. None is offered as a universal formula. Each is a structured prompt for engineering judgment, with worked numerical illustrations that show how the scores behave and where they can be abused. A high-fidelity simulation with poor validation should not be trusted because it looks sophisticated. A mathematically optimal design that fails manufacturing tolerance is not optimal in the real system. A control strategy that performs under nominal conditions but collapses under disturbance is not robust. The argument closes on a single standard: engineering mathematics should be judged by disciplined usefulness — whether it clarifies the problem, protects safety margins, improves technical decisions, and keeps complex systems from being governed by intuition alone.

Keywords: engineering mathematics, complex technical problem-solving, reliability analysis, optimization, uncertainty quantification, verification and validation, control systems, model credibility, NASA, National Grid, NIST, ASME, NYCAR.

Document map: Abstract · Chapter 1 Introduction · Chapter 2 Technical Foundations and Literature Review · Chapter 3 Methodology and Applied Quantitative Framework · Chapter 4 Public Case Evidence · Chapter 5 Analysis and Discussion · Chapter 6 Recommendations and Professional Standards · Chapter 7 Conclusion · References · Internal Editorial Review Report.

Chapter 1: Introduction

1.1 Problem Setting

Complex technical problems do not arrive as clean exercises. They arrive with partial measurements, competing objectives, damaged hardware, incomplete models, stressed teams, limited time, and consequences that can move from financial loss to human harm in a few bad decisions. A power grid cannot pause while engineers debate perfect theory. A spacecraft cannot wait for a complete laboratory replication of a fault. A bridge, aircraft, medical device, pipeline, data center, or automated production line is already embedded in material reality by the time its problem becomes visible. Engineering mathematics matters because it gives teams a disciplined way to think when the physical system refuses to simplify itself.

The weak reading of engineering mathematics treats it as calculation. The stronger reading treats it as constraint discipline. A model identifies what must be conserved, bounded, estimated, optimized, monitored, or rejected. A differential equation describes change only when the state variables and boundary conditions have been chosen honestly. A finite element mesh produces insight only when the load path, material model, contact assumptions, and validation evidence deserve confidence. A reliability equation helps only when failure modes have not been hidden for convenience. That distinction separates technical maturity from mathematical theatre, and it runs through every case examined later.

Modern engineering raises the difficulty because systems are increasingly coupled. Software changes hardware behavior. Sensors change maintenance strategy. Cloud computation changes operations. Renewable generation changes grid stability. Additive manufacturing changes material variation. Autonomy changes how uncertainty must be handled. A technical issue that once belonged to one discipline now crosses mechanics, electronics, software, data science, control, human factors, regulation, supply chains, and finance. The mathematics has to travel across those boundaries without losing physical meaning, and the people who own it have to travel with it.

The aim here is to examine the managerial and engineering value of that discipline. The concern is neither to celebrate mathematics as pure abstraction nor to reduce complex work to formulas. The concern is to show how engineering mathematics lets competent teams impose order on uncertainty, choose between imperfect options, and defend technical decisions in front of safety boards, regulators, operators, executives, and the public. Used well, mathematics makes assumptions visible. Used badly, it hides them behind precision, and a hidden assumption is the most expensive line item in any engineering programme.

1.2 Aim and Objectives

The aim of this research publication is to examine engineering mathematics as an applied problem-solving capability in technically complex environments. Mathematical modeling, optimization, reliability analysis, simulation, verification, validation, and uncertainty quantification are treated as parts of one decision system rather than as separate academic specialisms. The intent is not to produce a specialist monograph in a single branch of applied mathematics, but to show how mathematical reasoning supports engineering judgment when failure, cost, time, and operational constraints have to be managed together.

Five objectives organize the work. The leading objective is to clarify the difference between mathematical calculation and engineering model credibility, because the two are routinely confused in practice. A second objective reviews the foundations most relevant to high-consequence technical decisions — dimensional analysis, dynamic systems, optimization, reliability, control, simulation, and uncertainty. A third objective develops practical indices and diagnostic models that technical managers can adapt to real projects, complete with worked examples. A fourth objective analyzes documented public case studies from organizations whose technical challenges are a matter of record, including NASA, National Grid Electricity System Operator, NIST, and the professional verification communities served by ASME. A closing objective proposes a disciplined standard for deciding when an engineering model is credible enough to influence design, operation, or crisis response.

1.3 Research Questions

The inquiry is built around a set of connected questions. How should engineering mathematics be understood when technical problems involve physical uncertainty, operational pressure, and institutional accountability at the same time? Which mathematical tools are most useful for solving complex technical issues without oversimplifying the system they describe? How should engineers judge the credibility of simulations and analytical models before decisions come to depend on them? What can public case studies reveal about trajectory correction, autonomous navigation, power-system stability, and computational model validation? Which management practices keep mathematical analysis from drifting away from physical evidence, operator knowledge, and safety margins?

These questions are deliberately practical. They assume the reader already accepts the value of mathematics; the harder issue is governance — who owns assumptions, how errors are detected, where uncertainty is carried, and when a result is mature enough to guide action. In serious engineering, a number is not persuasive merely because it has decimals. It becomes persuasive when the chain from measurement to model to decision has survived scrutiny, and when someone with authority is willing to put their name on that chain.

1.4 Significance of the Work

The significance of the argument lies in the gap between technical complexity and decision confidence. Organizations are surrounded by models: digital twins, simulations, dashboards, forecasts, optimization engines, reliability tools, and automated diagnostics. Many of those tools are valuable. Some are fragile. Others are trusted well beyond what the evidence permits. Engineering leaders need a way to ask not only whether a model is advanced, but whether it is relevant, verified, validated, calibrated, explainable, and safe enough for the specific decision in front of them.

The topic also matters because mathematical failure is rarely announced as mathematical failure. It surfaces as underestimated load, poor tolerance stack-up, unstable control behavior, hidden fatigue, false precision, overfitted forecasting, brittle automation, or a plan that looked optimal until the real system moved outside its assumptions. The public sees a bridge closure, a grid warning, a mission delay, a production defect, or a safety incident. Inside the engineering record, the cause often traces back to a weak model, a missed boundary condition, a neglected uncertainty, or a decision-maker who accepted a calculation without asking what it left out.

1.5 Scope and Limitations

Several boundaries should be stated plainly so the contribution is not over-read. The analysis is integrative rather than experimental; it does not estimate empirical coefficients from a controlled dataset, and the weights proposed in the diagnostic tools are provisional values meant for expert recalibration, not validated constants. The case evidence is restricted to public, citable material, which protects against confidentiality problems but also means the internal engineering records of each programme are visible only through what their owning institutions chose to publish. The mathematical treatment favors breadth across disciplines over depth in any one method, on the judgment that decision-makers gain more from seeing how the tools connect than from a single exhaustive derivation. Where depth matters — reliability models, verification error, control stability — the relevant equations are stated and their assumptions named, so the reader can see exactly where credibility is conditional.

A further limitation is cultural rather than technical. The recommendations assume an organization willing to let mathematical evidence override schedule pressure when safety is at stake. In settings where that willingness is absent, no index or matrix will substitute for the missing governance, and the tools should be read as instruments for organizations that already want to think clearly, not as a cure for organizations that do not.

1.6 Positioning Relative to Existing Frameworks

The argument advanced here does not arrive on empty ground. Model verification and validation has a mature literature in computational mechanics, codified in community standards that distinguish verification, the question of whether the equations are solved correctly, from validation, the question of whether the correct equations are being solved. Reliability engineering has an equally mature apparatus of failure-mode analysis, fault trees, and probabilistic risk assessment. Decision analysis offers structured methods for ranking actions under uncertainty. The contribution of this work is not to displace any of these traditions but to connect them, because in everyday engineering practice they are too often kept in separate documents owned by separate specialists, and the decision that needs all three at once receives none of them in an integrated form.

Where the established verification-and-validation standards concentrate on the technical adequacy of a model in isolation, the instruments proposed here ask the adjacent question that those standards leave implicit: given a model of known and limited credibility, how much should it be allowed to influence a specific decision with specific stakes. That question is unavoidably about governance and consequence, not only about numerical accuracy, and it is the question that determines whether a sound model is used well or a flawed model is used recklessly. The three instruments are therefore best read as a translation layer between the deep technical practices that assess a model and the organizational decisions that consume it, rather than as a replacement for either.

This positioning also clarifies the work’s scope. It does not propose new numerical methods, new reliability mathematics, or new decision theory; each of those fields is deeper than any single framework could summarize. It proposes a disciplined way of bringing their outputs to bear on the moment of decision, expressed in instruments simple enough that a working team will actually use them and structured enough that their use leaves an auditable trace. A contribution of this kind is judged less by mathematical novelty than by whether it changes behavior in the room where the decision is made, which is the standard against which the case studies and the implementation guidance should be read.

Chapter 2: Technical Foundations and Literature Review

2.1 Engineering Mathematics as Working Judgment

Engineering mathematics begins with a severe demand: the abstraction must still answer to the object. A beam model must answer to a beam. A navigation filter must answer to a moving vehicle. A thermal model must answer to heat flow through material, joints, coatings, and ambient conditions. When the model is beautiful but the boundary conditions are fantasy, the beauty is irrelevant. Working engineers know this instinctively, and the literature on systems engineering, verification, validation, and uncertainty quantification gives the instinct formal structure rather than replacing it.

NASA’s Systems Engineering Handbook (National Aeronautics and Space Administration [NASA], 2016) frames systems engineering as a methodical, multidisciplinary approach spanning the design, realization, technical management, operation, and retirement of a system, and it links analysis directly to the use of mathematical modeling and analytical techniques for predicting compliance with requirements. That framing places mathematics inside a project life cycle rather than outside it. A calculation does not stand alone; it supports requirements, design choices, verification evidence, risk management, operations, and disposal. Mathematical work that cannot be connected to a system decision becomes intellectual residue rather than engineering evidence, and a mature programme treats it accordingly.

The practical distinction between calculation and judgment is visible in most major technical programmes. A load calculation may be correct under its assumptions yet useless when the design is manufactured to different tolerances. A forecast may be statistically elegant yet operationally dangerous when its tail risks drive safety. A control system may behave well in simulation yet fail when sensor noise, actuator delay, or human intervention changes the loop. Engineering mathematics is therefore judged by fit — fit to the decision, fit to the scale, fit to the evidence, and fit to the consequence of being wrong. The remainder of this chapter walks through the foundations that recur across the case evidence, with that test of fit kept in view throughout.

2.2 Dimensional Analysis, Scaling, and Physical Sanity

Dimensional analysis is one of the least glamorous and most protective habits in engineering. Before a team trusts a complicated model, it should know whether the quantities make physical sense. Units catch errors that sophistication misses. Scaling arguments expose impossible expectations. Non-dimensional numbers often reveal which forces dominate before detailed computation begins. Reynolds number, Mach number, Froude number, Biot number, Strouhal number, and dimensionless stiffness ratios are not academic decoration; they are compact tests of physical regime that a competent reviewer can apply in minutes.

The Buckingham Pi theorem formalizes the intuition: a physical relationship among n variables expressed in k independent dimensions can be rewritten as a relationship among n minus k dimensionless groups. The value is not the reduction of variables alone; it is the discipline of asking which combinations actually govern behavior. A heat-transfer correlation written in dimensionless form transfers across geometries that a dimensional fit cannot. A model that cannot be expressed in consistent dimensionless terms usually conceals a confusion about what it is really computing.

The habit matters because complex systems invite numerical seduction. A simulation may generate contour plots, convergence histories, and polished animations while the physical scale is wrong. A cost-optimization model may treat time as linear when delays compound. A structural model may report stress to four significant figures while the real uncertainty lives in the load assumptions. Dimensional analysis cannot solve every problem, but it frequently prevents teams from solving the wrong one, and it does so cheaply enough that skipping it is rarely defensible.

Scaling also protects against naïve transfer. A prototype that works at laboratory scale may fail at production scale because heat transfer, friction, turbulence, vibration, or material variability changes regime. A control strategy tuned in a quiet environment may behave differently under field noise. A process that appears efficient in a pilot plant may turn unstable once batch size, residence time, or mixing geometry change. Engineering mathematics therefore keeps asking whether the model has crossed a regime boundary that the project’s language has failed to notice — the kind of boundary that turns a validated correlation into a confident error.

2.3 Optimization Under Constraint

Optimization is often misunderstood as the search for the best answer. In serious engineering, it is the disciplined search for the best admissible compromise. The design must meet safety limits, cost limits, manufacturability limits, weight limits, thermal limits, control limits, maintenance limits, regulatory limits, and operating limits at once. Optimizing one variable while quietly violating another produces a number that may be mathematically clean and technically unusable.

Constrained optimization is most valuable where trade-offs are unavoidable. Aerospace design balances mass, fuel, thrust, structural strength, thermal protection, reliability, and mission envelope. Power-system operation balances generation, demand, frequency stability, reserves, inertia, emissions, and cost. Manufacturing balances throughput, yield, tolerance, energy use, maintenance, and quality risk. In each setting the mathematical task is not to maximize ambition but to locate feasible movement — the direction in design space that improves the objective without breaching a constraint that cannot be breached.

Formally, the engineer minimizes an objective f(x) subject to inequality constraints g_i(x) less than or equal to zero and equality constraints h_j(x) equal to zero. The Karush-Kuhn-Tucker conditions describe the stationary point where the gradient of the objective is balanced by a weighted sum of constraint gradients, with the multipliers revealing which constraints are active. Those multipliers carry engineering meaning: a large multiplier on a weight constraint says that relaxing weight would buy a large improvement elsewhere, which is precisely the kind of trade-off a design review should discuss rather than bury. An optimum where no constraint is active is often a sign that the model has been posed too loosely to be useful.

A workable optimization framework begins with three questions that sound simple and rarely are: what is the objective, what cannot be violated, and how will uncertainty change the result? The objective may represent cost, weight, time, energy, risk, reliability, or value. Constraints may be hard or soft. Uncertainty may enter through loads, demand, weather, human behavior, material properties, sensor error, or market conditions. A model that ignores uncertainty can be useful for exploration, but it should not be treated as final engineering direction once the real system is known to be disturbed. Robust and stochastic optimization exist precisely to keep the answer honest when the inputs are not fixed.

2.4 Reliability, Failure Probability, and Technical Risk

Reliability mathematics gives engineers a language for the uncomfortable fact that systems can satisfy design intent and still fail. Reliability is not the same as quality inspection. It is the probability that a system performs its required function for a specified time under stated conditions. That phrase carries several traps. The function must be defined. The time interval must be defined. The operating conditions must be stated. A reliability claim without those boundaries is vague reassurance dressed as a number.

The familiar exponential model R(t) = exp(−λt) is useful when the failure rate λ can be treated as constant, but many engineering systems do not behave so simply.

R(t) = exp(−λt),   with hazard rate h(t) = λ constant only during useful life.

Early-life failures, wear-out behavior, common-cause events, maintenance quality, environmental stress, software faults, operator action, and aging all break the constant-rate assumption. The familiar bathtub curve captures this: a decreasing hazard during infant mortality, a roughly flat hazard during useful life, and an increasing hazard during wear-out. The two-parameter Weibull distribution, with shape parameter beta and scale parameter eta, spans all three regimes — beta less than one for infant mortality, beta near one for the constant-rate region, and beta greater than one for wear-out — which is why it is the workhorse of life-data analysis. Fault trees, event trees, Markov chains, Bayesian updating, Monte Carlo simulation, and physics-of-failure methods extend the toolkit further. Selection of the model should follow the failure mechanism, not analyst habit or software default.

Reliability analysis also changes the culture of technical conversation. Instead of asking only whether a design works, the team asks how it fails, how failure propagates, whether failure is detectable, whether redundancy is real, and whether maintenance restores the intended state. In high-consequence systems a single component may meet its specification while the system stays vulnerable to coupling, software logic, human response, or maintenance delay. The mathematics should force those vulnerabilities into the open, which is exactly what the Reliability and Uncertainty Exposure Score introduced in Chapter 3 is designed to do.

2.5 Verification, Validation, and Uncertainty Quantification

Verification and validation are not interchangeable rituals. Verification asks whether the model or code solves the equations correctly. Validation asks whether those equations and assumptions represent the real system adequately for the intended use. Uncertainty quantification asks how much confidence should be placed in the result once input uncertainty, numerical error, model-form error, measurement error, and validation evidence have all been considered. Oberkampf and Roy (2010) give the canonical statement of this separation, and the verification, validation, and uncertainty-quantification standards of the American Society of Mechanical Engineers (ASME, 2006, 2009, 2024) exist because computational models have become influential enough that credibility must be disciplined rather than assumed.

Code verification and solution verification are distinct activities within the first question. Code verification confirms that the discrete algorithm converges to the governing equations, often through the method of manufactured solutions, which Roache (1998) helped establish. Solution verification estimates the discretization error in a specific calculation, typically through systematic mesh refinement and a grid-convergence index (Roy, 2005; American Institute of Aeronautics and Astronautics [AIAA], 1998). Skipping these steps and moving straight to comparison with experiment confuses two different sources of error and makes any apparent agreement difficult to trust, because a model can match data for the wrong reasons when numerical error and model-form error happen to cancel.

A summary of industrial verification, validation, and uncertainty-quantification procedures for simulation models (Raunak & Kuhn, 2021) stresses the sources of inaccuracy, the procedures for verification and validation, and the use of graded validation levels. The logic is not confined to fluid dynamics. The same structure applies across computational mechanics, thermal analysis, additive manufacturing (National Institute of Standards and Technology [NIST], 2024), structural dynamics, electromagnetics, and coupled multiphysics simulation. A model used for a low-risk screening decision does not require the same evidence as a model used for certification, mission safety, or the operation of public infrastructure. Credibility is graded because the stakes are graded.

Good practice changes the governing question from “is the model right?” to “is the model credible for this decision?” The shift matters because every model simplifies. Some simplifications are acceptable and some are lethal, and the difference depends on the decision rather than on the model in isolation. A simulation of a simple bracket may tolerate assumptions that would be indefensible in a coupled aeroelastic system. A model used for concept screening can be rough. A model used to authorize operation near a structural or thermal limit must be far stronger. Engineering mathematics matures at the moment it accepts that credibility is conditional and states the condition out loud.

2.6 Control, Estimation, and Feedback

Control theory supplies the mathematics for systems that must act while they are changing. A stable static design is not enough when the system is dynamic, sensed through imperfect measurements, and forced to respond in real time. Feedback loops, state estimation, observers, Kalman filters, robust control, model predictive control, and fault-tolerant control all exist because technical systems rarely sit still. Vehicles fly, grids fluctuate, robots move, temperatures drift, pressure waves propagate, and operators intervene at the least convenient moment.

Estimation is often the quiet center of control. A controller can act only on what it believes the state to be. The Kalman filter (Kalman, 1960) gives the optimal recursive estimate of a linear system’s state under Gaussian noise by blending a model prediction with a new measurement in proportion to their relative uncertainty. The same idea, extended and approximated, underlies the navigation filters that let a spacecraft know where it is. When sensor fusion is weak, a sophisticated control law will make confident decisions from poor information. When latency is ignored, the system responds to the past. When noise is treated as harmless, a controller chases fluctuations. When uncertainty is not bounded, the system can operate outside safe margins without knowing it.

Robust and predictive control address the gap between the nominal model and the real plant. Robust control seeks performance that degrades gracefully across a defined set of plant variations rather than performance that is excellent for one nominal model and brittle around it. Model predictive control repeatedly solves a constrained optimization over a finite horizon, which lets the controller respect actuator limits and safety constraints explicitly rather than hoping they are never reached. Both reflect the same engineering instinct that runs through this chapter: design for the disturbed system, not the convenient one.

2.7 Simulation, Digital Twins, and Model Governance

Simulation has become a central engineering instrument because it lets teams explore design space before physical testing becomes possible, expensive, or unsafe. Digital twins extend the idea by linking models with live operational data. Used well, these tools support predictive maintenance, performance monitoring, process optimization, and anomaly detection. Used carelessly, they manufacture false authority. A digital twin that is not maintained, calibrated, or connected to the right signals becomes a model wearing operational clothing, and the clothing is often more convincing than the model underneath.

Model governance is therefore a technical necessity rather than an administrative afterthought. Organizations need registers of models, owners, assumptions, validation evidence, version history, decision scope, uncertainty limits, and retirement triggers. The language sounds bureaucratic, but the function is pure engineering discipline. When a model changes without review, when input data drifts, when a parameter is reused outside its validation range, or when the operating environment shifts, the model can quietly lose credibility while its interface still looks reliable. The failure is silent precisely because the dashboard keeps rendering.

The rise of machine learning sharpens the issue. A physics-based model may fail because the physics is incomplete; a data-driven model may fail because the data does not represent future operating conditions. Hybrid models can be powerful, but they inherit both forms of risk and add the new risk of opacity. Engineering mathematics in the coming decade will increasingly require teams that can combine differential equations, statistics, optimization, software verification, and domain knowledge without letting any single method dominate the evidence. The governance question — who is accountable for this model in this decision — becomes more important, not less, as the methods grow more capable.

2.8 Human Factors and the Limits of Models

A foundation that the literature sometimes underweights is the human element inside the loop. Reason’s (1997) work on organizational accident causation and Rasmussen’s (1997) framing of risk management in dynamic socio-technical systems both show that complex failures rarely come from a single broken equation. They come from the migration of a whole system toward the boundary of safe operation under cost and workload pressure, with each local decision appearing reasonable at the time. A model that captures only the physical subsystem and ignores how operators, maintainers, and managers actually behave will misjudge where the real margin lies.

The practical consequence is that engineering mathematics should be embedded in a representation of the work as performed, not only the work as imagined. An emergency procedure that assumes unrealistic operator attention, an optimized maintenance interval that assumes a crew never defers a task, or an automation scheme that assumes a human will reliably take back control in two seconds are all mathematically clean and operationally fragile. The cases in Chapter 4 are partly stories about hardware, but they are equally stories about teams that understood, or failed to understand, the boundary between calculated behavior and human behavior.

2.9 Literature Gap

The literature on applied mathematics, systems engineering, verification, validation, reliability, and optimization is large and mature. The managerial gap is narrower but urgent. Technical leaders often need a practical structure for deciding how mathematical evidence should influence design and operations, and the specialist literature, while rich on method, offers less on judgment. Project teams need to know whether a method is mature enough for a given decision, whether uncertainty has been carried properly through the analysis, and whether the physical consequences of model error have been considered before the result is allowed to carry weight.

The contribution that follows sits in that gap. Rather than adding another method to an already crowded toolkit, the next chapter assembles the existing foundations into three diagnostic instruments aimed squarely at the decision: is this model credible enough to act on, which constraint should bind first, and how much hidden exposure is the system carrying? The instruments are deliberately simple to compute and deliberately hard to fake, which is the combination that survives contact with a real design review.

2.10 Numerical Methods and Discretization Error

Most engineering mathematics that matters in practice is not solved in closed form; it is solved numerically, and the numerical solution introduces its own error that has nothing to do with whether the underlying physics is right. A finite-element stress field, a finite-volume flow solution, and a time-stepped dynamic simulation are all approximations whose accuracy depends on mesh density, time-step size, element type, and solver tolerance. Treating the numerical answer as if it were the exact answer is one of the most common and least discussed errors in computational engineering, because the software rarely advertises its own discretization error on the same screen as the result.

Solution verification exists to quantify that error. Systematic mesh refinement, paired with a grid-convergence index, estimates how far a given solution sits from the mesh-independent answer and whether the solver is converging at its theoretical order of accuracy (Roy, 2005). When refinement does not reduce the error in the expected way, the problem is usually not the physics; it is a coding error, a singularity, a poorly posed boundary condition, or a solution that has not entered the asymptotic range. A team that reports a single-mesh result without a convergence study is reporting a number with an unknown error bar, and a decision built on that number inherits the unknown. The discipline is unglamorous and occasionally expensive, which is exactly why it is so often skipped and so often the root cause when a trusted simulation turns out to be wrong.

The managerial implication is that computational results should arrive with two error statements, not one. The first concerns model-form error, the gap between the equations and reality, which validation against experiment addresses. The second concerns numerical error, the gap between the discrete solution and the exact solution of those equations, which verification addresses. Confusing the two is how a model can appear validated while remaining numerically unconverged, agreeing with data only because two errors happened to cancel. The Engineering Model Credibility Index keeps the two separate by scoring verification and validation evidence as one weighted component while treating boundary-condition quality and uncertainty propagation as their own terms, so that a team cannot earn full marks by addressing one error and ignoring the other.

2.11 Probability, Statistics, and the Honest Error Bar

Probability and statistics enter engineering wherever a quantity is uncertain, which is almost everywhere once the system leaves the drawing board. Material properties scatter. Loads vary. Sensors carry noise. Manufacturing introduces tolerance. Demand fluctuates. The discipline is not the manipulation of distributions for their own sake; it is the honest expression of how much is not known and how that ignorance propagates into the decision. An engineer who reports a mean without a variance has reported half a result, and frequently the less important half, because the decision often turns on the tail rather than the center.

Two failures recur. The first is treating a fitted distribution as if it described the future when it only described a limited past, which is how a hundred-year load gets exceeded in year forty because the record was short and the climate or the usage changed. The second is propagating uncertainty through a nonlinear model by pushing the mean through and reporting the output, ignoring that the mean of a function is not the function of the mean. Monte Carlo propagation, polynomial chaos, and interval methods exist to handle this honestly, and the choice among them is itself an engineering judgment about how much the nonlinearity and the tail behavior matter for the decision at hand. None of these methods rescues a model whose input distributions were guessed; uncertainty quantification is only as honest as its inputs, which returns the burden to measurement discipline.

2.12 Coupled and Multiphysics Systems

The hardest contemporary problems are coupled: a structure that deforms changes the flow around it, which changes the load on the structure; a battery that heats changes its own chemistry, which changes how it heats; a control loop that acts on a plant changes the plant state the loop is trying to estimate. Coupling defeats the convenient habit of analyzing each subsystem in isolation and adding the results, because the interaction terms can dominate the behavior. Engineering mathematics for coupled systems has to represent the feedback between domains, and the credibility of such a model depends as much on the fidelity of the coupling as on the fidelity of each individual physics.

Coupling also reshapes uncertainty. An error in one subsystem can amplify through the interaction rather than staying contained, and a redundancy that looks robust in one domain can be defeated by a shared dependence in another. The Reliability and Uncertainty Exposure Score weights common-cause vulnerability heavily for exactly this reason: in a coupled system, the shared condition that links two supposedly independent paths is the failure that the component-level analysis never sees. A mature treatment of a coupled system therefore spends its scrutiny on the interfaces, because the interfaces are where the surprises live and where the isolated analyses quietly disagree with one another.

2.13 Linear Systems, Conditioning, and the Limits of Precision

A great deal of engineering computation reduces, somewhere in its interior, to the solution of a linear system. The deceptive feature of such systems is that a problem can be perfectly well-defined and still be nearly impossible to solve accurately, because the matrix that represents it is ill-conditioned. Conditioning measures how much a small perturbation in the input can be amplified into a large change in the output, and an ill-conditioned system amplifies the unavoidable rounding of finite-precision arithmetic and the unavoidable noise of measured inputs into an answer that may share few significant figures with the truth. The mathematics gives a clean warning in the form of the condition number, yet the warning is routinely ignored because the solver returns an answer without complaint.

The practical consequence is that an engineer cannot judge the trustworthiness of a computed result from the result alone. Two calculations can be set up identically, run on the same software, and return numbers of wildly different reliability because one problem was well-conditioned and the other was not. This is one of the clearest illustrations of the paper’s central theme: mathematical machinery that is internally flawless can still deliver an untrustworthy answer, and only an explicit examination of conditioning, residuals, and sensitivity reveals the difference. The Engineering Model Credibility Index folds this concern into its verification-evidence and sensitivity-analysis terms, because a team that has never examined the conditioning of its core computation cannot honestly claim to know its own numerical error.

2.14 Dimensional Analysis and the Discipline of Scaling

Dimensional analysis is among the oldest and most powerful tools in engineering mathematics, and it remains underused relative to its value. By insisting that equations be dimensionally consistent and by organizing variables into dimensionless groups, it reduces the number of independent parameters in a problem, exposes the scaling laws that govern behavior across size and speed, and catches a large class of formulation errors before any computation begins. A model that is dimensionally inconsistent is wrong regardless of how well it fits a particular data set, and a result that does not scale sensibly when its governing dimensionless groups are varied is a result to distrust.

Scaling discipline also guards against one of the most expensive errors in applied work: assuming that a result validated at one scale transfers to another. Behavior that is benign in a laboratory model can become dominant at full scale because a dimensionless group has crossed a threshold, and a design validated only at small scale carries a hidden extrapolation that the credibility index would flag under data sufficiency and misuse risk. Treating dimensional reasoning as a routine check rather than a textbook curiosity is one of the cheapest ways an organization can raise the baseline credibility of its mathematical work, because the check costs minutes and the error it prevents can cost a programme.

Chapter 3: Methodology and Applied Quantitative Framework

3.1 Research Design

The research design is integrative and applied. It combines literature-based synthesis, public case analysis, and the development of practical quantitative models for technical decision support. No confidential company data are used. The cases are drawn from public materials issued by NASA, National Grid Electricity System Operator, NIST, the ASME-linked verification communities, and related technical authorities. The design protects against legal and confidentiality problems while still grounding the analysis in real engineering situations rather than invented examples.

The method follows a four-step discipline that runs through every case. The opening step identifies technical settings in which mathematics carried operational consequence. The next step examines the type of mathematical reasoning involved — trajectory analysis, control, state estimation, simulation credibility, reliability, optimization, or power-system dynamics. A subsequent step extracts managerial lessons about evidence, constraints, uncertainty, and decision timing. The final step translates those lessons into tools that technical teams can adapt to their own projects. The sequence is deliberately repeatable so that a reader can apply it to a case the analysis does not cover.

This is not an empirical coefficient-estimation exercise, and it does not claim to prove universal weights for all engineering systems. The weighting in the proposed indices is provisional and should be recalibrated by domain experts. A nuclear safety case, an aerospace mission, a software-defined grid, a medical device, and a consumer product do not deserve identical risk weights, and any tool that pretends otherwise should be distrusted. The contribution is a usable structure for disciplined analysis, not a closed formula that removes the need for judgment.

3.2 Source Selection and Case Logic

Source selection prioritizes official and reputable public evidence. NASA materials support the Apollo 13 and Mars 2020 terrain-relative navigation cases because they document high-consequence engineering under mission constraints. National Grid Electricity System Operator materials are used because grid operability under low-carbon transition pressure is a current technical problem involving frequency, inertia, system stability, and balancing. NIST and ASME-linked materials are used because verification, validation, and uncertainty quantification provide the formal credibility framework behind computational engineering. Foundational texts — Oberkampf and Roy on verification and validation, Roache on computational verification, Kalman on estimation — anchor the methods in their primary literature rather than in secondary summaries.

The case logic is comparative by design. Each case was chosen to stress a different part of the mathematical decision system: crisis-time constraint management, autonomous estimation and guidance, dynamic stability under changing physics, and computational credibility under certification pressure. The comparison is what makes the cross-case lessons in Chapter 4 defensible, because a pattern that recurs across radically different technologies is more likely to reflect something real about engineering mathematics than a pattern observed in a single domain.

3.3 Engineering Model Credibility Index

The Engineering Model Credibility Index, abbreviated EMCI, is a diagnostic for judging whether a mathematical or computational model deserves influence over a technical decision. It is expressed as a weighted sum of eight positive components minus a misuse penalty.

EMCI = 0.18·FV + 0.16·VD + 0.14·BQ + 0.13·UP + 0.12·SA + 0.10·DS + 0.09·TR + 0.08·GO − 0.12·MU

FV is formulation validity, VD is verification and validation evidence, BQ is boundary-condition quality, UP is uncertainty propagation, SA is sensitivity analysis, DS is data sufficiency, TR is traceability, GO is governance ownership, and MU is misuse risk. Each component is scored from 0 to 100. The eight positive weights sum to exactly 1.00, so a model that scores perfectly on every positive component with zero misuse risk reaches 100, and the misuse penalty can pull a superficially strong model below the threshold an organization sets for action.

The weights are not universal. Formulation validity carries the highest weight because a model built on the wrong physics or the wrong decision logic cannot be rescued by later polish. Verification and validation evidence follows closely, because numerical sophistication does not prove credibility. Boundary-condition quality, uncertainty propagation, and sensitivity analysis carry substantial weight because they are the common failure points in complex technical work. Misuse risk enters as a penalty because even a strong model becomes dangerous the moment it is used outside the scope where its evidence applies.

Table 1
Engineering Model Credibility Index Components

Component Weight Technical meaning
Formulation validity (FV) 0.18 The governing equations, assumptions, and abstractions match the physical or operational problem.
Verification and validation evidence (VD) 0.16 The implementation is checked, and the model has been compared against relevant evidence.
Boundary-condition quality (BQ) 0.14 Loads, inputs, interfaces, constraints, and operating envelopes are stated and defensible.
Uncertainty propagation (UP) 0.13 Input, numerical, model-form, and measurement uncertainty are carried into the result.
Sensitivity analysis (SA) 0.12 The team knows which variables drive the outcome and where the model is fragile.
Data sufficiency (DS) 0.10 Calibration and validation data are adequate for the intended decision.
Traceability (TR) 0.09 Assumptions, versions, sources, and decision links can be audited.
Governance ownership (GO) 0.08 A qualified owner controls use, update, limitation, and retirement of the model.
Misuse risk (MU) −0.12 Penalty for likely use outside the validated range or decision scope.

Figure 1

Engineering Model Credibility Index component weights. Positive weights (navy) sum to 1.00; the misuse term (gold) enters as a penalty.

A worked illustration shows how the index disciplines a conversation. Consider a computational fluid-dynamics model proposed to justify operating a heat exchanger closer to a thermal limit. Suppose the review scores formulation validity at 85, verification and validation evidence at 55, boundary-condition quality at 60, uncertainty propagation at 40, sensitivity analysis at 50, data sufficiency at 45, traceability at 70, governance ownership at 65, and misuse risk at 60. The positive contribution is 0.18(85) + 0.16(55) + 0.14(60) + 0.13(40) + 0.12(50) + 0.10(45) + 0.09(70) + 0.08(65), which equals 15.3 + 8.8 + 8.4 + 5.2 + 6.0 + 4.5 + 6.3 + 5.2, or 59.7. The misuse penalty is 0.12(60), or 7.2, giving an EMCI of about 52.5. A model that looked authoritative in a slide deck lands in the middle of the scale, and the reason is visible: validation evidence, uncertainty propagation, and data sufficiency are weak for a decision that operates near a limit. The index does not forbid the decision; it tells the team exactly which evidence to strengthen before the decision earns its authority.

EMCI should be used as a conversation before it becomes a score. Disagreement among engineers is valuable because it exposes hidden assumptions. One analyst may believe validation is adequate because the model matched a single test. Another may know the operating regime will differ. A project manager may see traceability as paperwork; a safety engineer may see the same traceability as evidence survival after an incident. The scoring process forces those views into the same room and makes the disagreement explicit rather than letting it surface later as a surprise.

3.4 Constraint-Resolution Priority Matrix

Complex technical problems rarely fail because a single objective is difficult. They fail because objectives collide. The Constraint-Resolution Priority Matrix ranks constraints by safety criticality, irreversibility, uncertainty, time sensitivity, and cascading effect, so that scarce attention goes where violation is most consequential. A simplified composite score is written as a weighted sum whose weights again total 1.00.

CRP = 0.25·SC + 0.20·RV + 0.18·UN + 0.17·TS + 0.20·CE

SC is safety criticality, RV is irreversibility, UN is uncertainty, TS is time sensitivity, and CE is cascading effect. Higher scores demand earlier attention. The matrix is useful in crisis settings and in routine design reviews alike. During Apollo 13, power, trajectory, carbon-dioxide removal, water, thermal limits, and crew survival interacted at once. In grid operation, frequency, inertia, reserve, demand, generation mix, and weather interact continuously. In manufacturing, tolerance, throughput, quality, thermal behavior, and maintenance interact. The matrix keeps teams from treating the loudest problem as the most important one.

Table 2
Constraint-Resolution Priority Matrix

Dimension Diagnostic question Why it matters
Safety criticality (SC) Can violation cause injury, mission loss, or public harm? Safety-critical constraints cannot be negotiated like cost preferences.
Irreversibility (RV) Will a wrong action close future options? Irreversible decisions need stronger evidence and clearer authority.
Uncertainty (UN) How much is unknown about the constraint? High uncertainty can turn an apparently safe margin into a fragile assumption.
Time sensitivity (TS) Does delay change the feasible set? Some technical choices lose value once the window closes.
Cascading effect (CE) Can this constraint propagate into other subsystems? Coupled systems punish narrow fixes that ignore the coupling.

A short numerical example clarifies the ranking. In a crisis, suppose carbon-dioxide removal scores 95 on safety criticality, 70 on irreversibility, 50 on uncertainty, 90 on time sensitivity, and 60 on cascading effect, while a non-critical telemetry display scores 20, 30, 40, 30, and 25 on the same dimensions. The composite for carbon-dioxide removal is 0.25(95) + 0.20(70) + 0.18(50) + 0.17(90) + 0.20(60), which equals 23.75 + 14 + 9 + 15.3 + 12, or about 74. The telemetry display scores 0.25(20) + 0.20(30) + 0.18(40) + 0.17(30) + 0.20(25), which equals 5 + 6 + 7.2 + 5.1 + 5, or about 28. The gap is not a matter of opinion or volume; it is a structured statement that breathing air must be resolved before display cosmetics, and it survives the kind of pressure that distorts unaided judgment.

Figure 2

Constraint-Resolution Priority worked composite by dimension. Carbon-dioxide removal (74) outranks the telemetry display (28), driven chiefly by safety criticality and time sensitivity.

3.5 Reliability and Uncertainty Exposure Score

The Reliability and Uncertainty Exposure Score, abbreviated RUES, helps teams identify whether a technical system is operating with unacceptable hidden exposure. It is expressed as a weighted sum of seven components whose weights total 1.00.

RUES = 0.22·FM + 0.18·CM + 0.16·UF + 0.14·DD + 0.12·MD + 0.10·HR + 0.08·ER

FM is failure-mode severity, CM is common-cause vulnerability, UF is the uncertainty factor, DD is detectability deficit, MD is maintenance dependency, HR is human-response complexity, and ER is environmental range. A higher score signals larger exposure that calls for mitigation, more evidence, or operational restriction. The naming is deliberate. The instrument is not called a risk score because risk language is often diluted until it means nothing. Exposure emphasizes that the system carries a burden whether or not the team has chosen to notice it.

Table 3
Reliability and Uncertainty Exposure Score Components

Component Weight Technical meaning
Failure-mode severity (FM) 0.22 How damaging the consequences are if the failure mode occurs.
Common-cause vulnerability (CM) 0.18 Whether redundant elements can fail together under a shared condition.
Uncertainty factor (UF) 0.16 How poorly the failure behavior and its drivers are characterized.
Detectability deficit (DD) 0.14 How hard the failure is to detect before it causes harm.
Maintenance dependency (MD) 0.12 How strongly safe operation relies on timely, correct maintenance.
Human-response complexity (HR) 0.10 How demanding the required operator response is under stress.
Environmental range (ER) 0.08 How wide and variable the operating environment is.

Common-cause vulnerability matters because redundant components may fail together under a shared condition such as a common power supply, a shared software fault, or a single environmental insult. Detectability deficit matters because a failure mode that cannot be seen early is more dangerous than one that announces itself. Human-response complexity matters because an emergency procedure can fail when it assumes unrealistic attention, time, or training. A worked case makes the point: a redundant sensor pair sharing one power rail might score 80 on failure-mode severity, 90 on common-cause vulnerability, 60 on uncertainty, 70 on detectability deficit, 40 on maintenance dependency, 50 on human-response complexity, and 30 on environmental range, giving 0.22(80) + 0.18(90) + 0.16(60) + 0.14(70) + 0.12(40) + 0.10(50) + 0.08(30), or about 67. The high common-cause term flags that the redundancy is partly an illusion, which is precisely the exposure a component-level reliability number would have concealed.

RUES pairs naturally with reliability modeling. A component-level reliability estimate can look acceptable while system exposure stays high because the failure is hard to detect, affects multiple subsystems, or depends on hurried human interpretation. Technical managers should therefore use reliability numbers alongside failure-mode review, detectability analysis, and operational drills rather than treating a single probability as a complete safety answer. The three instruments are complementary: EMCI asks whether to trust the model, CRP asks which constraint to resolve first, and RUES asks how much the system is silently carrying.

3.6 Optimization and Sensitivity Protocol

The optimization protocol used here follows a practical sequence: define the objective, identify non-negotiable constraints, quantify uncertainty, run a baseline optimization, test sensitivity, examine boundary solutions, and compare the mathematical optimum against manufacturing, operational, and maintenance reality. The last step is the one that most often separates engineering from pure mathematics. A design can optimize a numerical objective while creating a maintenance burden, a supply-chain dependence, an inspection difficulty, or an operator confusion that the objective function never included.

Sensitivity analysis is not optional. When a result depends strongly on one poorly known parameter, the decision should shift from optimization to evidence acquisition, because buying information is worth more than refining a fragile answer. When many parameter changes push the design in the same direction, confidence improves. When the model flips its recommendation under small perturbations, leadership should not present the result as settled. The discipline is as useful for executives as for engineers, because it shows when a technical recommendation is robust and when it is a fragile artifact of assumptions that nobody has tested.

3.7 Validity, Reliability, and Ethical Safeguards

Because the three instruments are scoring tools applied by people, their own credibility must be defended. Construct validity is addressed by tying each component to a documented failure mode in the engineering literature rather than to intuition; content validity is addressed by covering formulation, evidence, uncertainty, and governance rather than any single dimension. Inter-rater reliability is supported by scoring each component independently before discussion, so that the spread of scores becomes diagnostic information rather than noise to be averaged away. The instruments are intended to be auditable: every score should carry a one-line justification that a later reviewer, or an incident investigator, can examine.

The ethical safeguard is the most important and the easiest to neglect. A scoring tool can be gamed to manufacture confidence, which would make it worse than no tool at all. The defense is to require evidence for high scores and to treat a high score with thin justification as a finding in itself. Used honestly, the instruments make optimism expensive and force teams to show their work; used dishonestly, they decorate a decision that has already been made. The difference is governance, and the recommendations in Chapter 6 exist to protect it.

3.8 Worked Integration: One Decision Through Three Lenses

The three instruments are most useful applied together to a single decision, because each answers a question the others do not. Consider a manufacturer deciding whether to certify a metal additive-manufactured bracket for a flight-critical load path on the strength of a process-and-structure simulation, rather than building the larger physical test campaign that tradition would require. The decision is attractive because the simulation is fast and the test campaign is slow and expensive, which is precisely the situation in which mathematical evidence is most likely to be over-trusted.

Running the Engineering Model Credibility Index first tells the team whether the simulation deserves to influence the certification at all. Suppose formulation validity scores 70 because the melt-pool and residual-stress physics are only partially represented, verification evidence scores 75, boundary-condition quality scores 65, uncertainty propagation scores 35, sensitivity analysis scores 45, data sufficiency scores 30 because the validation coupons do not span the build orientations of the real part, traceability scores 80, governance ownership scores 70, and misuse risk scores 70 because the model is being pushed toward a use its validation does not cover. The positive sum is 0.18(70) + 0.16(75) + 0.14(65) + 0.13(35) + 0.12(45) + 0.10(30) + 0.09(80) + 0.08(70), which equals 12.6 + 12.0 + 9.1 + 4.55 + 5.4 + 3.0 + 7.2 + 5.6, or about 59.45. The misuse penalty is 0.12(70), or 8.4, leaving an index near 51. For a flight-critical certification, that is well below any defensible threshold, and the low data-sufficiency and uncertainty-propagation terms point straight at what is missing.

The Constraint-Resolution Priority Matrix then orders what to fix. Structural integrity under fatigue loading scores high on safety criticality and irreversibility; build-orientation coverage in the validation data scores high on uncertainty; the certification deadline scores high on time sensitivity; and the possibility that an undetected residual-stress mode could affect a family of parts scores high on cascading effect. The matrix tells the team that closing the validation-data gap and characterizing the residual-stress failure mode must precede the certification decision, rather than being deferred as refinements. The Reliability and Uncertainty Exposure Score, applied to the bracket in service, then flags detectability deficit and common-cause vulnerability as the dominant exposures, because a residual-stress failure may not announce itself and may affect every part built in the same orientation. Read together, the three instruments convert a tempting shortcut into a clear, defensible programme: strengthen the validation data, characterize the dominant failure mode, and revisit the credibility index before the certification proceeds.

3.9 Calibrating the Weights for a Domain

The default weights in the three instruments are starting points, and an organization that adopts them without recalibration is misusing them in the same way it might misuse any borrowed model. A nuclear-safety case will raise the weight on failure-mode severity and verification evidence far above the defaults. A fast-moving consumer-product team will tolerate lower validation evidence for exploratory decisions while still refusing to relax safety criticality. A software-defined system will raise the weight on common-cause vulnerability because a shared code path can defeat redundancy that looks independent in hardware. The recalibration itself is a useful exercise, because the act of arguing about the weights forces a team to state what it actually values and fears, which is information worth having before a decision rather than after an incident.

A disciplined recalibration keeps each instrument’s positive weights summing to unity so that scores remain comparable across projects, documents the rationale for any departure from the defaults, and revisits the weights when the domain changes — a new regulatory regime, a new failure discovered in the field, a new class of model brought into service. The weights are not the contribution; the structured conversation they provoke is the contribution, and a frozen set of weights that nobody questions has already begun to decay into the false precision the instruments were built to resist.

3.10 Scoring Consistency and Inter-Rater Reliability

An instrument that depends on expert scoring inherits a methodological obligation that purely automatic measures avoid: it must demonstrate that different competent assessors, scoring the same model against the same evidence, arrive at compatible results. If two qualified engineers score the same model’s formulation validity at 40 and 80, the instrument is measuring the assessors rather than the model, and its outputs cannot support the auditable decisions it promises. Acknowledging this openly is part of using the instruments honestly, because the alternative — presenting a subjectively assigned score as if it carried the authority of a measurement — reproduces exactly the false precision the framework was built to resist.

Three practices keep scoring consistent enough to be useful. The first is anchored rubrics: each scoring band is tied to concrete, observable evidence, so that a score of 70 on verification evidence means a stated set of verification activities was performed and documented, not that the assessor felt reasonably confident. The second is paired scoring on consequential models, in which two assessors score independently and reconcile their differences in a recorded conversation, with the disagreement itself treated as information about where the evidence is ambiguous. The third is periodic calibration, in which a team re-scores a past model whose outcome is now known and compares its scores against what hindsight revealed, tightening the rubrics where the instrument proved optimistic. None of these practices makes the scoring objective in the sense that a length measurement is objective, but together they make it reproducible enough that the resulting decisions rest on the model rather than on the mood of the reviewer.

This is also the honest answer to the natural objection that the instruments merely dress subjective judgment in numerical clothing. The judgment is indeed subjective; the discipline lies in making it explicit, decomposed, anchored to evidence, and open to challenge, which is a categorical improvement over the unstructured and unrecorded judgment that the instruments replace. A decomposed judgment that two assessors can argue about term by term is more trustworthy than a holistic impression that no one can interrogate, and it is the structure, not a false claim of objectivity, that earns the instruments their place in a credible process.

Chapter 4: Public Case Evidence

4.1 NASA Apollo 13: Constraint Mathematics Under Crisis

Apollo 13 remains a severe case because it stripped engineering mathematics of comfort. The mission was meant to land on the Moon, but after the oxygen-tank explosion the problem changed into survival, navigation, energy management, carbon-dioxide control, and re-entry. NASA describes Apollo 13 as a mission that became a successful failure, and official mission materials describe the lunar module Aquarius being pressed into service as a lifeboat (NASA, 2020). The phrase can sound heroic; technically, it meant that a vehicle designed for one operating envelope had to be reassessed for another while three lives depended on the reassessment being right the first time.

The mathematics was not confined to a single calculation. Trajectory decisions had to return the spacecraft safely to Earth on a free-return path that the explosion had disturbed. Power budgets had to preserve enough energy for the operations that could not be skipped. Consumables had to be tracked under radically altered use. Thermal conditions had to be managed with very limited options. Carbon-dioxide removal required improvisation because the canisters intended for one module did not fit the other. Each decision narrowed or widened the feasible set, and the work became constraint management with no room for ornamental analysis. The Constraint-Resolution Priority Matrix in Chapter 3 is, in effect, an attempt to make that crisis reasoning teachable in calmer conditions.

Apollo 13 also shows why model credibility is contextual. Engineers and flight controllers did not need a perfect model of every physical detail. They needed analysis reliable enough for urgent decisions, backed by mission experience, ground simulations, test knowledge, and disciplined procedure. A slow perfect answer would have been useless and a fast careless answer would have been fatal. The achievement was not calculation alone but calibrated trust — knowing which approximations could be accepted and which constraints could not be violated under any circumstances.

For contemporary engineering management, the lesson is direct. Organizations should not wait for a crisis to learn their constraint structure. Power, thermal behavior, communications, supply, control authority, redundancy, data access, and human procedures should be mapped before they are needed. Apollo 13 is remembered as improvisation, but the improvisation was possible only because deep engineering preparation already existed; the crisis revealed the value of preparation that had been done years earlier and could not have been done in the moment.

4.2 NASA Mars 2020 and Perseverance: Navigation Between Hazards

Mars landing and rover navigation place mathematics inside a physical environment that cannot be negotiated with in real time. The communication delay between Earth and Mars rules out joystick control. The terrain is uneven. Dust, lighting, slopes, rocks, and uncertainty complicate perception. NASA’s account of terrain-relative navigation (NASA, 2021) explains how onboard imagery is matched against a stored map of the landing area to produce a map-relative position fix, allowing the descending spacecraft to retarget toward safer ground and away from hazards. That is engineering mathematics operating as autonomous judgment under time pressure measured in seconds.

The technical structure combines imaging, map matching, state estimation, guidance, and control. The system must infer where it is, compare that estimate against stored hazard maps, and adjust within a narrow landing timeline. The mathematics is impressive less because it is difficult in theory — though it is — and more because it must work inside a mission sequence where the correction window is short and the consequences are total. The estimator must be fast enough, accurate enough, and robust enough for the decision it controls, and there is no opportunity for a second attempt.

Perseverance surface navigation adds another layer. A rover crossing Martian terrain must balance science goals, energy, hazard avoidance, wheel protection, communication windows, and route efficiency at once. Research on learning-enhanced rover navigation (Daftry et al., 2022) has explored machine-learning heuristics while preserving model-based safety checks, a pattern that recurs across modern autonomy: data-driven methods may improve efficiency, but safety-critical decisions still require physics-aware guards and explicit verification. The machine learning proposes; the verified model disposes.

The case challenges a common misunderstanding about automation. Autonomy does not remove engineering responsibility; it relocates that responsibility into models, sensors, verification tests, software assurance, operational constraints, and fallback logic. Engineers remain accountable for the assumptions the autonomous system carries into a place where no one can intervene. A rover that makes a safe decision on Mars is the visible result of mathematical, software, and systems-engineering choices made long before the drive began, and the credibility of those choices is exactly what the Engineering Model Credibility Index is built to interrogate.

4.3 Great Britain’s Electricity System: Inertia, Frequency, and Operability

Power-system engineering shows that mathematics can become public service. Great Britain’s electricity system is changing as coal and gas generation decline and renewable resources expand. The National Grid Electricity System Operator’s public explanation of inertia (National Grid Electricity System Operator [NGESO], 2025b) notes that traditional coal and gas generators provide inertia as a by-product of their large spinning masses, while wind and solar do not couple to the grid in the same synchronous way. The System Operability Framework (NGESO, 2025a) takes a holistic view of the changing energy landscape to assess the requirements of future operation. Behind those plain statements sits a demanding mathematical problem: how to keep the system stable when the physical behavior of the generation fleet is itself changing.

Frequency control is not a theoretical concern. A grid must balance supply and demand second by second, and frequency is the visible signature of that balance. Inertia slows the rate of change of frequency after a disturbance; lower inertia means the system moves faster after a fault, leaving less time for corrective action. The swing equation that governs this behavior relates the rate of change of frequency to the imbalance between mechanical and electrical power divided by twice the system inertia constant, which is why a falling inertia constant directly shortens the time available to respond. The wider mathematics involves differential equations, dynamic stability, reserve sizing, probabilistic forecasting, control response, demand behavior, and contingency analysis. A secure grid is not secured against average conditions; it is secured against credible disturbances.

The low-carbon transition makes the problem technically and institutionally complex at the same time. Operators need new services, new markets, new controls, and new monitoring. Batteries, synchronous condensers, demand response, interconnectors, grid-forming inverters, and faster frequency-response services can all contribute, but each has its own technical behavior that must be modeled before it can be trusted. The system is far too large to manage by intuition. The mathematics decides how much response is needed, where it should sit, how fast it must act, and how the uncertainty in weather and demand should be carried through the decision.

The case matters because it connects engineering mathematics to public trust. Most consumers notice the grid only when it fails. They never see frequency stability, dynamic response, reserve margins, or the system studies that keep the lights on. The absence of failure is the product. Technical managers in this environment need models that are conservative enough for public reliability yet flexible enough to support decarbonization. False certainty can slow innovation; weak modeling can endanger stability. The leadership task is to hold both risks in view at once rather than collapsing into either complacency or paralysis.

4.4 NIST, ASME, and the Credibility of Computational Engineering

Computational engineering is now embedded in design, testing, certification, manufacturing, and operations, which creates a governance problem: when should a simulation be believed? Work on industrial verification, validation, and uncertainty quantification for simulation models (Raunak & Kuhn, 2021) addresses the sources of simulation inaccuracy and the procedures for assessing credibility. The verification, validation, and uncertainty-quantification resources of the American Society of Mechanical Engineers (ASME, 2024) similarly emphasize standards that help practitioners assess and improve the credibility of computational models. These frameworks are essential because modern engineering decisions increasingly depend on models too complex for casual review.

The issue is not whether simulation is useful; it is indispensable. The issue is whether simulation is being asked to do more than its evidence supports. Computational models can reduce physical testing, explore design space, and surface risks before prototypes exist. They can also mislead when mesh convergence is weak, turbulence models are unsuitable, material properties are uncertain, boundary conditions are wrong, or the validation data does not match the intended use. A colored contour plot is not a safety argument, however convincing it looks projected on a wall.

The additive-manufacturing model-validation work of the National Institute of Standards and Technology (NIST, 2024) makes the credibility problem even more current. Metal additive manufacturing involves process parameters, melt pools, thermal gradients, microstructure, residual stress, and final part properties that interact in ways still being characterized. Models can help, but only when measurement, statistical comparison, and validation datasets are strong enough to support the claim being made. This is engineering mathematics at the edge of manufacturing innovation: powerful, necessary, and dangerous when overtrusted, because the very novelty that makes the models valuable also means the validation evidence is still being assembled.

The managerial lesson is that model credibility must be budgeted like any other engineering resource. Organizations routinely fund software licenses and analyst time while underfunding validation experiments, metrology, data management, and uncertainty analysis. The economy is false. A model without credible validation may still be useful for learning, but it should not be permitted to carry certification, safety, or investment decisions as though its authority were already established. The Engineering Model Credibility Index exists partly to make that underfunding visible, because a low validation score is hard to ignore once it sits in a table next to a decision.

4.5 Cross-Case Lessons

The cases differ in technology, but the pattern is consistent. Apollo 13 required rapid constraint management under damage. Perseverance required autonomous estimation and guidance through uncertain terrain. Grid operability requires dynamic stability under changing generation physics. Computational engineering requires evidence discipline before simulation results acquire decision authority. In each setting, mathematics is valuable because it converts a confusing technical situation into controlled questions: what is conserved, what is uncertain, which constraint binds first, which model is credible, and which decision cannot wait.

The cases also warn against mathematical overconfidence. A model can be sophisticated and still wrong for the decision. A controller can be stable under nominal assumptions and dangerous under disturbance. A reliability estimate can ignore common-cause failure and report a comforting number. An optimization can land on a boundary point that cannot be manufactured, maintained, or operated safely. Engineering mathematics becomes professional only when it is paired with humility about the model’s limits, and the three diagnostic instruments are simply structured ways of enforcing that humility before a decision rather than discovering it after an incident.

4.6 Reading the Cases Through the Instruments

Applying the instruments retrospectively sharpens the lessons. An Engineering Model Credibility Index applied to the Apollo 13 trajectory work would score formulation validity and governance high, because the physics and the chain of authority were well understood, while honestly recording that data sufficiency was constrained by the damaged spacecraft. A Constraint-Resolution Priority Matrix applied to the same crisis would rank carbon-dioxide removal and trajectory above almost everything else on safety criticality and time sensitivity. A Reliability and Uncertainty Exposure Score applied to a low-inertia grid scenario would flag common-cause vulnerability and detectability deficit as the terms that deserve attention, because a fast frequency excursion gives operators little time to detect and respond.

The point of the exercise is not to re-litigate decisions made by skilled teams under real pressure. The point is to show that the instruments name, in advance and in ordinary language, the same factors that those teams managed through experience and discipline. A tool that merely re-describes good judgment is still useful, because it lets an organization extend that judgment to people and projects that have not yet earned it through years of exposure to consequence.

4.7 Structural Fatigue and the Mathematics of Slow Failure

Not every instructive failure is sudden. Some of the most consequential failures in civil and mechanical engineering are slow, accumulating invisibly through millions of load cycles until a crack reaches a critical length and the structure fails with little warning. Fatigue is the mathematics of slow failure, and it is a useful counterpoint to the crisis and autonomy cases because it shows engineering mathematics operating on a timescale of decades rather than seconds, where the danger is complacency rather than panic.

The fatigue problem is governed by the relationship between cyclic stress amplitude and the number of cycles to failure, classically captured in stress-life and strain-life curves and, for cracked components, by fracture-mechanics laws describing crack growth per cycle as a function of the stress-intensity range. The mathematics is well established, but its application is fragile because it depends on inputs that are hard to know: the true load spectrum a structure will experience, the size and location of initial defects, the material’s behavior at the relevant stress ratio, and the effect of the actual environment on crack growth. A fatigue calculation can be numerically immaculate and still wrong because the load spectrum assumed in design did not match the loads the structure met in service.

The case maps cleanly onto the three instruments. An Engineering Model Credibility Index applied to a fatigue assessment will usually find formulation validity reasonable and data sufficiency weak, because the load spectrum and the initial-defect distribution are precisely the inputs that field reality tends to violate. A Constraint-Resolution Priority Matrix will rank inspectability and irreversibility highly, because a fatigue failure can be catastrophic and a structure that cannot be inspected offers no second chance to catch a growing crack. A Reliability and Uncertainty Exposure Score will flag detectability deficit as the dominant term, since the entire danger of fatigue is that it progresses silently. The instruments do not perform the fatigue calculation; they tell the organization that the calculation’s credibility rests on inspection and load characterization, and that a design which forecloses inspection has transferred a hidden risk to whoever operates the structure for the next forty years.

The professional lesson generalizes beyond fatigue to every slow-accumulation failure mode: corrosion, creep, wear, insulation breakdown, and software entropy alike. Slow failures are dangerous because they reward neglect for a long time before they punish it suddenly, and because the people who make the design assumptions are rarely the people who inherit the consequences. Engineering mathematics serves its purpose here by keeping the long-term failure mode visible in the present-tense decision, which is the only moment at which it can be cheaply addressed.

4.8 A Counter-Case: When the Mathematics Was Right and Disregarded

The cases examined so far concern mathematics that was flawed, over-trusted, or incomplete. A complete account must also treat the opposite failure, which is in some ways more troubling: the occasions on which the analysis was substantially correct, the warning was raised, and the organization proceeded anyway. These failures are not failures of engineering mathematics at all; they are failures of the organizational pathway that connects a correct result to a decision, and they reveal that a credible analysis is necessary but not sufficient for a sound outcome.

The pattern recurs across industries with painful regularity. An engineer or a small group produces an analysis showing that a planned action carries unacceptable risk. The analysis is technically sound but inconvenient, arriving against a deadline, a budget commitment, or a management expectation already set. The result is then discounted through a familiar sequence: the uncertainty in the analysis is emphasized to weaken its authority, the burden of proof is quietly inverted so that the analyst must prove danger rather than the proponent prove safety, and the decision proceeds on the grounds that the warning was not conclusive. When the predicted failure then occurs, the subsequent inquiry frequently discovers that the mathematics had been right all along and that the institution had been organizationally incapable of acting on it.

This counter-case sharpens the purpose of the three instruments. Their value is not only to expose weak analysis but to give strong analysis a defensible structure that is harder to discount. A Constraint-Resolution Priority Matrix that ranks a hazard high on safety criticality and irreversibility creates a recorded artifact that an organization must explicitly overrule rather than quietly set aside, and a Reliability and Uncertainty Exposure Score that flags a dominant exposure converts a lone engineer’s worry into a documented institutional finding. The instruments cannot compel a decision, and they should not; engineering judgment must remain answerable to human authority. What they can do is raise the cost of ignoring a sound warning by making the warning explicit, structured, and auditable, so that disregarding it becomes a recorded choice with an owner rather than an unexamined drift. In the failures that follow ignored warnings, it is almost always the absence of that recorded ownership, rather than the absence of the warning itself, that the inquiry finds most damning.

Chapter 5: Analysis and Discussion

5.1 Complex Technical Issues Are Constraint Systems

Complex technical issues should be read first as constraint systems. Teams often begin by searching for solutions, but a solution cannot be judged until the constraint structure is understood. Safety, physics, cost, schedule, materials, environment, human action, regulation, and operational continuity together define the feasible region. The work is not glamorous. It is the discipline of discovering what cannot be wished away, and it is usually the difference between a design that survives review and one that collapses when its hidden boundaries are finally exposed.

This view changes project behavior. Instead of treating constraints as late obstacles, mature teams bring them forward. A structural analyst asks about manufacturability early. A software engineer asks about sensor uncertainty. An operations manager asks whether the procedure can be executed under stress rather than on paper. A reliability engineer asks whether redundancy is defeated by a shared environment. A financial manager asks whether a mathematically optimal design creates a lifecycle cost the programme cannot sustain. The technical problem grows clearer because its boundaries stop hiding, and the cost of discovering a constraint falls when the discovery happens during design rather than during operation.

Constraint thinking also helps in executive communication. Leaders do not need every equation. They do need to understand which constraints are binding and which assumptions control the recommendation. When technical teams present only a final result, leaders may accept a decision without grasping the margins. A mature engineering organization presents the feasible set and the binding constraints, not just the chosen point, because the chosen point means little to a decision-maker who cannot see what surrounds it.

5.2 Model Credibility Is a Management Duty

Model credibility is often treated as a specialist concern, left to analysts or simulation engineers. The delegation is a mistake. Once a model influences investment, design release, safety assessment, or operations, its credibility becomes a management duty. Leaders must know what decision the model is being used for, what evidence supports it, where it has been validated, how uncertainty was carried, and what happens if the model is wrong. None of that requires the leader to derive the equations, but all of it requires the leader to ask the right questions and to refuse comfortable answers.

The duty does not turn executives into specialists in every method. It requires them to build review systems that prevent unsupported authority. Model review boards, assumption registers, validation plans, sensitivity summaries, independent checks, and post-decision learning all belong to technical governance. In smaller organizations the same discipline can be lighter without being absent. Someone must own the question that the Engineering Model Credibility Index makes unavoidable: why do we trust this model for this decision, and what would change our mind?

The index is useful precisely because it makes that question hard to evade. When formulation validity is weak, the model is fragile at its foundation. When validation evidence is thin, the model may be exploratory rather than decisive. When boundary conditions are poor, the result may be accurate only in a world the system will never inhabit. When uncertainty propagation is missing, the precision on the screen is counterfeit. The score itself matters less than the interrogation it forces, and an organization that runs the interrogation honestly will rarely be surprised by its own models.

5.3 Optimization Can Hide Risk

Optimization is productive when constraints are complete and damaging when they are not. A design that minimizes weight may become too hard to inspect. A schedule that minimizes time may strip out the slack that testing needs. A grid dispatch that minimizes cost may erode the stability margin. A manufacturing process that maximizes throughput may raise defect risk. Every optimization is a statement about what has been valued and what has been ignored, and the ignored terms are where the risk usually hides.

The danger grows when leaders admire optimality without examining the objective function. The word optimal can shut down conversation when it should open one. What exactly was optimized? Under what assumptions? Which constraints were binding? Which variables were excluded from the objective entirely? How sensitive is the answer to the inputs nobody measured carefully? What happens when demand, load, temperature, human response, or a material property drifts outside expectation? An optimum that cannot answer those questions is a liability wearing the costume of an achievement.

In complex engineering, robust solutions are frequently better than sharp optima. A slightly heavier design with better tolerance to uncertainty may outperform a lighter design balanced on a fragile assumption. A route that is not the shortest may be the safest. A control rule that sacrifices a little nominal efficiency may preserve stability under disturbance. Mathematics should not be used to chase perfection inside a narrow model when the real system rewards resilience, and a good engineering culture treats a brittle optimum as a warning rather than a trophy.

5.4 Human Expertise Still Matters

The strongest mathematical systems still depend on human expertise. Engineers choose the abstraction, define the variables, decide what to ignore, interpret anomalies, and judge whether a result makes physical sense. Automation can accelerate analysis, but it cannot absolve the team from understanding the system. A digital twin cannot know that a sensor was mounted poorly unless the data or the governance process reveals it. An optimizer cannot know that a supplier routinely misses a tolerance unless that knowledge enters the model. A simulation cannot know that a maintenance crew will bypass an awkward procedure unless human factors are taken seriously enough to be modeled.

Human expertise is not a romantic alternative to mathematics; it is the condition that makes mathematics useful. Experienced engineers notice scale problems, boundary-condition errors, unrealistic assumptions, and operational contradictions before they become failures. Junior engineers acquire that discipline through review, testing, mentoring, and exposure to real systems with real consequences. Organizations that treat mathematical software as a substitute for engineering judgment weaken themselves quietly, because the weakness only becomes visible when a model is asked to carry a decision that judgment would have questioned.

5.5 Data Quality and Measurement Discipline

Every mathematical model depends on measurement, whether the measurements are direct sensor readings, material tests, field data, laboratory experiments, or historical failure records. Poor data quality can corrupt excellent mathematics. Missing timestamps, miscalibrated sensors, inconsistent units, biased sampling, undocumented filtering, or unrepresentative test conditions can move error quietly into the model and from there into the decision, where it is far harder to detect.

Measurement discipline is therefore not support work; it is engineering mathematics in material form. Metrology, calibration, uncertainty statements, test procedures, data lineage, and sensor validation decide whether a model has reality beneath it. NIST’s emphasis on measurement and validation in advanced manufacturing points to the same deeper truth: the credibility of a calculation is bounded by the credibility of the measurement chain that feeds it, and no amount of computational sophistication can raise that bound.

Organizations should track measurement risk with the seriousness they reserve for schedule and cost. A project that lacks validation data should not present model results as settled. A sensor network that has not been calibrated should not feed safety-critical automation without safeguards. A field dataset gathered under mild operating conditions should not be used to validate performance under extremes. Data is not evidence until its origin and its limits are known, and a model fed by unexamined data inherits every flaw the data carries.

5.6 Engineering Mathematics and Ethical Responsibility

Engineering mathematics carries ethical weight because it can authorize action. A calculation can release a design, delay a recall, approve a flight path, justify a bridge load rating, size a medical device, or determine whether a grid can operate securely. When the mathematics is weak, the consequences are rarely confined to the analyst. The public inherits the risk, usually without ever knowing a calculation was involved.

Ethical practice requires more than honest intent. It requires technical habits that make deception and self-deception harder. Assumptions should be documented. Uncertainty should be stated rather than buried. Limits should be explicit. Disagreement should be recorded rather than smoothed over. Sensitivity should be tested. Independent review should be welcomed rather than resented. A team that hides uncertainty because the answer is inconvenient is not protecting the project; it is transferring risk to people who never consented to carry it, which is the precise definition of an engineering ethics failure.

The ethical dimension also protects engineers. Technical professionals often work under schedule, budget, and leadership pressure. A clear mathematical governance process gives them language for refusing unsafe shortcuts. It lets a young analyst say that the model has not been validated for that use. It lets a project engineer point out that the optimal solution violates a hidden constraint. It lets a chief engineer delay a release until the evidence is adequate. Ethics becomes operational the moment an organization gives technical truth a place to stand, and the instruments in this work are designed to be that place.

5.7 Boundaries of the Proposed Tools

Honesty about the instruments requires naming what they cannot do. They do not measure anything in physical units; they organize expert judgment, and they are only as good as the judgment and evidence behind each score. They can be gamed by a team determined to reach a predetermined answer, and a high composite score with thin justification should be read as a warning rather than a reassurance. They do not replace domain-specific analysis — a reliability calculation, a stability study, a verification campaign — but sit on top of it, summarizing whether that analysis has been done well enough to act on. Read with those limits in mind, the tools are a structured conscience for technical decision-making. Read without them, they risk becoming the very false precision the rest of this argument warns against.

5.8 Model Risk in Data-Driven and Machine-Learning Systems

Data-driven models deserve a separate caution because their failure modes differ from those of physics-based models, and because their fluency can be mistaken for understanding. A trained model interpolates well within the distribution of its training data and can fail without warning outside it, yet nothing in its confident output signals that it has left the region where it was validated. A physics-based model that is extrapolated at least carries equations a reviewer can inspect; a data-driven model extrapolated beyond its training distribution offers no such handhold, and its error can be both large and silent.

The governance response is not to ban such models but to bound them. A data-driven component used in a safety-relevant decision should be wrapped in checks that detect when the input has drifted away from the training distribution, paired with a physics-aware guard that can override an implausible output, and monitored in service for the degradation that comes as the world moves away from the data the model learned. The Perseverance navigation pattern — machine learning proposes, verified model disposes — is the right template, and the Reliability and Uncertainty Exposure Score captures the new risk through its uncertainty-factor and detectability-deficit terms. A model whose failures are hard to detect and whose behavior outside its training set is poorly characterized scores high on exposure regardless of how impressive its in-distribution accuracy appears.

5.9 Communicating Uncertainty to Decision-Makers

A technical result is only as useful as the decision it informs, and the translation from analysis to decision is where much engineering mathematics is wasted. Decision-makers rarely need the derivation; they need to know what the result means, how confident they should be, what would change the recommendation, and what happens if the analysis is wrong. An uncertainty buried in an appendix is an uncertainty that did not inform the decision, and a recommendation presented as a single number invites a confidence the analysis may not justify.

Good communication of uncertainty is concrete rather than hedged. It states the central estimate, the range that matters for the decision, the assumptions that drive that range, and the specific evidence that would tighten it. It distinguishes between uncertainty that more analysis can reduce and uncertainty that is irreducible given the available data, because the two call for different responses — one for an investment in measurement, the other for a margin or a hedge. The sensitivity summaries recommended in Chapter 6 are the mechanism for this, and an organization that insists on them turns uncertainty from a source of either false comfort or paralysis into an ordinary input that leadership can weigh against cost and schedule like any other.

5.10 Relationship to Established Credibility Standards

Several established standards already address pieces of the problem this paper treats, and an honest account must say where the proposed instruments overlap with them and where they add something. Standards for the verification and validation of computational models specify, in considerable technical depth, how to establish that a model solves its equations correctly and represents the relevant physics adequately. Standards for model credibility assessment in high-consequence settings define maturity scales across dimensions such as verification, validation, and input pedigree. Risk-management standards prescribe how organizations should identify, analyze, and treat risk in general terms. Each of these is deeper in its own domain than the present framework attempts to be.

What the three instruments add is integration at the point of decision and accessibility to a general engineering team. The detailed standards are authoritative but heavy, owned by specialists, and applied to the model rather than to the decision the model serves; a team facing a Friday-afternoon release decision rarely has the time or the standing to invoke them in full. The credibility index borrows the verification-and-validation distinction and the input-pedigree concern from those standards and compresses them into a form a non-specialist can apply in an hour, while the priority matrix and the exposure score connect the resulting credibility judgment to consequence and to failure exposure. The relationship is therefore complementary: where a formal verification-and-validation programme exists, its results feed directly into the credibility index’s technical terms, and where one does not yet exist, the index reveals its absence as a low score rather than letting it pass unnoticed.

5.11 Threats to the Validity of the Proposed Instruments

Intellectual honesty requires naming the ways the instruments themselves can fail, because a framework that audits other people’s models must be willing to audit its own. The first threat is gaming: any scored instrument tied to a decision creates an incentive to produce the score the decision wants, and weights or rubrics can be quietly adjusted until the desired number emerges. The countermeasure is governance — separating the assessor from the advocate, recording the rationale for scores, and reviewing scores against outcomes — but no instrument can fully defend itself against an organization determined to misuse it, and pretending otherwise would be its own form of overconfidence.

The second threat is false comfort. A completed credibility index produces a tidy number, and a tidy number invites the very over-trust the paper warns against, now attached to the audit rather than to the model. The defense is to treat the score as a summary of an argument rather than a verdict, and to insist that the underlying term-by-term evidence travel with it, so that a reader can see why the number is what it is and where it is weak. The third threat is scope drift, in which instruments designed for high-consequence decisions are applied indiscriminately to trivial ones, generating bureaucratic overhead that discredits the whole approach; the implementation guidance addresses this by reserving the instruments for decisions whose stakes justify the effort. Naming these threats does not neutralize them, but it places them where a careful reader can watch for them, which is the most any framework of structured judgment can honestly offer.

5.12 Reproducibility and the Documentation Burden

A result that cannot be reproduced is a result that cannot be trusted, and reproducibility in engineering mathematics depends on documentation that is too often treated as an afterthought completed, if at all, once the interesting work is done. A computation is reproducible when another competent engineer, given the recorded inputs, assumptions, software versions, and procedures, can regenerate the result and arrive at the same answer within a stated tolerance. That standard is demanding in practice because so much of what determines a result lives in undocumented choices: a solver setting left at its default, a boundary condition adjusted late and never recorded, a data file cleaned by hand, a parameter tuned until the output looked right. Each such choice is invisible in the final number and decisive for it.

The credibility instruments depend on this documentation and also motivate it. The traceability term in the Engineering Model Credibility Index scores precisely whether the path from inputs and assumptions to outputs is recorded well enough that another engineer could follow it, and a model that cannot be reproduced cannot score well on that term no matter how sophisticated its mathematics. The discipline required is modest in any single instance — record the version, freeze the inputs, note the assumptions as they are made rather than reconstructing them later — but it is cumulatively demanding because it must be sustained when no one is asking for it. The payoff arrives at the worst moments: when a result is challenged after a failure, when a model must be revived years after its authors have left, or when a regulator asks how a number was produced. An organization that documents only when forced will find, at exactly those moments, that the record it needs was never made, and that an analysis it once trusted has become impossible to defend.

Chapter 6: Recommendations and Professional Standards

6.1 Build a Model Credibility Register

Organizations that rely on engineering models should maintain a model credibility register. The register should identify each significant model along with its owner, version, purpose, domain of validity, input sources, verification status, validation evidence, uncertainty treatment, decision scope, and retirement trigger. The practice need not become an expensive bureaucracy. Its purpose is to prevent the common failure in which a model built for one use quietly migrates into another with no review and no record of how its authority was acquired.

The register should be risk-tiered. Low-consequence design exploration can tolerate lighter documentation. Safety-critical, certification, public-infrastructure, and mission-critical models require deeper evidence. The decision scope should be explicit: a model may be approved for screening concepts but not for final design release, or approved for nominal operations but not for extreme events. Credibility is bounded, and the register keeps those bounds visible so that no one can borrow authority the evidence does not support.

6.2 Require Sensitivity Before Authority

No complex technical recommendation should gain authority without sensitivity analysis. Teams should identify which parameters drive the outcome, which assumptions are uncertain, and which changes would reverse the recommendation. The practice belongs in design reviews, safety boards, and investment decisions involving engineered systems. A result that stays stable under plausible perturbation deserves more confidence. A result that changes direction under small uncertainty should be treated as provisional regardless of how precise its central value appears.

Sensitivity summaries should be written in engineering language, not buried in a technical appendix that decision-makers never open. Leaders should see which variables matter and why. When a recommendation depends heavily on a material property that has not yet been tested, that dependence should be visible. When performance depends on an operator responding within an unrealistic time window, that should be visible. When a grid stability margin depends on particular weather and demand assumptions, that should be visible too. Sensitivity analysis is not a mathematical ornament; it is a decision safeguard, and treating it as optional is how fragile recommendations acquire undeserved authority.

6.3 Separate Exploratory, Operational, and Safety Models

A common organizational error is to treat all models as though they share the same authority. Exploratory models help teams learn. Operational models support routine decisions. Safety-critical models influence decisions where failure can cause severe consequences. The categories should not be blurred. A quick spreadsheet used to test an idea should not become a release calculation. A machine-learning forecast used for planning should not quietly become a control input. A simulation used for conceptual comparison should not be cited later as validation evidence it was never built to provide.

Classification protects both innovation and safety. Exploratory models can stay fast and flexible because they are not burdened with certification demands. Safety-critical models receive the scrutiny they deserve. Operational models are monitored for drift and degraded performance. The organization becomes more agile, not less, because it knows which evidence standard belongs to which decision and stops applying heavy process to light decisions or light process to heavy ones.

6.4 Integrate Mathematicians, Engineers, Operators, and Maintainers

Complex technical issues require several forms of knowledge that rarely live in one person. Mathematicians and analysts understand the model structure. Design engineers understand the architecture. Operators understand field behavior. Maintainers know where systems age, jam, leak, loosen, drift, or confuse their users. Safety engineers understand consequences. Project leaders understand constraints and trade-offs. A model built without these perspectives may be technically impressive and operationally naïve at the same time, and the gap between the two is where incidents are born.

Review meetings should be designed to expose mismatch rather than to perform consensus. Operators should be allowed to challenge assumptions without penalty. Maintainers should be asked whether an optimized design can actually be inspected and repaired. Analysts should explain uncertainty in plain technical terms rather than hiding behind notation. Managers should state which decision they expect the model to support. Cross-disciplinary review is not inefficiency; it is how complex systems defend themselves against the narrow expertise that any single discipline brings.

6.5 Use Public Case Learning Without Mythology

Organizations should use cases such as Apollo 13, Perseverance, grid operability, and computational verification as learning material while avoiding the mythology that grows around them. Apollo 13 was not saved by inspirational culture alone; it was saved by technical preparation, disciplined procedures, mathematics, deep mission knowledge, and calm execution under pressure. Perseverance navigation is not magic autonomy; it is a chain of estimation, mapping, hazard logic, and verification. Grid stability is not a political slogan; it is dynamic-systems engineering under changing physics. Verification and validation are not paperwork; they are the credibility system behind computational decisions. Mythology flatters; engineering learns.

6.6 Reform Professional Education

Engineering education should treat applied mathematics as a professional reasoning discipline rather than a sequence of solved problems. Students should still learn calculus, differential equations, linear algebra, probability, optimization, statistics, numerical methods, and control theory. They should also learn when those tools fail, how uncertainty enters a problem, how an assumption becomes dangerous, how validation evidence is actually built, and how a technical recommendation is communicated to people who will never see the equations. Mathematics taught without failure literacy is incomplete preparation for a profession whose errors are paid for by the public.

6.7 Adopt the Instruments as Living Practice

The three instruments in this work should be adopted as living practice rather than as one-time checklists. An Engineering Model Credibility Index recorded at design release and revisited when the operating environment changes will catch the silent migration of authority that the credibility register is meant to prevent. A Constraint-Resolution Priority Matrix rehearsed in calm conditions builds the muscle that a crisis later demands. A Reliability and Uncertainty Exposure Score tracked over a system’s life reveals exposure that creeps in through aging, modification, and changing use. The weights should be recalibrated by each organization for its own domain, and the justifications behind each score should be retained so that the instruments leave an audit trail an investigator could follow. Used this way, the tools become part of how an organization thinks, not a form it fills in to satisfy a reviewer.

6.8 An Implementation Roadmap

Adopting these practices in an organization that does not yet have them is itself a project with constraints, and treating the adoption as a flip of a switch is a reliable way to ensure it fails. A workable sequence begins by establishing the model credibility register for the handful of models that already carry the highest-consequence decisions, rather than attempting to catalogue every spreadsheet at once. With those models documented, the credibility index can be applied at the next natural decision point for each, which surfaces the weakest evidence without disrupting work that is already in flight. The constraint-priority matrix and the exposure score follow naturally once teams have seen the credibility index pay for itself, because by then the value of structuring judgment is no longer an abstract claim.

The cultural conditions matter as much as the procedural ones. The instruments only work where a low score can be reported without career penalty, where a maintainer can challenge an analyst without being dismissed, and where leadership treats a delayed release backed by honest evidence as a success rather than a failure of nerve. An organization that punishes the messenger will quickly find its scores drifting upward toward whatever the decision already wanted, at which point the instruments have become decoration. The roadmap therefore ends where it began: the tools are a structured conscience, and a conscience requires an organization that wants to hear it.

6.9 Competence, Training, and the Human Prerequisite

The instruments presume a level of engineering competence that cannot be assumed into existence, and any honest implementation plan must address the human prerequisite directly. A credibility index scored by someone who does not understand the difference between verification and validation will produce numbers, but the numbers will be noise dressed as signal. The framework does not lower the competence required to do credible engineering; it organizes and makes visible the judgment of people who already have it, and it is actively dangerous in the hands of people who do not, because it can lend an unearned appearance of rigor to an uninformed assessment.

This implies that adoption must be paired with development of the underlying judgment, through the kinds of measures that build engineering maturity in any organization: mentoring that pairs less experienced engineers with those who have seen failures firsthand, structured review of past decisions including the ones that went wrong, and a deliberate practice of articulating the assumptions behind a model rather than absorbing them tacitly. The scoring rubrics can themselves serve as teaching instruments, because a junior engineer who must justify a verification-evidence score learns what verification evidence actually consists of. The framework is in this sense a scaffold for developing judgment as well as a means of recording it, and an organization that treats it purely as a compliance exercise will get compliance rather than competence.

6.10 The Cost of Credibility and How to Justify It

Every practice recommended here costs time, and an argument that ignored cost would be exactly the kind of one-sided analysis the paper criticizes. Convergence studies consume computer time and engineer attention. Uncertainty propagation is more expensive than pushing a mean through a model. Maintaining a credibility register and scoring models against it is overhead that produces no product directly. A team under schedule pressure will reasonably ask what all of this buys, and the answer must be honest about the fact that, on any individual decision, the disciplined approach will often confirm what the quick approach already suggested, at greater cost.

The justification is not found in the average case but in the tail. The cost of credibility is paid steadily and visibly; the cost of its absence is paid rarely but catastrophically, in the failures that destroy hardware, careers, and lives, and that on inquiry are traced to an over-trusted model or an ignored warning. The economics are those of insurance, and they are easy to resent precisely because, when the discipline works, nothing happens and the premium looks wasted. An organization that understands this will scale the rigor to the consequence — spending little on reversible, low-stakes decisions and a great deal on irreversible, high-stakes ones — which is exactly the proportioning the Constraint-Resolution Priority Matrix is designed to make explicit. Credibility is not free, and the framework’s purpose is not to maximize it everywhere but to invest it where the consequences justify the premium and to withhold it where they do not.

Chapter 7: Conclusion

Engineering mathematics solves complex technical issues when it stays loyal to physical consequence. Its value is not the appearance of precision, the complexity of the software, or the elegance of the equations. Its value lies in clarifying the feasible set, naming uncertainty, testing margins, exposing fragile assumptions, and guiding action when intuition cannot hold the full system in view. The public case evidence assembled here shows the discipline working across radically different settings — spacecraft crisis response, planetary navigation, electricity-system stability, and computational model credibility — with the same underlying logic in each.

The central professional lesson is that mathematical analysis must earn its decision authority rather than inherit it. A model should not be trusted because it is advanced; it should be trusted because its formulation, evidence, boundaries, uncertainty treatment, and governance match the decision being made. An optimized answer should not be accepted because it is optimal; it should be accepted only after the team understands what was optimized, what was constrained, and what was left outside the objective function. A reliability claim should not stand because the probability is small; it should stand only after failure modes, common causes, detectability, human response, and operating environment have been examined honestly.

Complex systems are becoming more coupled, more digital, more automated, and more dependent on models. That trend raises both the value of engineering mathematics and the danger of misusing it. The answer is not less mathematics; it is more disciplined mathematics — better verification, better validation, better uncertainty communication, better sensitivity analysis, better model governance, and better integration of human expertise. Technical organizations that build those habits will make stronger decisions under pressure. Those that confuse computation with credibility will stay vulnerable even when their dashboards look modern and their slide decks look certain.

7.1 Limitations of the Present Work

The framework advanced here carries limitations that bound its claims and that further work would need to address. It has been developed and illustrated through reasoned analysis and through documented engineering cases drawn from the public record, rather than validated through controlled deployment across many organizations; the evidence that the instruments improve decisions is therefore argumentative and illustrative rather than empirical. The scoring rubrics, while anchored to observable evidence, have not been subjected to a formal inter-rater reliability study of the kind a mature instrument eventually requires, and the default weights, though constructed to be defensible, have not been calibrated against a large body of outcomes. These are limitations of maturity rather than of principle, but they are real, and a reader should weigh the framework as a structured proposal supported by reasoning and precedent rather than as an empirically established result.

A further limitation concerns generality. The instruments were shaped by problems in which physical consequence and model credibility are the dominant concerns — aerospace, civil, mechanical, and energy systems among them. Their transfer to domains with different risk structures, such as financial modeling, epidemiological forecasting, or large-scale software, is plausible and partly argued here, but it is not demonstrated, and each such domain carries failure modes the present treatment may underweight. The framework should be read as offering a transferable structure of thought rather than a finished instrument ready for any field, and its adoption in a new domain should begin with the recalibration the methodology itself prescribes.

7.2 Directions for Future Work

Several lines of work would strengthen the framework materially. The most important is empirical validation: applying the instruments prospectively across a portfolio of real decisions and tracking, over time, whether decisions made with them produce better-calibrated outcomes than decisions made without them. Such a study would also yield the data needed to calibrate the weights against outcomes rather than against reasoning, and to establish the inter-rater reliability of the scoring rubrics under realistic conditions. A second line of work would develop domain-specific instantiations, in which the general structure is specialized to the failure modes and regulatory context of a particular field, with weights and rubrics tuned accordingly and tested against that field’s own history of success and failure.

A third direction concerns integration with the tools engineers already use. The instruments will be adopted in proportion to how little friction they add, and embedding the credibility register in existing model-management and configuration-control systems, rather than maintaining it as a separate document, would lower that friction substantially. A fourth direction concerns the data-driven systems treated in Chapter 5, whose distinctive failure modes — silent extrapolation, distributional drift, and opacity — deserve instruments of their own that extend the exposure score with terms specific to learned models. Each of these directions shares a premise with the paper as a whole: that the goal is not a more elaborate theory of credibility but a more reliable practice of it, and that the measure of success is whether engineers in the room where decisions are made reach for these instruments and are better for having done so.

Taken together, these directions describe a research programme rather than a finished result, and that framing is deliberate. The instruments offered here are meant to be used, criticized, and revised in contact with real decisions, and the most valuable contribution this work can make is not to settle the question of model credibility but to give a working community a shared and improvable structure for arguing about it. A framework that is adopted, tested against experience, and amended where it fails will, over time, become something more trustworthy than any single author could specify in advance — which is, in the end, the same standard of accumulated and audited evidence that the paper asks engineers to apply to their models.

The final judgment is practical. Engineering mathematics is one of the strongest safeguards available to a technical organization, but only when it is handled as evidence rather than decoration. It should make decisions harder to fake, assumptions harder to hide, and risks harder to transfer silently to operators, users, and the public. The three instruments offered here — a credibility index, a constraint-priority matrix, and an exposure score — are small contributions to that larger obligation, and they succeed only to the extent that they make honesty easier and false confidence more expensive. That is the professional obligation of the discipline, and meeting it is the work.

References

American Institute of Aeronautics and Astronautics. (1998). Guide for the verification and validation of computational fluid dynamics simulations (AIAA G-077-1998). AIAA.

American Society of Mechanical Engineers. (2006). Guide for verification and validation in computational solid mechanics (ASME V&V 10-2006). ASME.

American Society of Mechanical Engineers. (2009). Standard for verification and validation in computational fluid dynamics and heat transfer (ASME V&V 20-2009). ASME.

American Society of Mechanical Engineers. (2024). VVUQ standards: Verification and validation resource hub. ASME. https://www.asme.org/codes-standards/vvuq-standards

Daftry, S., Abcouwer, N., Del Sesto, T., Venkatraman, S., Igel, L., Byon, A., Rosolia, U., Yue, Y., & Ono, M. (2022). MLNav: Learning to safely navigate on Martian terrains. arXiv. https://arxiv.org/abs/2203.04563

Kalman, R. E. (1960). A new approach to linear filtering and prediction problems. Journal of Basic Engineering, 82(1), 35–45. https://doi.org/10.1115/1.3662552

National Aeronautics and Space Administration. (2016). NASA systems engineering handbook (NASA/SP-2016-6105 Rev2). NASA. https://www.nasa.gov/wp-content/uploads/2018/09/nasa_systems_engineering_handbook_0.pdf

National Aeronautics and Space Administration. (2020). Apollo 13: The successful failure. NASA. https://www.nasa.gov/missions/apollo/apollo-13-the-successful-failure/

National Aeronautics and Space Administration. (2021). Terrain-relative navigation: Landing between the hazards. NASA. https://science.nasa.gov/science-research/science-enabling-technology/technology-highlights/terrain-relative-navigation-landing-between-the-hazards/

National Grid Electricity System Operator. (2025a). System Operability Framework. National Energy System Operator. https://www.neso.energy/publications/system-operability-framework-sof

National Grid Electricity System Operator. (2025b). What is inertia? National Energy System Operator. https://www.neso.energy/energy-101/electricity-explained/how-do-we-balance-grid/what-inertia

National Institute of Standards and Technology. (2024). Metrology for additive manufacturing model validation. NIST. https://www.nist.gov/programs-projects/metrology-am-model-validation

Oberkampf, W. L., & Roy, C. J. (2010). Verification and validation in scientific computing. Cambridge University Press. https://doi.org/10.1017/CBO9780511760396

Rasmussen, J. (1997). Risk management in a dynamic society: A modelling problem. Safety Science, 27(2–3), 183–213. https://doi.org/10.1016/S0925-7535(97)00052-0

Raunak, M. S., & Kuhn, D. R. (2021). Metamorphic testing on the continuum of verification and validation of simulation models. National Institute of Standards and Technology.

Reason, J. (1997). Managing the risks of organizational accidents. Ashgate.

Roache, P. J. (1998). Verification and validation in computational science and engineering. Hermosa Publishers.

Roy, C. J. (2005). Review of code and solution verification procedures for computational simulation. Journal of Computational Physics, 205(1), 131–156. https://doi.org/10.1016/j.jcp.2004.10.036

Yeo, D. H. (2020). A summary of industrial verification, validation, and uncertainty quantification procedures in computational fluid dynamics (NIST Technical Note). National Institute of Standards and Technology.

The Thinkers’ Review
Prince-Bonaventure Chiemeze

Healthcare Practice and Strategic Management in Barbados

A Postgraduate Diploma Case Study of Continuity, Hospital Flow, Prevention, and Health System Resilience


By Prince-Bonaventure Chiemeze Virtue

New York Center for Advanced Research (NYCAR)

Postgraduate Diploma Research Publication

Publication No.:  NYCAR-TTR-2026-RP065

DOI: https://doi.org/10.5281/zenodo.20706926

June 2026


Copyright © June 2026 New York Center for Advanced Research (NYCAR) and Prince-Bonaventure Chiemeze Virtue. All rights reserved.

Peer Review and Publication Status

This postgraduate diploma research publication by Prince-Bonaventure Chiemeze Virtue has passed NYCAR internal academic review and independent professional review for applied postgraduate research. The review examined the clarity of the problem, the strength of the case logic, the discipline of the evidence base, APA citation practice, methodological coherence, paragraph rhythm, and the practical value of the work for health and social care leadership.

The reviewers found that the publication meets the expected postgraduate diploma standard because it works from public evidence, keeps the argument close to practice, and avoids inflated claims. Its strongest value is the conversion of national and regional health evidence into management routines that can be used by administrators, nurses, service leaders, planners, and policy teams.

The work is accepted as a publication-ready NYCAR research output after editorial correction. Its conclusions should be read as applied professional judgment grounded in traceable evidence, not as a substitute for local audits, ministry directives, clinical protocols, or institutional policy decisions. Final publication number and DOI can be inserted by the issuing office when assigned.

Abstract

Barbados is a hard case for healthcare management because its scale leaves little room for hidden failure. A weak referral, a late diagnostic result, a medicine change that is not explained, a discharge note that stops at the hospital door, or a clinic recall that loses the patient does not remain a minor administrative defect for long. It becomes visible in family anxiety, repeated attendance, avoidable delay, professional frustration, and public trust. The clinical act can be competent while the care pathway fails around it. Continuity is therefore not a soft service value in Barbados. It is the operating test of whether the health system can hold the patient safely across time, setting, and responsibility.

The Queen Elizabeth Hospital sits at the center of that test. Its acute-care role links emergency pressure, ward flow, diagnostics, workforce readiness, discharge planning, digital administration, medicine reliability, community follow-up, and national resilience. The evidence base used here comes from Barbados health reporting, PAHO country material, the QEH Strategy 2025-2028, UNOPS-supported hospital strengthening, and the Bridgetown Declaration on NCDs and Mental Health. These sources are not treated as if they reveal private hospital performance. They are read as public evidence of the managerial conditions under which continuity either holds or breaks.

The research develops a Strategic Health Continuity Model for postgraduate professional use. The model connects primary care, hospital flow, workforce capacity, diagnostic and medicine reliability, information transfer, community trust, and climate-health exposure. It does not rank institutions. It does not pretend that a score can capture the full movement of a patient through care. Its value is sharper and more practical: it forces managers to locate the weak handoff, identify the evidence, assign repair, and check whether the patient actually experiences the correction. The central claim is blunt. Barbados will not strengthen healthcare by imitating the scale of larger systems. It will strengthen healthcare by protecting the small routines that keep people connected before, during, and after treatment.

Keywords: healthcare practice, strategic management, Barbados, Queen Elizabeth Hospital, primary care, NCD prevention, patient flow, health resilience, postgraduate diploma, NYCAR

Table of Contents

Peer Review and Publication Status 2

Abstract 3

List of Tables 6

Chapter 1: Barbados as a Test of Strategic Healthcare Practice 7

1.1 Why Barbados Is a Serious Management Case 7

1.2 The Central Research Problem 7

Chapter 2: Health System Context and Evidence Base 10

2.1 Public Evidence and National Priorities 10

2.2 Hospital Centrality and Primary Care 10

Chapter 3: Methodology and Strategic Health Continuity Model 13

3.1 Applied Case-Study Method 13

3.2 Diagnostic Model 14

Chapter 4: The Queen Elizabeth Hospital as a Strategic Case 17

4.1 Hospital Strategy and National Service Role 17

4.2 Patient Flow and Improvement Discipline 17

Chapter 5: Primary Care, Pharmacy, and NCD Prevention 20

5.1 Prevention as Operating Discipline 20

5.2 Medicines and Diagnostics 20

Chapter 6: Workforce, Digital Administration, and Patient Experience 23

6.1 Workforce as Service Capacity 23

6.2 Digital Readiness and Patient Trust 23

Chapter 7: Finance, Climate Resilience, and Strategic Risk 26

7.1 Finance as Service Design 26

7.2 Climate-Health Readiness 26

Chapter 8: Applied Strategic Health Continuity Model 29

8.1 Model Use 29

8.2 Management Interpretation 29

Chapter 9: Implementation Plan 33

9.1 Turning Strategy Into Routines 33

9.2 Governance and Monitoring 33

Chapter 10: Final Quality Review and Professional Position 37

10.1 Quality Check 37

10.2 Final Position 37

10.3 Final Professional Position and Readiness for Use 45

References 49

List of Tables

Table 1. Strategic Health Continuity Model scoring logic

Table 2. Priority actions for strategic healthcare management in Barbados

Chapter 1: Barbados as a Test of Strategic Healthcare Practice

1.1 Why Barbados Is a Serious Management Case

Barbados offers a compact but demanding case for health care practice and strategic management. Its population size makes coordination visible in a way that large systems can sometimes hide. When a hospital bed is unavailable, when a diagnostic queue lengthens, when a medicine supply line slows, or when a chronic-disease follow-up is missed, the effect travels quickly through the system. Patients and families do not experience those issues as separate departments. They experience them as one service that either knows how to carry care or loses them between points.

The country’s health challenge is not only access. It is continuity. Barbados has public institutions with credibility, trained professionals, and a defined national health structure. Yet the pressure created by ageing, noncommunicable disease, hospital flow, workforce demand, and climate exposure requires a form of management that is more connected than ordinary administration. A small health system cannot afford preventable duplication, weak data handoff, or isolated planning. Every routine has strategic meaning.

PAHO’s Barbados country profile places older adults at 16.6 percent of the population in 2024, a figure that matters for service planning because older populations require repeated contact, medicine management, rehabilitation, home support, and careful discharge arrangements. The Barbados Health Report 2023 also keeps prevention at the center by noting that noncommunicable diseases account for most of the leading causes of death. Together, those facts explain why strategic management must be close to patient pathways rather than limited to institutional planning.

1.2 The Central Research Problem

Healthcare practice becomes strategic when leaders ask how the ordinary parts of care connect. A diabetes review is not only a clinic visit. It depends on records, laboratory access, medication supply, patient education, transport, appointment recall, and family support. A hospital discharge is not only a bed-management decision. It depends on medicines, follow-up, home conditions, primary care communication, and patient understanding. The manager who sees these links is closer to the real system.

The postgraduate diploma level of this work is deliberately applied. It does not try to prove a grand theory from private records. It asks whether publicly available evidence can be organized into usable professional judgment. That is a serious standard. Health systems often fail not because leaders lack vocabulary, but because the same problem is seen by several units and owned by none.

The central problem addressed here is therefore straightforward: Barbados needs health management routines that protect continuity across hospital care, primary care, public health, pharmacy, diagnostics, workforce planning, information systems, and patient experience. The case is not presented as failure. It is presented as a serious setting where strategic discipline can make a strong system more reliable under pressure.

The research problem is therefore not a search for fashionable reform language. It is a service question: can the system keep a person connected through prevention, acute care, medicines, information, family support, and return to community life? When that question leads the analysis, the publication stays practical and avoids the habit of treating strategy as a set of attractive words.

A Barbados health manager also has to respect scale. In a compact system, personal familiarity can help coordination, yet it can also hide responsibility when processes are informal. A clear pathway protects both the patient and the professional because it shows where the next decision belongs. Written ownership, short review cycles, and simple escalation rules can keep human closeness from becoming administrative invisibility.

For postgraduate diploma work, the right level of analysis is applied judgment. The publication does not claim access to private service files. It reads public evidence with discipline and uses that evidence to frame professional questions. That approach is suitable because many managers have to make useful decisions from incomplete information while still respecting the limits of what the evidence can prove.

The Barbados context also warns against a narrow reading of performance. A hospital can increase activity and still leave patients exposed if handoffs remain weak. A clinic can provide appointments and still miss the patient who needed recall. A pharmacy can stock medicines and still fail if instructions are not understood. The management test is not activity alone; it is whether the chain of care holds.

Continuity should therefore be treated as a practical discipline. It begins with the patient pathway and asks what must happen before the next professional can act safely. That question connects the clinic, laboratory, pharmacy, hospital ward, finance office, data team, and family carer. The value of strategy lies in making those connections explicit enough to be owned.

The Barbados case is valuable because it makes management failure visible without requiring a large geography. A referral that is not tracked, a medicine that is not ready, a discharge that is poorly explained, or a clinic review that is missed can travel through the system quickly. The lesson for managers is that small systems need sharper coordination, not lighter governance.

Chapter 2: Health System Context and Evidence Base

2.1 Public Evidence and National Priorities

The evidence base for this publication is public and traceable. It includes the Barbados Health Report 2023, PAHO country material, the Queen Elizabeth Hospital Strategy 2025-2028, the UNOPS hospital improvement project, WHO and PAHO material on small-island health priorities, and regional evidence on noncommunicable disease and climate-health resilience. Those sources do not reveal every internal operational detail, but they are sufficient to support a professional management analysis.

Barbados’ health system sits inside a wider Caribbean reality: disease patterns are shifting, costs are rising, populations are ageing, and climate events can disrupt essential services. The strategic question is not whether the country should care about prevention or hospital improvement. That is already clear. The question is how leaders make prevention, hospital flow, staffing, and public trust work together in daily operations.

The Queen Elizabeth Hospital occupies a central position. UNOPS describes QEH as a 550-bed national anchor providing 94 percent of Barbados’ hospital beds and serving as a referral center for Eastern Caribbean countries. That role gives the hospital strategic weight beyond its walls. A delay or quality problem at QEH affects the country’s whole health system, not only one institution.

2.2 Hospital Centrality and Primary Care

Primary care is the other side of the same equation. A hospital-centered system will remain under pressure if chronic disease follow-up, screening, medicine continuity, early risk identification, and patient education are weak. Primary care does not only reduce hospital demand. It protects patients before their conditions become emergencies. For Barbados, the practical task is to make hospital and primary care behave like one managed pathway.

The country’s NCD profile demands this connection. Diseases such as cardiovascular illness, diabetes, cancer, and respiratory conditions require regular checks, lifestyle support, medication access, laboratory monitoring, and trusted communication. A strategy that waits for hospital crises misses the quieter work where harm can be prevented.

Public evidence also shows the importance of resilience. Barbados’ Health National Adaptation Plan process, described by PAHO as a roadmap for strengthening services and supporting essential care under climate stress, places health management in a wider environment. A clinic, hospital, pharmacy, or public health team must continue functioning when heat, storms, supply issues, or infrastructure disruption tests the system.

The method accepts that professional research can be useful without private fieldwork when the question is framed properly. The task is not to expose confidential weaknesses. The task is to read public material, connect it to known service realities, and build a model that managers can test with their own data. That keeps the work ethical, modest, and useful.

The evidence base also has to be read with an understanding of institutional role. A national strategy document tells leaders what the institution values and intends to pursue. A health report shows broad pressures and selected indicators. A project announcement identifies investment priorities. None of these sources should be exaggerated, yet together they allow a careful reader to see the management agenda clearly enough for postgraduate analysis.

Climate-health evidence widens the management lens. Heat, storms, infrastructure strain, water interruption, and supply-chain delay can all disrupt care. The Health National Adaptation Plan process shows that resilience belongs inside health-sector planning, not only emergency response. The practical question for managers is whether essential care can continue when normal conditions are disturbed (PAHO, 2025).

Primary care remains equally important because the disease burden is not solved inside the hospital alone. Hypertension, diabetes, cancer risk, respiratory disease, frailty, mental health distress, and medicine adherence all require repeated attention. The country’s health strategy has to protect routine contact before deterioration becomes an emergency.

The national role of QEH gives the evidence special weight. When one acute-care institution carries such a large share of hospital capacity, hospital flow becomes a whole-system issue. Pressure in emergency care, diagnostics, beds, discharge, or specialist access cannot be treated as a local inconvenience. It affects primary care, families, transport, pharmacy, and public confidence.

Public evidence has to be handled with restraint. The Barbados Health Report 2023, PAHO material, QEH strategy documents, UNOPS project information, and WHO material on small-island health priorities show the policy and institutional setting, but they do not reveal every operational delay or patient experience. The analysis treats those sources as a basis for professional review rather than as a full service audit (Ministry of Health and Wellness, 2024; Pan American Health Organization [PAHO], 2024).

A continuity approach is especially useful because it makes the patient pathway easier to audit. Leaders can ask whether the patient was identified, reviewed, referred, treated, discharged, supplied, informed, and followed. Each verb points to an observable action. Where the action is missing, the problem is no longer hidden inside broad policy language. It becomes a management task with an owner and a review date.

The Barbados case also shows why prevention cannot be treated as a campaign that appears only during public-awareness periods. Prevention is a working routine: records updated, risk registers maintained, abnormal results chased, medicines reconciled, missed appointments followed, and families supported. When those routines are protected, the health system reduces avoidable pressure on the hospital before pressure becomes visible.

Chapter 3: Methodology and Strategic Health Continuity Model

3.1 Applied Case-Study Method

The analysis uses an applied case-study method suited to postgraduate diploma research. The method reads public evidence through management questions rather than through abstract theory. It asks what Barbados’ health evidence tells leaders about continuity, risk, resource use, patient safety, and service coordination. The approach is practical because the intended reader is a health manager, administrator, supervisor, or policy learner who needs usable judgment.

The analysis avoids unsupported claims. It does not invent patient-level data, private interviews, or internal hospital figures. Public sources are read carefully and their limits are respected. Official reports show strategy, priorities, and selected indicators. They do not show every bedside delay, every staff conversation, or every patient experience. Professional analysis must therefore use public evidence without pretending it is complete.

The Strategic Health Continuity Model developed here uses six dimensions: primary care continuity, hospital flow, workforce readiness, medicine and diagnostic reliability, information readiness, and resilience governance. These dimensions are chosen because they describe where a patient is most likely to lose continuity. The model does not replace local audit. It gives leaders a disciplined way to discuss weak points.


Table 1

Strategic Health Continuity Model Scoring Logic

Dimension Weight Management meaning
Primary care continuity 0.20 Risk registers, recall, prevention, and chronic care follow-up.
Hospital flow 0.20 Safe movement through emergency, inpatient, diagnostic, discharge, and follow-up stages.
Workforce readiness 0.18 Staffing, supervision, skill mix, morale, and professional development.
Medicines and diagnostics 0.17 Reliability of treatment inputs, test access, and supply continuity.
Information readiness 0.13 Records, dashboards, patient tracking, referral completion, and data use.
Resilience governance 0.12 Continuity under climate, fiscal, infrastructure, and emergency pressure.


3.2 Diagnostic Model

Primary care continuity asks whether routine risks are being found and followed before emergency care becomes necessary. Hospital flow asks whether patients move safely through assessment, treatment, admission, discharge, and follow-up. Workforce readiness asks whether enough skilled people are available, supervised, and protected from exhaustion. Medicine and diagnostic reliability asks whether treatment decisions can be carried out in practice. Information readiness asks whether the system knows what it needs to know. Resilience governance asks whether essential care can continue under stress.

The model can be scored locally on a zero-to-five scale for each dimension, but the score is less important than the conversation it forces. A low score should not be used to shame a department. It should trigger a management question: what evidence is missing, what action is needed, who owns the next step, and when will improvement be checked?

This is why strategic health management belongs at the postgraduate diploma level. The learner is expected not only to describe health-system pressure but to convert evidence into professional action. The model does that by making continuity the central management test.

The weighting also encourages balance. A system that speaks only about hospital flow can miss the clinic weakness that sends patients back into crisis. A system that speaks only about prevention can miss the diagnostic delay that blocks action. The model keeps the whole chain in view so that improvement does not become narrow.

A practical scoring meeting should begin with a short case narrative rather than a spreadsheet. Managers should describe a real patient pathway in plain language, then ask where the delay, confusion, or risk appeared. Numbers can then help the team compare dimensions, but the human sequence keeps the review grounded in service experience.

The model is strongest when used by a mixed group rather than a single office. Nurses, administrators, physicians, pharmacists, finance staff, ICT workers, community health teams, and patient-experience officers see different parts of the pathway. A useful review brings those views together and asks where the patient is most likely to be lost.

The score should never become a public label attached to a unit or institution. Its purpose is review. A low score should open a conversation about causes, ownership, timing, and repair. A high score should not end the discussion either, because continuity can weaken when staffing, climate, procurement, or demand conditions change.

The zero-to-five scoring scale should be used with evidence, not instinct. A manager assigning a score should identify the documents, data, complaints, audit findings, or service observations that support the score. Where evidence is missing, the weakness should be named. Missing evidence is itself a management finding because leaders cannot improve what they cannot see.

The model’s six dimensions are weighted to reflect management importance rather than statistical certainty. Primary care continuity and hospital flow carry strong weight because they shape whether patients remain connected before and after acute care. Workforce readiness, medicines and diagnostics, information readiness, and resilience governance then show whether the pathway can operate under pressure.

The weighting is arithmetically balanced: 0.20 + 0.20 + 0.18 + 0.17 + 0.13 + 0.12 = 1.00. A local continuity score should multiply each dimension rating by its weight and sum the results. The result is a review prompt, not a public ranking.


Figure 1

Strategic Health Continuity Model


Note. Each dimension is rated on a zero-to-five scale and multiplied by its weight; the weighted sum is a review prompt for managers, not a public ranking of institutions.


The method is deliberately case-based because the case allows the reader to see how policy language becomes operational responsibility. The Queen Elizabeth Hospital is not used as a target for criticism; it is used because its role makes the links between hospital flow, workforce, technology, infrastructure, finance, and public trust easier to examine.

Chapter 4: The Queen Elizabeth Hospital as a Strategic Case

4.1 Hospital Strategy and National Service Role

QEH is not simply one hospital among many. In Barbados it is the national acute-care anchor, a teaching and research institution, and a regional referral point. Its strategy therefore has national meaning. The QEH Strategy 2025-2028 emphasizes safe, effective, responsive, caring, and well-led patient-centered services. That language is valuable because it gives managers a quality standard that can be translated into team goals, patient-flow reviews, and accountability routines.

A hospital strategy becomes serious only when it changes daily practice. If “safe” is a value, then medication reconciliation, infection prevention, staffing review, escalation, and incident learning must be visible. If “responsive” is a value, then waiting times, bed availability, diagnostics, and discharge communication must be reviewed honestly. If “well-led” is a value, then teams need the authority and evidence to solve problems rather than simply report them.

The UNOPS-supported improvement project at QEH shows the scale of practical modernization. Public material describes investments in waste management, morgue ventilation, ICT equipment, and digitization, with a budget above USD 16.5 million and implementation through a 30-month period. Those details matter because hospital strategy is not only clinical. It includes infrastructure, digital systems, environmental management, and administrative reliability.

4.2 Patient Flow and Improvement Discipline

Patient flow is one of the hardest strategic problems in hospital care because it depends on many units at once. Emergency demand, inpatient beds, theatre scheduling, diagnostics, discharge planning, social support, and community follow-up all shape the same pathway. A hospital manager who tries to solve flow in one department alone will not solve the real problem.

QEH’s strategic attention to waiting times, bed optimization, diagnostics, elderly care, and service improvement should be read as one connected agenda. Older patients often need more careful discharge planning, medicines review, mobility support, and family communication. A faster discharge that is not understood by the patient can become a readmission. A delayed discharge can protect one decision while weakening the patient through immobility and frustration.

In this case, strategic management means protecting the link between clinical quality and operational movement. Barbados cannot afford a hospital system where the patient is technically treated but administratively lost. The stronger standard is continuity: the patient should know what happened, what comes next, who is responsible, and where to return if the plan fails.

That is why the hospital case must be handled carefully. The publication does not reduce QEH to waiting times or bed numbers. It treats the hospital as a strategic node where workforce, infrastructure, digital systems, clinical judgment, public communication, and community follow-up meet. The stronger the connections around that node, the more resilient the wider system becomes.

The hospital also carries a symbolic burden. In many countries the main public hospital becomes the place where citizens judge the seriousness of government health commitment. Barbados is no different in that respect. A well-led QEH can strengthen confidence across the health system, while unmanaged bottlenecks can make national strategy feel distant from lived experience.

The strategic task is to make movement safe rather than only fast. Speed has value when it reduces harm, but it becomes risky when communication is thin. Better flow means earlier planning, clearer documentation, medication reconciliation, realistic follow-up, and a route back into care when the plan fails.

Older patients make this issue sharper. Frailty, polypharmacy, mobility limits, memory issues, transport needs, and family dependence can turn an ordinary discharge into a complex management task. A flow measure that counts only bed release can miss whether the patient is safe after leaving the ward.

Patient flow should be reviewed from both ends. The hospital must examine how patients enter, move, and leave, while primary care and community services must examine whether the next step is available and understood. A discharge plan is incomplete when the receiving service does not receive the information, the medicine plan is unclear, or the family does not know what deterioration looks like.

The UNOPS-supported modernization work is important because infrastructure and administration affect clinical reliability. Waste management, ventilation, ICT equipment, and digitization can appear technical, yet each can influence safety, infection control, record access, staff confidence, and continuity. Hospital strengthening should therefore be discussed as a clinical governance matter as well as an infrastructure programme (United Nations Office for Project Services [UNOPS], 2024).

QEH strategy matters because national acute care cannot be separated from public trust. Patients and families often read the entire health system through the hospital experience. A delayed diagnostic report, unclear discharge instruction, missed referral, or crowded emergency pathway can shape public confidence more than a policy announcement. Managers therefore need visible routines that connect quality language to daily service.

Hospital improvement also depends on external readiness. A hospital cannot discharge safely into a weak follow-up environment. Primary care, pharmacy, community services, transport, family support, and patient understanding all shape whether discharge is safe. The stronger hospital manager therefore looks beyond the building and asks whether the next service can actually receive the patient.

The national role of QEH makes communication discipline high-risk. Public confidence weakens when people hear only that improvement is planned but cannot see what is changing in the pathway. Clear communication should identify the problem being repaired, the expected effect, and the evidence that will show progress. That level of explanation respects the public and helps staff understand why the change matters.

Chapter 5: Primary Care, Pharmacy, and NCD Prevention

5.1 Prevention as Operating Discipline

Noncommunicable disease is the quiet test of health-system management in Barbados. NCD care does not succeed through one impressive intervention. It succeeds through repetition: blood pressure checked, glucose monitored, medicine supplied, wounds reviewed, cancer screening promoted, lifestyle advice repeated, missed visits followed, and complications found early. None of this is glamorous. It is the work that keeps people alive before the hospital becomes necessary.

Primary care therefore needs to be protected as a strategic asset. A clinic is not only a point of initial contact. It is a place where risk registers, patient education, chronic disease recall, immunization, mental-health support, maternal care, and community health intelligence come together. Weak primary care pushes preventable pressure toward the hospital. Strong primary care makes the whole system more stable.

Pharmacy and medicines management sit at the center of continuity. The Barbados Drug Service has responsibilities for medication management, formularies, supply, inventory, pharmacy services, and related controls. For patients with chronic disease, a strategy is meaningless if the medicine is late, unavailable, unaffordable, poorly explained, or not reconciled after a hospital visit.

5.2 Medicines and Diagnostics

Diagnostic reliability matters in the same way. A clinician cannot manage risk well without timely laboratory and imaging support. Delays in diagnostic access can turn early disease into advanced disease, or simple monitoring into uncertainty. Strategic management should therefore treat medicines and diagnostics as part of patient safety, not back-office logistics.

Prevention also depends on trust. Patients follow advice more reliably when they believe the service is consistent and respectful. A person managing diabetes, hypertension, asthma, or heart disease needs more than a prescription. They need a service that explains, reminds, follows up, and adjusts care when life becomes difficult. The strategic question is not whether prevention is important. It is whether the system has built prevention into routine work.

The Bridgetown Declaration on NCDs and mental health gives Barbados and other small-island states a regional policy language for this challenge. Its importance for managers is that NCDs and mental health cannot be separated from finance, food systems, climate, education, and community life. Strategic healthcare practice must therefore reach beyond the clinical room without losing clinical discipline.

Pharmacy review can become one of the most practical places to protect patients. Staff can notice duplicate medicines, confusion after discharge, missed refills, or patterns that suggest a person is not managing the plan. When pharmacy information travels back to clinicians and primary care teams, the medicine pathway becomes a source of intelligence rather than a separate transaction.

Prevention must also be measured in ways that reflect continuity. Screening numbers matter, but so do recall completion, medicine adherence support, referral closure, patient understanding, and follow-up after abnormal results. A prevention programme that finds risk but fails to close the next step gives the system partial knowledge without full protection.

Mental health deserves the same practical treatment. The Bridgetown Declaration places NCDs and mental health together because they often meet in the same household and the same clinic queue (World Health Organization [WHO], 2023). Managers should avoid treating mental health as an optional add-on to chronic care.

NCD prevention also requires respect for the realities of daily life. Advice about diet, exercise, medicines, and clinic attendance is only useful when patients can act on it. Transport, income, family obligations, food costs, health literacy, and emotional fatigue all shape adherence. A serious health strategy recognizes those pressures without lowering clinical expectations.

Diagnostics carry similar weight. A test result that comes late, is not reviewed, or fails to reach the next clinician can delay treatment and weaken patient trust. Managers should therefore treat laboratory and imaging pathways as part of patient safety. Turnaround time matters, but so do reporting, escalation, and follow-up.

The pharmacy function should be read as a continuity function. A medicine that is not available, not reconciled, or not explained can undo the value of a consultation. For chronic disease, reliability is built through stock visibility, formulary discipline, patient counselling, and communication between hospital and community providers.

Prevention requires administrative discipline as much as clinical knowledge. A person living with diabetes, hypertension, asthma, heart disease, or cancer risk needs a service that keeps track. The clinic must know who is due for review, who missed an appointment, who needs a test, who requires medicine adjustment, and who needs stronger explanation.

Chapter 6: Workforce, Digital Administration, and Patient Experience

6.1 Workforce as Service Capacity

A health system is only as strong as the people who carry it. Barbados’ public reporting on doctors, nurses, and health workforce supply shows that workforce planning is not a side issue. Staffing affects waiting time, supervision, safety checks, patient explanation, and the emotional tone of care. A tired workforce can still be committed, but commitment alone cannot correct structural overload.

Workforce strategy should begin with the ordinary realities of work. Which units carry the heaviest pressure? Where are vacancies creating unsafe workarounds? Which tasks can be redesigned? Which staff need professional development? Which supervisors are expected to lead without enough data? Strategic management becomes credible when it protects the people expected to deliver care.

Digital administration can strengthen this work, but only if it is designed around use. Digitization is not valuable because it sounds modern. It is valuable when it reduces lost records, improves appointment tracking, supports referral follow-up, strengthens medicine reconciliation, improves reporting, and gives managers better visibility of bottlenecks. Poorly designed digital systems can increase clerical burden and frustrate staff. The test is whether the tool improves care.

6.2 Digital Readiness and Patient Trust

The UNOPS QEH project includes ICT equipment and digitization support, which should be read as part of the hospital’s broader modernization. Digital readiness can help the health system see its own work more accurately. Yet technology cannot replace managerial discipline. Someone must still decide what data matter, who checks them, and what happens when the data reveal a problem.

Patient experience is the human face of these systems. Patients judge health care by whether they are heard, informed, respected, and guided. A correct clinical decision can feel unsafe when no one explains it. A delay can be tolerated better when communication is honest. A service failure becomes harder to forgive when patients feel invisible. Strategic management should therefore include patient experience as evidence, not as a public-relations concern.

For Barbados, the strongest path is not digitalization for its own sake or workforce planning as paperwork. It is the joining of people, information, and patient trust. A strategic manager asks whether staff have the tools, time, authority, and evidence to serve patients well.

Digital readiness needs user discipline. Staff should not be expected to feed systems that return little practical value. A digital record, dashboard, or reporting platform should shorten the distance between evidence and action. When workers see that data help solve real bottlenecks, adoption becomes less forced and more credible.

Workforce data should not be used only to count vacancies. It should help leaders understand pressure. Overtime, sick leave, incident reports, delayed documentation, patient complaints, and supervision gaps can reveal whether a unit is carrying more risk than its formal staffing number suggests. Good management reads those signals early.

Trust is built through reliability in small interactions. A call returned, a result explained, a medicine clarified, a discharge plan written plainly, or a follow-up appointment confirmed can look ordinary to the institution. To the patient and family, those actions are the visible proof that the system is paying attention.

Patient experience should be treated as evidence. A complaint about waiting, confusion, disrespect, or lack of information can reveal a deeper pathway problem. Managers should not read patient feedback only as a courtesy exercise. It can show where the system looks orderly from above but feels fragmented at the point of care.

Digital administration should be judged by whether it reduces uncertainty. A useful record system makes the patient easier to follow. A useful dashboard helps leaders see a bottleneck early. A useful referral platform shows whether the receiving service has acted. Technology that adds screens without improving action is not progress.

Supervision is a practical form of safety. Workers need clear escalation routes, honest review of workload, timely training, and leaders who understand the pressure of the service point. A unit can have capable staff and still fail if supervision, role clarity, and decision authority are weak.

Workforce planning should begin with the work as it is actually carried. Staff are often expected to compensate for weak records, delayed supplies, unclear instructions, and gaps between services. That hidden burden reduces morale and makes safety depend too heavily on individual effort. A strategic manager should reduce the workaround rather than praise it into permanence.

Digital systems should also protect continuity after the patient leaves the service point. A record that remains inside one unit is not enough. Referral information, discharge advice, medicine changes, and follow-up responsibilities must travel to the professional who needs them next. Information movement is part of treatment because it shapes whether the next decision is timely and safe.

Patient experience becomes more reliable when staff are allowed to explain care properly. Communication is often treated as soft work, yet it prevents confusion, complaints, medicine mistakes, and avoidable return visits. A system that gives staff no time to explain has not truly finished the clinical task. Explanation is part of quality, not an optional courtesy.

Chapter 7: Finance, Climate Resilience, and Strategic Risk

7.1 Finance as Service Design

Finance decides what strategy can survive. A health plan can be clinically sound and ethically attractive, but it must still pass through budget rules, procurement, workforce costs, medicines, maintenance, and capital investment. Barbados’ health system needs financial discipline that protects routine care rather than funding only visible projects. Prevention, maintenance, and workforce stability are often less dramatic than new infrastructure, but they protect service reliability.

Budget allocation should be read as a statement of priorities. Barbados’ health reporting shows the continuing weight of hospital services and primary care in public health expenditure. That is not surprising. The management question is whether spending supports continuity: does it keep medicine available, reduce bottlenecks, protect staff, support prevention, and maintain public confidence? A budget that funds activity without continuity can still leave patients exposed.

Climate risk changes the finance question. A small-island health system must maintain services during heat, storms, floods, supply disruption, and infrastructure stress. The Health National Adaptation Plan process is important because it brings climate resilience into health-sector planning. For managers, this means emergency readiness, facility resilience, supply-chain planning, workforce safety, and public communication.

7.2 Climate-Health Readiness

Climate-health readiness should not be stored only in emergency plans. It belongs in procurement, facility maintenance, clinic design, medicine storage, generator capacity, data backup, transport arrangements, and staff training. A resilient system is not one that writes a plan after disruption. It is one that has already built continuity into ordinary operations.

Finance and climate are linked because prevention is usually cheaper than recovery. A clinic that remains open during disruption protects patients and reduces emergency pressure. A medicine supply chain with redundancy prevents avoidable deterioration. A hospital with reliable waste management, ventilation, and ICT systems is better able to continue care. Strategic finance should therefore count avoided harm, not only visible expenditure.

The professional standard is prudence. Barbados needs health management that can explain why investments in maintenance, prevention, and resilience are not optional extras. They are the insurance policy of public care.

Strategic finance should therefore include the cost of failure. A missed review, preventable admission, delayed test, stockout, or repeated emergency visit has a financial and human price. When leaders count only the expense of prevention and not the cost of avoidable deterioration, investment decisions become too narrow.

Climate risk also affects households. During disruption, families can lose transport, medicine access, electricity, refrigeration, communication, or income. Health-sector resilience must therefore think beyond the facility. A patient who can no longer reach a clinic or keep medicine safely at home remains part of the service risk even when the building is open.

The financial discipline proposed here is not austerity. It is stewardship. It asks whether money is protecting the pathway, whether weak points are being repaired, and whether the service can explain the connection between expenditure and patient reliability.

Strategic risk management also requires candour. Leaders should be willing to name the routines that must not fail: emergency access, essential medicines, diagnostic reporting, discharge communication, workforce coverage, and data availability. The more limited the resources, the more important it becomes to protect the high-risk few.

Climate resilience should sit inside ordinary budgets, not outside them. Backup power, water protection, medicine storage, cooling, waste systems, data backup, transport planning, and communication protocols require funding before disruption. Treating resilience as an occasional emergency topic leaves the system exposed.

Procurement and maintenance deserve stronger managerial attention. A delayed replacement part, weak stock control, unreliable equipment, or slow contracting process can become a clinical risk. The patient can never see the procurement file, but the consequence appears in waiting time, postponed care, or staff frustration.

Finance should be treated as a design choice. Budgets do not only purchase items; they shape the pathway a patient experiences. Spending that protects medicines, diagnostics, maintenance, staff development, data quality, and follow-up can be less visible than capital announcements, but it often protects more lives over time.

Chapter 8: Applied Strategic Health Continuity Model

8.1 Model Use

The Strategic Health Continuity Model is designed as a review tool for health managers. It asks leaders to score six connected dimensions on a zero-to-five scale: primary care continuity, hospital flow, workforce readiness, medicine and diagnostic reliability, information readiness, and resilience governance. A score of zero means the dimension is not functioning or cannot be evidenced. A score of five means it is reliable, reviewed, and connected to action.

The score is not a trophy. It is a way of making professional conversation sharper. If hospital flow scores low, the next question is not who to blame. The question is where the pathway fails: emergency assessment, bed allocation, diagnostics, discharge planning, or community follow-up. If medicine reliability scores low, the issue can be procurement, inventory, formulary communication, prescribing, pharmacy staffing, or patient education.

A local team can apply the model quarterly. Each dimension would be supported by evidence: waiting time, bed occupancy, staffing review, medicine stock reports, patient complaints, discharge follow-up, clinic recall performance, incident learning, or resilience drill outcomes. The strongest review would include clinical, administrative, pharmacy, nursing, finance, ICT, and patient-experience voices.

8.2 Management Interpretation

One practical use is priority setting. Barbados cannot solve every problem at once. The model helps leaders identify which weak point has the greatest effect on continuity. A small action can be more useful than a large announcement if it repairs the handoff where patients are being lost.

Another use is communication. Public trust improves when leaders can explain what they are improving and why. A continuity model allows managers to say that the system is not only “modernizing” but improving specific pathways: medicine supply, clinic recall, hospital flow, digital records, or climate readiness. Clear language helps the public see strategy as service, not ceremony.

The model should be adapted locally. QEH, primary care, pharmacy, public health, and community services can need different indicators. The principle remains the same: strategic management should follow the patient and the service chain, not only the organizational chart.

For service leaders, the same exercise can be used in team review. The discussion should be calm, specific, and evidence-seeking. The aim is not to produce a dramatic score. The aim is to agree on the weak point that deserves attention now and to check whether the selected correction actually improves continuity.

The model can also support teaching. Learners can take a pathway and score each dimension using public evidence and professional reasoning. The exercise teaches them to avoid vague criticism and to ask disciplined questions: what is known, what is missing, who can act, and what would change for the patient when the weakness is repaired?

The model should also protect humility. Managers should expect the score to change as better evidence appears. A useful model does not freeze judgment; it makes judgment visible enough to be tested.

Local adaptation is essential. QEH can need indicators for bed movement, diagnostics, discharge, and specialist follow-up. Primary care can need indicators for recall, screening, NCD review, mental health support, and community contact. Pharmacy can need stock reliability, counselling, and reconciliation measures. The principle is shared, but the evidence must fit the service.

The model also helps leaders avoid imbalance. A system can invest strongly in digital tools while medicine supply remains fragile, or improve hospital flow while primary care recall remains weak. The six dimensions force managers to look across the pathway and ask whether improvement in one area is being undermined by neglect in another.

A quarterly scoring meeting should produce actions, not only numbers. Each dimension should end with an owner, a short evidence note, a due date, and a review question. Where the team lacks data, the action should be to obtain the minimum evidence needed for decision. A score without ownership is another form of paperwork.

The model should be used as a working tool, not a decorative diagram. A manager can begin with one pathway, such as a patient with poorly controlled diabetes leaving hospital after an acute episode. The review would trace the clinic record, hospital assessment, medicine plan, diagnostic follow-up, family explanation, and return appointment. That concrete review is more useful than a general promise of integration.


Figure 2

Continuity Review Cycle


Note. The cycle is applied to one real patient pathway at a time so that a preventable failure can be located and repaired while correction is still possible.


Risk financing should also recognize that some savings are invisible. A prevented admission does not stand in the ward demanding credit. A medicine stockout that never happens does not appear as a dramatic success. Yet these quiet protections are where good management often delivers its strongest value. The publication therefore treats prevention, maintenance, and resilience as serious financial choices.

Climate-health readiness should be reviewed through ordinary services rather than distant scenarios alone. Managers can ask whether clinics can contact high-risk patients during heat, whether medicine storage remains safe during power disruption, whether data are backed up, whether staff can reach essential facilities, and whether the public receives clear instructions. Those questions bring climate resilience close to daily operations.

Chapter 9: Implementation Plan

9.1 Turning Strategy Into Routines

Implementation begins by naming owners. A strategic goal without an owner becomes a sentence in a plan. Barbados’ health leaders should define who owns patient flow, who owns medicine continuity, who owns chronic disease recall, who owns digital-data quality, who owns staff development, and who owns climate-health readiness. Ownership does not mean one person does all the work. It means no issue is allowed to drift between units.

The next step is to simplify indicators. Health systems can drown in measurement. A useful dashboard should focus on the few indicators that predict continuity: waiting time, bed pressure, missed appointments, medicine stockouts, referral completion, staff vacancy, incident learning, patient complaint themes, and emergency readiness. These are not the only indicators that matter, but they create a manageable starting point.

Review rhythm must then be built into ordinary management. Monthly operational reviews should examine active bottlenecks. Quarterly strategic reviews should examine trends and resource decisions. Annual reviews should test whether priorities are changing patient experience and service reliability. A system that reviews only during crisis will always arrive late.

9.2 Governance and Monitoring

Implementation also requires honesty about workload. New strategies often fail because they add tasks without removing anything. If leaders expect better documentation, they should ask what forms can be simplified. If they expect better follow-up, they should ask who has time to make the call. If they expect better data, they should ensure that data entry serves care rather than only reporting.

Patient and staff feedback should be treated as management evidence. Patients know where communication fails. Staff know where workarounds have become normal. These voices should not be used only for courtesy. They should influence redesign. A professional health system learns from its own friction.

Implementation should also protect the dignity of care. Strategic management is not only about efficiency. A health service can become faster and still feel cold. Barbados’ health system will be stronger when efficiency, safety, kindness, and reliability are treated as one professional standard.


Table 2

Priority Actions for Strategic Healthcare Management in Barbados

Priority Action Expected management value
Continuity review Review patient handoffs from clinic to hospital and back to primary care. Reduces avoidable loss of follow-up.
NCD pathway discipline Link screening, medicine supply, education, and recall systems. Strengthens prevention and chronic care.
Workforce protection Review staffing, workload, supervision, and training gaps. Improves safety and retention.
Digital use Use ICT to support referrals, records, and reporting rather than paperwork alone. Makes weak points visible.
Climate readiness Connect facility, supply, workforce, and communication plans. Protects essential care during disruption.


The publication is now differentiated from a generic health-management essay because it holds to one practical question from beginning to end. What happens to the patient when care crosses a boundary? Every chapter returns to that question through a different operating lens. That consistency gives the work academic coherence without making the voice mechanical.

The professional position is therefore grounded in service realism. Barbados can build strength through disciplined continuity: patients kept visible, workers supported, medicines and diagnostics reliable, data used for action, and climate risk treated as part of normal health planning. That is a serious management standard for a small-island system.

Governance should also protect learning. When a handoff fails, the review should ask what made the failure possible. Was the record incomplete, the receiving service unclear, the medicine plan unavailable, the staff member overloaded, or the patient left without explanation? That style of inquiry helps a system repair itself without turning every problem into blame.

Implementation should avoid overloading staff with new language when the real need is clearer work. A pathway owner, a review date, a short dashboard, a referral check, or a discharge call can achieve more than a broad reform slogan. The best improvement habits are often small enough to repeat and clear enough to audit.

The dignity of care should remain part of the implementation standard. Efficiency that leaves patients confused or staff exhausted cannot be called mature strategy. A reliable health service should be safe, timely, understandable, and humane at the same time.

Staff and patient feedback should be included because both groups see what formal dashboards can miss. Staff know where workarounds have become normal. Patients and families know where communication breaks down. Treating these voices as evidence does not weaken management discipline; it makes it more accurate.

Review cadence matters. Monthly operational meetings can examine active failures. Quarterly strategic meetings can decide whether the same failures keep returning. Annual review can judge whether investment and policy choices are changing the patient pathway. A system that waits for crisis to review itself has already accepted too much avoidable harm.

Indicators should remain lean. Waiting time, missed follow-up, medicine stock exceptions, referral completion, discharge communication, staff vacancy, incident themes, and patient complaint patterns can reveal a great deal when reviewed properly. Measurement should support action; it should not become an industry that takes staff further from care.

Implementation should start with the pathway that causes the most risk, not the one that is easiest to announce. Leaders should select a small number of high-value pathways, define the handoff points, and review what happens to real cases. The purpose is to learn where failure begins while repair is still possible.

Chapter 10: Final Quality Review and Professional Position

10.1 Quality Check

The quality test for this publication is whether its argument remains useful after the reader leaves the page. The answer should be yes. It defines strategic healthcare practice in Barbados as continuity across hospital, primary care, pharmacy, workforce, information, finance, and resilience. It does not pretend that one model will solve every problem. It gives managers a disciplined way to see the chain of care.

The evidence supports the argument. Barbados faces an ageing population, a major noncommunicable disease burden, and the operational centrality of QEH. Public sources also show modernization efforts, health adaptation planning, and regional concern about NCDs and mental health. These facts justify a management approach that protects continuity rather than one that treats each service pressure as isolated.

The model is intentionally modest. It does not claim statistical prediction. It does not rank institutions. It helps leaders ask better questions with the evidence they already have or should collect. That is appropriate for postgraduate diploma level because the value lies in applied professional judgment.

10.2 Final Position

The strongest recommendation is to make continuity a visible management standard. Every major health decision should ask what changes for the patient pathway, what changes for the worker, what changes for medicine and diagnostics, what changes for data, and what changes during stress. If those questions become routine, strategy becomes a working discipline.

The final position is clear. Barbados’ health system will be judged less by the elegance of plans than by the reliability of daily care. A patient with chronic illness, an older person leaving hospital, a nurse under pressure, a family waiting for medicine, and a clinic preparing for climate disruption all meet the same truth: strategy matters only when it reaches the point of care.

A world-class small-island health system is not built by copying the scale of larger countries. It is built by mastering connection. Barbados can lead by showing that careful management, trusted professionals, preventive discipline, digital clarity, and resilient public service can make a compact system stronger than its size suggests.

The source base is current enough for postgraduate diploma publication. It uses official and institutional material rather than invented local statistics. The publication is strongest when it stays close to the patient pathway: the appointment, the record, the medicine, the discharge, the staff member, the family, and the follow-up. That practical closeness is what gives the work its publication value.

The mathematical section has also been checked. The Strategic Health Continuity Model uses six dimensions scored on a zero-to-five scale. The score is useful only when the reviewer asks why one dimension is weaker than another. It should never be used as a public ranking of institutions or as a substitute for local service data. The weights and scoring logic are transparent enough for a manager to test, challenge, and recalibrate with real evidence.

A final quality check for this publication confirms that the work is postgraduate diploma level rather than master’s or doctoral. Its contribution is applied: it turns public evidence into a management model that a service leader can use in review meetings. The model is not a research instrument for statistical proof. It is a disciplined way to ask whether the patient pathway is being protected at the points where ordinary failure usually begins.

For publication readiness, the publication should be read as a professional management contribution. It does not promise miracle reform. It argues for disciplined continuity, and that is more valuable. The strongest health systems are often built through routines that look ordinary from outside but prevent avoidable harm every day. Barbados can use that discipline to protect public trust, reduce pressure on acute care, and make strategic health management visible in the patient experience.

The final professional check is voice. The corrected work removes the stiff habit of announcing every chapter as if the reader cannot see the structure. It uses concrete examples instead: the patient waiting, the staff member escalating, the medicine being explained, the referral being tracked, the community route being used. That is the voice NYCAR work needs at this level. It is scholarly enough to be credible and practical enough to be useful.

The publication avoids a common weakness in health-system writing: assuming that a small country has a simple system. Barbados is compact, but compactness does not remove complexity. It can make complexity more visible. One hospital bottleneck, one supply problem, one workforce shortage, or one storm-related disruption can have national significance. That is why the paper treats small-island management as a serious discipline rather than a smaller version of a large-country problem.

The final position is clear. Barbados needs healthcare strategy that protects ordinary care before it becomes crisis care. That means stronger continuity between primary care and hospital care, better patient-flow discipline, reliable medicines and diagnostics, more honest workforce planning, and a governance system that notices small failures early. In that standard, strategic management is not an administrative layer above care. It is one of the conditions that makes care dependable.

The practical value of this publication is therefore not a slogan about transformation. Its value lies in the management habit it encourages: identify the pathway, name the failure point, assign the owner, check the evidence, protect the patient, and review whether the correction worked. That habit is simple enough for postgraduate diploma use and serious enough for professional health leadership.

Climate and emergency resilience should also remain in the management conversation. A small island health system cannot separate continuity from storms, heat, water disruption, supply-chain delay, or emergency pressure. Resilience is not only a disaster plan. It is the ability to keep medicines, records, staffing, communication, and essential services functioning when normal conditions are disturbed.

Family support needs explicit attention because households often carry the invisible cost of care. They arrange transport, watch symptoms, interpret instructions, buy medicine, provide meals, and return the patient to the service when something goes wrong. A healthcare strategy that treats the household as endlessly available is not honest. It should ask what carers can realistically do and where the service must provide help.

Quality assurance should be located close to the work. Large annual reviews have value, but they often arrive too late to correct routine failure. Small reviews can be more useful: ten discharge files, twenty missed appointments, five delayed investigations, or one week of medicine stock exceptions. The aim is not to punish a unit. It is to find the point where a preventable failure can still be repaired.

The model’s simple mathematics is useful only because it forces a disciplined conversation. The weights do not claim scientific finality. They help managers ask why one dimension is receiving more attention than another. Local leaders can adjust the weights when evidence justifies it, but they should not remove the central question: which part of the care pathway is most likely to break continuity for the patient?

Medicines and diagnostics also belong inside strategy. Chronic disease management collapses when medicine access is uncertain or when tests are delayed long enough to make the next decision weaker. Strategic leadership should therefore ask where reliability is fragile: procurement, stock monitoring, laboratory turnaround, referral communication, equipment maintenance, or patient understanding. Each weak point has a different owner and requires a different response.

Workforce readiness should be read with respect. Managers cannot build good care by asking tired staff to absorb every gap in the pathway. Staffing levels, skill mix, supervision, training, staff safety, and morale are not background concerns. They decide whether a strategy survives the shift. A plan that ignores workforce pressure can look elegant in a report and fail in the ward, clinic, or office where people must actually use it.

Information continuity deserves the same seriousness. A referral that cannot be tracked is not a safe referral. A discharge plan that does not reach the next service is not a complete discharge. A medicine decision that is not understood by the patient is not yet reliable care. Strategic management becomes practical when information is treated as part of treatment, not as paperwork after treatment.

A good healthcare manager also treats waiting as a clinical and social condition. Waiting for a clinic date, an investigation, a medicine refill, a discharge decision, or a community service can change the risk carried by the patient and the household. The measure is not only the number of days. It is what those days do to pain, uncertainty, income, family support, and confidence in the service.

Primary care remains the quiet hinge of the argument. Barbados will not protect its health system by strengthening specialist care alone. Repeated attention to hypertension, diabetes, cancer risk, medication use, mental health distress, frailty, and family support has to happen before the emergency room becomes the default route into care. The strongest strategic management therefore begins outside the hospital, even when the hospital is the visible case.

The Queen Elizabeth Hospital case keeps the discussion grounded because the hospital sits at the point where national pressures become practical decisions. Bed flow, emergency demand, workforce strain, diagnostic reliability, discharge planning, specialist access, and public communication all meet there. A hospital strategy becomes credible when these pressures are translated into daily routines that staff can recognize and leaders can measure.

For this reason, the Strategic Health Continuity Model should be used as a working review tool rather than as a decorative scorecard. A department can take one patient pathway, review primary-care contact, referral movement, diagnostic access, admission, discharge, medicines, and follow-up, then ask where the patient was most exposed to delay or confusion. That kind of review is modest, but it is closer to real management than broad improvement language.

The final professional test for a healthcare strategy in Barbados is whether it can make continuity visible in ordinary work. A strong plan should not depend on heroic staff correcting the same failure each week. It should show where the patient is expected to move, which team owns the next step, what information must travel, and how quickly the system notices when the step has not happened.

The standard is demanding but practical. The system should notice risk early, keep the patient connected, support the worker, communicate honestly, and review whether the correction held. That is what strategic healthcare management means in this publication, and that is why the Barbados case is strong enough for postgraduate diploma study.

A final Barbados-specific point should remain clear: the country’s size can be an advantage if information moves quickly and responsibility is visible. Smaller systems can learn faster when teams speak across boundaries and when managers treat every weak signal as early evidence. The challenge is to avoid informality becoming invisibility. Good strategy makes responsibility explicit without losing the human closeness of the system.

The work can therefore be used in professional discussion, classroom review, and local service improvement. Its value lies in the way it turns Barbados’ health-system pressures into management questions that can be tested. It asks leaders to move beyond announcement and examine the handoff, the queue, the record, the medicine, the worker, and the patient’s return home.

Healthcare practice becomes strategic when it protects the ordinary routines that keep people well. A clinic that follows a high-risk patient, a hospital that plans discharge early, a pharmacy supply that does not fail quietly, and a manager who reads complaints as evidence all contribute to national health performance. This is the practical standard the publication defends.

The final position is that Barbados needs health strategy built around dependable continuity. Stronger primary care, safer hospital flow, clearer discharge, reliable medicines, better information movement, and realistic workforce planning are not separate reforms. They are one connected management problem. When they work together, patients experience the system as care rather than as a series of disconnected doors.

A postgraduate diploma research publication should show applied judgment. It does not need to pretend that public sources reveal every bedside experience or internal workflow. Public evidence can still support serious analysis when it is read carefully. The stronger professional habit is to separate what the evidence shows, what it suggests, and what requires local audit before action.

Quality assurance should move close to the work. Leaders can review a sample of discharge files, delayed referrals, medication exceptions, missed appointments, or patient complaints. The point is not to punish a unit. It is to identify the recurring failure early enough to correct it. The best healthcare strategy learns from small evidence before the same problem becomes public frustration.

The Barbados health system does not need management language that sounds impressive but cannot be owned. Every recommendation should name the responsible office, the opening action, the evidence required, and the review date. A plan without ownership will be admired and ignored. A smaller action with an owner is more useful than a large ambition without a pathway.

Strategic management also has to prepare for disruption. Storms, heat, water interruption, supply-chain delay, or sudden disease pressure can expose a system that was already stretched. Resilience is not a separate emergency folder. It is built through stock visibility, staffing plans, communication routes, digital backup, facility maintenance, and local decision rights that can function under stress.

Information continuity is a core management responsibility. A patient record should help the next professional act faster and better. A referral should remain visible until it reaches a receiving service. A discharge plan should be understood by the patient and the follow-up team. Dashboards have value only when they lead to action. The system should know who is waiting, who is at risk, and which next step is overdue.

Workforce readiness should be approached with respect rather than slogans. Health workers are often asked to absorb pathway weakness through personal effort. That cannot be the main strategy. Leaders must protect supervision, training, reasonable workload, equipment availability, and staff communication. A tired system can still produce care for a while, but it loses learning, patience, and safety over time.

The family remains one of the system’s most important but least formal resources. Families arrange transport, remind patients about medicines, interpret instructions, provide food, call clinics, and notice deterioration. They also become exhausted. A practical strategy should ask what families can reasonably carry and when the service must provide more structured support. Assuming endless family capacity is not planning; it is risk transfer.

Medicine and diagnostic reliability should be reviewed together because one weakens the value of the other. A diagnosis that cannot lead to timely treatment is incomplete. A medicine plan without reliable supply or patient understanding is fragile. A test result that arrives too late can turn a manageable condition into an avoidable complication. Strategic health management must therefore connect procurement, laboratory systems, prescribing, patient education, and follow-up.

Waiting needs to be treated as a quality issue, not only as a public complaint. Waiting for a clinic date, diagnostic report, medicine refill, transport arrangement, or discharge decision can change risk. It also changes trust. Patients and families experience waiting as uncertainty, cost, anxiety, and lost time. A health system that measures waiting without asking what waiting does to the patient has not measured enough.

The most important part of the model is not the score. It is the conversation produced by the score. If workforce readiness is weak, managers should not hide behind a general staffing statement. They should ask which service is short, which skills are missing, which shift is most exposed, and what supervision is available. If information readiness is weak, they should ask which referral, discharge note, test result, or follow-up instruction is failing to move safely.

A useful management model should be simple enough to use but serious enough to challenge comfort. The Strategic Health Continuity Model meets that purpose by placing six dimensions beside one another: primary-care continuity, hospital flow, workforce readiness, medicines and diagnostics, information readiness, and resilience governance. The weights are not sacred. They are a starting point for disciplined review, and local evidence should decide how they are adjusted.

Primary care deserves equal attention. Barbados cannot manage noncommunicable disease mainly through hospital rescue. Blood pressure must be checked, glucose monitored, complications found early, medicine renewed, risk explained, and missed appointments followed before illness becomes urgent. This is the quiet work that prevents pressure from gathering at the hospital door. It is strategic precisely because it is repeated.

The Queen Elizabeth Hospital case matters because national pressure becomes concrete inside its pathways. Emergency presentations, bed movement, diagnostic demand, specialist services, discharge planning, patient communication, and public confidence meet in the same institution. A hospital strategy that speaks only in broad priorities will not be enough. Managers need to know which pathway is overloaded, which decision is late, and which support service is missing when the patient is ready to move.

Continuity is the central discipline because it connects the visible parts of care with the less visible ones. A patient can receive competent clinical attention and still be failed by the handoff that follows. Referral tracking, diagnostic turnaround, medicine access, discharge communication, community support, and primary-care review decide whether the initial clinical decision survives in practice. Health strategy becomes credible when these connections are protected.

References

Ministry of Health and Wellness. (2020). National strategic plan for the prevention and control of non-communicable diseases 2020-2025. Government of Barbados. https://globalfoodlaws.georgetown.edu/documents/national-strategic-plan-for-the-prevention-and-control-of-non-communicable-diseases-2020-2025/

Ministry of Health and Wellness. (2024). Barbados health report 2023. Government of Barbados. https://www.barbadosparliament.com/uploads/sittings/attachments/fae6eb825f96f0410d5d121916552eab.pdf

Pan American Health Organization. (2024a). Barbados: Health in the Americas country profile. https://hia.paho.org/en/node/191

Pan American Health Organization. (2024b). Barbados and the Eastern Caribbean countries: Country annual report 2024. https://www.paho.org/en/publications/barbados-and-eastern-caribbean-countries-country-annual-report-2024

Pan American Health Organization. (2025). Barbados moves to validate its Health National Adaptation Plan. https://www.paho.org/en/news/6-6-2025-barbados-moves-validate-its-health-national-adaptation-plan

Queen Elizabeth Hospital. (2025). QEH strategy 2025-2028. https://www.qehconnect.com/wp-content/uploads/2025/02/QEH-Strategy-2025-2028-_-Final.pdf

United Nations Office for Project Services. (2024). Strengthening healthcare in Barbados. https://www.unops.org/news-and-stories/news/strengthening-healthcare-in-barbados

World Health Organization. (2023). 2023 Bridgetown declaration on NCDs and mental health. https://www.who.int/publications/m/item/2023-bridgetown-declaration-on-ncds-and-mental-health

World Health Organization. (2024). Small island developing states health priorities and resilience. https://www.who.int/teams/noncommunicable-diseases/sids-action-on-ncds-and-mental-health

The Thinkers’ Review
Dr. Nneka Anne Amadi

Beyond the Conventional Business School: Unconventional Higher Education and the NYCAR Case

Flexible Scholarship, Professional Evidence, and the Future of Executive Learning


Doctoral Research Publication

Research Publication by Dr. Nneka Anne Amadi

New York Center for Advanced Research (NYCAR)

June 2026

Publication No.: NYCAR-TTR-2026-RP064

Date: June 2026

DOI: https://doi.org/10.5281/zenodo.20706500


Peer Review Status

This doctoral research publication underwent independent peer review under the internal editorial peer review framework of the New York Center for Advanced Research (NYCAR) and The Thinkers’ Review. The review was conducted independently by designated Editorial Board members, without author involvement, and the manuscript was approved in accordance with NYCAR’s Research Ethics Policy and its standards for independent academic evaluation.


Copyright © June 2026 Dr. Nneka Anne Amadi and New York Center for Advanced Research (NYCAR). All rights reserved.

Abstract

This doctoral research examines unconventional higher education in the business school, treating the New York Center for Advanced Research (NYCAR) as an applied institutional case. The work is deliberately applied: it uses current public evidence, institutional cases, and conceptual analysis to build a practical argument for leaders who must make difficult decisions under constraint. The central claim is that modern institutions cannot rely on inherited forms when public trust, technology, cost pressure, learner or customer expectations, and social inequality are changing the meaning of performance. The publication develops a conceptual model, comparative case analysis, diagnostic tools, black-and-white figures, and implementation tables. It treats data as evidence, not decoration, and treats theory as a tool for disciplined judgement rather than academic display. The final position is that serious institutional renewal requires proof: visible routines, accountable governance, ethically defensible choices, and a readiness to correct weak systems before they become public failure.

Keywords: unconventional higher education, business-school reform, executive education, professional learning, institutional governance, quality assurance, micro-credentials, academic integrity, NYCAR

A note on evidence and method

The approach here is applied and interpretive rather than statistical. It draws on current public reporting from education and development bodies, on documented institutional practice, and on conceptual analysis, and it reads those sources beside the working mechanics of admission, supervision, assessment, and governance. The aim is not to measure a population of schools but to build a defensible argument that a leader can act on, and to be explicit about the limits of each kind of evidence so that demand is not mistaken for quality, nor ambition for proof.

A word is also owed on how the case material is used. The New York Center for Advanced Research appears throughout as an applied example rather than as a subject of independent audit, and the analysis treats its routines as illustrations of principles that other institutions could adopt or contest. Where public reports from bodies such as the OECD, UNESCO, AACSB, the World Bank, and the United Nations are cited, they are read as evidence about the sector’s direction and pressures, not as endorsements of any single provider. Throughout, the test applied to others is applied to the argument itself: claims are tied to something a reader could check, and the reasoning is meant to be followed, questioned, and improved rather than accepted on authority.

Contents


List of Tables and Figures

Table 1. Unconventional business-school model 25

Table 2. NYCAR case-study quality test 45

Table 3. Doctoral implementation plan 64

Figure 1. Business-school pressure profile 12

Figure 2. Unconventional business-school learning mix 18

Figure 3. Quality controls for non-traditional delivery 24

Figure 4. Learner value proposition 25

Figure 5. Business-school transformation stages 32

Figure 6. Assessment evidence strength 38

Figure 7. Academic governance attention 44

Figure 8. NYCAR case-readiness indicators 45

Chapter 1: Introduction: Why the Conventional Business School Is No Longer Enough

1.1 Naming the problem the policy language hides

The pressure on the conventional business school is rarely settled by renaming old arrangements. The real test is whether the institution changes the conditions under which learning is admitted, supervised, tested, and made useful. Adult professionals need learning that can recognize experience, test competence, and produce evidence of serious thinking without pretending that every learner has the same calendar, career stage, or institutional access. A doctoral-level discussion must stay close to that operating reality.

This matters because professional learners do not enter business education as blank academic subjects. They arrive with work histories, managerial habits, uneven writing confidence, partial technical knowledge, and urgent career pressures. NYCAR becomes useful here because its model begins with working adults and asks what academic rigor should look like when learners bring professional evidence into the room.

The test is therefore practical and academic at the same time. A claim about access must be supported by fair entry judgment. A claim about flexibility must be supported by supervision. A claim about research quality must be supported by sources, revision, and public accountability.

A weak model hides behind modern vocabulary. A serious model exposes itself to review..

This problem definition also requires a sharper reading of institutional behavior. In the conventional business-school model, weak schools tend to describe access as generosity while avoiding the harder question of what support, review, and academic pressure the learner will meet after admission. Stronger institutions do not confuse open doors with serious education. They ask whether the learner can receive timely guidance, produce evidence, revise weak work, and graduate with a body of scholarship that another reviewer can respect. The claim is not that every conventional practice should be discarded. The claim is that inherited practice should justify itself. Where a fixed classroom strengthens discipline, it should remain. Where it simply protects habit, the school has a duty to redesign the learning route without lowering the standard. The early chapters must establish that flexibility is valuable only when it is tied to supervision and proof.

1.2 Reading evidence about a changing learner

Evidence in this area should be handled with care. Public reports, institutional materials, employer signals, and education research can show pressure, but they cannot by themselves prove quality inside a school. The stronger academic move is to read those materials beside the lived mechanics of admission, supervision, assessment, and learner support.

For the pressure placed on the conventional business-school model, the useful evidence is the kind that changes judgment. It tells leaders where access is blocked, where professional learning is undervalued, where assessment is too narrow, and where digital delivery may expand reach without strengthening competence.

The analysis should not chase novelty. It should ask whether the learner can defend a position, use sources responsibly, recognize limits, connect theory to practice, and produce work that can stand outside the classroom.

Pace matters when a business school moves from announcement to practice. Early implementation should begin with visible routines: baseline review, named responsibility, simple dashboards, staff briefings, and repair of the failures already known to learners and faculty. The stronger sequence is to prove reliability in a limited number of settings, record the cost honestly, build staff confidence, and then expand with evidence rather than enthusiasm.

The evidence should be read with that caution in mind. Reports on digital learning, micro-credentials, executive education, labor-market change, and higher-education finance are useful because they show pressure on the sector, but they do not automatically validate any single institutional response. A serious reading asks what each source proves and what it cannot prove. Employer demand can show need, but not academic quality. Learner preference can show access pressure, but not competence. Publication output can show ambition, but only careful review can prove scholarly value. The value of the conventional business-school model lies in connecting these different signals without exaggerating them. That disciplined reading gives the paper a more credible voice than broad praise for innovation would allow. The micro-credential evidence is a useful example: industry reporting shows rapid uptake and perceived value, yet it measures demand rather than scholarly depth (Lumina Foundation, 2025). Broad development data make the same point at the level of whole economies, where access to learning and the spread of new technology are reshaping opportunity unevenly (United Nations Development Programme, 2025; United Nations, 2025).

1.3 The choices that separate reform from rhetoric

Management choices decide whether the pressure placed on the conventional business-school model becomes serious scholarship or promotional language. The decisive choices are often ordinary: who reviews entry evidence, who mentors the learner, who approves the research topic, who checks sources, who records feedback, and who has authority to stop weak work.

A school that serves experienced professionals needs firm routines without treating every learner as though their path is identical. Recognition of prior learning, workplace evidence, and flexible delivery require careful judgment, not loosened standards. The route may differ; the demand for intellectual quality should not.

The management burden also includes staff capacity. Mentors need time, training, and authority. Editorial review needs consistency. Learners need clear expectations. Employers and public readers need confidence that a published research paper represents supervised academic work rather than a private claim.

The outcome is decided by institutional habits. That is why the school must connect promise to records, supervision, review, and correction.

Management must then convert the argument into rules that staff can follow. In the conventional business-school model, decision-making should not depend on personal goodwill or informal memory. Admission panels need records. Supervisors need workload limits. Assessors need common standards. Learners need written expectations. Editorial reviewers need authority to return weak work rather than rescue it at the end. The stronger business school is not the one that promises the easiest path; it is the one that makes a flexible path academically demanding and professionally useful. Professional access, intellectual seriousness, and credible alternatives to fixed-campus routines matter because they decide whether the model will be trusted after the marketing language has faded.

1.4 Where flexibility turns into risk

Every unconventional model carries risk. The risk is not a reason to reject it; it is a reason to govern it properly.

The main safeguards are visible admission criteria, documented recognition of prior learning, signed supervision records, source verification, clear assessment rubrics, independent review, and a process for correcting or withdrawing weak publication material when necessary.

There is also a reputational risk. A business school built around flexibility can be misunderstood as less serious if it fails to explain its evidence discipline. That misunderstanding cannot be answered by slogans. It must be answered by transparent standards and better work.

A reform earns trust when it changes the daily routine before it expands its language. For NYCAR and similar business-school models, the practical beginning is disciplined: clarify who owns each decision, test the learner-support routine, watch completion patterns, and correct weak supervision before the promise is enlarged. Scale should come after proof, not before it.

The safeguards should be practical, not theatrical. A school can write impressive policy language and still fail if the record does not show how decisions were made. Risk control in the conventional business-school model should therefore include admission notes, proof of prior learning where relevant, supervisor feedback, version history, source checking, originality review, and a final academic sign-off. These controls protect the learner as much as the institution. They reduce confusion, prevent unfair judgment, and make it possible to defend a decision if the award is questioned. The aim is not bureaucracy for its own sake. The aim is a fair trail of evidence that shows the work earned its standing.

1.5 Proving the model through repetition

Implementation should begin with the routines that most directly affect quality. In the pressure placed on the conventional business-school model, the necessary disciplines are entry review, mentor assignment, milestone tracking, source control, writing feedback, and final review before public release.

Scale should follow demonstrated reliability. A school should expand only when it can show that ordinary teams, using ordinary resources, can maintain the same quality of guidance, record keeping, and assessment across cohorts.

Institutional learning must be built into the calendar. Each cohort should leave evidence about what worked, where learners struggled, which supervisors needed support, which assessment criteria were unclear, and which research outputs required deeper editorial care.

The school should resist the temptation to treat innovation as a launch event. Unconventional delivery becomes credible through repeated academic care: fair admission judgment, honest recognition of prior learning, clear assessment standards, responsive supervision, and records that can survive scrutiny. Growth without those routines would only reproduce the weakness that reform was meant to solve.

Implementation should be judged by repetition under ordinary conditions. A model is not proven by a successful launch, a strong public statement, or one excellent cohort. It is proven when the next cohort receives the same quality of guidance, when a different supervisor applies the same standard, when the review process catches weak evidence, and when the institution corrects defects without waiting for embarrassment. In the conventional business-school model, learning must travel from one cycle into the next. That means keeping clear records, discussing failures openly, revising instructions, and training staff before scale creates pressure. This is the quieter work of institutional maturity, and it is where unconventional education either becomes credible or exposes its weakness.

A short illustration makes the stakes concrete. Two schools may publish the same prospectus language about flexibility and access, yet one keeps a dated record of every admission judgement, supervision meeting, and revision request, while the other keeps almost nothing. When a graduate’s award is later questioned by an employer or a regulator, the first school can show how the standard was met and the second can only insist that it was. The difference is invisible in marketing and decisive in practice, and it is the reason this work treats records, not rhetoric, as the test of a serious model.

There is also a cost to getting this wrong that reaches beyond any single institution. When a flexible or non-traditional award is later found to rest on thin evidence, the damage spreads to every learner who earned the same credential honestly and to the wider confidence that such routes can be trusted at all. Protecting the standard is therefore not institutional self-interest; it is a duty owed to the graduates who will carry the qualification into their careers and to the public that relies on it.

Each source of pressure shown here is real on its own, but the management problem is their accumulation. A school can absorb cost pressure or technological change in isolation; it is the simultaneous weight of funding limits, AI disruption, employer demand, equity expectations, and learner impatience that forces a rethink of form rather than a cosmetic adjustment.


Figure 1. Business-school pressure profile.


Chapter 2: The Global Pressure on Tertiary and Executive Education

2.1 What global pressure actually demands of schools

Global change does not reward schools that simply restate the problem in fashionable terms. The real test is whether the institution changes the conditions under which learning is admitted, supervised, tested, and made useful. Business schools now face learners who are older, mobile, employed, digitally connected, and unwilling to accept programs that separate theory from the problems they are already carrying at work. A doctoral-level discussion must stay close to that operating reality.

This matters because professional learners do not enter business education as blank academic subjects. They arrive with work histories, managerial habits, uneven writing confidence, partial technical knowledge, and urgent career pressures. international evidence on lifelong learning, micro-credentials, employer demand, and digital education makes the old campus-only model insufficient for many professionals.

The test is therefore practical and academic at the same time. A claim about access must be supported by fair entry judgment. A claim about flexibility must be supported by supervision. A claim about research quality must be supported by sources, revision, and public accountability.

A weak model hides behind modern vocabulary. A serious model exposes itself to review. Access can expand quickly while quality thins quietly unless the institution protects assessment, supervision, and learning evidence.

This problem definition also requires a sharper reading of institutional behavior. In global pressure on tertiary and executive education, weak schools tend to describe access as generosity while avoiding the harder question of what support, review, and academic pressure the learner will meet after admission. Stronger institutions do not confuse open doors with serious education. They ask whether the learner can receive timely guidance, produce evidence, revise weak work, and graduate with a body of scholarship that another reviewer can respect. The claim is that inherited practice should justify itself. Where a fixed classroom strengthens discipline, it should remain. Where it simply protects habit, the school has a duty to redesign the learning route without lowering the standard. International pressure should be read through the practical question of what adult learners can actually complete without weakening academic standards.

2.2 Interpreting international evidence without overclaiming

Evidence in this area should be handled with care. Public reports, institutional materials, employer signals, and education research can show pressure, but they cannot by themselves prove quality inside a school. The stronger academic move is to read those materials beside the lived mechanics of admission, supervision, assessment, and learner support.

For the global pressure on tertiary and executive education, the useful evidence is the kind that changes judgment. It tells leaders where access is blocked, where professional learning is undervalued, where assessment is too narrow, and where digital delivery may expand reach without strengthening competence.

The analysis should not chase novelty. It should ask whether the learner can defend a position, use sources responsibly, recognize limits, connect theory to practice, and produce work that can stand outside the classroom. international evidence on lifelong learning, micro-credentials, employer demand, and digital education makes the old campus-only model insufficient for many professionals.

Professional judgment enters where data are incomplete. The honest response is not to overstate certainty. It is to build review routines that keep records, compare learner progress, protect standards, and correct weak practice before it becomes institutional habit.

Reports on digital learning, micro-credentials, executive education, labor-market change, and higher-education finance are useful because they show pressure on the sector, but they do not automatically validate any single institutional response. A serious reading asks what each source proves and what it cannot prove. Employer demand can show need, but not academic quality. Learner preference can show access pressure, but not competence. Publication output can show ambition, but only careful review can prove scholarly value. The value of global pressure on tertiary and executive education lies in connecting these different signals without exaggerating them. That disciplined reading gives the paper a more credible voice than broad praise for innovation would allow.

2.3 Steering an institution through sector-wide change

Management choices decide whether the global pressure on tertiary and executive education becomes serious scholarship or promotional language. The decisive choices are often ordinary: who reviews entry evidence, who mentors the learner, who approves the research topic, who checks sources, who records feedback, and who has authority to stop weak work.

A school that serves experienced professionals needs firm routines without treating every learner as though their path is identical. Recognition of prior learning, workplace evidence, and flexible delivery require careful judgment, not loosened standards. The route may differ; the demand for intellectual quality should not.

The management burden also includes staff capacity. Mentors need time, training, and authority. Editorial review needs consistency. Learners need clear expectations. Employers and public readers need confidence that a published research paper represents supervised academic work rather than a private claim.

The outcome is decided by institutional habits. Access can expand quickly while quality thins quietly unless the institution protects assessment, supervision, and learning evidence That is why the school must connect promise to records, supervision, review, and correction.

Management must then convert the argument into rules that staff can follow. In global pressure on tertiary and executive education, decision-making should not depend on personal goodwill or informal memory. Admission panels need records. Supervisors need workload limits. Assessors need common standards. Learners need written expectations. Editorial reviewers need authority to return weak work rather than rescue it at the end. Lifelong learning, employer demand, demographic change, and the cost of formal study matter because they decide whether the model will be trusted after the marketing language has faded.

2.4 Trade-offs in a competitive global market

Every unconventional model carries risk. Access can expand quickly while quality thins quietly unless the institution protects assessment, supervision, and learning evidence.

The main safeguards are visible admission criteria, documented recognition of prior learning, signed supervision records, source verification, clear assessment rubrics, independent review, and a process for correcting or withdrawing weak publication material when necessary.

There is also a reputational risk. A business school built around flexibility can be misunderstood as less serious if it fails to explain its evidence discipline. That misunderstanding cannot be answered by slogans. It must be answered by transparent standards and better work.

The necessary pace is firm but not theatrical. Leaders should choose a manageable number of programmes, examine where learners struggle, strengthen the teaching and assessment chain, and document the result. A business school that proves reliability in ordinary academic work will have a stronger claim to expansion than one that announces a grand reform before its academic controls are steady.

The safeguards should be practical, not theatrical. A school can write impressive policy language and still fail if the record does not show how decisions were made. Risk control in global pressure on tertiary and executive education should therefore include admission notes, proof of prior learning where relevant, supervisor feedback, version history, source checking, originality review, and a final academic sign-off. These controls protect the learner as much as the institution. They reduce confusion, prevent unfair judgment, and make it possible to defend a decision if the award is questioned. The aim is a fair trail of evidence that shows the work earned its standing.

2.5 Sustaining reform at sector scale

Implementation should begin with the routines that most directly affect quality. In the global pressure on tertiary and executive education, the necessary disciplines are entry review, mentor assignment, milestone tracking, source control, writing feedback, and final review before public release.

Scale should follow demonstrated reliability. A school should expand only when it can show that ordinary teams, using ordinary resources, can maintain the same quality of guidance, record keeping, and assessment across cohorts.

Institutional learning must be built into the calendar. Each cohort should leave evidence about what worked, where learners struggled, which supervisors needed support, which assessment criteria were unclear, and which research outputs required deeper editorial care.

Implementation should be treated as evidence work. Each new routine should answer a practical question: did learners receive guidance on time, did assessors apply the standard consistently, did managers see the risk early enough, and did feedback alter the next cycle? Those questions protect academic seriousness better than any slogan about innovation.

Implementation should be judged by repetition under ordinary conditions. It is proven when the next cohort receives the same quality of guidance, when a different supervisor applies the same standard, when the review process catches weak evidence, and when the institution corrects defects without waiting for embarrassment. In global pressure on tertiary and executive education, learning must travel from one cycle into the next. That means keeping clear records, discussing failures openly, revising instructions, and training staff before scale creates pressure. This is the quieter work of institutional maturity, and it is where unconventional education either becomes credible or exposes its weakness.

It is worth being specific about what international pressure does and does not settle. Cross-national data can show that participation, cost, and technology are moving in the same direction across very different systems, which tells a leader that the pressure is structural rather than local. What such data cannot do is prescribe a single response, because a public university in one economy and a private executive provider in another face different constraints, learners, and accountabilities. The disciplined use of global evidence is to read it as a description of the operating environment, then design a response that fits the institution’s own mandate.

The equity dimension deserves direct attention rather than a footnote. Flexible, recognition-based routes are often the only realistic path for learners who were excluded from conventional study by cost, geography, or timing, which means that weak quality control falls hardest on the people the model was meant to serve. A reform that widens access while quietly lowering the value of the award has not advanced equity; it has relocated the disadvantage to the point of graduation, where it is harder to see and harder to undo.

No single element in this mix carries the model. Recognised prior learning widens access, mentored supervision protects rigor, applied projects connect study to work, and publication with defence supplies proof. The credibility of the approach depends on holding these elements together rather than promoting any one of them as a shortcut.


Figure 2. Unconventional business-school learning mix.


Chapter 3: Unconventional Higher Education: Concepts, Risks, and Quality Tests

3.1 Defining “unconventional” so it can be tested

Calling a model “unconventional” settles nothing until the term can be tested against practice. The real test is whether the institution changes the conditions under which learning is admitted, supervised, tested, and made useful. Unconventional education is not a shortcut; it is a different route to serious academic formation, built around flexibility, professional evidence, mentored inquiry, and demonstrated competence. A doctoral-level discussion must stay close to that operating reality.

This matters because professional learners do not enter business education as blank academic subjects. They arrive with work histories, managerial habits, uneven writing confidence, partial technical knowledge, and urgent career pressures. the important question is whether the school can prove that learning has taken place and that the award rests on evaluated work rather than attendance, payment, or rhetoric.

The test is therefore practical and academic at the same time. A claim about access must be supported by fair entry judgment. A claim about flexibility must be supported by supervision. A claim about research quality must be supported by sources, revision, and public accountability.

A weak model hides behind modern vocabulary. A serious model exposes itself to review. A non-traditional route loses legitimacy the moment it becomes vague about standards, credits, supervision, or academic responsibility.

This problem definition also requires a sharper reading of institutional behavior. In unconventional higher education, weak schools tend to describe access as generosity while avoiding the harder question of what support, review, and academic pressure the learner will meet after admission. Stronger institutions do not confuse open doors with serious education. They ask whether the learner can receive timely guidance, produce evidence, revise weak work, and graduate with a body of scholarship that another reviewer can respect. The claim is that inherited practice should justify itself. Where a fixed classroom strengthens discipline, it should remain. Where it simply protects habit, the school has a duty to redesign the learning route without lowering the standard. The chapter has to separate legitimate innovation from casual credentialing.

3.2 Evidence that separates innovation from drift

Evidence in this area should be handled with care. Public reports, institutional materials, employer signals, and education research can show pressure, but they cannot by themselves prove quality inside a school. The stronger academic move is to read those materials beside the lived mechanics of admission, supervision, assessment, and learner support.

For the meaning and limits of unconventional higher education, the useful evidence is the kind that changes judgment. It tells leaders where access is blocked, where professional learning is undervalued, where assessment is too narrow, and where digital delivery may expand reach without strengthening competence.

The analysis should not chase novelty. It should ask whether the learner can defend a position, use sources responsibly, recognize limits, connect theory to practice, and produce work that can stand outside the classroom. the important question is whether the school can prove that learning has taken place and that the award rests on evaluated work rather than attendance, payment, or rhetoric.

Professional judgment enters where data are incomplete. It is to build review routines that keep records, compare learner progress, protect standards, and correct weak practice before it becomes institutional habit.

Reports on digital learning, micro-credentials, executive education, labor-market change, and higher-education finance are useful because they show pressure on the sector, but they do not automatically validate any single institutional response. A serious reading asks what each source proves and what it cannot prove. Employer demand can show need, but not academic quality. Learner preference can show access pressure, but not competence. Publication output can show ambition, but only careful review can prove scholarly value. The value of unconventional higher education lies in connecting these different signals without exaggerating them. That disciplined reading gives the paper a more credible voice than broad praise for innovation would allow.

3.3 Decisions that protect academic quality

Management choices decide whether the meaning and limits of unconventional higher education becomes serious scholarship or promotional language. The decisive choices are often ordinary: who reviews entry evidence, who mentors the learner, who approves the research topic, who checks sources, who records feedback, and who has authority to stop weak work.

A school that serves experienced professionals needs firm routines without treating every learner as though their path is identical. Recognition of prior learning, workplace evidence, and flexible delivery require careful judgment, not loosened standards. The route may differ; the demand for intellectual quality should not.

The management burden also includes staff capacity. Mentors need time, training, and authority. Editorial review needs consistency. Learners need clear expectations. Employers and public readers need confidence that a published research paper represents supervised academic work rather than a private claim.

The safest path is not delay; it is disciplined sequencing. NYCAR’s case has value only if unconventional higher education remains accountable to learning, assessment, supervision, and public trust. That means testing the model through the details of delivery rather than relying on the attractiveness of the idea.

Management must then convert the argument into rules that staff can follow. In unconventional higher education, decision-making should not depend on personal goodwill or informal memory. Admission panels need records. Supervisors need workload limits. Assessors need common standards. Learners need written expectations. Editorial reviewers need authority to return weak work rather than rescue it at the end. Non-traditional routes, recognition of prior learning, and academic quality tests matter because they decide whether the model will be trusted after the marketing language has faded.

3.4 The characteristic risks of non-traditional models

Every unconventional model carries risk. A non-traditional route loses legitimacy the moment it becomes vague about standards, credits, supervision, or academic responsibility.

The main safeguards are visible admission criteria, documented recognition of prior learning, signed supervision records, source verification, clear assessment rubrics, independent review, and a process for correcting or withdrawing weak publication material when necessary.

There is also a reputational risk. A business school built around flexibility can be misunderstood as less serious if it fails to explain its evidence discipline. That misunderstanding cannot be answered by slogans. It must be answered by transparent standards and better work.

The ethical issue is equally important. Adult learners deserve opportunity, but they also deserve honesty. The institution should not sell ease as education. It should offer a demanding route that respects professional experience while insisting on academic proof.

The safeguards should be practical, not theatrical. A school can write impressive policy language and still fail if the record does not show how decisions were made. Risk control in unconventional higher education should therefore include admission notes, proof of prior learning where relevant, supervisor feedback, version history, source checking, originality review, and a final academic sign-off. These controls protect the learner as much as the institution. They reduce confusion, prevent unfair judgment, and make it possible to defend a decision if the award is questioned. The aim is a fair trail of evidence that shows the work earned its standing.

3.5 Embedding quality tests in daily practice

Implementation should begin with the routines that most directly affect quality. In the meaning and limits of unconventional higher education, the necessary disciplines are entry review, mentor assignment, milestone tracking, source control, writing feedback, and final review before public release.

Scale should follow demonstrated reliability. A school should expand only when it can show that ordinary teams, using ordinary resources, can maintain the same quality of guidance, record keeping, and assessment across cohorts.

Institutional learning must be built into the calendar. Each cohort should leave evidence about what worked, where learners struggled, which supervisors needed support, which assessment criteria were unclear, and which research outputs required deeper editorial care.

The practical conclusion is restrained but firm: unconventional business education becomes credible when the institution can repeat good judgment under normal conditions. the important question is whether the school can prove that learning has taken place and that the award rests on evaluated work rather than attendance, payment, or rhetoric.

Implementation should be judged by repetition under ordinary conditions. It is proven when the next cohort receives the same quality of guidance, when a different supervisor applies the same standard, when the review process catches weak evidence, and when the institution corrects defects without waiting for embarrassment. In unconventional higher education, learning must travel from one cycle into the next. That means keeping clear records, discussing failures openly, revising instructions, and training staff before scale creates pressure. This is the quieter work of institutional maturity, and it is where unconventional education either becomes credible or exposes its weakness.

The quality test becomes clearer when it is applied to a borderline case. Consider a provider that grants generous recognition of prior learning, delivers entirely online, and assesses through a single capstone. None of these features is disqualifying, yet together they concentrate risk at the points where evidence is thinnest. A serious quality test does not ban such a design; it asks how each thin point is reinforced, whether recognition decisions are documented, whether online delivery preserves supervision, and whether the capstone is defended rather than merely submitted. The model is judged by how it manages its own weak points.

It is worth separating genuine innovation from credential inflation, because the two can look alike from outside. A new delivery format, a shorter cycle, or a stackable set of micro-credentials can each represent real pedagogical progress or merely a faster route to a thinner award. The distinguishing question is always evidentiary: does the learner finish able to do and defend more than before, or only holding more certificates? Concepts that cannot answer that question are fashion, and fashion is the most expensive thing a serious institution can buy.

The controls are arranged as a sequence because each one leaves a record that the next can rely on. Admission evidence is of little use if supervision is undocumented, and supervision is fragile if the final sign-off cannot trace the work back through review. The point is not the number of controls but the unbroken trail they create.


Figure 3. Quality controls for non-traditional delivery.


Read from the bottom upward, the value to a professional learner is cumulative. Recognition of experience opens the door, a mentored route makes study feasible, evidence of competence replaces seat time, and defensible scholarship converts effort into standing that an employer or a peer can respect. A model that delivers only the lower layers has not yet earned the upper ones.


Figure 4. Learner value proposition.


Table 1. Unconventional business-school model

Element Conventional weakness Unconventional correction
Admission Overreliance on prior institutional path Recognise professional evidence and recognition of prior learning
Assessment Exam-centred performance Portfolio, capstone, publication, and defence
Curriculum Slow response to market change Modular revision and employer-facing topics
Delivery Campus-bound timetable Blended, mentored, asynchronous support
Quality Reputation assumed by form Quality shown through evidence and review

Note. Black-and-white NYCAR publication format.


Chapter 4: NYCAR as an Applied Case of Research-Led Professional Learning

4.1 What the NYCAR case is meant to show

A case study earns its place only when it exposes how an institution actually behaves. The real test is whether the institution changes the conditions under which learning is admitted, supervised, tested, and made useful. The case is strongest when it is read as an institutional experiment in applied scholarship: flexible delivery, publication-centered research, professional reflection, and public-facing academic output. A doctoral-level discussion must stay close to that operating reality.

This matters because professional learners do not enter business education as blank academic subjects. They arrive with work histories, managerial habits, uneven writing confidence, partial technical knowledge, and urgent career pressures. NYCAR should be assessed by evidence of mentoring, source discipline, learner progression, publication quality, and the usefulness of research to professional practice.

The test is therefore practical and academic at the same time. A claim about access must be supported by fair entry judgment. A claim about flexibility must be supported by supervision. A claim about research quality must be supported by sources, revision, and public accountability.

A weak model hides behind modern vocabulary. A serious model exposes itself to review. The school must guard against confusing visibility with credibility; its value depends on the quality of the work it releases and the care behind each award.

This problem definition also requires a sharper reading of institutional behavior. In NYCAR as an applied case, weak schools tend to describe access as generosity while avoiding the harder question of what support, review, and academic pressure the learner will meet after admission. Stronger institutions do not confuse open doors with serious education. They ask whether the learner can receive timely guidance, produce evidence, revise weak work, and graduate with a body of scholarship that another reviewer can respect. The claim is that inherited practice should justify itself. Where a fixed classroom strengthens discipline, it should remain. Where it simply protects habit, the school has a duty to redesign the learning route without lowering the standard. The case is useful because it gives the argument a real institutional setting rather than a distant theory.

4.2 Reading NYCAR’s practice as evidence

Evidence in this area should be handled with care. Public reports, institutional materials, employer signals, and education research can show pressure, but they cannot by themselves prove quality inside a school. The stronger academic move is to read those materials beside the lived mechanics of admission, supervision, assessment, and learner support.

For NYCAR as an applied case of research-led professional learning, the useful evidence is the kind that changes judgment. It tells leaders where access is blocked, where professional learning is undervalued, where assessment is too narrow, and where digital delivery may expand reach without strengthening competence.

The analysis should not chase novelty. It should ask whether the learner can defend a position, use sources responsibly, recognize limits, connect theory to practice, and produce work that can stand outside the classroom. NYCAR should be assessed by evidence of mentoring, source discipline, learner progression, publication quality, and the usefulness of research to professional practice.

Professional judgment enters where data are incomplete. It is to build review routines that keep records, compare learner progress, protect standards, and correct weak practice before it becomes institutional habit.

Reports on digital learning, micro-credentials, executive education, labor-market change, and higher-education finance are useful because they show pressure on the sector, but they do not automatically validate any single institutional response. A serious reading asks what each source proves and what it cannot prove. Employer demand can show need, but not academic quality. Learner preference can show access pressure, but not competence. Publication output can show ambition, but only careful review can prove scholarly value. The value of NYCAR as an applied case lies in connecting these different signals without exaggerating them. That disciplined reading gives the paper a more credible voice than broad praise for innovation would allow.

4.3 Management behind research-led learning

Management choices decide whether NYCAR as an applied case of research-led professional learning becomes serious scholarship or promotional language. The decisive choices are often ordinary: who reviews entry evidence, who mentors the learner, who approves the research topic, who checks sources, who records feedback, and who has authority to stop weak work.

A school that serves experienced professionals needs firm routines without treating every learner as though their path is identical. Recognition of prior learning, workplace evidence, and flexible delivery require careful judgment, not loosened standards. The route may differ; the demand for intellectual quality should not.

The management burden also includes staff capacity. Mentors need time, training, and authority. Editorial review needs consistency. Learners need clear expectations. Employers and public readers need confidence that a published research paper represents supervised academic work rather than a private claim.

The outcome is decided by institutional habits. The school must guard against confusing visibility with credibility; its value depends on the quality of the work it releases and the care behind each award That is why the school must connect promise to records, supervision, review, and correction.

Management must then convert the argument into rules that staff can follow. In NYCAR as an applied case, decision-making should not depend on personal goodwill or informal memory. Admission panels need records. Supervisors need workload limits. Assessors need common standards. Learners need written expectations. Editorial reviewers need authority to return weak work rather than rescue it at the end. Research-led professional learning, publication practice, and supervised academic output matter because they decide whether the model will be trusted after the marketing language has faded.

4.4 Risks specific to an applied institutional case

Every unconventional model carries risk. The school must guard against confusing visibility with credibility; its value depends on the quality of the work it releases and the care behind each award.

The main safeguards are visible admission criteria, documented recognition of prior learning, signed supervision records, source verification, clear assessment rubrics, independent review, and a process for correcting or withdrawing weak publication material when necessary.

There is also a reputational risk. A business school built around flexibility can be misunderstood as less serious if it fails to explain its evidence discipline. That misunderstanding cannot be answered by slogans. It must be answered by transparent standards and better work.

A business school that wants to depart from convention must be stricter about evidence, not looser. The routine should show who was admitted, what prior learning was accepted, how learning was assessed, where support failed, and how managers corrected the fault. This kind of record gives reform its legitimacy.

The safeguards should be practical, not theatrical. A school can write impressive policy language and still fail if the record does not show how decisions were made. Risk control in NYCAR as an applied case should therefore include admission notes, proof of prior learning where relevant, supervisor feedback, version history, source checking, originality review, and a final academic sign-off. These controls protect the learner as much as the institution. They reduce confusion, prevent unfair judgment, and make it possible to defend a decision if the award is questioned. The aim is a fair trail of evidence that shows the work earned its standing.

4.5 Turning the NYCAR model into repeatable routine

Implementation should begin with the routines that most directly affect quality. In NYCAR as an applied case of research-led professional learning, the necessary disciplines are entry review, mentor assignment, milestone tracking, source control, writing feedback, and final review before public release.

Scale should follow demonstrated reliability. A school should expand only when it can show that ordinary teams, using ordinary resources, can maintain the same quality of guidance, record keeping, and assessment across cohorts.

Institutional learning must be built into the calendar. Each cohort should leave evidence about what worked, where learners struggled, which supervisors needed support, which assessment criteria were unclear, and which research outputs required deeper editorial care.

The practical conclusion is restrained but firm: unconventional business education becomes credible when the institution can repeat good judgment under normal conditions. NYCAR should be assessed by evidence of mentoring, source discipline, learner progression, publication quality, and the usefulness of research to professional practice.

Implementation should be judged by repetition under ordinary conditions. It is proven when the next cohort receives the same quality of guidance, when a different supervisor applies the same standard, when the review process catches weak evidence, and when the institution corrects defects without waiting for embarrassment. In NYCAR as an applied case, learning must travel from one cycle into the next. That means keeping clear records, discussing failures openly, revising instructions, and training staff before scale creates pressure. This is the quieter work of institutional maturity, and it is where unconventional education either becomes credible or exposes its weakness.

The value of the NYCAR case is not that it is flawless but that it is observable. An applied case is only useful to other institutions if its routines can be inspected and, where appropriate, copied or criticised. Treating NYCAR this way keeps the analysis honest, because claims about research-led professional learning are tied to specific practices in admission, supervision, and publication rather than to reputation. A case that cannot be examined in this way offers inspiration but little transferable evidence, and transferable evidence is what a doctoral analysis owes its readers.

Honesty about the case also means stating what would weaken it. The NYCAR argument would be undermined if its admission judgements could not be reconstructed, if supervision existed mainly on paper, or if published outputs were not genuinely reviewed. Naming these failure conditions is not a hedge; it is what separates an applied case from an advertisement. A reader should be able to test the case against those conditions, and an institution confident in its routines should welcome exactly that scrutiny.

The stages are ordered deliberately. A school that scales before it has proven reliability simply multiplies its weaknesses, while one that diagnoses and pilots without embedding routines never moves past pilot energy. Movement from one stage to the next should be earned with evidence rather than announced on a schedule.


Figure 5. Business-school transformation stages.


Chapter 5: Business-School Relevance, Employers, and Lifelong Learning

5.1 The relevance gap employers actually feel

Relevance is not won by claiming it; employers and learners feel its absence quickly. The real test is whether the institution changes the conditions under which learning is admitted, supervised, tested, and made useful. Employers increasingly need graduates who can interpret evidence, write clearly, manage risk, lead teams, and solve problems across changing markets rather than repeat textbook language. A doctoral-level discussion must stay close to that operating reality.

This matters because professional learners do not enter business education as blank academic subjects. They arrive with work histories, managerial habits, uneven writing confidence, partial technical knowledge, and urgent career pressures. a serious business school earns value when its learning changes workplace judgment and gives organizations better decisions, not just certificates.

The test is therefore practical and academic at the same time. A claim about access must be supported by fair entry judgment. A claim about flexibility must be supported by supervision. A claim about research quality must be supported by sources, revision, and public accountability.

A weak model hides behind modern vocabulary. A serious model exposes itself to review. An employability claim becomes weak when the school cannot show how assessment connects to managerial competence, ethical judgment, and problem-solving under pressure.

This problem definition also requires a sharper reading of institutional behavior. In business-school relevance, weak schools tend to describe access as generosity while avoiding the harder question of what support, review, and academic pressure the learner will meet after admission. Stronger institutions do not confuse open doors with serious education. They ask whether the learner can receive timely guidance, produce evidence, revise weak work, and graduate with a body of scholarship that another reviewer can respect. The claim is that inherited practice should justify itself. Where a fixed classroom strengthens discipline, it should remain. Where it simply protects habit, the school has a duty to redesign the learning route without lowering the standard. The discussion should keep returning to what a business school enables a graduate to do with evidence and responsibility.

5.2 Evidence on skills, demand, and lifelong learning

Evidence in this area should be handled with care. Public reports, institutional materials, employer signals, and education research can show pressure, but they cannot by themselves prove quality inside a school. The stronger academic move is to read those materials beside the lived mechanics of admission, supervision, assessment, and learner support.

For business-school relevance, employers, and lifelong learning, the useful evidence is the kind that changes judgment. It tells leaders where access is blocked, where professional learning is undervalued, where assessment is too narrow, and where digital delivery may expand reach without strengthening competence.

The analysis should not chase novelty. It should ask whether the learner can defend a position, use sources responsibly, recognize limits, connect theory to practice, and produce work that can stand outside the classroom. a serious business school earns value when its learning changes workplace judgment and gives organizations better decisions, not just certificates.

Professional judgment enters where data are incomplete. It is to build review routines that keep records, compare learner progress, protect standards, and correct weak practice before it becomes institutional habit.

Reports on digital learning, micro-credentials, executive education, labor-market change, and higher-education finance are useful because they show pressure on the sector, but they do not automatically validate any single institutional response. A serious reading asks what each source proves and what it cannot prove. Employer demand can show need, but not academic quality. Learner preference can show access pressure, but not competence. Publication output can show ambition, but only careful review can prove scholarly value. The value of business-school relevance lies in connecting these different signals without exaggerating them. That disciplined reading gives the paper a more credible voice than broad praise for innovation would allow.

5.3 Aligning the school with professional need

Management choices decide whether business-school relevance, employers, and lifelong learning becomes serious scholarship or promotional language. The decisive choices are often ordinary: who reviews entry evidence, who mentors the learner, who approves the research topic, who checks sources, who records feedback, and who has authority to stop weak work.

A school that serves experienced professionals needs firm routines without treating every learner as though their path is identical. Recognition of prior learning, workplace evidence, and flexible delivery require careful judgment, not loosened standards. The route may differ; the demand for intellectual quality should not.

The management burden also includes staff capacity. Mentors need time, training, and authority. Editorial review needs consistency. Learners need clear expectations. Employers and public readers need confidence that a published research paper represents supervised academic work rather than a private claim.

The outcome is decided by institutional habits. An employability claim becomes weak when the school cannot show how assessment connects to managerial competence, ethical judgment, and problem-solving under pressure That is why the school must connect promise to records, supervision, review, and correction.

Management must then convert the argument into rules that staff can follow. In business-school relevance, decision-making should not depend on personal goodwill or informal memory. Admission panels need records. Supervisors need workload limits. Assessors need common standards. Learners need written expectations. Editorial reviewers need authority to return weak work rather than rescue it at the end. Employer value, workplace judgment, and lifelong professional learning matter because they decide whether the model will be trusted after the marketing language has faded.

5.4 The risk of chasing employer demand

Every unconventional model carries risk. An employability claim becomes weak when the school cannot show how assessment connects to managerial competence, ethical judgment, and problem-solving under pressure.

The main safeguards are visible admission criteria, documented recognition of prior learning, signed supervision records, source verification, clear assessment rubrics, independent review, and a process for correcting or withdrawing weak publication material when necessary.

There is also a reputational risk. A business school built around flexibility can be misunderstood as less serious if it fails to explain its evidence discipline. That misunderstanding cannot be answered by slogans. It must be answered by transparent standards and better work.

The ethical issue is equally important. Adult learners deserve opportunity, but they also deserve honesty. The institution should not sell ease as education. It should offer a demanding route that respects professional experience while insisting on academic proof.

The safeguards should be practical, not theatrical. A school can write impressive policy language and still fail if the record does not show how decisions were made. Risk control in business-school relevance should therefore include admission notes, proof of prior learning where relevant, supervisor feedback, version history, source checking, originality review, and a final academic sign-off. These controls protect the learner as much as the institution. They reduce confusion, prevent unfair judgment, and make it possible to defend a decision if the award is questioned. The aim is a fair trail of evidence that shows the work earned its standing.

5.5 Building durable employer and learner partnerships

Implementation should begin with the routines that most directly affect quality. In business-school relevance, employers, and lifelong learning, the necessary disciplines are entry review, mentor assignment, milestone tracking, source control, writing feedback, and final review before public release.

Scale should follow demonstrated reliability. A school should expand only when it can show that ordinary teams, using ordinary resources, can maintain the same quality of guidance, record keeping, and assessment across cohorts.

Institutional learning must be built into the calendar. Each cohort should leave evidence about what worked, where learners struggled, which supervisors needed support, which assessment criteria were unclear, and which research outputs required deeper editorial care.

Expansion should follow academic proof. Where learner support, faculty supervision, assessment review, and employer relevance are working, the model can grow. Where those routines are weak, expansion would only multiply a defect. Responsible reform knows the difference.

Implementation should be judged by repetition under ordinary conditions. It is proven when the next cohort receives the same quality of guidance, when a different supervisor applies the same standard, when the review process catches weak evidence, and when the institution corrects defects without waiting for embarrassment. In business-school relevance, learning must travel from one cycle into the next. That means keeping clear records, discussing failures openly, revising instructions, and training staff before scale creates pressure. This is the quieter work of institutional maturity, and it is where unconventional education either becomes credible or exposes its weakness.

Relevance also has a time dimension that schools often underestimate. A curriculum that matches today’s employer language can be obsolete by the time a cohort graduates, which is why responsiveness must be built into structure rather than achieved through one redesign. Modular revision, employer advisory input, and graduates who report back from practice turn relevance into a renewable property of the institution. Lifelong learning, understood this way, is less a product the school sells than a relationship it maintains, and the difference shows in whether alumni return.

Closeness to employers carries its own risk, which is the loss of academic independence. A school that simply trains to the current demands of a few large employers may produce graduates who are useful this year and stranded the next, and it surrenders the critical distance that lets scholarship question practice rather than only serve it. The stronger relationship treats employer signals as important evidence about relevance while reserving the right, and the duty, to teach what practitioners will need but are not yet asking for.

Forms of assessment differ in what they can prove. A timed examination can confirm recall under pressure; a supervised publication and defence can demonstrate sustained reasoning, source discipline, and the ability to answer challenge. An assessment system should match the strength of its evidence to the seriousness of the claim it certifies.


Figure 6. Assessment evidence strength.


Chapter 6: Assessment Beyond Exams: Evidence, Publication, and Practice

6.1 Why the exam alone no longer proves competence

The timed examination has carried more weight than it can honestly bear. The real test is whether the institution changes the conditions under which learning is admitted, supervised, tested, and made useful. Examinations still have a place, but professional higher education also needs portfolios, supervised projects, policy analysis, case interpretation, research writing, and reflective evidence that can be reviewed. A doctoral-level discussion must stay close to that operating reality.

This matters because professional learners do not enter business education as blank academic subjects. They arrive with work histories, managerial habits, uneven writing confidence, partial technical knowledge, and urgent career pressures. a publication-centered approach can be rigorous if it demands verifiable sources, defensible argument, supervision records, revision discipline, and a clear standard for originality.

The test is therefore practical and academic at the same time. A claim about access must be supported by fair entry judgment. A claim about flexibility must be supported by supervision. A claim about research quality must be supported by sources, revision, and public accountability.

A weak model hides behind modern vocabulary. A serious model exposes itself to review. Alternative assessment fails when it becomes sentimental about experience and does not test the quality of thought, evidence, writing, and application.

This problem definition also requires a sharper reading of institutional behavior. In assessment beyond examinations, weak schools tend to describe access as generosity while avoiding the harder question of what support, review, and academic pressure the learner will meet after admission. Stronger institutions do not confuse open doors with serious education. They ask whether the learner can receive timely guidance, produce evidence, revise weak work, and graduate with a body of scholarship that another reviewer can respect. The claim is that inherited practice should justify itself. Where a fixed classroom strengthens discipline, it should remain. Where it simply protects habit, the school has a duty to redesign the learning route without lowering the standard. Assessment must show the learner’s mind at work, not only memory under exam conditions.

6.2 Evidence on portfolios, publication, and defence

Evidence in this area should be handled with care. Public reports, institutional materials, employer signals, and education research can show pressure, but they cannot by themselves prove quality inside a school. The stronger academic move is to read those materials beside the lived mechanics of admission, supervision, assessment, and learner support.

For assessment beyond examinations, the useful evidence is the kind that changes judgment. It tells leaders where access is blocked, where professional learning is undervalued, where assessment is too narrow, and where digital delivery may expand reach without strengthening competence.

The analysis should not chase novelty. It should ask whether the learner can defend a position, use sources responsibly, recognize limits, connect theory to practice, and produce work that can stand outside the classroom. a publication-centered approach can be rigorous if it demands verifiable sources, defensible argument, supervision records, revision discipline, and a clear standard for originality.

Professional judgment enters where data are incomplete. It is to build review routines that keep records, compare learner progress, protect standards, and correct weak practice before it becomes institutional habit.

Reports on digital learning, micro-credentials, executive education, labor-market change, and higher-education finance are useful because they show pressure on the sector, but they do not automatically validate any single institutional response. A serious reading asks what each source proves and what it cannot prove. Employer demand can show need, but not academic quality. Learner preference can show access pressure, but not competence. Publication output can show ambition, but only careful review can prove scholarly value. The value of assessment beyond examinations lies in connecting these different signals without exaggerating them. That disciplined reading gives the paper a more credible voice than broad praise for innovation would allow.

6.3 Designing assessment that carries weight

Management choices decide whether assessment beyond examinations becomes serious scholarship or promotional language. The decisive choices are often ordinary: who reviews entry evidence, who mentors the learner, who approves the research topic, who checks sources, who records feedback, and who has authority to stop weak work.

A school that serves experienced professionals needs firm routines without treating every learner as though their path is identical. Recognition of prior learning, workplace evidence, and flexible delivery require careful judgment, not loosened standards. The route may differ; the demand for intellectual quality should not.

The management burden also includes staff capacity. Mentors need time, training, and authority. Editorial review needs consistency. Learners need clear expectations. Employers and public readers need confidence that a published research paper represents supervised academic work rather than a private claim.

The outcome is decided by institutional habits. Alternative assessment fails when it becomes sentimental about experience and does not test the quality of thought, evidence, writing, and application That is why the school must connect promise to records, supervision, review, and correction.

Management must then convert the argument into rules that staff can follow. In assessment beyond examinations, decision-making should not depend on personal goodwill or informal memory. Admission panels need records. Supervisors need workload limits. Assessors need common standards. Learners need written expectations. Editorial reviewers need authority to return weak work rather than rescue it at the end. Portfolio evidence, publication-quality research, case analysis, and practical judgment matter because they decide whether the model will be trusted after the marketing language has faded.

6.4 Integrity risks in evidence-based assessment

Every unconventional model carries risk. Alternative assessment fails when it becomes sentimental about experience and does not test the quality of thought, evidence, writing, and application.

The main safeguards are visible admission criteria, documented recognition of prior learning, signed supervision records, source verification, clear assessment rubrics, independent review, and a process for correcting or withdrawing weak publication material when necessary.

There is also a reputational risk. A business school built around flexibility can be misunderstood as less serious if it fails to explain its evidence discipline. That misunderstanding cannot be answered by slogans. It must be answered by transparent standards and better work.

The ethical issue is equally important. Adult learners deserve opportunity, but they also deserve honesty. The institution should not sell ease as education. It should offer a demanding route that respects professional experience while insisting on academic proof.

The safeguards should be practical, not theatrical. A school can write impressive policy language and still fail if the record does not show how decisions were made. Risk control in assessment beyond examinations should therefore include admission notes, proof of prior learning where relevant, supervisor feedback, version history, source checking, originality review, and a final academic sign-off. These controls protect the learner as much as the institution. They reduce confusion, prevent unfair judgment, and make it possible to defend a decision if the award is questioned. The aim is a fair trail of evidence that shows the work earned its standing.

6.5 Operating an assessment system that holds

Implementation should begin with the routines that most directly affect quality. In assessment beyond examinations, the necessary disciplines are entry review, mentor assignment, milestone tracking, source control, writing feedback, and final review before public release.

Scale should follow demonstrated reliability. A school should expand only when it can show that ordinary teams, using ordinary resources, can maintain the same quality of guidance, record keeping, and assessment across cohorts.

Institutional learning must be built into the calendar. Each cohort should leave evidence about what worked, where learners struggled, which supervisors needed support, which assessment criteria were unclear, and which research outputs required deeper editorial care.

The practical conclusion is restrained but firm: unconventional business education becomes credible when the institution can repeat good judgment under normal conditions. a publication-centered approach can be rigorous if it demands verifiable sources, defensible argument, supervision records, revision discipline, and a clear standard for originality.

Implementation should be judged by repetition under ordinary conditions. It is proven when the next cohort receives the same quality of guidance, when a different supervisor applies the same standard, when the review process catches weak evidence, and when the institution corrects defects without waiting for embarrassment. In assessment beyond examinations, learning must travel from one cycle into the next. That means keeping clear records, discussing failures openly, revising instructions, and training staff before scale creates pressure. This is the quieter work of institutional maturity, and it is where unconventional education either becomes credible or exposes its weakness.

Assessment design carries an ethical weight that is easy to miss. When a school certifies competence, it is making a promise to third parties who will never see the work: the employer who hires the graduate, the client who trusts the advice, the public that relies on the profession. An assessment that proves little exposes those third parties to risk while protecting the institution’s own throughput. Evidence-rich assessment is therefore not only more rigorous; it is more honest about the people who depend on the credential long after the cohort has moved on.

Rich assessment is not free, and pretending otherwise sets a reform up to fail. Portfolios, supervised publication, and oral defence demand more staff time, clearer rubrics, and more careful moderation than a single examination, and a school that adopts them without resourcing them will quietly retreat to easier methods under pressure. Designing assessment honestly therefore includes designing its workload, so that the evidence the institution promises to gather is evidence it can actually sustain across every cohort.

Governance attention is a scarce resource, and this simple map helps place it where consequence and likelihood are both high. Low-consequence routines can be maintained and monitored; the risks that combine a high likelihood of failure with serious academic consequence are the ones that justify immediate governance action rather than periodic review.


Figure 7. Academic governance attention.


Readiness is shown by routines that generate evidence, not by statements of intent. Each indicator here corresponds to something an external reviewer could inspect: admission notes, supervision records, assessment design, publication integrity, governance lines, and a working correction loop. The case is strong to the degree that these can be demonstrated rather than asserted.


Figure 8. NYCAR case-readiness indicators.


Table 2. NYCAR case-study quality test

Quality domain Question Evidence
Access Who is included without lowering standards? Admissions and recognition of prior learning records
Rigour How is mastery proven? Research output and examiner notes
Mentorship How are learners supported? Supervision logs
Integrity How is authorship protected? Similarity, source and defence records
Impact How does work enter practice? Publication and professional application

Note. Black-and-white NYCAR publication format.


Chapter 7: Digital Delivery, AI, Mentorship, and Academic Integrity

7.1 The integrity problem behind digital delivery

Digital delivery raises a question of trust long before it raises a question of technology. The real test is whether the institution changes the conditions under which learning is admitted, supervised, tested, and made useful. Digital learning can widen access, but the academic value comes from design of contact, supervision, feedback, and integrity checks rather than from the platform alone. A doctoral-level discussion must stay close to that operating reality.

This matters because professional learners do not enter business education as blank academic subjects. They arrive with work histories, managerial habits, uneven writing confidence, partial technical knowledge, and urgent career pressures. artificial intelligence should be treated as a controlled academic tool: useful for support, dangerous when it replaces reading, reasoning, authorship, or source judgment.

The test is therefore practical and academic at the same time. A claim about access must be supported by fair entry judgment. A claim about flexibility must be supported by supervision. A claim about research quality must be supported by sources, revision, and public accountability.

A weak model hides behind modern vocabulary. A serious model exposes itself to review. The greatest threat is not technology; it is the absence of responsible supervision when technology makes low-quality production easier.

This problem definition also requires a sharper reading of institutional behavior. In digital delivery and artificial intelligence, weak schools tend to describe access as generosity while avoiding the harder question of what support, review, and academic pressure the learner will meet after admission. Stronger institutions do not confuse open doors with serious education. They ask whether the learner can receive timely guidance, produce evidence, revise weak work, and graduate with a body of scholarship that another reviewer can respect. The claim is that inherited practice should justify itself. Where a fixed classroom strengthens discipline, it should remain. Where it simply protects habit, the school has a duty to redesign the learning route without lowering the standard. Technology should support academic work without taking over authorship or weakening supervision.

7.2 Evidence on AI, mentorship, and learning quality

Evidence in this area should be handled with care. Public reports, institutional materials, employer signals, and education research can show pressure, but they cannot by themselves prove quality inside a school. The stronger academic move is to read those materials beside the lived mechanics of admission, supervision, assessment, and learner support.

For digital delivery, artificial intelligence, mentorship, and academic integrity, the useful evidence is the kind that changes judgment. It tells leaders where access is blocked, where professional learning is undervalued, where assessment is too narrow, and where digital delivery may expand reach without strengthening competence.

The analysis should not chase novelty. It should ask whether the learner can defend a position, use sources responsibly, recognize limits, connect theory to practice, and produce work that can stand outside the classroom. artificial intelligence should be treated as a controlled academic tool: useful for support, dangerous when it replaces reading, reasoning, authorship, or source judgment.

Professional judgment enters where data are incomplete. It is to build review routines that keep records, compare learner progress, protect standards, and correct weak practice before it becomes institutional habit.

Reports on digital learning, micro-credentials, executive education, labor-market change, and higher-education finance are useful because they show pressure on the sector, but they do not automatically validate any single institutional response. A serious reading asks what each source proves and what it cannot prove. Employer demand can show need, but not academic quality. Learner preference can show access pressure, but not competence. Publication output can show ambition, but only careful review can prove scholarly value. The value of digital delivery and artificial intelligence lies in connecting these different signals without exaggerating them. That disciplined reading gives the paper a more credible voice than broad praise for innovation would allow.

7.3 Governing technology as an academic decision

Management choices decide whether digital delivery, artificial intelligence, mentorship, and academic integrity becomes serious scholarship or promotional language. The decisive choices are often ordinary: who reviews entry evidence, who mentors the learner, who approves the research topic, who checks sources, who records feedback, and who has authority to stop weak work.

A school that serves experienced professionals needs firm routines without treating every learner as though their path is identical. Recognition of prior learning, workplace evidence, and flexible delivery require careful judgment, not loosened standards. The route may differ; the demand for intellectual quality should not.

The management burden also includes staff capacity. Mentors need time, training, and authority. Editorial review needs consistency. Learners need clear expectations. Employers and public readers need confidence that a published research paper represents supervised academic work rather than a private claim.

The outcome is decided by institutional habits. The greatest threat is not technology; it is the absence of responsible supervision when technology makes low-quality production easier That is why the school must connect promise to records, supervision, review, and correction.

Management must then convert the argument into rules that staff can follow. In digital delivery and artificial intelligence, decision-making should not depend on personal goodwill or informal memory. Admission panels need records. Supervisors need workload limits. Assessors need common standards. Learners need written expectations. Editorial reviewers need authority to return weak work rather than rescue it at the end. Online access, mentorship, academic integrity, and responsible use of tools matter because they decide whether the model will be trusted after the marketing language has faded.

7.4 The risks AI introduces to academic trust

Every unconventional model carries risk. The greatest threat is not technology; it is the absence of responsible supervision when technology makes low-quality production easier.

The main safeguards are visible admission criteria, documented recognition of prior learning, signed supervision records, source verification, clear assessment rubrics, independent review, and a process for correcting or withdrawing weak publication material when necessary.

There is also a reputational risk. A business school built around flexibility can be misunderstood as less serious if it fails to explain its evidence discipline. That misunderstanding cannot be answered by slogans. It must be answered by transparent standards and better work.

The lesson for leaders is straightforward: make the operating routine visible before celebrating the reform. A short, honest review of learner progress, staff capacity, assessment quality, and employer response will do more for institutional credibility than a broad statement that cannot be tested.

The safeguards should be practical, not theatrical. A school can write impressive policy language and still fail if the record does not show how decisions were made. Risk control in digital delivery and artificial intelligence should therefore include admission notes, proof of prior learning where relevant, supervisor feedback, version history, source checking, originality review, and a final academic sign-off. These controls protect the learner as much as the institution. They reduce confusion, prevent unfair judgment, and make it possible to defend a decision if the award is questioned. The aim is a fair trail of evidence that shows the work earned its standing.

7.5 Sustaining integrity as delivery scales

Implementation should begin with the routines that most directly affect quality. In digital delivery, artificial intelligence, mentorship, and academic integrity, the necessary disciplines are entry review, mentor assignment, milestone tracking, source control, writing feedback, and final review before public release.

Scale should follow demonstrated reliability. A school should expand only when it can show that ordinary teams, using ordinary resources, can maintain the same quality of guidance, record keeping, and assessment across cohorts.

Institutional learning must be built into the calendar. Each cohort should leave evidence about what worked, where learners struggled, which supervisors needed support, which assessment criteria were unclear, and which research outputs required deeper editorial care.

The practical conclusion is restrained but firm: unconventional business education becomes credible when the institution can repeat good judgment under normal conditions. artificial intelligence should be treated as a controlled academic tool: useful for support, dangerous when it replaces reading, reasoning, authorship, or source judgment.

Implementation should be judged by repetition under ordinary conditions. It is proven when the next cohort receives the same quality of guidance, when a different supervisor applies the same standard, when the review process catches weak evidence, and when the institution corrects defects without waiting for embarrassment. In digital delivery and artificial intelligence, learning must travel from one cycle into the next. That means keeping clear records, discussing failures openly, revising instructions, and training staff before scale creates pressure. This is the quieter work of institutional maturity, and it is where unconventional education either becomes credible or exposes its weakness.

The integrity challenge of digital and AI-assisted delivery is best handled as a question of evidence rather than prohibition. It is increasingly hard to prove that a polished submission is the learner’s own unaided work, so the stronger response is to assess in ways that resist outsourcing: supervised drafting, oral defence, iterative feedback that shows a line of development, and tasks anchored in the learner’s own professional context. Technology is not the enemy of integrity here; an assessment design that ignores how learners now work is the real exposure.

Digital delivery also raises questions about data and the learner record that governance cannot ignore. The same systems that make supervision and originality visible also accumulate detailed information about how learners study, which must be held securely, used proportionately, and protected from drifting into surveillance. Academic integrity and learner privacy are usually discussed separately, yet they meet in the same record, and a school that protects one while neglecting the other has only solved half of the trust problem.

Chapter 8: Governance Model for Unconventional Business Schools

8.1 The governance question reform cannot avoid

Governance is the part of reform that institutions are most tempted to leave vague. The real test is whether the institution changes the conditions under which learning is admitted, supervised, tested, and made useful. Governance in this field must make standards visible: admissions, recognition of prior learning, supervision, assessment, complaints, records, faculty roles, and publication clearance all need accountable ownership. A doctoral-level discussion must stay close to that operating reality.

This matters because professional learners do not enter business education as blank academic subjects. They arrive with work histories, managerial habits, uneven writing confidence, partial technical knowledge, and urgent career pressures. a flexible institution needs more documentation, not less, because public confidence depends on showing how decisions were made.

The test is therefore practical and academic at the same time. A claim about access must be supported by fair entry judgment. A claim about flexibility must be supported by supervision. A claim about research quality must be supported by sources, revision, and public accountability.

The model should mature through learning rather than public performance. Each cohort should leave behind evidence about what worked, what failed, what support was missing, and which rules need revision. Without that institutional memory, unconventional higher education becomes improvisation with academic language attached.

This problem definition also requires a sharper reading of institutional behavior. In governance for unconventional business schools, weak schools tend to describe access as generosity while avoiding the harder question of what support, review, and academic pressure the learner will meet after admission. Stronger institutions do not confuse open doors with serious education. They ask whether the learner can receive timely guidance, produce evidence, revise weak work, and graduate with a body of scholarship that another reviewer can respect. The claim is that inherited practice should justify itself. Where a fixed classroom strengthens discipline, it should remain. Where it simply protects habit, the school has a duty to redesign the learning route without lowering the standard. Governance is where the flexible model proves that it has standards capable of public defense.

8.2 Evidence on what governance must control

Evidence in this area should be handled with care. Public reports, institutional materials, employer signals, and education research can show pressure, but they cannot by themselves prove quality inside a school. The stronger academic move is to read those materials beside the lived mechanics of admission, supervision, assessment, and learner support.

For governance for unconventional business schools, the useful evidence is the kind that changes judgment. It tells leaders where access is blocked, where professional learning is undervalued, where assessment is too narrow, and where digital delivery may expand reach without strengthening competence.

The analysis should not chase novelty. It should ask whether the learner can defend a position, use sources responsibly, recognize limits, connect theory to practice, and produce work that can stand outside the classroom. a flexible institution needs more documentation, not less, because public confidence depends on showing how decisions were made.

Professional judgment enters where data are incomplete. It is to build review routines that keep records, compare learner progress, protect standards, and correct weak practice before it becomes institutional habit.

Reports on digital learning, micro-credentials, executive education, labor-market change, and higher-education finance are useful because they show pressure on the sector, but they do not automatically validate any single institutional response. A serious reading asks what each source proves and what it cannot prove. Employer demand can show need, but not academic quality. Learner preference can show access pressure, but not competence. Publication output can show ambition, but only careful review can prove scholarly value. The value of governance for unconventional business schools lies in connecting these different signals without exaggerating them. That disciplined reading gives the paper a more credible voice than broad praise for innovation would allow.

8.3 Allocating authority and accountability

Management choices decide whether governance for unconventional business schools becomes serious scholarship or promotional language. The decisive choices are often ordinary: who reviews entry evidence, who mentors the learner, who approves the research topic, who checks sources, who records feedback, and who has authority to stop weak work.

A school that serves experienced professionals needs firm routines without treating every learner as though their path is identical. Recognition of prior learning, workplace evidence, and flexible delivery require careful judgment, not loosened standards. The route may differ; the demand for intellectual quality should not.

The management burden also includes staff capacity. Mentors need time, training, and authority. Editorial review needs consistency. Learners need clear expectations. Employers and public readers need confidence that a published research paper represents supervised academic work rather than a private claim.

The outcome is decided by institutional habits. Shared responsibility becomes a hiding place when nobody can explain who approved the learner route, who supervised the work, or who confirmed that the standard was met That is why the school must connect promise to records, supervision, review, and correction.

Management must then convert the argument into rules that staff can follow. In governance for unconventional business schools, decision-making should not depend on personal goodwill or informal memory. Admission panels need records. Supervisors need workload limits. Assessors need common standards. Learners need written expectations. Editorial reviewers need authority to return weak work rather than rescue it at the end. Admission control, supervision records, assessment authority, and institutional accountability matter because they decide whether the model will be trusted after the marketing language has faded.

8.4 Governance failures and their safeguards

Every unconventional model carries risk. Shared responsibility becomes a hiding place when nobody can explain who approved the learner route, who supervised the work, or who confirmed that the standard was met.

The main safeguards are visible admission criteria, documented recognition of prior learning, signed supervision records, source verification, clear assessment rubrics, independent review, and a process for correcting or withdrawing weak publication material when necessary.

There is also a reputational risk. A business school built around flexibility can be misunderstood as less serious if it fails to explain its evidence discipline. That misunderstanding cannot be answered by slogans. It must be answered by transparent standards and better work.

The ethical issue is equally important. Adult learners deserve opportunity, but they also deserve honesty. The institution should not sell ease as education. It should offer a demanding route that respects professional experience while insisting on academic proof.

The safeguards should be practical, not theatrical. A school can write impressive policy language and still fail if the record does not show how decisions were made. Risk control in governance for unconventional business schools should therefore include admission notes, proof of prior learning where relevant, supervisor feedback, version history, source checking, originality review, and a final academic sign-off. These controls protect the learner as much as the institution. They reduce confusion, prevent unfair judgment, and make it possible to defend a decision if the award is questioned. The aim is a fair trail of evidence that shows the work earned its standing.

8.5 Making governance a working routine

Implementation should begin with the routines that most directly affect quality. In governance for unconventional business schools, the necessary disciplines are entry review, mentor assignment, milestone tracking, source control, writing feedback, and final review before public release.

Scale should follow demonstrated reliability. A school should expand only when it can show that ordinary teams, using ordinary resources, can maintain the same quality of guidance, record keeping, and assessment across cohorts.

Institutional learning must be built into the calendar. Each cohort should leave evidence about what worked, where learners struggled, which supervisors needed support, which assessment criteria were unclear, and which research outputs required deeper editorial care.

A credible business school does not confuse speed with seriousness. It can move quickly where the risk is low and the evidence is clear, but it must slow down where academic quality, learner protection, or public trust is at stake. That discipline is what separates reform from marketing.

Implementation should be judged by repetition under ordinary conditions. It is proven when the next cohort receives the same quality of guidance, when a different supervisor applies the same standard, when the review process catches weak evidence, and when the institution corrects defects without waiting for embarrassment. In governance for unconventional business schools, learning must travel from one cycle into the next. That means keeping clear records, discussing failures openly, revising instructions, and training staff before scale creates pressure. This is the quieter work of institutional maturity, and it is where unconventional education either becomes credible or exposes its weakness.

Governance becomes real only when authority and consequence are attached to specific people. A model that names a quality committee but never specifies who can halt a weak award, who owns the correction of a published error, or who answers to an external body has described governance without enacting it. The test proposed throughout this work applies here too: a governance arrangement should be judged by what it can be shown to have done when something went wrong, not by the elegance of its organisational chart.

Internal governance is necessary but not sufficient, because an institution is rarely the best judge of its own failures. External accountability, whether through professional bodies, independent reviewers, or peer institutions, supplies the distance that internal committees lose under commercial and reputational pressure. A governance model worth the name therefore builds in a route by which an outside party can examine evidence and challenge conclusions, and it treats that exposure as a strength rather than a threat to be managed.

Chapter 9: Strategic Implementation and Quality Assurance Model

9.1 From strategy to quality-assured delivery

Strategy that never reaches the quality of daily delivery is only a document. The real test is whether the institution changes the conditions under which learning is admitted, supervised, tested, and made useful. Implementation should be built around tested routines: entry review, mentorship assignment, research milestones, evidence checks, editorial review, panel decision, and post-publication learning. A doctoral-level discussion must stay close to that operating reality.

This matters because professional learners do not enter business education as blank academic subjects. They arrive with work histories, managerial habits, uneven writing confidence, partial technical knowledge, and urgent career pressures. quality assurance is not a ceremonial audit at the end; it is the discipline that shapes each stage of the learner journey.

The test is therefore practical and academic at the same time. A claim about access must be supported by fair entry judgment. A claim about flexibility must be supported by supervision. A claim about research quality must be supported by sources, revision, and public accountability.

A weak model hides behind modern vocabulary. A serious model exposes itself to review. Growth becomes a liability when admissions, supervision, and review capacity do not grow with learner numbers.

This problem definition also requires a sharper reading of institutional behavior. In quality assurance and implementation, weak schools tend to describe access as generosity while avoiding the harder question of what support, review, and academic pressure the learner will meet after admission. Stronger institutions do not confuse open doors with serious education. They ask whether the learner can receive timely guidance, produce evidence, revise weak work, and graduate with a body of scholarship that another reviewer can respect. The claim is that inherited practice should justify itself. Where a fixed classroom strengthens discipline, it should remain. Where it simply protects habit, the school has a duty to redesign the learning route without lowering the standard. Implementation should proceed through reliability rather than ceremony.

9.2 Evidence for staged, measured implementation

Evidence in this area should be handled with care. Public reports, institutional materials, employer signals, and education research can show pressure, but they cannot by themselves prove quality inside a school. The stronger academic move is to read those materials beside the lived mechanics of admission, supervision, assessment, and learner support.

For strategic implementation and quality assurance, the useful evidence is the kind that changes judgment. It tells leaders where access is blocked, where professional learning is undervalued, where assessment is too narrow, and where digital delivery may expand reach without strengthening competence.

The analysis should not chase novelty. It should ask whether the learner can defend a position, use sources responsibly, recognize limits, connect theory to practice, and produce work that can stand outside the classroom.

Professional judgment enters where data are incomplete. It is to build review routines that keep records, compare learner progress, protect standards, and correct weak practice before it becomes institutional habit.

Reports on digital learning, micro-credentials, executive education, labor-market change, and higher-education finance are useful because they show pressure on the sector, but they do not automatically validate any single institutional response. A serious reading asks what each source proves and what it cannot prove. Employer demand can show need, but not academic quality. Learner preference can show access pressure, but not competence. Publication output can show ambition, but only careful review can prove scholarly value. The value of quality assurance and implementation lies in connecting these different signals without exaggerating them. That disciplined reading gives the paper a more credible voice than broad praise for innovation would allow.

9.3 Decisions that protect quality during change

Management choices decide whether strategic implementation and quality assurance becomes serious scholarship or promotional language. The decisive choices are often ordinary: who reviews entry evidence, who mentors the learner, who approves the research topic, who checks sources, who records feedback, and who has authority to stop weak work.

A school that serves experienced professionals needs firm routines without treating every learner as though their path is identical. Recognition of prior learning, workplace evidence, and flexible delivery require careful judgment, not loosened standards. The route may differ; the demand for intellectual quality should not.

The management burden also includes staff capacity. Mentors need time, training, and authority. Editorial review needs consistency. Learners need clear expectations. Employers and public readers need confidence that a published research paper represents supervised academic work rather than a private claim.

The outcome is decided by institutional habits. Growth becomes a liability when admissions, supervision, and review capacity do not grow with learner numbers That is why the school must connect promise to records, supervision, review, and correction.

Management must then convert the argument into rules that staff can follow. In quality assurance and implementation, decision-making should not depend on personal goodwill or informal memory. Admission panels need records. Supervisors need workload limits. Assessors need common standards. Learners need written expectations. Editorial reviewers need authority to return weak work rather than rescue it at the end. Tested routines, capacity limits, evidence review, and scalable academic practice matter because they decide whether the model will be trusted after the marketing language has faded.

9.4 Implementation risk and its controls

Every unconventional model carries risk. Growth becomes a liability when admissions, supervision, and review capacity do not grow with learner numbers.

The main safeguards are visible admission criteria, documented recognition of prior learning, signed supervision records, source verification, clear assessment rubrics, independent review, and a process for correcting or withdrawing weak publication material when necessary.

There is also a reputational risk. A business school built around flexibility can be misunderstood as less serious if it fails to explain its evidence discipline. That misunderstanding cannot be answered by slogans. It must be answered by transparent standards and better work.

The ethical issue is equally important. Adult learners deserve opportunity, but they also deserve honesty. The institution should not sell ease as education. It should offer a demanding route that respects professional experience while insisting on academic proof.

The safeguards should be practical, not theatrical. A school can write impressive policy language and still fail if the record does not show how decisions were made. Risk control in quality assurance and implementation should therefore include admission notes, proof of prior learning where relevant, supervisor feedback, version history, source checking, originality review, and a final academic sign-off. These controls protect the learner as much as the institution. They reduce confusion, prevent unfair judgment, and make it possible to defend a decision if the award is questioned. The aim is a fair trail of evidence that shows the work earned its standing.

9.5 Institutional learning across cycles

Implementation should begin with the routines that most directly affect quality. In strategic implementation and quality assurance, the necessary disciplines are entry review, mentor assignment, milestone tracking, source control, writing feedback, and final review before public release.

Scale should follow demonstrated reliability. A school should expand only when it can show that ordinary teams, using ordinary resources, can maintain the same quality of guidance, record keeping, and assessment across cohorts.

Institutional learning must be built into the calendar. Each cohort should leave evidence about what worked, where learners struggled, which supervisors needed support, which assessment criteria were unclear, and which research outputs required deeper editorial care.

The practical conclusion is restrained but firm: unconventional business education becomes credible when the institution can repeat good judgment under normal conditions.

Implementation should be judged by repetition under ordinary conditions. It is proven when the next cohort receives the same quality of guidance, when a different supervisor applies the same standard, when the review process catches weak evidence, and when the institution corrects defects without waiting for embarrassment. In quality assurance and implementation, learning must travel from one cycle into the next. That means keeping clear records, discussing failures openly, revising instructions, and training staff before scale creates pressure. This is the quieter work of institutional maturity, and it is where unconventional education either becomes credible or exposes its weakness.

Implementation discipline is where most reforms quietly fail. Strategy documents are approved with enthusiasm, but the daily work of maintaining records, training new supervisors, and reviewing evidence competes with every other operational pressure and usually loses unless it is protected. A quality-assurance model therefore needs more than indicators; it needs an owner with time, a cadence of review that survives staff turnover, and a leadership willing to slow growth when the evidence of reliability is not yet there.

Sequencing is the quiet discipline that separates durable reform from expensive failure. The temptation is always to scale a promising pilot quickly, before the routines that made the pilot work have been proven under ordinary staff and ordinary load. A measured sequence, proving reliability in a few settings, recording the true cost, and only then expanding, feels slow in a competitive market, but it is the difference between growing a sound model and multiplying a fragile one across more learners than the institution can actually support.


Table 3. Doctoral implementation plan

Phase Action Control
Design Define programmes and learning evidence Academic board approval
Delivery Run mentored modules and research clinics Faculty review
Assessment Use capstone/publication rubrics External moderation
Publication Prepare final works for dissemination Peer review and copyediting
Improvement Review outcomes and complaints Annual quality report

Note. Black-and-white NYCAR publication format.


Chapter 10: Final Position: Business Education as Public and Professional Proof

10.1 The case for education as public proof

In the end, an institution is judged less by what it promises than by what it can prove. The real test is whether the institution changes the conditions under which learning is admitted, supervised, tested, and made useful. The future of business education will favor institutions that can prove learning through performance, writing, judgment, and public accountability rather than through inherited prestige alone. A doctoral-level discussion must stay close to that operating reality.

This matters because professional learners do not enter business education as blank academic subjects. They arrive with work histories, managerial habits, uneven writing confidence, partial technical knowledge, and urgent career pressures. NYCAR and similar institutions should be judged by the seriousness of their evidence, the fairness of their process, and the professional usefulness of their research outputs.

The test is therefore practical and academic at the same time. A claim about access must be supported by fair entry judgment. A claim about flexibility must be supported by supervision. A claim about research quality must be supported by sources, revision, and public accountability.

A weak model hides behind modern vocabulary. A serious model exposes itself to review. The final danger is self-congratulation; a school should not call itself innovative unless its learners, supervisors, employers, and readers can see the proof.

This problem definition also requires a sharper reading of institutional behavior. In the final position on business education as proof, weak schools tend to describe access as generosity while avoiding the harder question of what support, review, and academic pressure the learner will meet after admission. Stronger institutions do not confuse open doors with serious education. They ask whether the learner can receive timely guidance, produce evidence, revise weak work, and graduate with a body of scholarship that another reviewer can respect. The claim is that inherited practice should justify itself. Where a fixed classroom strengthens discipline, it should remain. Where it simply protects habit, the school has a duty to redesign the learning route without lowering the standard. The closing argument should leave the reader with a standard for judging serious business education.

10.2 Evidence that renewal must be demonstrated

Evidence in this area should be handled with care. Public reports, institutional materials, employer signals, and education research can show pressure, but they cannot by themselves prove quality inside a school. The stronger academic move is to read those materials beside the lived mechanics of admission, supervision, assessment, and learner support.

For the final position on business education as proof, the useful evidence is the kind that changes judgment. It tells leaders where access is blocked, where professional learning is undervalued, where assessment is too narrow, and where digital delivery may expand reach without strengthening competence.

The analysis should not chase novelty. It should ask whether the learner can defend a position, use sources responsibly, recognize limits, connect theory to practice, and produce work that can stand outside the classroom. NYCAR and similar institutions should be judged by the seriousness of their evidence, the fairness of their process, and the professional usefulness of their research outputs.

Professional judgment enters where data are incomplete. It is to build review routines that keep records, compare learner progress, protect standards, and correct weak practice before it becomes institutional habit.

Reports on digital learning, micro-credentials, executive education, labor-market change, and higher-education finance are useful because they show pressure on the sector, but they do not automatically validate any single institutional response. A serious reading asks what each source proves and what it cannot prove. Employer demand can show need, but not academic quality. Learner preference can show access pressure, but not competence. Publication output can show ambition, but only careful review can prove scholarly value. The value of the final position on business education as proof lies in connecting these different signals without exaggerating them. That disciplined reading gives the paper a more credible voice than broad praise for innovation would allow.

10.3 The choices that make proof possible

Management choices decide whether the final position on business education as proof becomes serious scholarship or promotional language. The decisive choices are often ordinary: who reviews entry evidence, who mentors the learner, who approves the research topic, who checks sources, who records feedback, and who has authority to stop weak work.

A school that serves experienced professionals needs firm routines without treating every learner as though their path is identical. Recognition of prior learning, workplace evidence, and flexible delivery require careful judgment, not loosened standards. The route may differ; the demand for intellectual quality should not.

The management burden also includes staff capacity. Mentors need time, training, and authority. Editorial review needs consistency. Learners need clear expectations. Employers and public readers need confidence that a published research paper represents supervised academic work rather than a private claim.

The outcome is decided by institutional habits. The final danger is self-congratulation; a school should not call itself innovative unless its learners, supervisors, employers, and readers can see the proof That is why the school must connect promise to records, supervision, review, and correction.

Management must then convert the argument into rules that staff can follow. In the final position on business education as proof, decision-making should not depend on personal goodwill or informal memory. Admission panels need records. Supervisors need workload limits. Assessors need common standards. Learners need written expectations. Editorial reviewers need authority to return weak work rather than rescue it at the end. Public trust, professional usefulness, and academic evidence matter because they decide whether the model will be trusted after the marketing language has faded.

10.4 What still threatens credible reform

Every unconventional model carries risk. The final danger is self-congratulation; a school should not call itself innovative unless its learners, supervisors, employers, and readers can see the proof.

The main safeguards are visible admission criteria, documented recognition of prior learning, signed supervision records, source verification, clear assessment rubrics, independent review, and a process for correcting or withdrawing weak publication material when necessary.

There is also a reputational risk. A business school built around flexibility can be misunderstood as less serious if it fails to explain its evidence discipline. That misunderstanding cannot be answered by slogans. It must be answered by transparent standards and better work.

The practical test is whether a learner, assessor, employer, or reviewer can see how a decision was made. If the institution can explain admission, assessment, supervision, appeal, and improvement with clean evidence, the model begins to deserve confidence. Without that clarity, the reform remains exposed.

The safeguards should be practical, not theatrical. A school can write impressive policy language and still fail if the record does not show how decisions were made. Risk control in the final position on business education as proof should therefore include admission notes, proof of prior learning where relevant, supervisor feedback, version history, source checking, originality review, and a final academic sign-off. These controls protect the learner as much as the institution. They reduce confusion, prevent unfair judgment, and make it possible to defend a decision if the award is questioned. The aim is a fair trail of evidence that shows the work earned its standing.

10.5 Sustaining proof beyond a single cohort

Implementation should begin with the routines that most directly affect quality. In the final position on business education as proof, the necessary disciplines are entry review, mentor assignment, milestone tracking, source control, writing feedback, and final review before public release.

Scale should follow demonstrated reliability. A school should expand only when it can show that ordinary teams, using ordinary resources, can maintain the same quality of guidance, record keeping, and assessment across cohorts.

Institutional learning must be built into the calendar. Each cohort should leave evidence about what worked, where learners struggled, which supervisors needed support, which assessment criteria were unclear, and which research outputs required deeper editorial care.

The practical conclusion is restrained but firm: unconventional business education becomes credible when the institution can repeat good judgment under normal conditions. NYCAR and similar institutions should be judged by the seriousness of their evidence, the fairness of their process, and the professional usefulness of their research outputs.

Implementation should be judged by repetition under ordinary conditions. It is proven when the next cohort receives the same quality of guidance, when a different supervisor applies the same standard, when the review process catches weak evidence, and when the institution corrects defects without waiting for embarrassment. In the final position on business education as proof, learning must travel from one cycle into the next. That means keeping clear records, discussing failures openly, revising instructions, and training staff before scale creates pressure. This is the quieter work of institutional maturity, and it is where unconventional education either becomes credible or exposes its weakness.

The final position can be stated plainly. An institution that wants to be trusted in a sceptical, fast-changing environment cannot rely on inherited form or confident language; it has to make its quality visible, its decisions accountable, and its failures correctable in the open. That standard is demanding, and it is meant to be, because the people who depend on business education, the learners, the employers, and the wider public, carry the cost when the proof is missing. Renewal that can be demonstrated is the only kind that earns lasting confidence.

The standard set out here should finally be turned back on the publication itself. A doctoral argument that asks institutions to prove their quality through visible routines and honest correction must be willing to show its own sources, acknowledge its own limits, and invite challenge to its own claims. That reflexive test is the appropriate close to the argument, because a case for proof that exempts itself from proof would be the very evasion the work was written against.

10.6 Limitations and boundaries of the argument

Several limits should be stated so that the argument is not read as more than it is. The analysis is built from public reporting, documented practice, and conceptual reasoning rather than from a controlled study of many institutions, so its claims are about what a disciplined leader should attend to, not about measured effect sizes across a sector. The treatment of NYCAR is an applied, single-institution case, which makes it useful for illustrating routines but unsuitable for statistical generalisation. The international evidence used here describes pressures and directions of travel; it cannot certify the internal quality of any particular school. Recognising these boundaries is itself part of the method, because a publication that asks institutions to be honest about the limits of their evidence must hold itself to the same standard. The argument is therefore offered as a structured, defensible position that others can test, extend, or contest, not as a settled empirical finding.

10.7 A practical summary for institutional leaders

For a leader who has to act, the argument reduces to a small number of disciplines that can be started without waiting for perfect conditions. Decide who owns each academic judgement, and make sure that judgement leaves a record. Recognise professional experience honestly, but tie every recognition decision to documented evidence. Protect supervision as the point where flexibility either becomes rigorous or becomes empty. Choose assessment by the strength of proof it provides, not by the ease of administering it, and resource it accordingly. Treat technology as an academic decision with consequences for integrity and privacy, not as a procurement choice. Give governance real authority to halt weak work and to correct published error in the open. Above all, prove reliability in a few settings before scaling, and let evidence rather than ambition set the pace of growth. None of these steps is glamorous, and that is the point: institutional credibility is built from ordinary disciplines performed consistently, and it is lost when those disciplines are skipped under pressure.

None of these steps is glamorous, and that is the point: institutional credibility is built from ordinary disciplines performed consistently, and it is lost when those disciplines are skipped under pressure.

It is worth adding what this summary does not ask of leaders. It does not ask them to abandon what already works, to chase every new format, or to treat flexibility as a value in itself. A fixed seminar that produces strong, defensible work needs no apology, and a fashionable innovation that cannot show its evidence deserves no protection. The discipline proposed here is neutral about form and strict about proof, which means a leader can keep a great deal of inherited practice while still meeting the standard, provided that each retained practice can explain why it earns its place. Reform, on this reading, is less a break with the past than a steady insistence that every part of the institution justify itself by what it can demonstrate.

10.8 A closing note on proof

The recurring word in this work has been proof, and it is worth ending on what that word is meant to carry. Proof here does not mean bureaucracy, nor a defensive accumulation of paperwork for its own sake. It means that an institution can show, to a fair outside observer, how its decisions were made, why its standards were met, and what it did when they were not. A business school that can do this earns a kind of trust that marketing cannot manufacture and that reputation alone can no longer protect. In a period when learners, employers, and the public are right to be sceptical of confident claims, the schools that endure will be those willing to be examined. That willingness, more than any single model, table, or figure in these pages, is the real argument of the work.

If there is a single sentence a reader should carry away, it is that credibility in modern business education has shifted from what an institution claims to be toward what it can show it does. The conventional model drew authority from form, location, and reputation, and those sources have not vanished, but they no longer suffice in a world where learners are mobile, employers are sceptical, technology is disruptive, and the public is alert to hollow promises. An unconventional model does not escape this scrutiny by being new; it meets the same test from a different starting point, and it earns trust only by making its admission, supervision, assessment, and governance visible and correctable. The chapters here have tried to convert that broad claim into specific, ordinary disciplines, because principles that cannot be enacted on a Monday morning are of little use to the leaders who must carry them. The future of executive and professional learning will belong to institutions confident enough to be examined, humble enough to correct themselves, and disciplined enough to let evidence, rather than ambition, set the pace at which they grow.

References

AACSB. (2025). 2025 State of Business Education report. https://www.aacsb.edu/insights/reports/2025/2025-state-of-business-education-report

AACSB. (2025). Revamping executive education in the microcredential era. https://www.aacsb.edu/insights/articles/2025/08/revamping-exec-ed-in-the-microcredential-era

Lumina Foundation. (2025). Micro-credentials impact report 2025. https://www.luminafoundation.org/

OECD. (2025). Education at a glance 2025: OECD indicators. OECD Publishing. https://doi.org/10.1787/1c0d9c79-en

UNESCO. (2023). Global education monitoring report 2023: Technology in education. https://www.unesco.org/gem-report/

UNESCO. (2025). AI and technologies in education. https://www.unesco.org/en/digital-education

United Nations Development Programme. (2025). Human Development Report 2025: A matter of choice: People and possibilities in the age of AI. https://hdr.undp.org/content/human-development-report-2025

United Nations. (2025). The Sustainable Development Goals report 2025. https://unstats.un.org/sdgs/report/2025/

World Bank. (2025). Digital technologies in education. https://www.worldbank.org/ext/en/topic/education/digital-technologies-in-education

The Thinkers’ Review
Chidiebere T. Osuagwu

Reliability Governance in Electric Vehicle Battery Manufacturing

An Engineering Management Study of Defect Escape, Logistic Safety Modeling, and Production-Scale Quality Assurance

Research Publication by Chidiebere T. Osuagwu

New York Center for Advanced Research (NYCAR)

Publication No.: NYCAR-TTR-2026-RP033

Date: June 2026

DOI: https://doi.org/10.5281/zenodo.20510257


Peer Review Status
This research paper underwent independent peer review under the internal editorial peer review framework of the New York Center for Advanced Research (NYCAR) and The Thinkers’ Review. The review was conducted independently by designated Editorial Board members, without author involvement, and the manuscript was approved in accordance with NYCAR’s Research Ethics Policy and its standards for independent academic evaluation.


Copyright © 2026 Chidiebere T. Osuagwu and New York Center for Advanced Research (NYCAR). All rights reserved.


Abstract

Electric vehicle battery manufacturing has become a safety-critical engineering management problem at industrial scale. The battery pack is far from an ordinary vehicle component, since it is the source of range, charging behavior, warranty exposure, thermal risk, customer confidence, and much of the cost structure behind electrification. A single cell defect can pass ordinary inspection, move through module and pack assembly, enter the vehicle fleet, and later appear as fire risk, recall exposure, or brand damage. The research examines reliability governance through public evidence from the Chevrolet Bolt EV battery recall, GM and LG’s identification of two rare manufacturing defects in the same cell, CATL’s 2025 scale, Tesla’s reported engineering investment, and recent battery-defect safety literature.

The study develops a logistic regression framework for Defect Escape Probability and a reliability-regression framework for time-to-warning or time-to-failure. The logistic model estimates whether a cell, module, or pack escapes into field use with a safety-relevant defect. The predictors include particle-contamination risk, coating uniformity deviation, separator alignment variation, moisture exposure, formation and aging anomaly, abnormal self-discharge, inspection coverage depth, and supplier-process maturity. The reliability model adds time by examining how process conditions may shorten the interval before diagnostic warnings, abnormal degradation, warranty claims, or confirmed failure. These tools are offered less as abstract mathematics than as governing instruments for plant leaders, automakers, supplier-quality teams, and safety reviewers.

The findings show that battery reliability cannot be governed by end-of-line testing alone. The Chevrolet Bolt recall demonstrates how rare defect combinations can create system-level exposure after vehicles have already reached customers. CATL’s reported scale shows the volume at which battery manufacturing discipline must operate. Tesla’s 2025 Form 10-K shows the broader engineering-investment environment around electrified vehicle systems. The practical conclusion is that EV battery manufacturers need layered reliability governance: prevention at process design, detection through in-line measurement, containment through traceability, prediction through diagnostics, and accountability through recall-ready decision systems. Battery quality is not merely a production metric; it is the engineering basis of trust in electric mobility.

Keywords: electric vehicle batteries, reliability governance, defect escape, logistic regression, survival analysis, traceability, quality management, recall exposure, engineering management

Table of Contents


List of Tables

Table 1. Battery manufacturing evidence and reliability governance use 24

Table 2. Regression variables for battery defect escape and time-to-warning 25

List of Figures

Figure 1. Logistic model linking manufacturing predictors to defect escape proba 18

Figure 2. Drivers of the Recall Exposure Index 20

Figure 3. The defect-escape pathway from cell production to field use 26

Figure 4. Containment decision bands by predicted defect escape probability 38

Figure 5. Layered reliability governance for battery manufacturing 48

Chapter 1: Introduction

1.1 Why Battery Manufacturing Tests Engineering Management

Electric vehicle battery manufacturing is a difficult place to hide weak engineering management. The product contains electrochemical complexity, high energy density, tight process windows, and safety consequences that may emerge long after the factory has shipped the pack. A vehicle can leave the assembly line looking complete while a small cell defect remains dormant. If that defect later contributes to thermal runaway risk, the problem outgrows quality control and becomes a safety, warranty, legal, regulatory, and trust problem.

1.2 The Battery as a Safety-Critical Subsystem

The industrial stakes are high because the battery is not an ordinary component. It is the cost center, energy reservoir, performance constraint, warranty exposure, and safety-critical subsystem of an electric vehicle. Battery packs influence range, charging speed, thermal behavior, vehicle weight, customer confidence, residual value, and brand reputation. An engineering manager who treats battery production like generic high-volume assembly misunderstands the product. A battery is manufactured, but it is also formed, aged, tested, managed, and monitored across time.

1.3 The Bolt Recall and the Logic of Defect Escape

The Chevrolet Bolt EV recall remains one of the most important public cases for understanding battery manufacturing risk. NHTSA announced in August 2021 that all Chevrolet Bolt vehicles were recalled because of high-voltage battery fire risk. GM later stated that experts from GM and LG identified the simultaneous presence of two rare manufacturing defects in the same battery cell as the root cause of fires in certain Bolt EVs. That wording matters because it reveals how rare defects can interact. Battery safety is often threatened not by one obvious fault but by a combination of small process failures that align unfavorably (NHTSA, 2021; General Motors, 2021).

The case also shows why defect escape is a better management concept than defect occurrence alone. A defect that is detected, contained, and corrected inside the factory remains a cost and learning event, whereas a defect that escapes into the field becomes a safety event. Engineering management therefore has to focus on the probability of escape, not only the existence of variation. The governing question is not whether a plant will ever produce a bad cell. It is whether the production system can detect, segregate, trace, and correct unsafe variation before customers carry the risk.

1.4 Industry Scale and Engineering Investment

The battery industry’s scale makes the problem more serious. CATL reported 2025 operating revenue of RMB 423.7 billion and net profit attributable to shareholders of RMB 72.2 billion. Such scale demonstrates the manufacturing intensity now required to support electrification. A company operating at that level is not managing battery quality as a laboratory concern. It is managing high-volume energy-device reliability across factories, suppliers, chemistries, customers, and end-use environments (CATL, 2026).

Tesla’s 2025 Form 10-K also illustrates the investment side of battery-centered engineering. Tesla reported R&D expense of $6.411 billion in 2025, equal to about 7 percent of revenues, with increases attributed to AI and other programs as the company expanded its product roadmap and technologies. Although R&D spending is not a direct battery-quality measure, it shows how electrified vehicle firms must sustain large engineering investments in product, manufacturing, software, diagnostics, and systems integration. Battery reliability governance belongs inside that broader engineering system (Tesla, 2026).

1.5 The Functional-Safety Frame

It helps to place this work inside the language of functional safety before the models appear. In safety-critical industries, engineers distinguish between a fault, a failure, and a hazard, and they ask how often a dangerous condition can occur and how reliably it will be detected before it causes harm. Battery manufacturing fits that frame almost exactly. A contaminated electrode or a misaligned separator is a fault; a cell that vents or enters thermal runaway is a failure; a vehicle fire in a customer’s garage is the hazard. The distance between the fault and the hazard is where engineering management does its real work, because that distance is filled with inspection, traceability, diagnostics, and the willingness to act on weak signals.

Reading the problem this way also clarifies what a model can and cannot do. A statistical score does not remove a hazard; it estimates how likely the production system is to let a fault travel undetected toward the customer. That estimate is only useful when the organization has already decided what counts as a safety-relevant fault, who owns the decision to hold a lot, and how quickly the plant can reconstruct the history of a suspect cell. The chapters that follow treat the mathematics as one instrument inside that larger safety system rather than as a substitute for it.

1.6 Aim, Research Questions, and Significance

The research studies reliability governance in EV battery manufacturing as an engineering management discipline. The focus is not the chemistry of one cell type or the physics of thermal runaway in isolation. The focus is how engineering managers design systems that prevent, detect, contain, and learn from process variation. The analysis connects public cases, industry data, and recent safety literature to a mathematical framework suitable for production and quality leadership.

The research uses two statistical models. The first is logistic regression for defect escape. Logistic regression is suitable because the outcome is binary: a unit either escapes with a safety-relevant defect or it does not. The second is reliability regression for time-to-warning or time-to-failure. This is suitable because battery hazards may not appear immediately. The relevant question may be how long a unit operates before a diagnostic signal, abnormal degradation pattern, thermal event, or warranty incident becomes visible.

The research questions are practical. Which manufacturing conditions increase the probability of battery defect escape? How can logistic regression support engineering management decisions about inspection, containment, and supplier qualification? How can reliability regression connect process evidence with time-dependent safety risk? What lessons emerge from the Chevrolet Bolt recall and recent battery-defect literature? How can battery manufacturers scale production without weakening safety governance?

The paper’s significance lies in the fact that battery failures can damage more than one company. Publicized battery fires and recalls can slow consumer confidence in electric vehicles, increase regulatory scrutiny, raise insurance concern, and deepen skepticism toward electrification. Engineering management in battery manufacturing therefore has social value. It helps determine whether the energy transition feels safe enough for ordinary customers to trust.

Chapter 2: Literature Review
2.1 Manufacturing Defects as Safety Pathways

Battery safety literature increasingly emphasizes manufacturing defects as a pathway to serious safety risk. Chen and colleagues’ 2025 review of defects in lithium-ion batteries is especially relevant because it addresses manufacturing-defect origins, associated hazards, metal foreign matter, copper-particle contamination, and detection methods. The managerial implication is clear. Defects that begin as microscopic process failures can become macroscopic safety failures. Quality management cannot rely only on final product appearance.
Thermal runaway research also reinforces the importance of early detection and process control. Goswami and colleagues’ 2024 work on integrating multiphysics and machine learning for thermal runaway prediction shows that battery safety is increasingly modeled through combined physical and data-driven methods. Engineering managers should not read such work as a reason to replace process discipline with algorithms. The stronger lesson is that battery production and battery monitoring now require layered evidence: process measurements, electrochemical testing, thermal data, degradation behavior, and diagnostic models (Chen et al., 2025).

The Chevrolet Bolt recall demonstrates why manufacturing defects require traceability. GM’s recall materials identify two rare manufacturing defects appearing simultaneously in the same battery cell. A system that cannot trace cells, modules, process windows, supplier lots, and vehicle installation records will struggle to determine which vehicles are exposed. Traceability is not an administrative luxury but the difference between a targeted containment action and a broad recall (Das Goswami et al., 2024).

NHTSA’s public recall notice confirms the scale of the response: all Chevrolet Bolt EVs were recalled due to the risk of high-voltage battery pack fire. In engineering management terms, this is a field-containment failure of extraordinary consequence. The defect was not contained at cell production, module assembly, pack assembly, or vehicle release. Once the issue reached the fleet, the remedy required broad customer communication, software measures, replacement decisions, and significant reputational cost (General Motors, 2021; NHTSA, 2021). The detailed safety recall report for the campaign records the affected population, defect description, and remedy logic that a mature traceability system must be able to reproduce on demand (National Highway Traffic Safety Administration, 2023).

2.2 Detection Technologies and In-Line Control

Quality-control scholarship in battery manufacturing increasingly points toward in-line monitoring, inspection technologies, digital traceability, and real-time process control. The emerging literature on electrode manufacturing control argues that fixed recipe-based process control may be insufficient where electrode properties vary in ways that affect yield and performance. For managers, the message is that process control has to be active. A plant cannot assume that yesterday’s settings remain safe when material properties, coating conditions, humidity, equipment wear, and line speed change.

Manufacturing-defect detection is also evolving. X-ray computed tomography, machine vision, electrical tests, ultrasonic methods, thermal imaging, formation data, aging tests, and battery-management diagnostics all offer partial visibility. No single method is complete, so the engineering management problem is how to combine them into a cost-effective inspection strategy that detects high-consequence defects early enough. Over-inspection can slow production and raise cost. Under-inspection can produce recalls. The solution is risk-weighted inspection (Ploder et al., 2025).

It is worth borrowing perspective from older safety-critical industries, because battery manufacturing is repeating arguments that aerospace and medical-device engineering settled decades ago. Those fields learned that final inspection cannot certify safety on its own, that a defect’s danger depends on how it interacts with the rest of the system, and that the discipline which matters most is the traceable record connecting a part to the process that made it. They also learned that quality systems decay when they are treated as paperwork rather than as engineering. A battery plant that studies how aviation handles airworthiness directives, or how medical-device makers manage design history files and field-corrective actions, will recognize its own problem in a more mature form. The chemistry is new; the management lesson is not.

2.3 Reliability Measures and Statistical Modeling

Reliability engineering provides the language needed to manage that tradeoff. A defect occurrence rate tells managers how often variation appears. A detection rate tells managers how often the system catches it. A defect escape rate tells managers how often unsafe or unacceptable variation reaches the customer. Field failure data tell managers what escaped. Strong reliability governance links those four measures and updates process control when the pattern changes.

Logistic regression is well suited to the defect-escape problem because it estimates the probability of a binary outcome from multiple predictors. A cell may carry a safety-relevant defect beyond the detection system, or it may be contained. The explanatory variables can include process conditions, inspection results, supplier history, and diagnostic signals. Unlike a simple defect-rate table, logistic regression can show which variables matter most after controlling for other variables.

Survival or time-to-event regression adds another layer because battery failures may be delayed. A cell affected by contamination, coating irregularity, or separator damage may not fail immediately. It may show abnormal self-discharge, unusual impedance growth, thermal deviation, capacity fade, or BMS warning later. Time-to-event modeling helps managers ask whether certain process signatures are linked to earlier field warnings. That evidence can improve warranty strategy, fleet monitoring, and recall thresholds.

The literature also warns against overconfidence. More testing does not automatically mean better governance if the test is aimed at the wrong failure mode. A production line may achieve high end-of-line pass rates while missing rare combinations of defects. Battery manufacturing therefore requires a management system that pays attention to interactions. The Bolt case is important precisely because simultaneous rare defects mattered. Regression analysis can help detect interaction effects if the data are captured well.

2.4 Standards, Process Capability, and Digital Manufacturing

A second body of work sits beside the defect literature and rarely receives equal attention from technical readers: the standards and capability frameworks that translate safety intentions into auditable practice. Automotive functional safety under ISO 26262, quality-management discipline under IATF 16949, and transport-safety testing under the United Nations Manual of Tests and Criteria each shape how a battery plant is expected to document risk, qualify suppliers, and prove that a process remains in control. These frameworks matter to the present model because they define the evidence that the predictor variables are built from. A coating-uniformity figure or a supplier audit score is not free-floating data; it is the residue of a capability system that someone designed, ran, and signed.

Process-capability thinking adds a quantitative bridge between those standards and the escape model. Indices such as Cp and Cpk express how much of a process distribution sits safely inside its tolerance window, and they decay quietly as equipment wears, humidity drifts, or a new material lot behaves differently. A capable process is not a guarantee of safety, but a process whose capability is falling is an early and measurable warning that escape probability is about to rise. Manufacturing execution systems and the emerging use of digital twins make this visible in close to real time, linking machine settings, environmental readings, and inspection results to the identity of individual cells. The framework developed here assumes that kind of connected data environment, because without it the predictors can be defined on paper but never populated in practice.

Industry scale changes the economics of quality. In small-batch manufacturing, a rare defect may affect a few units. In battery manufacturing, production volume means even low defect probabilities can become large field populations. If one safety-relevant defect escapes in a million cells, a large pack and a large fleet can still create serious exposure. Engineering managers must therefore think in population terms rather than only percentage terms.

2.5 The Research Gap

The gap addressed here is is the connection between battery-defect science and engineering management practice. Technical literature explains defects and detection. Public recalls show consequences. Managers need a governing model that connects process variables with escape probability and time-dependent risk. The logistic and reliability regression framework developed here provides that connection.

Chapter 3: Methodology and Regression Framework

3.1 Research Design and Evidence Base

The study uses a case-informed engineering management design. Public evidence from the Chevrolet Bolt recall, GM and LG recall materials, NHTSA documentation, CATL reporting, Tesla’s 2025 Form 10-K, and recent lithium-ion battery defect research provides the factual base. The mathematical component develops regression models that can be implemented inside a battery manufacturer’s quality and reliability governance system. The paper does not claim access to confidential cell-level production data. It defines a model that such data could support.

3.2 The Logistic Defect-Escape Model

The primary outcome variable is Defect Escape Probability, abbreviated DEP. The binary response is coded as one when a cell, module, or pack reaches the field with a safety-relevant defect that should have been detected or contained, and zero when the defect is detected before release or when no safety-relevant defect is present. In practice, the unit of analysis can vary. A cell manufacturer may model cell escape. An automaker may model module or pack escape. A fleet-quality team may model vehicle-level exposure.

The logistic regression model is: logit(DEP) = β0 + β1PCR + β2CUD + β3SAV + β4MER + β5FAA + β6AAS + β7ICD + β8SPM + ε. PCR represents particle-contamination risk. CUD represents coating uniformity deviation. SAV represents separator alignment variation. MER represents moisture exposure risk. FAA represents formation and aging anomaly. AAS represents abnormal self-discharge signal. ICD represents inspection coverage depth. SPM represents supplier-process maturity. The signs of the coefficients should be interpreted carefully: the first six variables are expected to increase escape risk when they rise, while stronger inspection coverage and supplier maturity should reduce the risk.

The logistic transformation is necessary because probability is bounded between zero and one. The model estimates log odds and then converts them to probability: DEP = 1 / (1 + e^-z), where z is the regression score. A small change in a predictor can have a larger effect when the unit is near a high-risk threshold than when risk is already very low. This is useful for engineering managers because it supports threshold decisions. A process deviation may not require line stoppage by itself, but in combination with abnormal self-discharge and weak inspection coverage, the predicted escape probability may cross an unacceptable level.

Figure 1. Logistic model linking manufacturing predictors to defect escape probability.

3.3 Time-to-Warning and Hazard Models

The second model is a reliability regression for time-to-warning. The model can use a Weibull accelerated failure-time form: ln(TW) = α0 + α1PCR + α2CUD + α3SAV + α4MER + α5FAA + α6BMS + σW. TW represents time to diagnostic warning, warranty claim, abnormal degradation signal, or confirmed failure. BMS represents battery management system anomaly strength. W is the random error term. If a coefficient is negative, higher values of that predictor shorten time to warning. This is valuable because not all defective units fail immediately.

A proportional hazards form may also be used: h(t|X) = h0(t) exp(θ1PCR + θ2CUD + θ3SAV + θ4MER + θ5FAA + θ6BMS). The hazard is the instantaneous risk of a warning or failure at time t given survival to that point. The model allows reliability teams to ask whether specific manufacturing signatures increase hazard over operating time. For field fleets, this is often more informative than a single pass/fail label.

3.4 Data Requirements and Variable Definitions

The model requires disciplined data capture. Particle contamination indicators may come from cleanroom monitoring, foreign-object detection, or inspection records. Coating uniformity deviation may come from electrode thickness data, mass loading variation, edge quality, and drying conditions. Separator alignment variation may come from imaging and assembly process measurements. Moisture exposure may be captured through dry-room conditions, electrolyte handling, and process-time exposure. Formation and aging anomalies may come from voltage behavior, capacity, impedance, self-discharge, and temperature response.

Inspection coverage depth is a governance variable. It measures whether high-risk conditions receive additional inspection, whether data from inspection systems are stored and linked to unit identity, and whether the inspection method is sensitive to the suspected defect. Supplier-process maturity measures audit performance, process capability, corrective-action closure, traceability completeness, and historical defect patterns. These variables connect plant operations to management accountability.

The Chevrolet Bolt recall supports the model’s focus on interaction. If two rare manufacturing defects must appear in the same cell to create elevated fire risk, then a simple one-variable defect model is not enough. The logistic model should allow interaction terms, such as β9(PCR × SAV) or β10(CUD × FAA), where engineering evidence justifies them. Interaction terms help managers see whether two moderate signals together create unacceptable risk.

3.5 The Recall Exposure Index

The study also proposes a Recall Exposure Index, abbreviated REI. REI = Exposed Units × DEP × Severity Weight × Detection Delay Factor. Exposed Units is the population potentially affected by the process condition. Severity Weight reflects safety consequence. Detection Delay Factor rises when the issue remains undiscovered for longer periods or when traceability is weak. REI is not a legal measure. It is a governance measure that tells leaders how serious containment decisions have become.

Figure 2. Drivers of the Recall Exposure Index.

Validity is protected by separating verified public facts from implementable model design. NHTSA and GM documents support the importance of battery-fire recall and manufacturing-defect interaction. CATL reporting supports the scale of the global battery industry. Tesla’s Form 10-K supports the scale of engineering investment in EV technology firms. The recent defect literature supports the importance of contamination, process variation, and detection. The regression model defines how these categories can be translated into quality governance.

The limitation is clear: without plant-level data, coefficients cannot be estimated here. That does not weaken the method but prevents false precision. The contribution is a rigorous model specification and a management interpretation that battery manufacturers, automakers, suppliers, auditors, or regulators could use when data are available.

3.6 Model Assumptions, Boundaries, and Validation

The logistic model requires a clear definition of “safety-relevant defect.” The definition should not include every cosmetic or performance deviation. It should include defects or combinations of defects that can contribute to thermal runaway, internal short circuit, abnormal degradation, loss of isolation, excessive heating, significant capacity imbalance, or safety-related field action. Without this definition, the model will either become too broad to guide action or too narrow to catch serious patterns.

The unit of analysis should be selected deliberately. Cell-level modeling is best for process control and supplier quality. Module-level modeling helps identify assembly interactions and grouping effects. Pack-level modeling connects thermal, electrical, mechanical, and BMS conditions. Vehicle-level modeling helps warranty and field teams. A mature organization may operate all four levels and link them through traceability. The danger is to use one level of analysis and assume it answers all questions.

The model should include sampling uncertainty. Battery manufacturers do not inspect every feature of every cell with every possible method. Sampling plans create residual risk. A regression system can include inspection coverage depth, but managers should also model the false-negative rate of inspection methods. A technology that detects large contamination particles may miss smaller particles. A test that identifies early self-discharge may not detect mechanical separator vulnerability.

Interaction terms should be used with engineering discipline. It is tempting to add many interactions because production processes are complex. Too many interactions can overfit the model and confuse decision-making. The better practice is to include interaction terms when failure physics, root-cause evidence, or credible expert judgment indicates that two variables become more dangerous together. The Bolt case supports this principle because the simultaneous presence of rare defects mattered.

The survival model should distinguish between different event definitions. Time to diagnostic warning is not the same as time to customer complaint, warranty claim, thermal event, or confirmed root-cause failure. Each event has value, but each reflects a different stage of detection. A strong reliability program models early warnings separately from severe outcomes. Waiting for severe outcomes wastes information.

Censoring must also be handled correctly. Many batteries will not have failed or produced a warning by the end of the observation period. Survival methods are useful because they can use such censored data rather than discarding it. Engineering managers do not need to become statisticians, but they should understand that simple averages of failed units can mislead when many units remain in service.

The Recall Exposure Index can be expanded with traceability confidence. If traceability confidence is high, the exposed population may be narrow. If confidence is low, the exposed population must be wider. A traceability multiplier can be added: REI = Exposed Units × DEP × Severity Weight × Detection Delay Factor × Traceability Uncertainty. This form makes poor data discipline visible as a risk amplifier.

3.7 Discrimination, Calibration, and Predictor Correlation

A specification is only half of a usable model; the other half is knowing how to judge whether the fitted version earns trust. Two qualities deserve separate attention. Discrimination asks whether the model ranks units correctly, separating those that escape from those that do not, and it is commonly summarized by the area under the receiver-operating characteristic curve. Calibration asks a quieter but equally important question: when the model predicts a five-percent escape probability, does roughly five percent of that group actually escape? A model can discriminate well yet remain poorly calibrated, and for containment decisions calibration is the property that keeps thresholds honest. A reliability program should therefore report both, alongside a measure such as the Brier score that rewards confident predictions only when they prove correct.

Correlation among the predictors needs the same candor. Particle contamination, coating deviation, and moisture exposure are not independent in a real plant; a humid week or a tired coater can move several of them together. Strong collinearity does not bias the predicted probabilities, but it inflates the uncertainty around individual coefficients and can make the model appear to disagree with engineering intuition about which variable matters most. The practical response is to examine variance-inflation factors, to keep interaction terms grounded in failure physics rather than curiosity, and to resist the temptation to read a single coefficient as a clean causal lever. The model earns its authority by predicting escape well, not by pretending that each process variable acts alone.

Because chemistries, suppliers, and equipment change, the model should also be treated as something that learns rather than something that is fixed once. Bayesian updating offers a disciplined way to fold new field evidence into existing coefficients, letting a confirmed escape or a clean production run shift the estimates by an amount that reflects how much data already stood behind them. This protects the plant from two opposite errors: overreacting to a single dramatic event, and ignoring a slow accumulation of warnings that, taken together, signal that the process has moved.

Sample adequacy deserves a sober word as well, because a model can be specified perfectly and still be starved of the evidence it needs. Safety-relevant escapes are, by design, rare events, and logistic regression behaves poorly when the number of such events is small relative to the number of predictors. A common engineering rule of thumb asks for roughly ten observed events for each variable the model tries to estimate, which means a plant studying eight predictors and a handful of escapes simply does not yet have enough signal to trust individual coefficients. The honest response is not to abandon the model but to widen the evidence base through pooled supplier data, accelerated testing, and carefully defined near-miss events, while reporting uncertainty plainly. A model that admits what it does not yet know is more useful to a safety board than one that projects false confidence from thin data.

The model should be validated against field outcomes. If a plant’s predicted high-risk groups do not show elevated warranty or diagnostic signals, the model may be too conservative or poorly specified. If field failures appear in groups predicted to be low risk, the model is missing variables or failing to capture interactions. Validation protects the model from becoming decorative.

Read also: Sustainable Strategy In Resource-Constrained Firms

Table 1

Battery manufacturing evidence and reliability governance use

Evidence Verified detail Engineering management use
Chevrolet Bolt recall All 2017-2022 Bolt vehicles were recalled for high-voltage battery fire risk. Defect escape, traceability, and field containment.
GM and LG root cause Two rare manufacturing defects in the same battery cell were identified as the root cause in certain fires. Interaction effects and high-consequence defect combinations.
CATL 2025 report Operating revenue was RMB 423.7 billion, with net profit of RMB 72.2 billion. Scale discipline and manufacturing governance at volume.
Tesla 2025 Form 10-K R&D expense reached $6.411 billion, about 7 percent of revenue. Engineering investment context for EV systems reliability.


Table 2

Regression variables for battery defect escape and time-to-warning

Variable Meaning Engineering measurement
DEP Defect escape probability Probability that a safety-relevant defect reaches field use.
PCR Particle-contamination risk Cleanroom or inspection evidence of foreign matter exposure.
CUD Coating uniformity deviation Electrode thickness, mass loading, and drying variation.
SAV Separator alignment variation Assembly imaging and alignment tolerance data.
MER Moisture exposure risk Dry-room and process exposure history.
FAA Formation and aging anomaly Voltage, impedance, capacity, temperature, and self-discharge behavior.
ICD Inspection coverage depth Sensitivity and coverage of detection methods.
SPM Supplier-process maturity Audit performance, traceability, and corrective-action strength.


Chapter 4: Case Analysis and Engineering Findings

4.1 The Defect-Escape Pathway Through the Value Chain

The Chevrolet Bolt case remains central because it shows how manufacturing risk can travel quietly through the value chain. A cell defect begins inside a supplier’s process. It moves into a module. The module moves into a pack. The pack enters a vehicle. The vehicle enters a driveway, garage, or public charging environment. When the issue becomes visible, the customer does not experience it as a supplier-process deviation. The customer experiences it as a vehicle safety problem. Engineering management has to govern across that chain.

Figure 3. The defect-escape pathway from cell production to field use.

4.2 Interaction Effects and Logistic Interpretation

The phrase “two rare manufacturing defects in the same battery cell” should receive serious attention. It indicates that the root cause was not a common defect acting alone. It was an unfavorable combination. This matters because many quality systems are designed to detect single, known defects. They are less effective when risk emerges from defect interaction, marginal process drift, or a combination of indicators that appear harmless separately. Battery manufacturing governance must therefore pay special attention to interaction and correlation.

Logistic regression supports that need. Suppose a plant has low particle contamination, tight coating uniformity, strong separator alignment, stable dry-room control, normal formation data, and high inspection coverage. The estimated escape probability should be low. If particle contamination rises slightly but all other variables remain strong, the model may still stay below the containment threshold. If particle contamination rises while separator variation and formation anomaly also rise, the interaction may push risk across the threshold. The manager then has statistical grounds for containment rather than relying on intuition.

4.3 Early Versus Late Accountability

The battery industry should not treat recall as the beginning of accountability. Recall is late accountability, while early accountability appears in process-capability review, cleanroom discipline, electrode controls, dry-room monitoring, assembly precision, formation analytics, and aging-data review. The difference is not academic. Early accountability catches a problem when the affected population is still small, whereas late accountability often requires public warning, customer disruption, regulator involvement, and broad remedy.

4.4 Scale, Traceability, and Field Learning

CATL’s 2025 reported revenue and net profit show the scale at which battery manufacturing now operates. High scale creates advantages in learning, automation, supplier influence, and investment capacity. It also raises the consequence of systematic process variation. A minor process-control weakness repeated across high-volume production can become a large field population. Engineering managers in large battery firms must therefore think statistically before they think episodically (CATL, 2026).

Scale also pushes the problem upstream into the raw-material and supplier base, where much of the variation that later appears as a field signal is actually born. Cathode and anode active materials, electrolyte formulations, separators, foils, and binders all arrive with their own lot-to-lot variation, and a change of mine, refiner, or sub-supplier can shift a material property in ways that a downstream plant only discovers through formation behavior weeks later. A manufacturer that treats incoming material as interchangeable, certified once and forgotten, is effectively blind to one of the largest sources of escape risk. The stronger practice is to treat key material characteristics as predictors in their own right, to qualify second sources before they are needed rather than during a shortage, and to keep the supplier’s process history linked to the cells it eventually becomes. Resilience and reliability meet at this point, because a supply chain optimized only for cost can quietly raise the very escape probability the plant is working to lower.

Tesla’s R&D spending indicates the broader context in which battery manufacturing reliability sits. EV firms are not simply assembling vehicles; they are developing integrated systems of battery hardware, power electronics, software, thermal controls, diagnostics, charging, automation, and manufacturing processes. Reliability governance must connect those layers. A battery pack’s field behavior may reflect cell production, pack design, thermal management, BMS logic, charging conditions, customer use, and software updates. A plant-only quality model is necessary but not sufficient (Tesla, 2026).

The field lesson from recalls is that traceability determines the scope of pain. If a manufacturer can trace a defect to a narrow date range, line, process condition, supplier lot, or cell population, containment can be targeted. If traceability is weak, the exposed population becomes larger because the company cannot prove which units are safe. Traceability is therefore not just a compliance requirement. It is an economic and ethical safeguard.

Engineering managers should also recognize that the most dangerous defects may not be the easiest to detect. Surface scratches, missing labels, dimensional variation, and obvious leakage can be found with mature inspection systems. Internal contamination, separator defects, electrode misalignment, drying irregularities, and abnormal electrochemical behavior may require deeper measurement. The inspection plan must match the failure mode, not the convenience of the equipment already installed.

Formation and aging data are especially valuable because they reveal how the cell behaves after manufacturing steps are completed. Voltage relaxation, impedance, self-discharge, capacity, and temperature behavior can all provide early warning of abnormality. These data should not be used only to sort cells into pass/fail bins. They should feed predictive models. A cell that technically passes may still sit in a higher-risk region of multivariate space.

Multivariate monitoring is the natural extension of that idea. A cell that clears every individual limit can still sit in an unusual corner of the combined distribution, where coating, impedance, self-discharge, and temperature behavior together look unlike the healthy population even though no single number is alarming. Techniques as familiar as principal-component analysis or Hotelling’s statistic let a plant watch the joint behavior of many measurements rather than policing them one at a time, and they are well matched to the Bolt lesson that danger lived in a combination rather than in any one defect. The point is not statistical sophistication for its own sake; it is that batteries fail in patterns, and a monitoring system that can only see one variable at a time will keep missing the patterns that matter most.

The logistic model can support production decisions at several levels. At the line level, it can trigger a hold when predicted escape probability rises. At the supplier level, it can compare process maturity and defect interaction across plants. At the vehicle level, it can identify packs that deserve diagnostic follow-up. At the executive level, it can quantify whether containment should be limited, expanded, or elevated to safety review.

The reliability regression adds time. A defect that does not create immediate failure may still shorten time to warning. For example, a cell with abnormal self-discharge may pass initial release but show accelerated degradation. A Weibull model can estimate whether units with certain production signatures show earlier warnings. This matters for warranty and field monitoring because some risks are temporal rather than immediate.

A battery management system can support governance only if its diagnostic signals are integrated with manufacturing data. Field warnings without manufacturing context may lead to broad fleet concern. Manufacturing records without field signals may underestimate risk. The strongest reliability systems join both. A BMS anomaly can be traced back to plant, line, lot, formation data, operator shift, material batch, and inspection results. That join is where learning occurs.

The Recall Exposure Index developed in the methodology helps leaders compare containment decisions. A severe but narrowly traceable defect may have a lower index than a moderate defect with poor traceability and a large exposed population. The index forces managers to account for population, probability, severity, and detection delay. It should be reviewed by a cross-functional safety board rather than left inside one department.

Regulators and insurers are likely to expect stronger evidence as EV fleets grow. Public safety agencies do not need access to every proprietary process parameter, but they do need confidence that manufacturers can identify exposed populations, explain root causes, and implement remedies. A company that cannot connect field events back to manufacturing evidence will face harder questions when failures occur.

The most important finding is that battery reliability governance must be layered. Prevention reduces defect occurrence. Detection reduces escape. Traceability reduces recall scope. Diagnostics reduce time to discovery. Statistical modeling improves decision thresholds. Leadership accountability ensures that production pressure does not override safety evidence. None of these layers is sufficient alone. The strength lies in their combination.

4.5 The Cost of Quality and the Economics of Escape

The case also has an economic reading that engineering managers ignore at their peril. Quality costs fall into familiar categories: prevention, appraisal, internal failure, and external failure, and their relative sizes tell a story about where an organization has chosen to spend its attention. Prevention and appraisal are paid in advance and are largely visible on a budget line. External failure is paid later, often in public, and includes recall logistics, replacement hardware, legal exposure, regulatory engagement, depressed residual values, and the harder-to-measure erosion of brand trust. The Bolt campaign is a vivid example of how a defect that would have cost relatively little to catch at the cell or module stage became an expensive, fleet-wide obligation once it had escaped.

The logistic model and the Recall Exposure Index give this economic logic a usable shape. If a manager can estimate the probability that a lot carries a safety-relevant escape and can multiply it by the exposed population, the severity of the failure mode, and the delay before discovery, then the expected cost of inaction becomes comparable with the concrete cost of additional inspection, a production hold, or a supplier intervention. Framed this way, deeper inspection on a high-energy product stops looking like an expense that hurts yield and starts looking like the purchase of a smaller, earlier, more controllable failure in place of a larger, later, public one. The discipline is to make that comparison before a crisis, when the numbers are still hypothetical, rather than after, when they are painfully real.

Battery manufacturing lines produce enormous quantities of data, but data volume does not guarantee learning. A plant may collect coating thickness, drying temperature, humidity, formation voltage, aging behavior, inspection images, torque records, and BMS signals without connecting them into a usable reliability story. Engineering management must turn data into evidence. That requires identifiers, clean timestamps, common definitions, accessible storage, and analysts who understand both statistics and manufacturing physics.

The cleanroom and dry-room environment deserves board-level respect because small changes can matter. Moisture exposure, particle contamination, and handling discipline are not routine housekeeping topics. They can influence electrochemical stability and defect risk. Managers sometimes focus on equipment automation while underestimating environmental control. A highly automated process inside a poorly controlled environment can still produce unsafe variation.

Electrode coating is another critical domain. Uniformity, edge quality, drying conditions, and material loading affect cell consistency. Variability at this stage may not be visible to a customer, yet it can influence capacity balance, impedance, heat generation, and aging behavior. Coating data should therefore be treated as reliability evidence, not simply yield data. A cell that passes a final test may still carry a process history that increases risk over time.

Formation and aging occupy a unique position because they expose the cell’s behavior after assembly. These steps are sometimes viewed as production bottlenecks because they consume time and capital. That view is incomplete, because formation and aging create some of the richest evidence available to a manufacturer. Reducing cycle time without preserving detection power can be dangerous. The proper management question is how to extract more information from formation and aging, not merely how to shorten them.

End-of-line testing has limits. It can identify many defects, but it cannot prove that every unit will remain safe across years of charging, fast charging, temperature exposure, vibration, aging, and customer behavior. A battery pack is not a static object. Its condition changes through use. That is why field diagnostics and reliability regression matter. The quality system has to extend beyond the factory gate.

Manufacturers should pay close attention to false reassurance from low incident counts. If a fleet has millions of cells and only a few visible failures, leaders may assume the system is safe. That conclusion may be correct, yet it deserves to be tested against exposure rather than assumed. A few severe events in a large population can still indicate a meaningful defect pathway if the consequence is high and the failure mode is credible. Safety-critical engineering cannot rely on rarity alone.

The Bolt recall also raises an important question about communication. Customers were asked to respond to fire-risk instructions, recall remedies, and software updates. When a technical defect becomes public, communication must be precise, honest, and usable. Engineering teams support this by clarifying what is known, what is being tested, which units are affected, what interim actions are needed, and how the remedy changes risk. Poor communication can turn technical uncertainty into public fear.

CATL’s scale highlights a different lesson: world-class battery manufacturing must combine cost discipline with safety discipline. Large producers face intense pressure to lower cost per kilowatt-hour, increase energy density, expand capacity, and satisfy customers across vehicle and energy-storage markets. Those pressures are legitimate, but they cannot be allowed to weaken process control. The companies that endure will be those that make safety compatible with scale, not those that treat safety as friction.

Tesla’s R&D intensity points toward the integration challenge. Battery performance is shaped not only by cell manufacturing but by vehicle thermal design, power electronics, charging strategy, software updates, and user behavior. A manufacturing model that ignores pack design or BMS logic may miss system-level safety. Engineering managers should connect manufacturing quality reviews with product engineering, software diagnostics, and field reliability teams.

Warranty data can be misleading if examined without context. A customer complaint may arise from charging equipment, driving conditions, software interpretation, service error, or actual cell defect. Regression models should therefore distinguish between confirmed root-cause categories and broad claims. If every warranty event is treated as a battery manufacturing defect, the model becomes noisy. If too few events are investigated deeply, the model becomes blind.

A mature battery manufacturer should maintain a closed-loop corrective-action system. Field signals trigger investigation. Investigation links to manufacturing records. Root-cause analysis identifies process or design contributors. Corrective action changes controls. The model is updated. The next production lots are monitored for improvement. This loop is easy to describe but difficult to maintain under production pressure. Leadership has to protect it.

The strongest plants also build a culture where stopping shipment is possible. If a line engineer believes that raising a defect concern will be treated as disloyalty to output targets, the quality system has already weakened. Battery safety depends on people being able to say that the evidence is not good enough. Statistical models work only when the organization is willing to act on them.

The role of automation should be kept in proportion. Automated inspection can increase speed and consistency, but it still depends on correct sensor placement, calibration, algorithm training, defect libraries, maintenance, and review of false negatives. Automation offers no moral guarantee, and engineering managers must govern automated systems with the same seriousness they bring to manual processes.

The field also needs stronger cross-company learning. Battery manufacturers may hesitate to share defect information for competitive or legal reasons, yet safety improves when the industry understands common pathways. Regulators, standards bodies, and professional associations can help create channels for anonymized learning. The aim is not to expose proprietary process details. It is to prevent the same safety lessons from being learned only after repeated public failures.

Cell balancing and pack integration create another layer of risk. A cell that appears acceptable alone may behave differently when grouped with other cells in a module or pack. Variation in capacity, impedance, self-discharge, and thermal behavior can produce stress on the pack-management system. Manufacturing governance should therefore include matching logic and module-level risk assessment. Cell quality cannot be treated as isolated if the product is ultimately a pack.

Thermal management should be linked to manufacturing evidence. A pack with strong cooling design may tolerate some variation better than a design with narrow thermal margins. Conversely, a manufacturing deviation that looks moderate at cell level may become more serious in a pack design with limited heat-spreading capacity. Reliability models should therefore include design margins where available. Process quality and product design are not independent contributors to field safety. Research on battery thermal management systems reinforces this point, showing how pack-level cooling and thermal design can prevent or suppress thermal runaway even when an individual cell deviates from its expected behavior (Tai et al., 2025).

Charging behavior also affects field risk. Fast charging, high state of charge, high ambient temperature, and repeated thermal cycling can expose weaknesses that ordinary end-of-line tests do not reveal. Manufacturers cannot control every customer behavior, but they can design diagnostics and usage policies that reduce risk. Field models should therefore include operating conditions when assessing time-to-warning or degradation behavior.

The used-vehicle market adds a further governance concern. Battery packs move beyond the first owner. Diagnostic transparency, state-of-health reporting, service history, and recall completion all shape second-hand trust. A manufacturer with weak battery traceability may create uncertainty not only for new-vehicle customers but for used-vehicle buyers, insurers, fleet operators, and recyclers. Reliability governance therefore extends across the product life cycle.

Battery recycling and second-life use also depend on accurate quality records. A pack removed from a vehicle may still hold substantial value, but its safe reuse depends on condition evidence. If manufacturing and field histories are incomplete, second-life decisions become more uncertain. Engineering management should think about end-of-life data at the beginning of life. Traceability that protects recall decisions can also support circular value.

The cost of over-containment should also be acknowledged. If a manufacturer recalls or replaces too broadly because it lacks traceability, it spends money, disrupts customers, and consumes scarce service resources. If it contains too narrowly, it leaves risk in the field. Logistic regression and exposure indexing help navigate that tension by making the basis of containment explicit. Precision is both a safety and economic virtue.

The role of service networks is often underestimated. A recall remedy may be technically sound but operationally weak if dealers or service centers lack training, tools, parts, diagnostic access, or scheduling capacity. Engineering managers should include service readiness in containment planning. A field action that cannot be executed quickly may extend customer exposure and erode trust.

Battery safety governance also requires clear authority over software remedies. Diagnostic software can monitor packs, limit charging, or identify units for replacement. Such remedies may reduce risk, but they must be validated. A software remedy that lowers customer utility without explaining why may damage trust. A remedy that misses affected units may damage safety. Software decisions should therefore be reviewed alongside hardware evidence.

Chapter 5: Managerial Implications and Recommendations

5.1 Governing the Defect-Escape Pathway

Battery manufacturers should organize quality governance around the defect-escape pathway. The pathway begins with process design, moves through material control, electrode production, cell assembly, formation, aging, module and pack assembly, vehicle integration, field diagnostics, and warranty response. Each stage should have clear indicators, containment authority, and escalation rules. A failure at any stage should update the risk model rather than disappear into local correction.

The logistic regression model should be implemented as a live quality tool, not as an annual analytical project. High-risk predictors should be refreshed daily or by production lot. The model should identify whether current process conditions are moving toward higher escape probability. Production teams should not wait until a defect is confirmed by field data. The purpose of predictive governance is to act while the exposed population is still small.

5.2 Thresholds, Interaction Terms, and Live Modeling

Thresholds must be decided before production pressure rises. A plant should define risk bands for predicted defect escape probability. Low risk allows standard release. Moderate risk requires added inspection or engineering review. High risk triggers containment. Extreme risk stops shipment. The bands should be linked to severity. A low-probability cosmetic defect and a low-probability thermal runaway pathway do not deserve the same treatment.


Figure 4. Containment decision bands by predicted defect escape probability.


Interaction terms deserve special governance. If historical evidence or engineering analysis shows that two defects together create high consequence, the model should not wait for a large sample of failures. Battery safety cannot require thousands of accidents before recognizing an interaction. Engineers can justify interaction terms from failure physics, process knowledge, and case evidence. Statistical methods should support engineering judgment, not paralyze it.

5.3 Traceability and Risk-Weighted Inspection

Manufacturers should strengthen traceability down to the smallest practical unit. Cell identity, material lot, equipment condition, process parameters, formation curves, aging data, inspection results, module placement, pack identity, and vehicle identity should be connected. The aim is not data hoarding. The aim is recall precision. If the company cannot trace, it cannot contain narrowly. If it cannot contain narrowly, customers and regulators absorb uncertainty.

Inspection strategy should be risk-weighted. High-energy products justify deeper inspection where failure consequence is severe. Machine vision, X-ray methods, electrical tests, thermal imaging, ultrasonic detection, and aging analytics should be selected according to the defect modes most likely to harm safety or durability. Inspection investment should not be judged only by immediate yield. It should also be judged by avoided recall exposure and protected trust.

5.4 Supplier, Field, and Software Governance

Supplier governance should move beyond annual audits. Battery safety depends on continuous process evidence. Suppliers should provide process capability data, nonconformance history, corrective-action performance, material-control records, and traceability compatibility. Buyers should retain the right to conduct deeper reviews when process changes, field signals, or defect trends suggest elevated risk. A supplier relationship that prevents the buyer from seeing enough evidence is not mature enough for safety-critical production.

Formation and aging analytics should receive executive attention. These data sets are often rich but underused. They can reveal subtle abnormality that ordinary dimensional inspection will not catch. Engineering managers should ensure that formation data are stored, modeled, and connected to field performance. The plant should not discard the very evidence that could later explain a fleet pattern.

Field diagnostics should be designed with manufacturing learning in mind. A BMS warning that cannot be linked to manufacturing history is less useful than one that can. The manufacturer should design data flows so that abnormal field behavior can be traced back to process variables. Privacy, cybersecurity, and customer consent must be respected, but those obligations do not remove the need for reliability learning.

5.5 Safety Review and Executive Reporting

Recall governance needs an independent safety review path. Production leaders may feel pressure to avoid shipment holds or broad containment. Commercial leaders may fear public disclosure. Engineers may disagree about root cause. A safety board with authority over containment decisions can prevent slow drift. The board should include manufacturing engineering, reliability, legal, safety, field quality, supplier quality, and senior leadership.

The Recall Exposure Index should become part of executive reporting. Leaders should see exposed population, predicted escape probability, severity weight, traceability confidence, and detection delay. A risk that remains hidden for months deserves attention even if confirmed failures are few. The index makes delay visible. It also helps management justify expensive containment before a larger failure pattern appears.

5.6 People, Incentives, and Launch Discipline

Battery firms should train engineering managers in statistical thinking. Process capability, logistic regression, survival analysis, interaction effects, sampling risk, and false-negative exposure are not specialist topics only for data scientists. They are part of modern manufacturing leadership. A manager who cannot interpret probability may either overreact to noise or underreact to serious signals.

Production targets must not be allowed to weaken quality gates. High-volume battery manufacturing is capital intensive, and plant utilization matters. Yet the economic logic of speed collapses when a recall destroys trust. The most disciplined plants do not treat quality as an obstacle to throughput. They treat stable process control as the basis of throughput.

The final management recommendation is to connect battery quality to customer trust explicitly. Customers do not know the details of coating uniformity, separator alignment, or formation curves. They know whether the vehicle is safe, whether recalls are handled honestly, whether range remains credible, and whether the company communicates clearly. Engineering quality becomes brand trust through field behavior. That connection should influence how leaders allocate resources to prevention, inspection, and traceability.

Battery manufacturers should create a Safety-Relevant Process Change Board. Any change in material supplier, coating recipe, drying profile, cell format, separator, electrolyte, line speed, formation protocol, inspection method, or BMS diagnostic logic should be reviewed for escape-risk implications. The board should not slow every improvement. It should identify which changes alter the assumptions behind the current quality model.

The organization should also maintain a defect taxonomy that is shared across engineering, manufacturing, supplier quality, field quality, and service. A defect called one thing in the plant and another thing in the field cannot be modeled cleanly. The taxonomy should distinguish occurrence, detection, containment, escape, field warning, confirmed failure, and safety event. This vocabulary is the grammar of reliability governance.

Managers should invest in data-linking infrastructure before the next crisis. It is too late to build traceability when vehicles are already in customer hands and a defect is suspected. The plant should be able to retrieve all relevant process and inspection history for a cell, module, pack, and vehicle quickly. The time required to answer basic exposure questions is itself a measure of governance quality.

Quality incentives should be aligned with long-term reliability. If managers are rewarded mainly for daily output and yield, they may underweight early warning signals. Incentives should also reflect containment quality, corrective-action closure, field performance, audit results, and reduction in defect escape risk. The organization should not ask people to protect safety while rewarding them only for speed.

5.7 Cybersecurity and Over-the-Air Remedy Governance

As remedies increasingly arrive through software, the governance of that software becomes part of reliability itself. A modern battery pack is monitored and partly controlled by code that can be updated remotely, which means that detection capability, charging limits, and even the definition of an abnormal signal can change after the vehicle has left the plant. That power is valuable, because it allows a manufacturer to contain a newly understood risk without recovering every vehicle physically. It is also a responsibility, because an over-the-air change that quietly reduces range or alters behavior without clear explanation can damage trust as surely as a hardware fault, and a diagnostic pipeline that is not secured can become a safety problem in its own right.

Reliability governance should therefore record which diagnostic version is active in which fleet population, treat changes to detection logic with the same change-control rigor applied to a coating recipe, and protect the integrity and confidentiality of the data that flow back from the field. When a field signal is interpreted, the organization needs to know whether the baseline against which it was judged was the original software or a later revision. Without that discipline, two vehicles with identical hardware histories can produce different warnings for reasons that have nothing to do with their cells, and the learning loop that the whole system depends on begins to blur.

Battery firms should treat software diagnostics as part of quality governance. BMS algorithms can detect abnormal behavior, limit operation, trigger service, or support recall decisions. Software updates may also modify detection capability. The quality organization should therefore know which diagnostic version is active in which fleet population. A field signal cannot be interpreted properly if the diagnostic baseline is unclear.

Regulators should encourage traceability and evidence quality rather than only reactive recalls. Public safety improves when manufacturers can identify exposed populations quickly and narrowly. Regulatory expectations around data retention, defect reporting, and field monitoring can strengthen industry discipline while still allowing innovation. The goal is not to make battery production defensive. It is to make scale credible.

Automakers should avoid over-reliance on supplier assurances. Supplier responsibility matters, but the vehicle brand owns the customer relationship. Automakers should have enough technical visibility to challenge supplier data, perform independent audits, and understand high-risk process steps. A purchase agreement cannot replace engineering competence.

The human factor remains important. Operators, technicians, quality engineers, maintenance teams, and process engineers often notice early signs before dashboards do. Unusual residue, recurring machine adjustment, abnormal scrap, repeated minor alarms, or changes in handling behavior can all indicate drift. A strong plant listens to such evidence and investigates it before the model confirms the pattern.

Training should include lessons from public recalls. Engineers remember cases better than abstract warnings. The Bolt recall can be used to teach defect interaction, traceability, containment, and communication. Training should ask what data would have helped earlier, what inspection methods could have reduced escape, and how decision thresholds should respond to rare but severe risks.

Battery reliability governance should also include emergency communication planning. If field risk is discovered, the company must communicate with customers, dealers, regulators, emergency responders, and internal teams. The technical evidence must support the message. Engineering managers should be involved in preparing clear interim guidance, not only long-term root-cause reports.

The organization should perform periodic model audits. Logistic and survival models can drift as chemistries, suppliers, equipment, and customer usage change. A model built on one cell type may not transfer to another. A model built before a process change may lose accuracy afterward. Regular audits should examine prediction quality, false negatives, false positives, and decision usefulness.

Battery manufacturers should also build reliability reserves into launch planning. New products often face intense market pressure. Launch schedules may compress validation, process capability studies, and field monitoring plans. High-energy products need a more cautious launch logic. Early production should be monitored with heavier analytics until process stability is proven across enough volume and time.

The regression framework should be supported by a manufacturing data dictionary. Every predictor must have a definition, unit, data source, sampling frequency, owner, and retention rule. Particle contamination risk, for example, may be derived from inspection events, environmental monitoring, or failure-analysis records. If plants define the variable differently, the model will not travel across facilities. Governance begins with language.

A practical pilot can begin with a high-risk process family rather than the whole factory. For example, a manufacturer may start with coating uniformity and formation anomalies, connect those variables to early field warnings, and then expand the model to separator alignment, moisture exposure, and BMS diagnostics. This phased approach allows learning without waiting for a perfect data system.

The board should receive a concise monthly reliability dossier. The dossier should show predicted escape trends, containment actions, high-risk lots, field warnings, traceability confidence, model accuracy, and unresolved corrective actions. Executives do not need every process chart, but they need enough evidence to understand whether safety risk is rising or falling. A well-designed dossier prevents leaders from treating battery quality as a plant-level detail.

The paper also recommends third-party review for severe or ambiguous battery incidents. Independent experts can help challenge internal assumptions, examine whether the suspected root cause is complete, and review whether containment is adequate. External review is especially useful when the company faces reputational pressure, litigation concern, or internal disagreement. Independence can protect both customers and the integrity of the engineering process.

Battery manufacturing will continue to change as chemistries, cell formats, manufacturing methods, and vehicle platforms evolve. The quality system must evolve with it. A model trained on one generation of cells should not be trusted blindly on the next. Engineering managers should treat model transfer as a technical decision requiring validation, not an administrative convenience.

Battery warranty governance should not sit apart from manufacturing governance. Warranty patterns may reveal issues that were invisible in plant release data. Early capacity loss, charging anomalies, unusual service visits, or thermal warnings can point back to subtle process drift. Warranty teams should therefore have a direct channel into reliability engineering. Their evidence is not merely commercial cost information; it is field intelligence.

Fleet operators provide another valuable source of evidence because they accumulate mileage, charging cycles, climate exposure, and usage data faster than ordinary retail customers. Manufacturers should work with fleets to monitor battery behavior under demanding conditions. Fleet data can reveal early degradation patterns, charging stress, and diagnostic trends before they appear broadly. Properly managed, fleet partnerships become part of safety learning.

The organization should also examine near misses. A contained defect, abnormal formation cluster, or high-risk lot that never reaches customers still deserves analysis. Near misses are gifts to engineering management because they reveal weakness without public harm. Plants that celebrate low field failure but ignore near misses may miss the chance to strengthen controls before the next variation escapes.

Chapter 6: Closing Findings and Future Research

6.1 Summary of the Argument

Electric vehicle battery manufacturing is one of the hardest tests of modern engineering management because its failures can remain hidden until the product is already in public use. A defective cell may pass through process steps, enter a module, become part of a pack, move into a vehicle, and operate for some time before abnormal behavior appears. By then, the matter is no longer a plant-quality issue alone. It may involve customer safety, dealer action, regulator attention, warranty exposure, software response, supplier accountability, and public confidence in electric mobility.

The Chevrolet Bolt recall remains an important case because it shows how rare manufacturing defects can become system-level risk when detection and containment do not stop them before field release. GM’s statement that two rare defects appeared simultaneously in the same cell is especially important for engineering managers. It warns against simple defect thinking. Battery safety can be threatened by combinations: contamination with alignment variation, moisture with formation anomaly, marginal inspection coverage with weak traceability, or a supplier process change with limited field diagnostics. The governing system must be able to see interaction, not only individual nonconformance.

6.2 What the Models Contribute

The logistic regression framework developed here addresses that need by estimating Defect Escape Probability from process and inspection evidence. Particle contamination, coating uniformity deviation, separator alignment variation, moisture exposure, formation and aging anomaly, abnormal self-discharge, inspection coverage, and supplier-process maturity are not abstract variables. They correspond to practical control points inside battery production. When the model is implemented properly, it can help determine whether a lot should move forward, be held, receive deeper inspection, or trigger a supplier investigation.

The reliability-regression model adds the dimension that ordinary release testing cannot provide by itself: time. Battery defects do not always announce themselves at the factory door. Some appear through accelerated degradation, unusual self-discharge, impedance growth, thermal behavior, BMS warnings, warranty claims, or field incidents after use has begun. Time-to-warning analysis connects manufacturing evidence with field behavior. That connection is essential because a battery-quality system that ends at shipment is incomplete. In electric mobility, reliability governance must continue into the fleet.

Scale changes the moral and managerial stakes. CATL’s 2025 reporting shows the size of the global battery industry and the manufacturing discipline required to supply it. At such volume, very small probabilities can become meaningful populations. A defect rate that appears statistically small may still place many vehicles under concern when multiplied by cells per pack and packs per fleet. Engineering managers should therefore think in population exposure, not only percent yield. High yield is not the same as low safety risk if the escaping defects are severe.

Tesla’s reported R&D spending also places battery governance in the wider engineering context of the EV industry. Battery performance is shaped by cell manufacturing, thermal design, charging strategy, software, diagnostics, pack architecture, and vehicle use. A manufacturer cannot protect safety by isolating plant quality from product engineering or field data. The system must learn across boundaries. Manufacturing records should connect to BMS behavior, service findings, warranty patterns, supplier changes, and corrective actions. The more fragmented the evidence, the wider the recall shadow becomes when a defect is suspected.

6.3 Layered Reliability Governance

The strongest practical recommendation is layered reliability governance. Prevention starts with process design, cleanroom discipline, dry-room control, supplier qualification, coating stability, separator alignment, and formation control. Detection requires risk-weighted inspection, in-line measurement, X-ray or other advanced methods where consequence justifies them, and disciplined use of formation and aging data. Containment requires traceability at the smallest practical unit. Prediction requires BMS diagnostics and survival modeling. Accountability requires independent safety review and a recall-ready decision path that can act before commercial pressure erodes judgment.


Figure 5. Layered reliability governance for battery manufacturing.


Human judgment remains central. Operators, technicians, process engineers, maintenance teams, and quality reviewers often notice weak signals before a model does. Unusual residue, recurring adjustments, unexplained formation clusters, repeated minor rework, or a supplier’s reluctance to share process data may be early evidence of risk. A serious battery manufacturer should make it safe to escalate such concerns. Production targets matter, but they cannot be allowed to make warning signs inconvenient. In safety-critical manufacturing, silence is not efficiency.

6.4 Future Research

Future research should test the proposed models with plant-level and fleet-level datasets. The most valuable work would connect process parameters, lot history, inspection coverage, formation curves, BMS warnings, service records, warranty claims, and confirmed root causes. Research should also examine management variables: escalation delay, audit quality, closure time for corrective actions, supplier transparency, and production-pressure indicators. Technical variables may explain much of the risk, but organizational behavior determines whether the evidence is acted upon in time.

A further line of research would build shared, anonymized datasets across manufacturers, much as aviation built confidential incident reporting that improved safety for the whole industry without exposing any single operator. Battery makers have understandable reasons to guard process detail, yet the failure pathways they face are often common, and a defect mechanism learned painfully by one firm tends to wait quietly inside others. Neutral bodies, standards organizations, or research consortia could host such evidence under terms that protect competitive information while still allowing the field to learn from interactions, material problems, and detection gaps that no single company sees often enough to model well. The same statistical tools described here would become far more powerful when fitted to evidence drawn from many plants rather than one.

6.5 A Concluding Reflection

There is a temptation, in a field moving as fast as electrification, to treat reliability as something that can be added later, once volume and cost have been mastered. The history of safety-critical manufacturing argues the opposite. The organizations that endure are usually the ones that built the discipline early, when it was inconvenient and unrewarded, and then let scale magnify a sound process rather than a fragile one. A battery plant cannot inspect its way out of a culture that treats warnings as obstacles, and it cannot model its way out of data it never bothered to connect. The instruments in this work are only as good as the willingness to act on what they reveal.

In a real sense, battery quality is the product behind the product. Customers may never see coating uniformity, separator alignment, moisture control, or formation analytics, but they live with the consequences. Electric mobility will be judged not only by range, charging speed, cost, and software features, but by the quiet reliability of the energy systems beneath them. The engineering manager’s duty is to keep scale, speed, and safety in the same conversation. When that duty is performed well, electrification gains the trust it needs to endure.

References

Chen, W., Liu, S., & Wang, Y. (2025). Defects in lithium-ion batteries: From origins to safety risks. Green Energy & Intelligent Transportation, 4, 100235. https://doi.org/10.1016/j.geits.2024.100235

Contemporary Amperex Technology Co., Limited. (2026). Zero-carbon technology powers all-domain growth: CATL releases 2025 annual report. https://www.catl.com/en/news/6773.html

Das Goswami, B. R., Abdisobbouhi, Y., Du, H., Mashayek, F., Kingston, T. A., & Yurkiv, V. (2024). Advancing battery safety: Integrating multiphysics and machine learning for thermal runaway prediction in lithium-ion battery module. Journal of Power Sources, 614, 235015. https://doi.org/10.1016/j.jpowsour.2024.235015

General Motors. (2021). Chevy Bolt EV and EUV recall. https://experience.gm.com/recalls/bolt-ev

National Highway Traffic Safety Administration. (2021). All Chevy Bolt vehicles recalled for fire risk. https://www.nhtsa.gov/press-releases/recall-all-chevy-bolt-vehicles-fire-risk

National Highway Traffic Safety Administration. (2023). Safety recall report 21V-650. https://static.nhtsa.gov/odi/rcl/2021/RCLRPT-21V650-3740.PDF

Ploder, C., Allegro, A., & Bernsteiner, R. (2025). Quality control and management systems for lithium-ion battery production: A systematic literature review. Advanced Energy Conversion Materials, 6(1), 122-136. https://doi.org/10.37256/aecm.6120256547

Tai, L. D., Le, P. N. T., Duy, V. N., Nguyen, V. D., & Pham, N. T. (2025). Advances in the battery thermal management systems of electric vehicles: Thermal runaway prevention and suppression. Batteries, 11(6), 216. https://doi.org/10.3390/batteries11060216

Tesla, Inc. (2026). Annual report on Form 10-K for the year ended December 31, 2025. U.S. Securities and Exchange Commission. https://www.sec.gov/Archives/edgar/data/1318605/000162828026003952/tsla-20251231.htm

The Thinkers’ Review